CUDA 是 NVIDIA 开发的并行计算平台和编程模型,可利用 GPU 的强大能力大幅提升计算性能。它使开发者能够加速计算密集型应用,并广泛应用于深度学习、科学计算和高性能计算(HPC)等领域。
本 CUDA 编程指南是介绍 CUDA 编程模型以及如何使用 CUDA 平台编写在 GPU 上执行的代码的官方综合性资料。本指南涵盖从 CUDA 编程模型、CUDA 平台到语言扩展细节的各方面内容,并介绍如何利用特定的硬件和软件特性。本指南为初学开发者提供了学习 CUDA 的途径,同时也为开发者使用 CUDA 构建应用提供了必不可少的参考资料。
本指南的组织结构
即使对于主要使用库、框架或领域专用语言(DSL)的开发者,了解 CUDA 编程模型以及 GPU 如何执行代码,也有助于理解各层抽象背后发生的事情。本指南首先用一章介绍独立于任何特定编程语言的CUDA 编程模型,适合任何有兴趣了解 CUDA 工作原理的人,甚至包括非开发者。
本指南分为五个主要部分:
第 1 部分:简介与编程模型概述
独立于具体语言的 CUDA 编程模型概述,以及对 CUDA 平台的简要介绍。
本部分面向任何希望了解 GPU 以及在 GPU 上执行代码的概念的人,即使他们不是开发者。
第 2 部分:使用 CUDA 进行 GPU 编程
使用 C++ 和 Python 进行 GPU 编程的基础知识。
本部分面向任何希望入门 GPU 编程的人。
本部分旨在提供教学指导,而非全面介绍,讲解 CUDA 编程中最重要且最常用的内容,包括一些常见的性能考量。
第 3 部分:高级 CUDA
介绍 CUDA 的一些更高级的特性,这些特性既支持细粒度控制,也提供了更多最大化性能的机会,包括在单个应用中使用多个 GPU。
本章从总体上介绍 CUDA 编程模型,且不依赖任何语言。此处介绍的术语和概念适用于以任何受支持的编程语言使用 CUDA 的情况。后续章节将使用 C++ 说明这些概念。
1.2.1. 异构系统
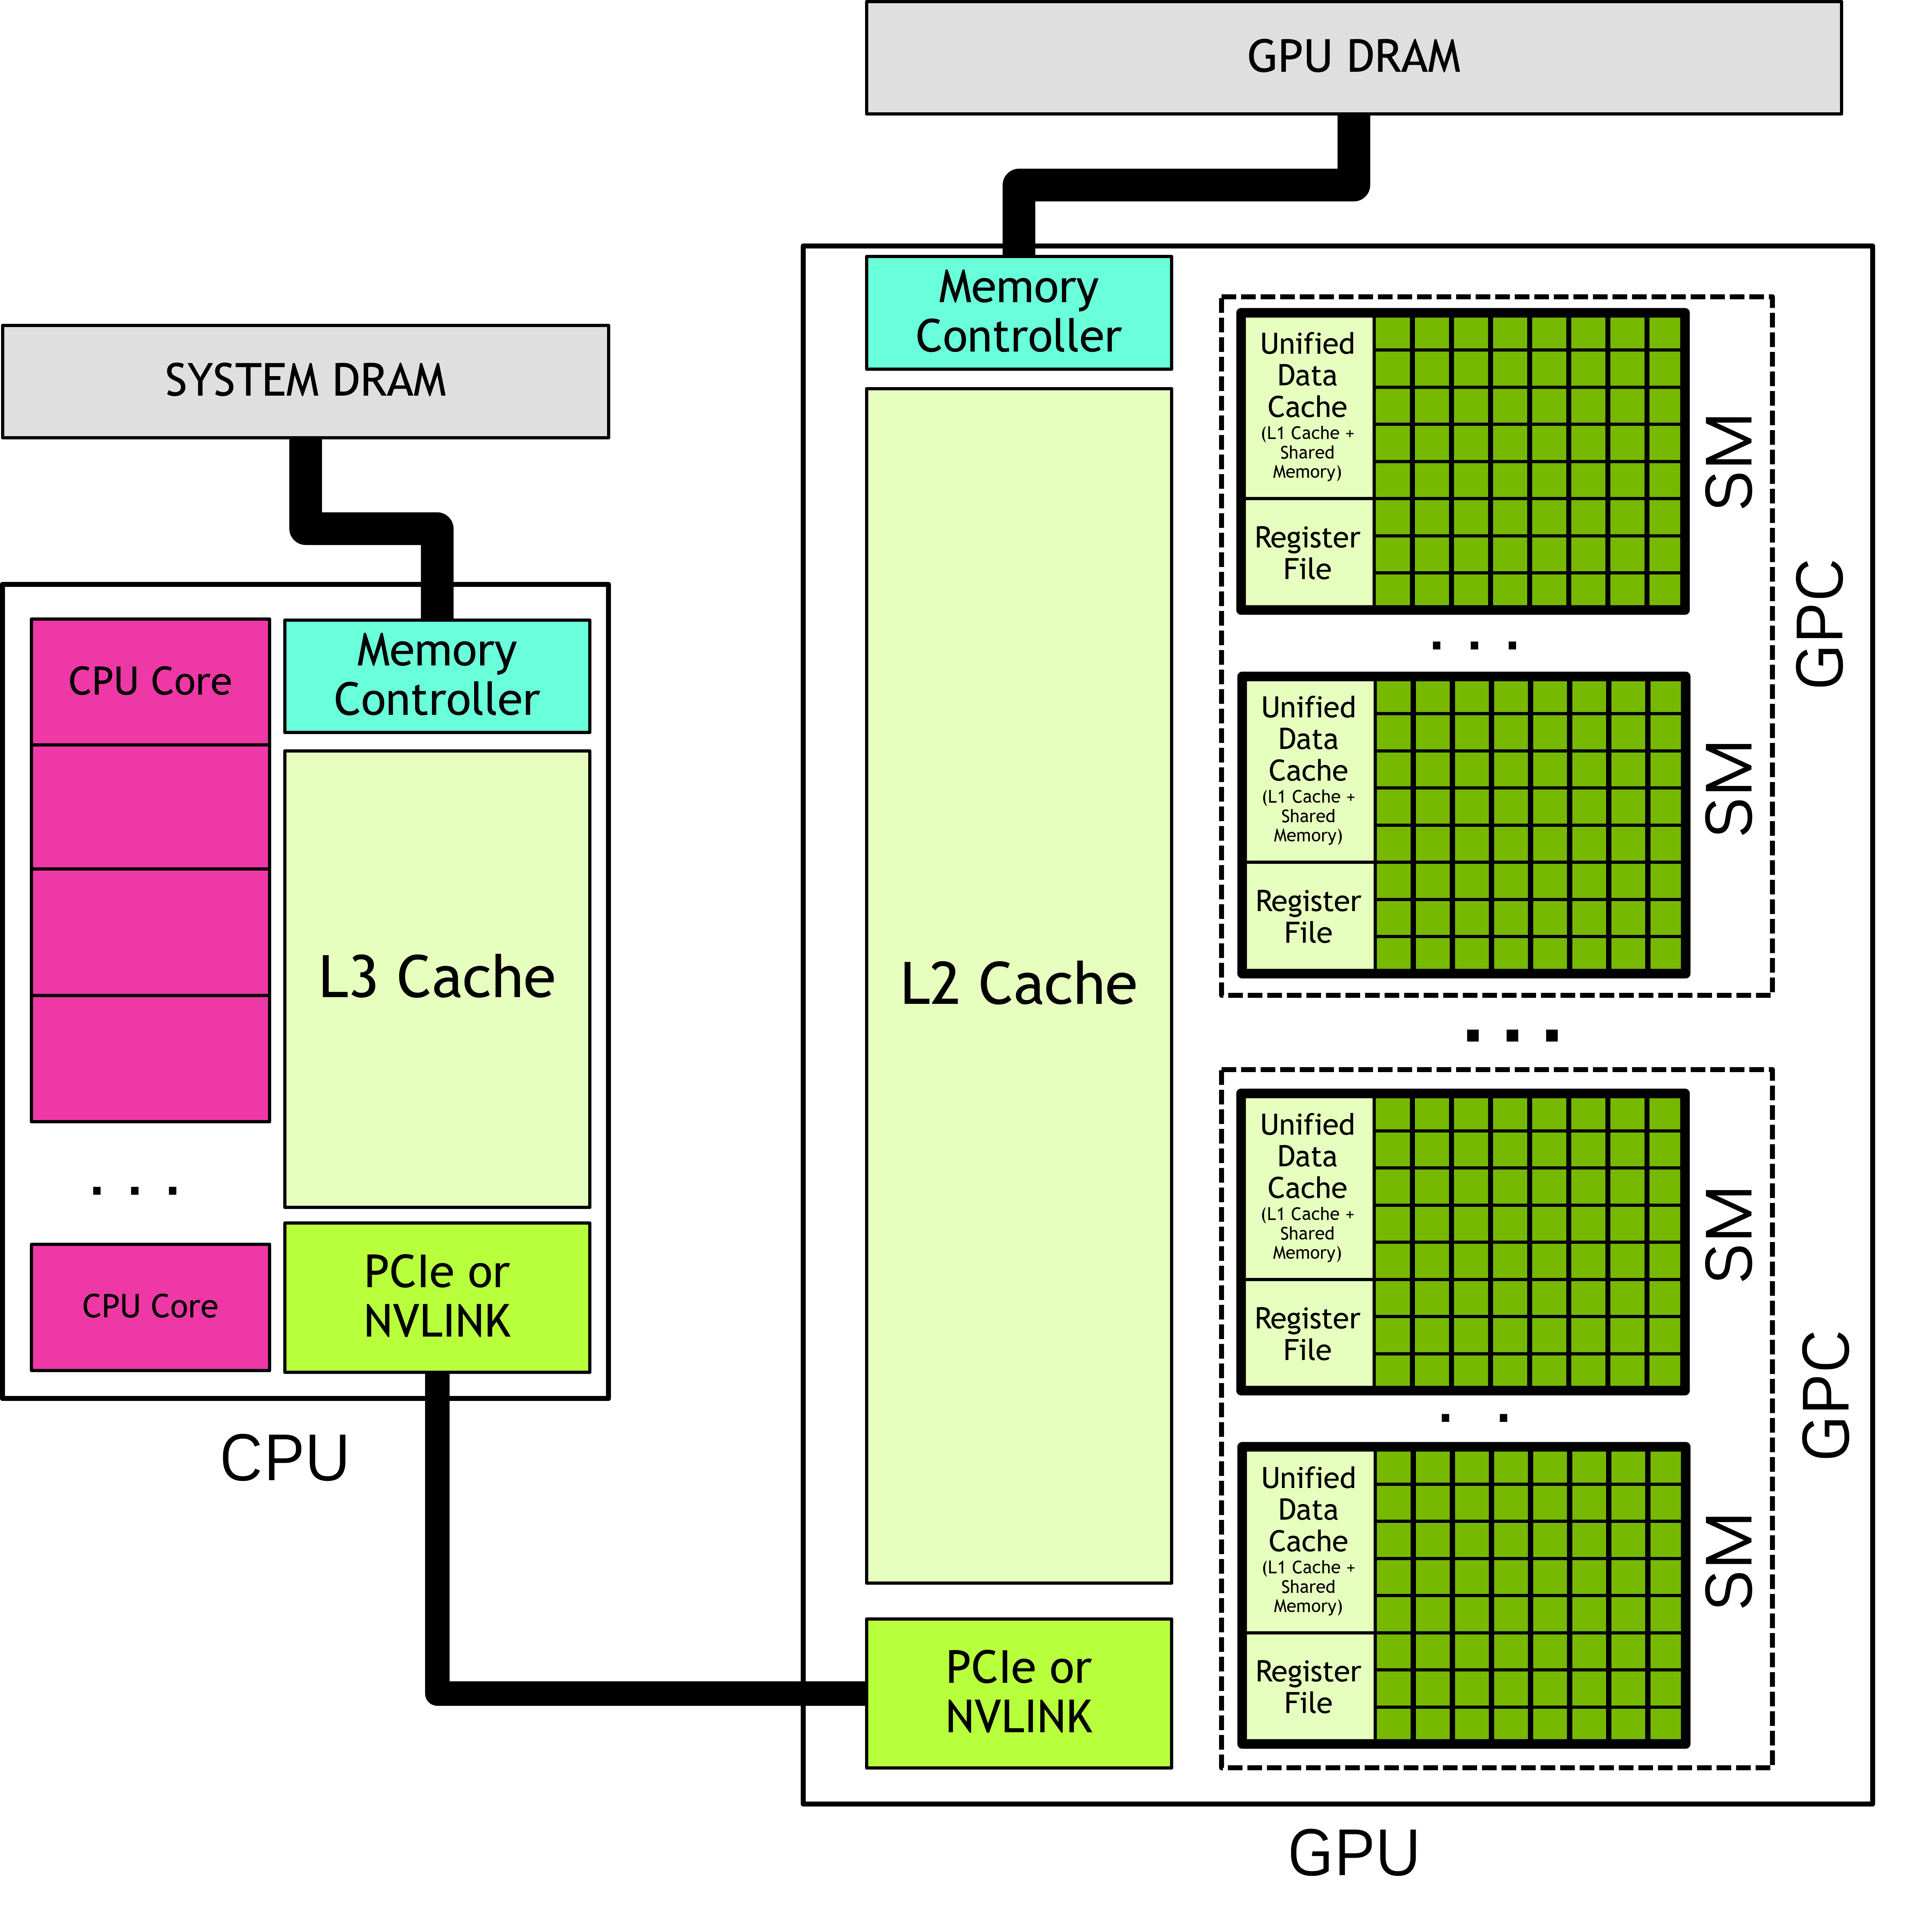
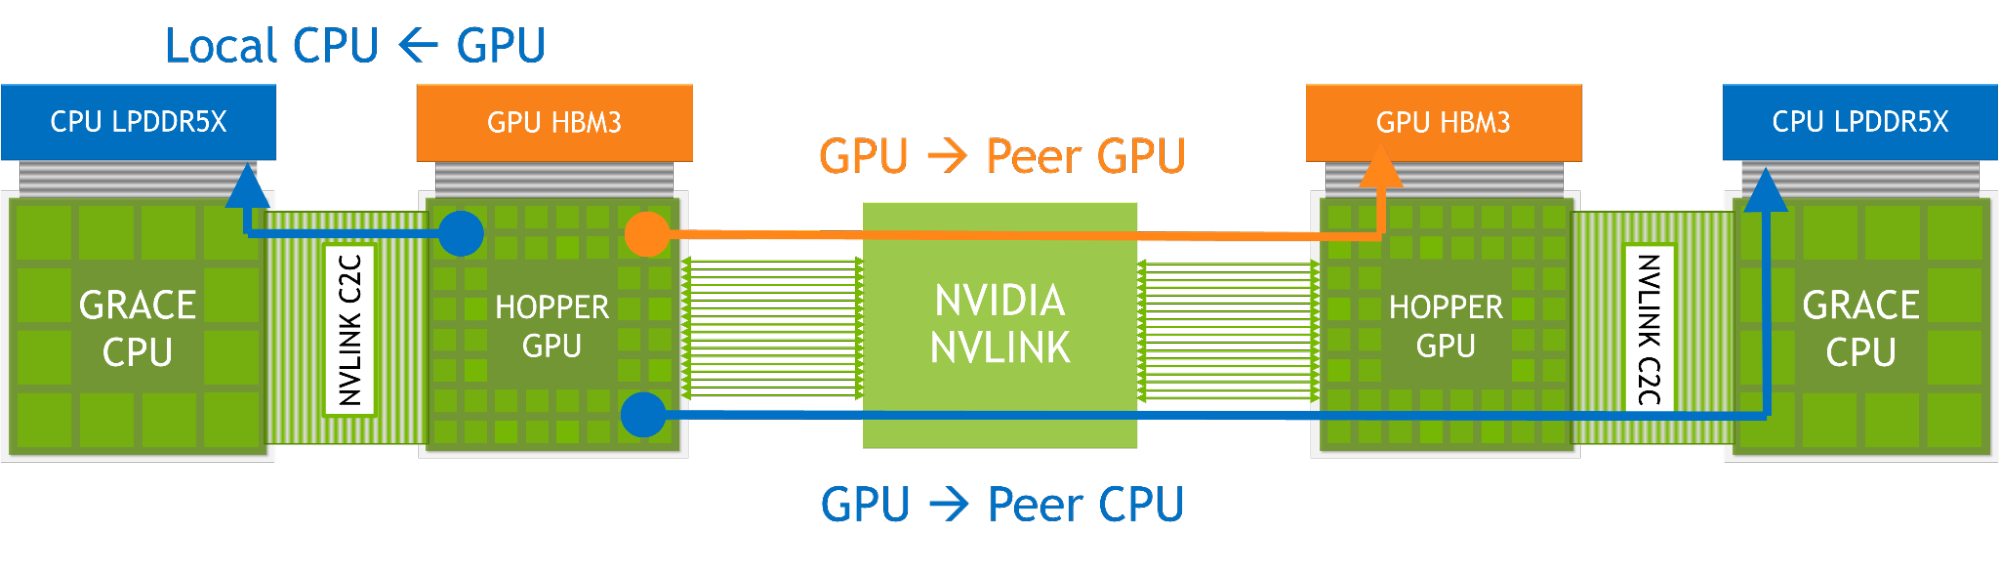
CUDA 编程模型假定使用异构计算系统,即同时包含 GPU 和 CPU 的系统。CPU 及与其直接连接的内存分别称为主机和主机内存。GPU 及与其直接连接的内存分别称为设备和设备内存。在某些片上系统(SoC)中,它们可能是同一封装的一部分。在更大的系统中,可能有多个 CPU 或 GPU。
CUDA 应用在 GPU 上执行部分代码,但应用始终从 CPU 上开始执行。主机代码,即在 CPU 上运行的代码,可以使用 CUDA API 在主机内存与设备内存之间复制数据、启动在 GPU 上执行的代码,以及等待数据复制或 GPU 代码执行完成。CPU 和 GPU 可以同时执行代码,通常通过最大化 CPU 和 GPU 两者的利用率来获得最佳性能。
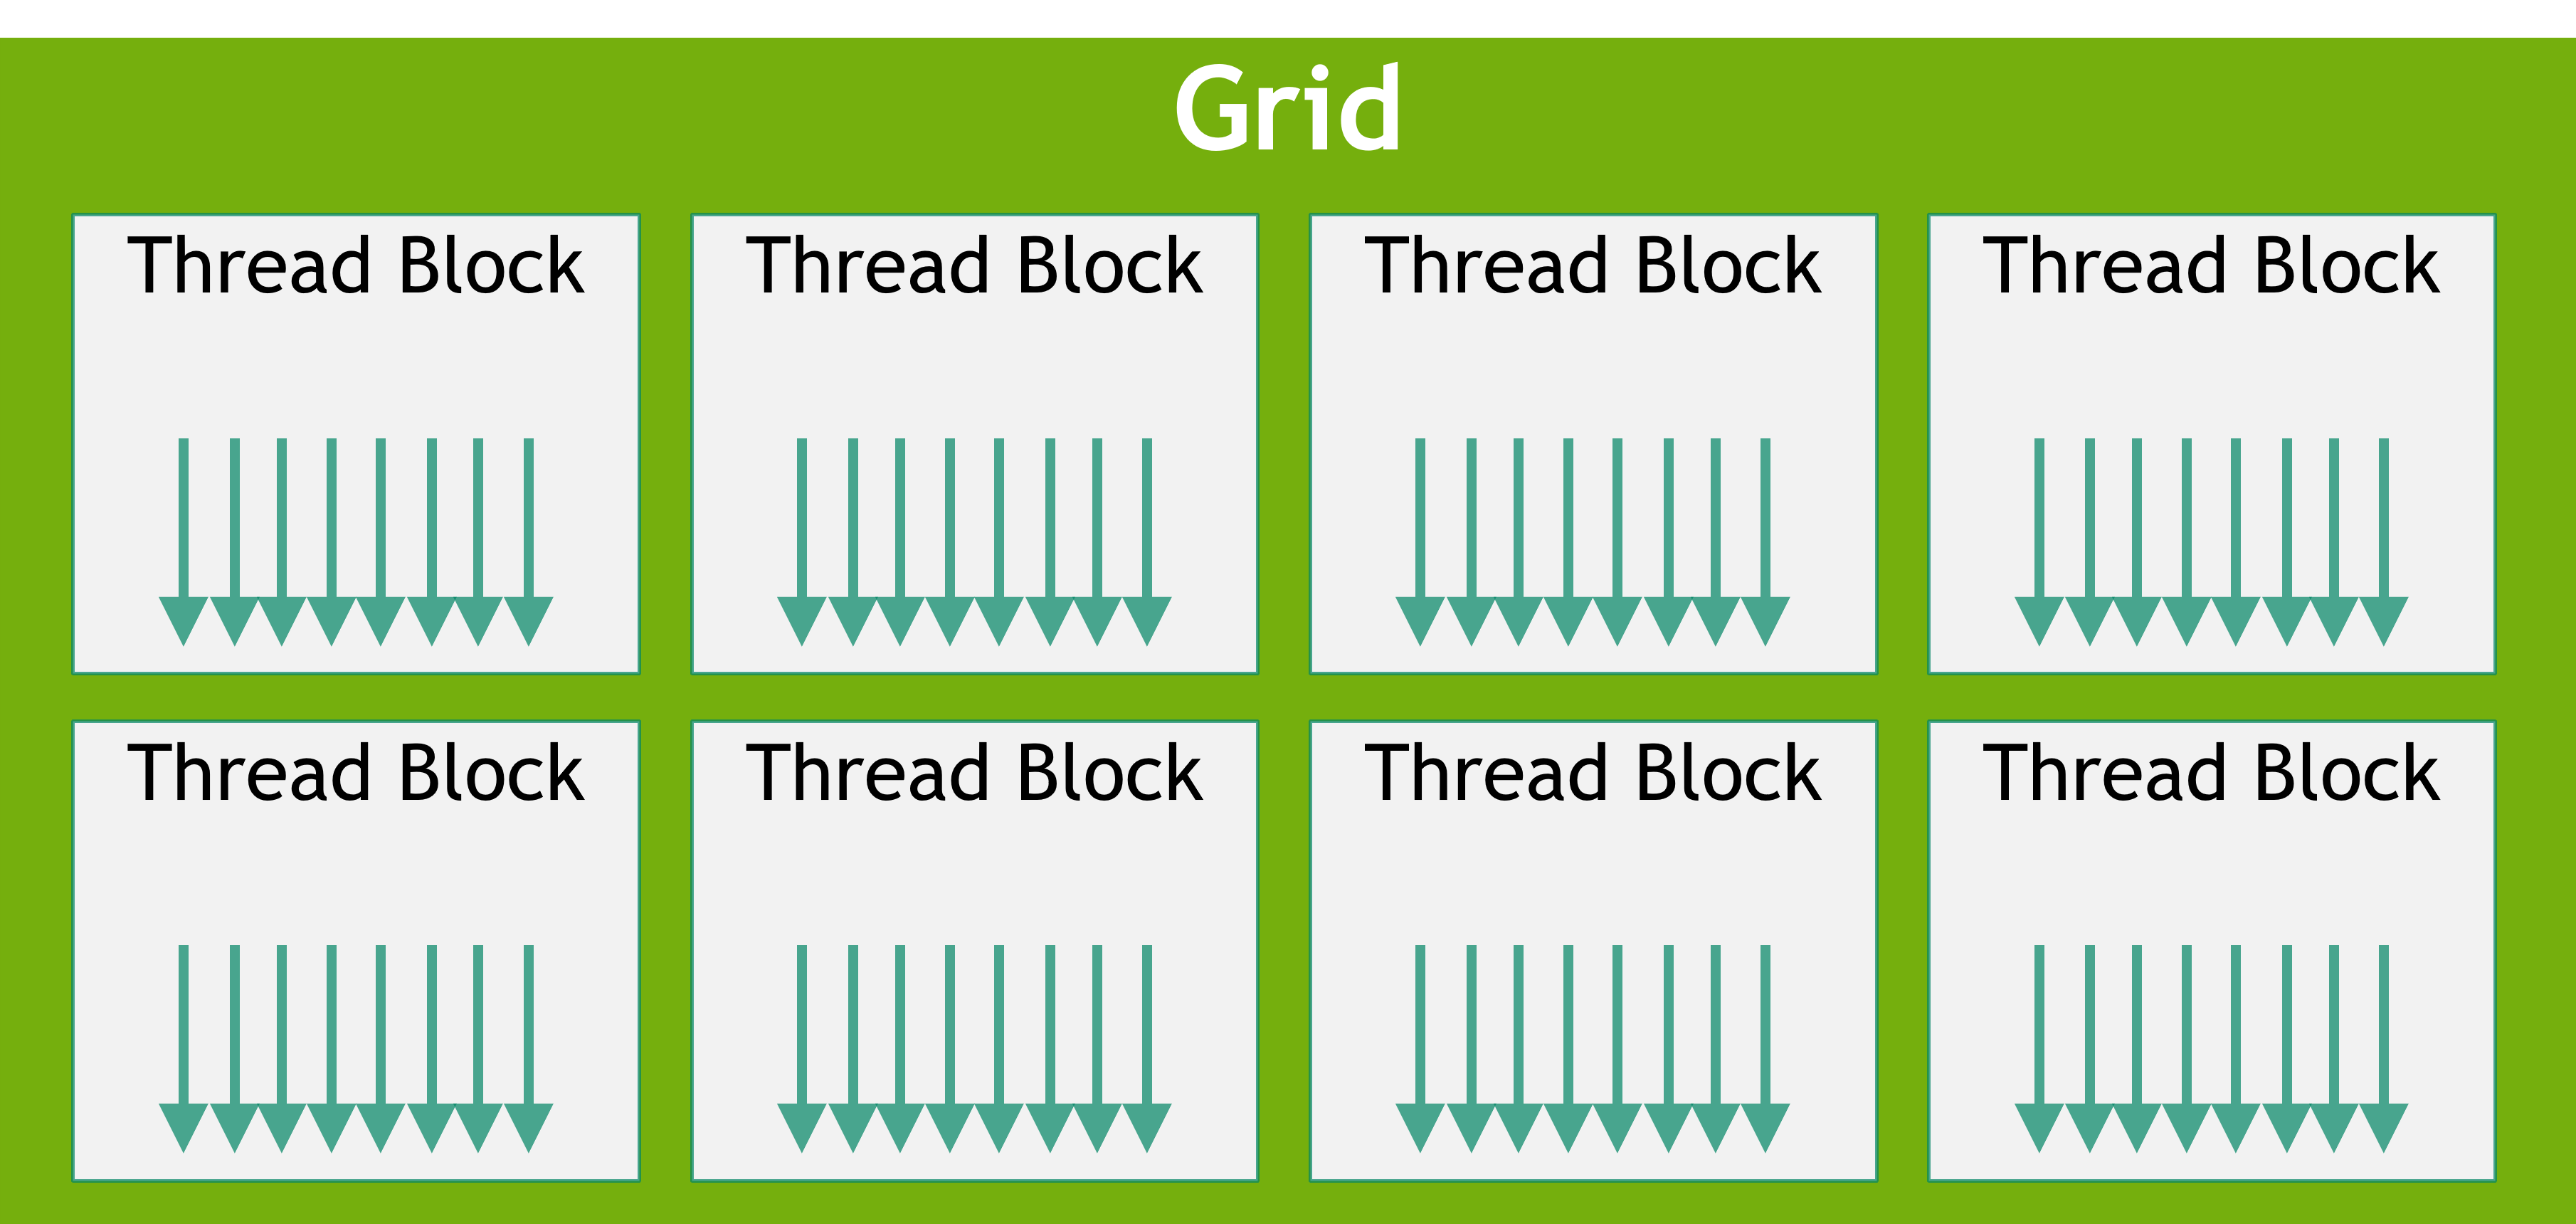
一个线程块的所有线程都在单个 SM 中执行。这使得线程块内的线程能够高效地相互通信和同步。线程块内的所有线程都可以访问片上共享内存,该内存可用于在线程块的线程之间交换信息。
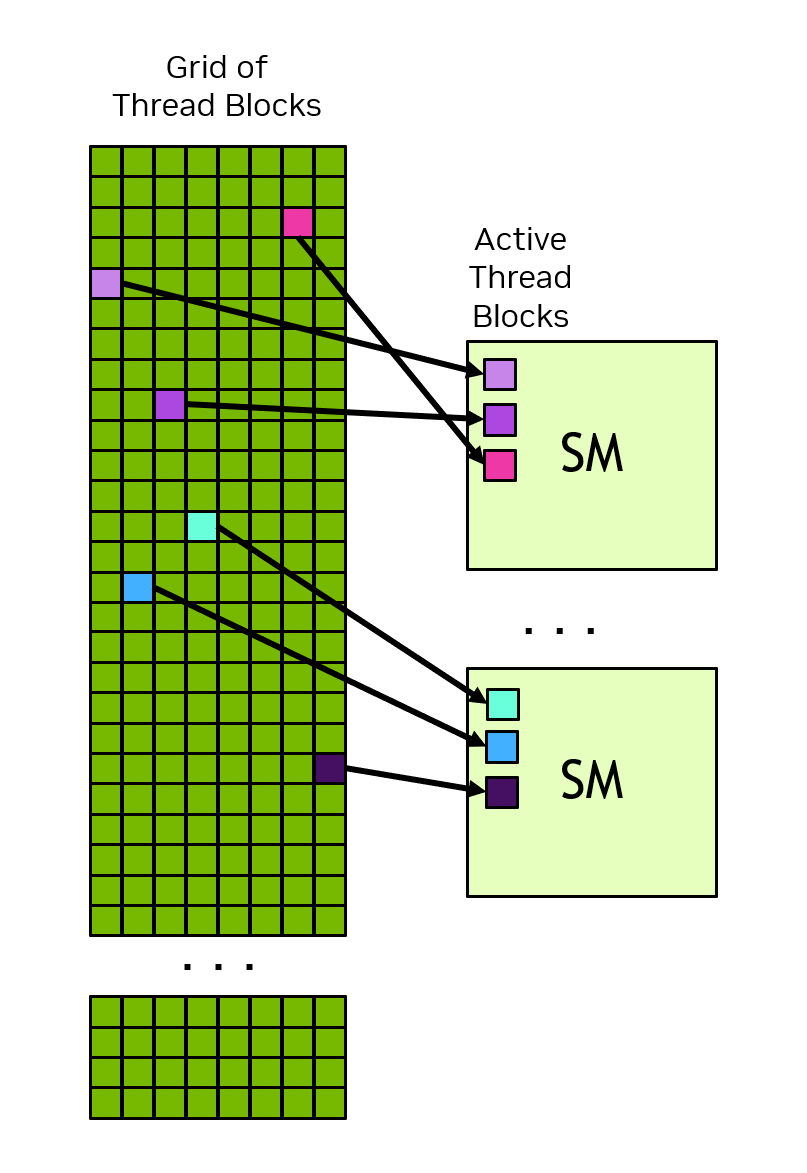
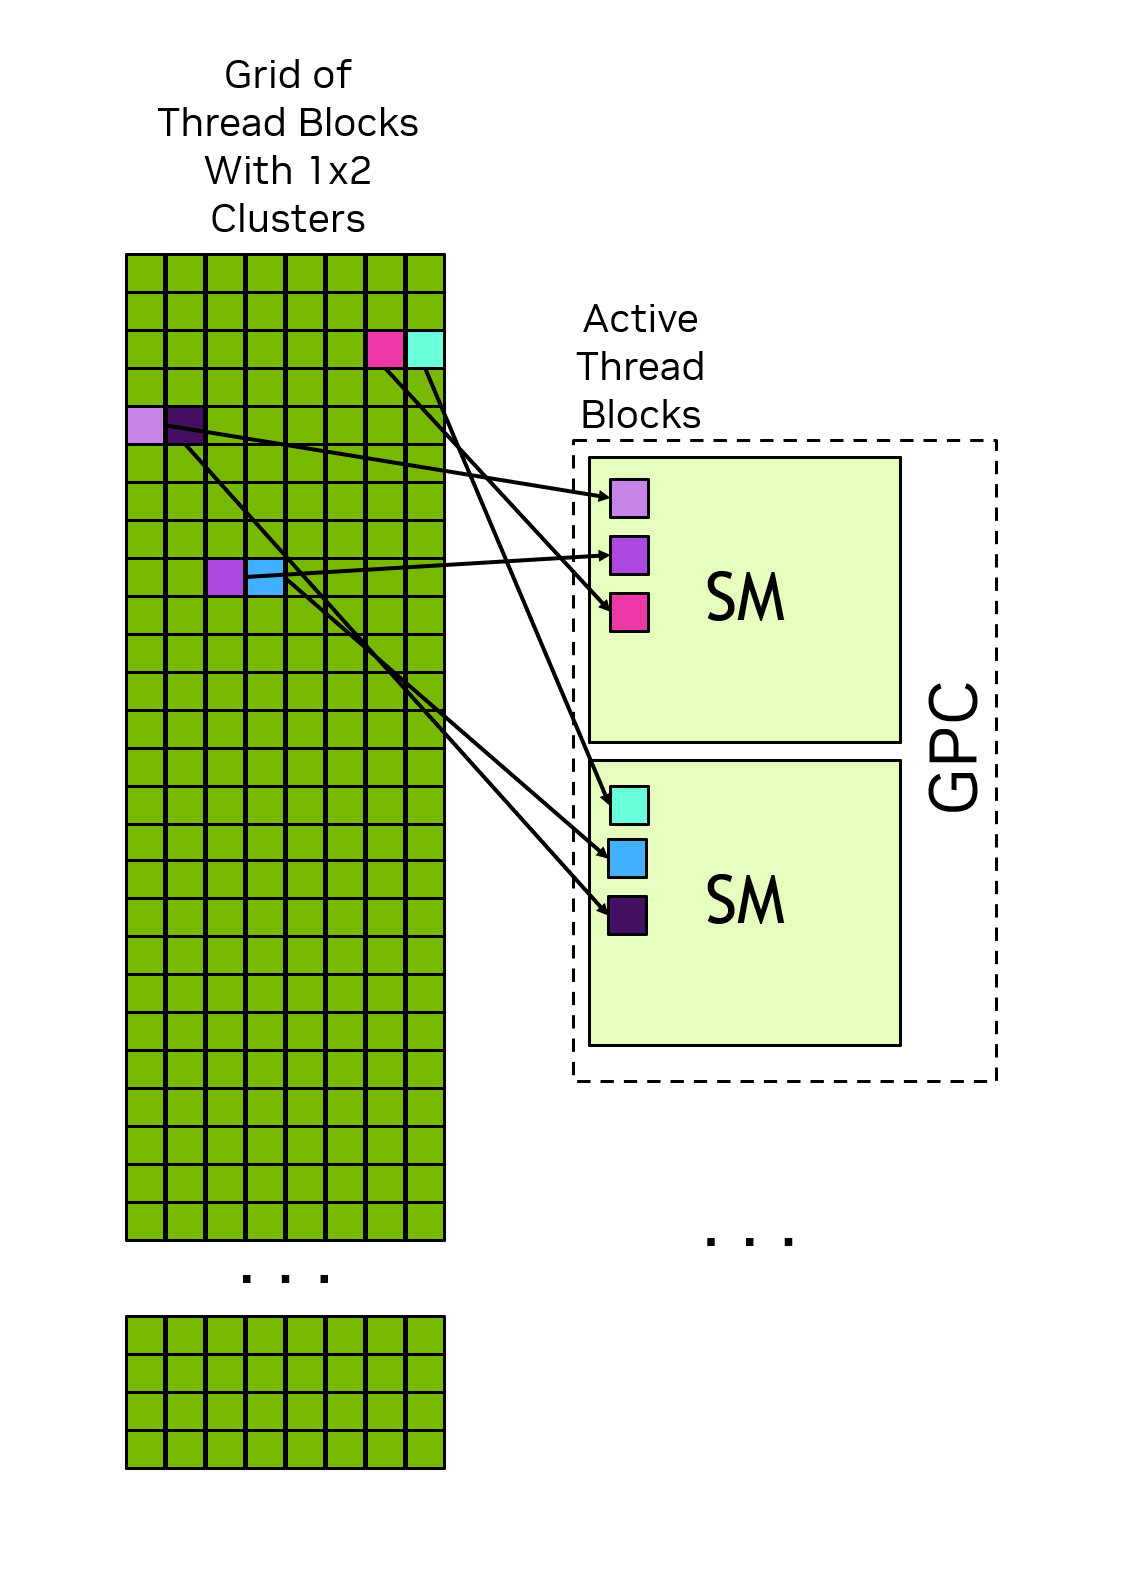
一个网格可能由数百万个线程块组成,而执行该网格的 GPU 可能只有几十个或几百个 SM。一个线程块的所有线程都由单个 SM 执行,并且在大多数情况下[1],会在该 SM 上运行直至完成。线程块之间的调度没有任何保证,因此一个线程块不能依赖其他线程块的结果,因为其他线程块可能必须等到该线程块完成后才能被调度。图 4展示了将网格中的线程块分配给 SM 的示例。
图 4 每个 SM 都有一个或多个活动线程块。在此示例中,每个 SM 同时调度了三个线程块。对于网格中的线程块被分配给 SM 的顺序,没有任何保证。
图内文字中文对照
Grid of Thread Blocks
线程块网格
Active Thread Blocks
活动线程块
SM
流式多处理器
CUDA 编程模型使任意大的网格都能在任何规模的 GPU 上运行,无论 GPU 仅有一个 SM,还是有数千个 SM。为实现这一点,除少数例外情况外,CUDA 编程模型要求不同线程块中的线程之间不存在数据依赖。也就是说,一个线程不应依赖同一网格中其他线程块内线程的结果,也不应与其同步。一个线程块内的所有线程同时在同一个 SM 上运行。网格中的不同线程块被调度到可用的 SM 上,并且可以按任意顺序执行。简而言之,CUDA 编程模型要求线程块能够以任意顺序、并行或串行执行。
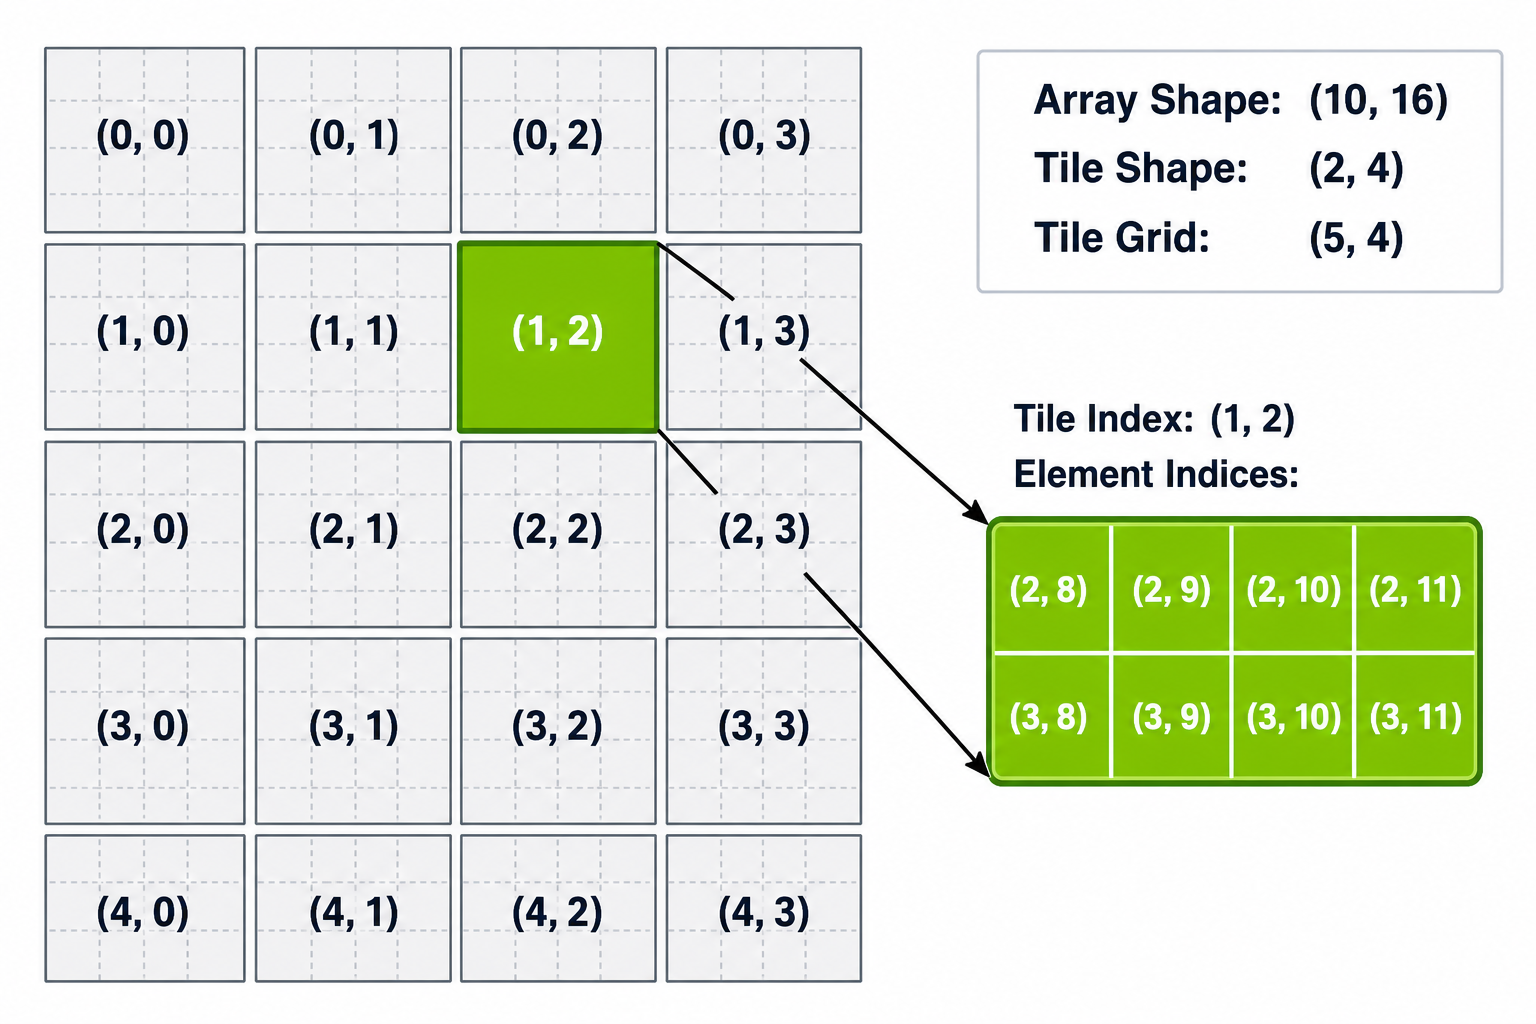
分块是一个多维值集合,仅存在于分块代码中,并且局限于单个线程块。分块是不可变的:对分块执行的每个操作都会产生一个新分块,而不是修改现有分块。与数组不同,分块不一定在内存中具有表示形式;编译器决定如何存储分块数据,可能会使用寄存器、共享内存或 SM 的其他资源。分块的每个维度都必须是 2 的幂,并且必须在编译时已知(也就是说,其值必须能够在核函数执行前确定,而不是在执行期间计算)。分块不能作为核函数参数传递;它们完全在分块代码内创建和使用。
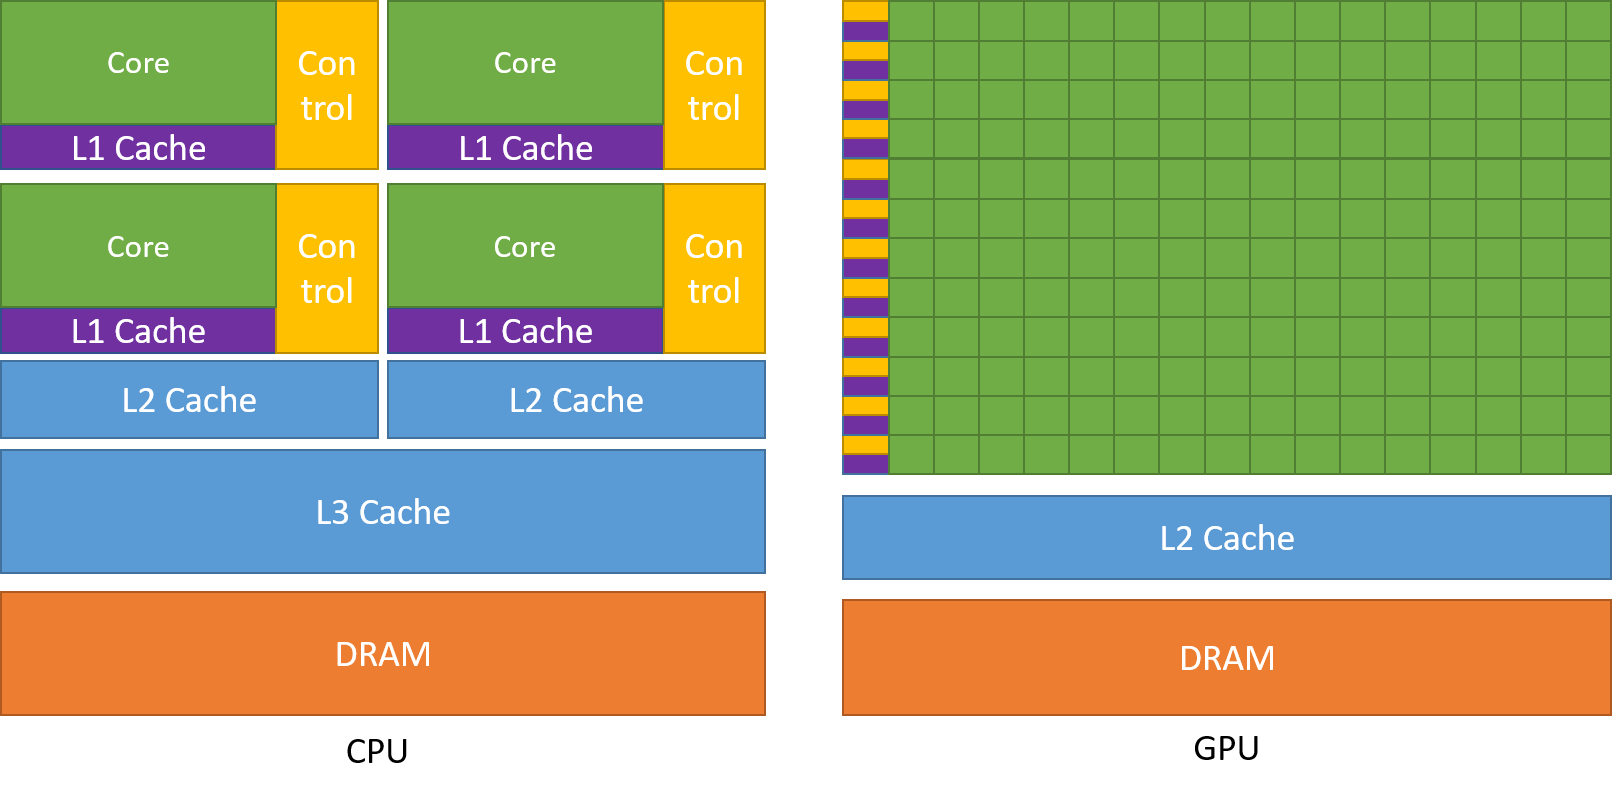
GPU 和 CPU 都具有直接连接的 DRAM 芯片。在具有多个 GPU 的系统中,每个 GPU 都有自己的内存。从设备代码的角度看,连接到 GPU 的 DRAM 称为全局内存,因为 GPU 中的所有 SM 都可以访问它。这一术语并不意味着系统中的任何位置都一定能访问它。连接到一个或多个 CPU 的 DRAM 称为系统内存或主机内存。
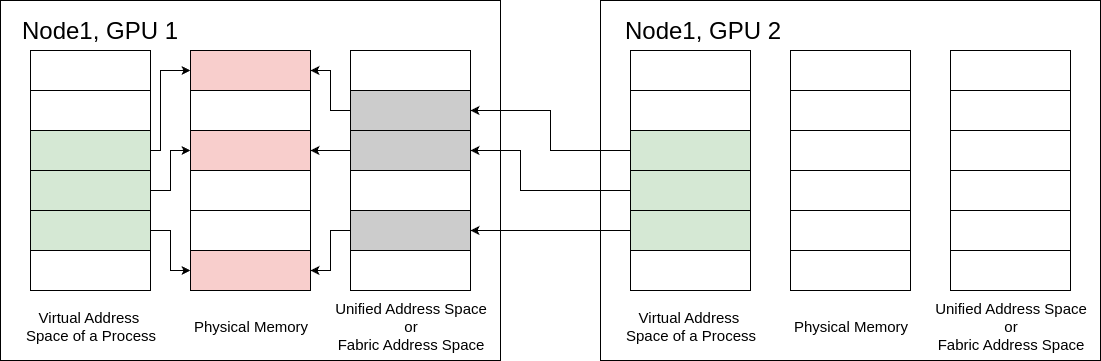
与 CPU 一样,GPU 使用虚拟内存寻址。在目前支持的所有系统上,CPU 和 GPU 使用单一的统一虚拟内存空间。这意味着,系统中每个 GPU 的虚拟内存地址范围都是唯一的,并且与 CPU 及系统中其他每个 GPU 的地址范围不同。对于给定的虚拟内存地址,可以确定该地址位于 GPU 内存还是系统内存中;在具有多个 GPU 的系统上,还可以确定该地址位于哪个 GPU 的内存中。
CUDA 提供了用于分配 GPU 内存、CPU 内存以及在 CPU 和 GPU 的内存分配之间、在一个 GPU 内部或在多 GPU 系统的 GPU 之间进行复制的 API。需要时,可以显式控制数据的局部性。下文讨论的统一内存允许 CUDA 运行时或系统硬件自动处理内存的放置。
除了可编程内存,GPU 还具有 L1 和 L2 缓存。每个 SM 都有一个 L1 缓存,它是统一数据缓存的一部分。一个更大的 L2 缓存由 GPU 内的所有 SM 共享。这可以在图 2的 GPU 框图中看到。每个 SM 还具有一个独立的常量缓存,用于缓存全局内存中已声明在核函数整个生命周期内保持不变的值。编译器也可能将核函数参数放入常量内存。这使核函数参数能够在 SM 中独立于 L1 数据缓存进行缓存,从而可以提高核函数性能。
1.2.3.4. 统一内存
当应用程序显式地在 GPU 或 CPU 上分配内存时,该内存只能由在该设备上运行的代码访问。也就是说,CPU 内存只能由 CPU 代码访问,而 GPU 内存只能由在 GPU 上运行的核函数访问[2]。用于在 CPU 和 GPU 之间复制内存的 CUDA API 可用来在适当的时间将数据显式复制到正确的内存中。
一项称为统一内存的 CUDA 功能允许应用程序分配可由 CPU 或 GPU 访问的内存。CUDA 运行时或底层硬件会在需要时启用访问,或将数据重新放置到正确的位置。即便使用统一内存,也要尽量减少内存迁移,并尽可能从与数据所在内存直接相连的处理器访问数据,才能获得最佳性能。
CUDA Toolkit是一组库、头文件和工具,用于编写、构建和分析利用 GPU 计算的软件。CUDA Toolkit 是独立于 NVIDIA 驱动程序的软件产品
CUDA 运行时是 CUDA Toolkit 所提供的库中的一个特例。CUDA 运行时提供 API 和一些语言扩展,用于处理常见任务,例如分配内存、在 GPU 与其他 GPU 或 CPU 之间复制数据,以及启动核函数。CUDA 运行时的 API 组件被称为 CUDA 运行时 API。
CUDA 兼容性文档提供了有关不同 GPU、NVIDIA 驱动程序和 CUDA Toolkit 版本之间兼容性的完整详细信息。
1.3.2.1. CUDA 运行时 API 与 CUDA 驱动程序 API
CUDA 运行时 API 基于一个称为CUDA 驱动程序 API的更底层 API 实现,后者是 NVIDIA 驱动程序公开的 API。本指南重点介绍 CUDA 运行时 API 所公开的 API。如果需要,仅使用驱动程序 API 也可以实现所有相同的功能。有些功能只能通过驱动程序 API 使用。应用程序可以使用其中一种 API,也可以让两种 API 互操作。CUDA 驱动程序 API一节介绍了运行时 API 与驱动程序 API 之间的互操作。
本指南假定已安装 CUDA Toolkit 和 NVIDIA 驱动程序,并且系统中配备了受支持的 NVIDIA GPU。有关安装所需 CUDA 组件的说明,请参阅《CUDA 快速入门指南》。
2.1.1. 使用 NVCC 编译
用 C++ 编写的 GPU 代码使用 NVIDIA Cuda Compiler,即nvcc进行编译。nvcc是一个编译器驱动程序,它简化了编译 C++ 或 PTX 代码的过程:它提供简单且熟悉的命令行选项,并通过调用实现各个编译阶段的一组工具来执行这些选项。
本指南将展示nvcc命令行,这些命令行可用于安装了 CUDA Toolkit 的任何 Linux 系统、Windows 命令行或 power shell,也可用于装有 CUDA Toolkit 的 Windows Subsystem for Linux。本指南的nvcc 章节涵盖了nvcc的常见用例,完整文档由nvcc 用户手册提供。
__global__voidvecAdd(float*A,float*B,float*C){// calculate which element this thread is responsible for computingintworkIndex=threadIdx.x+blockDim.x*blockIdx.x;// Perform computationC[workIndex]=A[workIndex]+B[workIndex];}intmain(){...// A, B, and C are vectors of 1024 elementsvecAdd<<<4,256>>>(A,B,C);...}
__global__voidvecAdd(float*A,float*B,float*C,intvectorLength){// calculate which element this thread is responsible for computingintworkIndex=threadIdx.x+blockDim.x*blockIdx.x;if(workIndex<vectorLength){// Perform computationC[workIndex]=A[workIndex]+B[workIndex];}}
// vectorLength is an integer storing number of elements in the vectorintthreads=256;intblocks=(vectorLength+threads-1)/threads;vecAdd<<<blocks,threads>>>(devA,devB,devC,vectorLength);
// vectorLength is an integer storing number of elements in the vectorintthreads=256;intblocks=cuda::ceil_div(vectorLength,threads);vecAdd<<<blocks,threads>>>(devA,devB,devC,vectorLength);
统一内存是 CUDA 运行时的一项功能,它让 NVIDIA 驱动程序管理主机与一个或多个设备之间的数据移动。内存通过cudaMallocManagedAPI 分配,或通过使用__managed__说明符声明变量来分配。无论 GPU 还是 CPU 尝试访问该内存,NVIDIA 驱动程序都会确保它能够访问该内存。
下面的代码展示了一个用于启动vecAdd核函数的完整函数,它为将在 GPU 上使用的输入和输出向量使用统一内存。cudaMallocManaged分配可从 CPU 或 GPU 访问的缓冲区。这些缓冲区使用cudaFree释放。
voidunifiedMemExample(intvectorLength){// Pointers to memory vectorsfloat*A=nullptr;float*B=nullptr;float*C=nullptr;float*comparisonResult=(float*)malloc(vectorLength*sizeof(float));// Use unified memory to allocate bufferscudaMallocManaged(&A,vectorLength*sizeof(float));cudaMallocManaged(&B,vectorLength*sizeof(float));cudaMallocManaged(&C,vectorLength*sizeof(float));// Initialize vectors on the hostinitArray(A,vectorLength);initArray(B,vectorLength);// Launch the kernel. Unified memory will make sure A, B, and C are// accessible to the GPUintthreads=256;intblocks=cuda::ceil_div(vectorLength,threads);vecAdd<<<blocks,threads>>>(A,B,C,vectorLength);// Wait for the kernel to complete executioncudaDeviceSynchronize();// Perform computation serially on CPU for comparisonserialVecAdd(A,B,comparisonResult,vectorLength);// Confirm that CPU and GPU got the same answerif(vectorApproximatelyEqual(C,comparisonResult,vectorLength)){printf("Unified Memory: CPU and GPU answers match\n");}else{printf("Unified Memory: Error - CPU and GPU answers do not match\n");}// Clean UpcudaFree(A);cudaFree(B);cudaFree(C);free(comparisonResult);}
CUDA 支持的所有操作系统和 GPU 都支持统一内存,不过其底层机制和性能可能因系统架构而异。统一内存提供了更多详细信息。在某些 Linux 系统上(例如具有地址转换服务或异构内存管理的系统),所有系统内存都会自动成为统一内存,无需使用cudaMallocManaged或__managed__说明符。
2.1.3.2. 显式内存管理
显式管理内存分配和内存空间之间的数据迁移有助于提高应用程序性能,不过这确实会使代码更加冗长。下面的代码使用cudaMalloc在 GPU 上显式分配内存。GPU 上的内存使用cudaFreeAPI 释放,这与前一个示例中用于统一内存的 API 相同。
voidexplicitMemExample(intvectorLength){// Pointers for host memoryfloat*A=nullptr;float*B=nullptr;float*C=nullptr;float*comparisonResult=(float*)malloc(vectorLength*sizeof(float));// Pointers for device memoryfloat*devA=nullptr;float*devB=nullptr;float*devC=nullptr;//Allocate Host Memory using cudaMallocHost API. This is best practice// when buffers will be used for copies between CPU and GPU memorycudaMallocHost(&A,vectorLength*sizeof(float));cudaMallocHost(&B,vectorLength*sizeof(float));cudaMallocHost(&C,vectorLength*sizeof(float));// Initialize vectors on the hostinitArray(A,vectorLength);initArray(B,vectorLength);// start-allocate-and-copy// Allocate memory on the GPUcudaMalloc(&devA,vectorLength*sizeof(float));cudaMalloc(&devB,vectorLength*sizeof(float));cudaMalloc(&devC,vectorLength*sizeof(float));// Copy data to the GPUcudaMemcpy(devA,A,vectorLength*sizeof(float),cudaMemcpyDefault);cudaMemcpy(devB,B,vectorLength*sizeof(float),cudaMemcpyDefault);cudaMemset(devC,0,vectorLength*sizeof(float));// end-allocate-and-copy// Launch the kernelintthreads=256;intblocks=cuda::ceil_div(vectorLength,threads);vecAdd<<<blocks,threads>>>(devA,devB,devC,vectorLength);// wait for kernel execution to completecudaDeviceSynchronize();// Copy results back to hostcudaMemcpy(C,devC,vectorLength*sizeof(float),cudaMemcpyDefault);// Perform computation serially on CPU for comparisonserialVecAdd(A,B,comparisonResult,vectorLength);// Confirm that CPU and GPU got the same answerif(vectorApproximatelyEqual(C,comparisonResult,vectorLength)){printf("Explicit Memory: CPU and GPU answers match\n");}else{printf("Explicit Memory: Error - CPU and GPU answers to not match\n");}// clean upcudaFree(devA);cudaFree(devB);cudaFree(devC);cudaFreeHost(A);cudaFreeHost(B);cudaFreeHost(C);free(comparisonResult);}
CUDA APIcudaMemcpy用于将数据从位于 CPU 上的缓冲区复制到位于 GPU 上的缓冲区。除了目标指针、源指针和以字节为单位的大小之外,cudaMemcpy的最后一个参数是cudaMemcpyKind_t。它可以具有如下取值:
cudaMemcpyHostToDevice用于从 CPU 到 GPU 的复制
cudaMemcpyDeviceToHost用于从 GPU 到 CPU 的复制
cudaMemcpyDeviceToDevice用于 GPU 内部或 GPU 之间的复制
在此示例中,cudaMemcpyDefault作为最后一个参数传递给cudaMemcpy。这使 CUDA 使用源指针和目标指针的值来确定要执行的复制类型。
cudaMemcpyAPI 是同步的。也就是说,它直到复制完成后才会返回。异步复制在在 CUDA 流中启动内存传输中介绍。
该代码使用cudaMallocHost在 CPU 上分配内存。这会在主机上分配页锁定内存,这种内存可以提高复制性能,并且是异步内存传输所必需的。通常,对于将用于与 GPU 进行双向数据传输的 CPU 缓冲区,使用页锁定内存是一种良好做法。如果过多的主机内存被页锁定,某些系统上的性能可能会下降。最佳做法是仅对将用于向 GPU 发送数据或从 GPU 接收数据的缓冲区进行页锁定。
#include<cuda_runtime_api.h>#include<memory.h>#include<cstdlib>#include<ctime>#include<stdio.h>#include<cuda/cmath>__global__voidvecAdd(float*A,float*B,float*C,intvectorLength){intworkIndex=threadIdx.x+blockIdx.x*blockDim.x;if(workIndex<vectorLength){C[workIndex]=A[workIndex]+B[workIndex];}}voidinitArray(float*A,intlength){std::srand(std::time({}));for(inti=0;i<length;i++){A[i]=rand()/(float)RAND_MAX;}}voidserialVecAdd(float*A,float*B,float*C,intlength){for(inti=0;i<length;i++){C[i]=A[i]+B[i];}}boolvectorApproximatelyEqual(float*A,float*B,intlength,floatepsilon=0.00001){for(inti=0;i<length;i++){if(fabs(A[i]-B[i])>epsilon){printf("Index %d mismatch: %f != %f",i,A[i],B[i]);returnfalse;}}returntrue;}//unified-memory-beginvoidunifiedMemExample(intvectorLength){// Pointers to memory vectorsfloat*A=nullptr;float*B=nullptr;float*C=nullptr;float*comparisonResult=(float*)malloc(vectorLength*sizeof(float));// Use unified memory to allocate bufferscudaMallocManaged(&A,vectorLength*sizeof(float));cudaMallocManaged(&B,vectorLength*sizeof(float));cudaMallocManaged(&C,vectorLength*sizeof(float));// Initialize vectors on the hostinitArray(A,vectorLength);initArray(B,vectorLength);// Launch the kernel. Unified memory will make sure A, B, and C are// accessible to the GPUintthreads=256;intblocks=cuda::ceil_div(vectorLength,threads);vecAdd<<<blocks,threads>>>(A,B,C,vectorLength);// Wait for the kernel to complete executioncudaDeviceSynchronize();// Perform computation serially on CPU for comparisonserialVecAdd(A,B,comparisonResult,vectorLength);// Confirm that CPU and GPU got the same answerif(vectorApproximatelyEqual(C,comparisonResult,vectorLength)){printf("Unified Memory: CPU and GPU answers match\n");}else{printf("Unified Memory: Error - CPU and GPU answers do not match\n");}// Clean UpcudaFree(A);cudaFree(B);cudaFree(C);free(comparisonResult);}//unified-memory-endintmain(intargc,char**argv){intvectorLength=1024;if(argc>=2){vectorLength=std::atoi(argv[1]);}unifiedMemExample(vectorLength);return0;}
#include<cuda_runtime_api.h>#include<memory.h>#include<cstdlib>#include<ctime>#include<stdio.h>#include<cuda/cmath>__global__voidvecAdd(float*A,float*B,float*C,intvectorLength){intworkIndex=threadIdx.x+blockIdx.x*blockDim.x;if(workIndex<vectorLength){C[workIndex]=A[workIndex]+B[workIndex];}}voidinitArray(float*A,intlength){std::srand(std::time({}));for(inti=0;i<length;i++){A[i]=rand()/(float)RAND_MAX;}}voidserialVecAdd(float*A,float*B,float*C,intlength){for(inti=0;i<length;i++){C[i]=A[i]+B[i];}}boolvectorApproximatelyEqual(float*A,float*B,intlength,floatepsilon=0.00001){for(inti=0;i<length;i++){if(fabs(A[i]-B[i])>epsilon){printf("Index %d mismatch: %f != %f",i,A[i],B[i]);returnfalse;}}returntrue;}//explicit-memory-beginvoidexplicitMemExample(intvectorLength){// Pointers for host memoryfloat*A=nullptr;float*B=nullptr;float*C=nullptr;float*comparisonResult=(float*)malloc(vectorLength*sizeof(float));// Pointers for device memoryfloat*devA=nullptr;float*devB=nullptr;float*devC=nullptr;//Allocate Host Memory using cudaMallocHost API. This is best practice// when buffers will be used for copies between CPU and GPU memorycudaMallocHost(&A,vectorLength*sizeof(float));cudaMallocHost(&B,vectorLength*sizeof(float));cudaMallocHost(&C,vectorLength*sizeof(float));// Initialize vectors on the hostinitArray(A,vectorLength);initArray(B,vectorLength);// start-allocate-and-copy// Allocate memory on the GPUcudaMalloc(&devA,vectorLength*sizeof(float));cudaMalloc(&devB,vectorLength*sizeof(float));cudaMalloc(&devC,vectorLength*sizeof(float));// Copy data to the GPUcudaMemcpy(devA,A,vectorLength*sizeof(float),cudaMemcpyDefault);cudaMemcpy(devB,B,vectorLength*sizeof(float),cudaMemcpyDefault);cudaMemset(devC,0,vectorLength*sizeof(float));// end-allocate-and-copy// Launch the kernelintthreads=256;intblocks=cuda::ceil_div(vectorLength,threads);vecAdd<<<blocks,threads>>>(devA,devB,devC,vectorLength);// wait for kernel execution to completecudaDeviceSynchronize();// Copy results back to hostcudaMemcpy(C,devC,vectorLength*sizeof(float),cudaMemcpyDefault);// Perform computation serially on CPU for comparisonserialVecAdd(A,B,comparisonResult,vectorLength);// Confirm that CPU and GPU got the same answerif(vectorApproximatelyEqual(C,comparisonResult,vectorLength)){printf("Explicit Memory: CPU and GPU answers match\n");}else{printf("Explicit Memory: Error - CPU and GPU answers to not match\n");}// clean upcudaFree(devA);cudaFree(devB);cudaFree(devC);cudaFreeHost(A);cudaFreeHost(B);cudaFreeHost(C);free(comparisonResult);}//explicit-memory-endintmain(intargc,char**argv){intvectorLength=1024;if(argc>=2){vectorLength=std::atoi(argv[1]);}explicitMemExample(vectorLength);return0;}
在第 3.2.4 节这一节中,介绍了 CUDA 同步原语,它们提供非常细粒度的控制,以最大限度地提高性能和资源利用率。
2.1.6. 运行时初始化
CUDA 运行时为系统中的每个设备创建一个CUDA 上下文。该上下文是此设备的主上下文,在首次调用需要此设备上的活动上下文的运行时函数时进行初始化。该上下文由应用程序的所有主机线程共享。作为上下文创建过程的一部分,设备代码会在必要时进行即时编译,并加载到设备内存中。所有这一切都是透明进行的。可以通过驱动程序 API 访问 CUDA 运行时创建的主上下文,以实现互操作,如运行时 API 与驱动程序 API 之间的互操作性中所述。
从 CUDA 12.0 开始,cudaInitDevice和cudaSetDevice调用会初始化运行时以及与指定设备关联的主上下文。如果运行时 API 请求发生在这些调用之前,运行时将隐式使用设备 0,并根据需要自行初始化以处理这些请求。在对运行时函数调用计时以及解读首次调用运行时所返回的错误码时,这一点很重要。在 CUDA 12.0 之前,cudaSetDevice不会初始化运行时。
cudaDeviceReset会销毁当前设备的主上下文。如果在主上下文被销毁后调用 CUDA 运行时 API,则会为该设备创建一个新的主上下文。
注意
CUDA 接口使用全局状态,该状态在主机程序启动期间初始化,并在主机程序终止期间销毁。在程序启动期间或 main 之后的程序终止期间使用任何这些接口(无论隐式还是显式),都会导致未定义行为。
从 CUDA 12.0 开始,cudaSetDevice在更改主机线程的当前设备后,如果运行时尚未初始化,就会显式初始化运行时。早期版本的 CUDA 会延迟新设备上的运行时初始化,直到cudaSetDevice之后首次调用运行时函数时才进行。因此,检查cudaSetDevice的返回值以发现初始化错误非常重要。
参考手册中错误处理和版本管理部分的运行时函数不会初始化运行时。
2.1.7. CUDA 中的错误检查
每个 CUDA API 都会返回一个枚举类型cudaError_t的值。在示例代码中,通常不会检查这些错误。在生产应用程序中,最佳实践是始终检查和处理每次 CUDA API 调用的返回值。没有错误时,返回值为cudaSuccess。许多应用程序选择实现一个实用宏,如下所示
CUDA 核函数启动和许多运行时 API 都是异步的。异步 CUDA 运行时 API 将在异步执行中详细讨论。每当发生错误时,CUDA 错误状态都会被设置并覆盖。这意味着,异步操作执行期间发生的错误,只有在下一次检查错误状态时才会报告。如前所述,这可能是对cudaGetLastError、cudaPeekAtLastError的调用,也可能是任何返回cudaError_t的 CUDA API 调用。
CUDA 运行时 API 函数返回错误时,不会清除错误状态。这意味着,对于异步错误(例如核函数的无效内存访问),每个 CUDA 运行时 API 都会返回其错误码,直到通过调用cudaGetLastError清除错误状态为止。
vecAdd<<<blocks,threads>>>(devA,devB,devC);// check error state after kernel launchCUDA_CHECK(cudaGetLastError());// wait for kernel execution to complete// The CUDA_CHECK will report errors that occurred during execution of the kernelCUDA_CHECK(cudaDeviceSynchronize());
将CUDA_LOG_FILE设置为stdout或stderr,会分别打印到标准输出和标准错误。使用CUDA_LOG_FILE环境变量,即使应用程序没有针对 CUDA 返回值实现适当的错误检查,也能够捕获并识别 CUDA 错误。这种方法对于调试可能极为有效,但仅靠该环境变量并不能让应用程序在运行时处理 CUDA 错误并从中恢复。CUDA 的错误日志管理功能还允许向驱动程序注册一个回调函数,每当检测到错误时就会调用该函数。这可用于在运行时捕获和处理错误,还可将 CUDA 错误日志记录无缝集成到应用程序现有的日志系统中。
第 4.9 节给出了 CUDA 错误日志管理功能的更多示例。错误日志管理和CUDA_LOG_FILE可用于 NVIDIA 驱动程序 r570 及更高版本。
在使用簇支持启动的核函数中,出于兼容性考虑,gridDim 变量仍然以线程块数量表示大小。可以使用协作组 API 获取一个块在簇中的秩。
2.1.10.1. 使用三重尖括号表示法进行带簇的启动
可以通过使用__cluster_dims__(X,Y,Z)的编译时核函数属性,或通过 CUDA 核函数启动 APIcudaLaunchKernelEx,在核函数中启用线程块簇。下面的示例展示了如何使用编译时核函数属性启动簇。使用核函数属性设置的簇大小在编译时就已固定,之后可以使用传统的<<<,>>>启动核函数。如果核函数使用编译时簇大小,则在启动该核函数时无法修改簇大小。
// Kernel definition// Compile time cluster size 2 in X-dimension and 1 in Y and Z dimension__global__void__cluster_dims__(2,1,1)cluster_kernel(float*input,float*output){}intmain(){float*input,*output;// Kernel invocation with compile time cluster sizedim3threadsPerBlock(16,16);dim3numBlocks(N/threadsPerBlock.x,N/threadsPerBlock.y);// The grid dimension is not affected by cluster launch, and is still enumerated// using number of blocks.// The grid dimension must be a multiple of cluster size.cluster_kernel<<<numBlocks,threadsPerBlock>>>(input,output);}
cuda.tile:一种 Python 领域专用语言(DSL),用于在分块编程模型中编写 CUDA 核函数和设备函数。
其他组件
cuda.pathfinder:一个用于定位 Python 环境中已安装的 CUDA 组件的实用工具
cuda.bindings:CUDA 库和实用工具的底层 Python 绑定,包括 CUDA Driver API、CUDA Runtime API、NVRTC、NVVM 等。cuda.bindings通过 CUDA Driver 和 CUDA Runtime 组件提供与cuda.core中可用功能相同的功能。不过,cuda.bindings是通过对 C 语言 API 的 Python 封装来提供这些功能的,而不是通过原生的 Python 风格接口。
2.2.1.1. 在 Python 中使用 CUDA 库
CUDA C++ 拥有丰富的库生态系统,无需直接编写核函数或 GPU 代码即可实现 GPU 加速。CUDA C++ 于 2006 年推出时,库的数量很少,开发者基本上必须自行编写 GPU 核函数代码。此后,人们开发了大量库,使开发者无需编写太多 GPU 代码,甚至完全不必编写 GPU 代码,就能在 C++ 中利用 GPU 计算。
CUDA Python 生态系统则从另一个方向演进而来:在能够直接使用 Python 语法和语义编写自定义核函数之前,CuPy 等 Python 库就已经为 Python 开发者提供了计算和算法的 GPU 加速实现。这些库中的许多库为使用 CUDA C++ 实现的 GPU 代码提供了 Python 绑定。
在当今的 CUDA 时代,如果 GPU 加速库能够提供满足您需求所需的表达能力,那么几乎总是建议使用这些库。这些库中的许多实现都经过 GPU 计算专家的调优。当没有可用的库或库无法满足需求时,在 Python 中也可以像在 C++ 中一样,直接编写 GPU 核函数和设备函数。
CUDA Python 应用程序无论是使用 CUDA 加速库,还是包含用户编写的 GPU 代码,其运行方式都与常规 Python 应用程序相同。在本节中,示例始终通过命令行运行,具体做法是如下所示调用python3来执行名为cuda-python-app.py的程序。
$python3cuda-python-app.py
2.2.2. Python 中的 SIMT 核函数
如CUDA 编程模型的介绍中所述,在 GPU 上执行且可以从主机调用的函数称为核函数。CUDA 提供两种不同的模型:单指令多线程(SIMT)和CUDA tile。SIMT 核函数是为由许多并行线程同时运行而编写的。这一概念在 CUDA Python 和 CUDA C++ 中是相同的。本章通过 SIMT 核函数介绍 CUDA Python。
2.2.2.1. 指定核函数
在 CUDA Python 中指定核函数之前,必须导入numba.cuda包。通常采用如下所示的方式完成此操作。
fromnumbaimportcuda
这会导入numba.cuda包,并允许我们使用该包提供的cuda命名空间中的组件。
要在 CUDA Python 中将一个函数指定为核函数,请如下所示将装饰器@cuda.jit放在函数定义的上一行。
fromnumbaimportcuda@cuda.jitdefmy_kernel(input,output):...## launch the kernelmy_kernel[num_thread_blocks,threads_per_block](in_array,out_array)
每个块的线程数量存在限制,因为一个块中的所有线程都驻留在同一个流式多处理器(SM)上,且必须共享该 SM 的资源。在当前的 GPU 上,一个线程块最多可以包含 1024 个线程。如果资源允许,可以在一个 SM 上同时调度多个线程块。
2.2.2.2.2. 多维网格和线程块
在 CUDA 中,线程块以及由线程块组成的网格可以是一维、二维或三维的。当网格或线程块是一维时,可以在指定核函数启动的执行配置时使用整数。当线程块或网格是二维或三维时,则使用二维或三维元组,如下方的二维网格和线程块启动示例所示,其中gridX和gridY是网格的 x 和 y 维度大小,blockX和blockY是网格中每个线程块的 x 和 y 维度大小。
fromnumbaimportcuda@cuda.jitdeffunction(input,output):...## launch the kernelfunction[(gridX,gridY),(blockX,blockY)](in_array,out_array)
cuPy 等 Python 包通过直接使用 CUDA C++ API 来执行 GPU 内存管理,例如第 2.1.3.2 节所介绍的那些 API。多个 Python 包提供了用于控制 GPU 内存分配的封装和实用工具。本指南仅介绍 cuPy。大多数包的概念都相似,并且除非另有说明,否则大多数包的行为方式都与其对应的 C++ 实现相似。
如第 1.2.3 节所介绍,GPU 连接有 DRAM。将在核函数中使用的数据数组,通常需要在核函数访问它们之前就位于 GPU 的 DRAM 中。在 Python 中,控制数据在内存中的位置,即在 CPU 与 GPU 之间移动数据,是程序员的责任。这与第 2.1.3.2 节所介绍的 C++ 中的显式内存管理情况相同。
importcupyascpimportnumpyasnp## create a matrix of zeros on the GPU## when a datatype is not specified, float32 is used by defaultA_device=cp.zeros((1024,1024))## create an array of 2^20 random doubles on the GPUB_device=cp.rand.random((2**20),dtype=np.double)## create an array of zeroes with the same shape and datatype as an existing arrayC_device=cp.zeros_like(A)
2.2.3.2. 在主机内存与 GPU 内存之间复制数组
CuPy 还可用于将数据从位于 CPU 内存中的 Numpyndarrays复制到位于 GPU 内存中的 CuPy 数组。
importcupyascpimportnumpyasnp## Create an array in host memoryA_host=np.zeros((1024,1024))## Copy the array to the GPUA_device=cp.array(A_host)## Create an array in GPU memoryB_device=cp.rand.random((1024,1024))## copy the array to host memoryB_host=cp.asnumpy(B_device)
2.2.3.3. ndarray 对象类型
上一节展示的ndarray对象要么存在于主机内存中,要么存在于 GPU 内存中,但不会同时存在于两者中。将驻留在主机上的数组作为实参传递给核函数会导致错误。将驻留在 GPU 内存中的数组传递给普通 Python 函数,即非核函数,也会导致错误。CuPy 不会隐式执行 CPU 与 GPU 之间的复制,因为这些操作可能开销很大,而且过多的数据复制会损害性能。因此,CuPy 要求程序员有意识地决定何时在 CPU 与 GPU 之间复制数据。
与 C++ 一样,CUDA Python 中的核函数启动相对于主机线程是异步的。也就是说,在核函数启动之后,主机代码会继续在 CPU 上执行,而不能保证核函数已经完成执行,甚至不能保证它已经开始执行。为了保证 GPU 核函数已经执行完毕,主机线程必须与 GPU 进行某种形式的同步。
最简单的同步形式是同步整个 GPU。这种设备范围的同步是 CUDA 驱动程序提供的一种操作,cuPy 和 numba.cuda 都通过synchronize()方法将其暴露给 Python。
importcupyascpfromnumbaimportcuda..## Wait on host thread for all pending GPU work to complete## this uses the interface provided by cupycp.synchronize()## Wait on host thread for all pending GPU work to complete## this uses the interface provided by numba.cudacuda.synchronize()
设备范围的同步会让主机线程等待,直到此前在 GPU 上发出的所有工作都已完成。使用 CUDA 流可以实现更细粒度的同步,如第 2.5 节所述。在 Python 中使用流时,建议使用cuda.core创建 CUDA 流,并根据需要仅与特定的流进行同步。
2.2.5. 综合运用
下面的源代码清单给出了通常用作第一个 GPU 核函数的并行向量加法核函数的 Python 形式。
importnumpyasnpfromnumbaimportcudaimportcupyascp## Defines a CUDA kernel to perform C = A + B vector addition@cuda.jitdefvecadd(A,B,C):work_index=cuda.grid(1)C[work_index]=A[work_index]+B[work_index]# note that vector size is not a power of 2 nor a multiple of the block_size defined belowvector_size=2**24+11device=cp.cuda.Device()## Create device arrays of uniform random float32 values as input, and an array of zeros ## as the result vectora=cp.random.uniform(-1,1,vector_size)b=cp.random.uniform(-1,1,vector_size)c=cp.zeros_like(a)block_size=256grid_size=int(np.ceil(vector_size/block_size))vecadd[grid_size,block_size](a,b,c)## synchronize the CPU thread and the GPU to ensure that the kernel has completed## this is included to illustrate good practices, even though the copy below would implicitly wait for## the kernel to completedevice.synchronize()## Copy all 3 arrays to the CPU as ndarraysa_np=cp.asnumpy(a)b_np=cp.asnumpy(b)c_np=cp.asnumpy(c)## Perform the copy on the CPU to verify the answerexpected=a_np+b_np## Test that the answer is correct, within floating point epsilonnp.testing.assert_array_almost_equal(c_np,expected)## The assert will print diagnostics and abort## so this only prints if the assertion passesprint("Test succeeded")
在此示例中,输入数组A和B由 CuPy 在 GPU 上创建并初始化为随机值。在代码末尾将它们复制到 CPU,仅仅是为了让 CPU 也能执行向量加法,并验证 CPU 和 GPU 的结果是否一致。
2.2.6. CUDA Python 中的错误检查
任何影响 GPU 的操作,从内存分配和复制到核函数启动,都有可能引发错误状况。如第 2.1.7 节针对 C++ 所示,确保在与 GPU 交互的过程中没有发生错误是最佳实践。
importnumpyasnpfromnumbaimportcudaimportcupyascp## Defines a CUDA kernel to perform C = A + B vector addition@cuda.jitdefvecadd(A,B,C):work_index=cuda.grid(1)C[work_index]=A[work_index]+B[work_index]try:vector_size=2**24+11device=cp.cuda.Device()a=cp.random.uniform(-1,1,vector_size)b=cp.random.uniform(-1,1,vector_size)c=cp.zeros_like(a)## this block size is too large for any current GPUsblock_size=2048grid_size=int(np.ceil(vector_size/block_size))# Error: launching kernel with invalid block sizevecadd[grid_size,block_size](a,b,c)device.synchronize()print("Test did not encounter any errors")exceptExceptionase:print(f"Exception occurred: {e}")
共享内存是线程块内所有线程都可以访问的内存空间。它在物理上位于每个 SM 上,并与 L1 缓存使用相同的物理资源,即统一数据缓存。共享内存中的数据在整个核函数执行期间持续存在。共享内存可以视为由用户管理、供核函数执行期间使用的暂存区。虽然与全局内存相比容量较小,但由于共享内存位于每个 SM 上,因此访问共享内存的带宽高于访问全局内存的带宽,延迟也更低。
由于线程块内的所有线程都可以访问共享内存,因此必须注意避免同一线程块内线程之间的数据竞争。在 C++ 中,可以使用__syncthreads()函数实现同一线程块内线程之间的同步。在 Python 中,使用cuda.syncthreads()实现同样的线程块同步。该函数会阻塞线程块中的所有线程,直到所有线程都到达对__syncthreads()或cuda.syncthreads()的调用处。
// assuming blockDim.x is 128__global__voidexample_syncthreads(int*input_data,int*output_data){__shared__intshared_data[128];shared_data[threadIdx.x]=input_data[blockDim.x*blockIdx.x+threadIdx.x];// All threads synchronize, guaranteeing all writes to 'shared_data' are ordered // before any thread is unblocked from '__syncthreads()':__syncthreads();// A single thread safely reads 'shared_data':if(threadIdx.x==0){floatsum=0;for(inti=0;i<blockDim.x;++i){sum+=shared_data[i];}output_data[blockIdx.x]=sum;}}
要在 C++ 中动态分配共享内存,程序员可以在核函数启动的三重尖括号记法中,将每个线程块所需的共享内存字节数指定为第三个(可选的)参数,如functionName<<<grid,block,sharedMemoryBytes>>>()所示。未指定此参数时,其默认值为 0。
在 Python 中,必须使用cuda.core.launch()来启动核函数。LaunchConfig参数接受一个cuda.core.LaunchConfig对象,该对象具有一个名为shmem_size的字段,其作用与 C++ 中三重尖括号记法的第三个参数相同。
在核函数内部,程序员可以在 C++ 中使用extern__shared__说明符和空的[]来声明一个将在核函数启动时动态分配的变量。在 Python 中,则使用与静态分配共享内存时相同的cuda.shared.array方法,并将shape参数设为 0。
extern__shared__floatsharedArray[];
fromnumbaimportcudaimportnumpyasnp## setting shape=0 indicates that this array will be dynamically sized by the kernel launch's execution configurationshared_array=cuda.shared.array(shape=0,type=np.float32)
需要注意的一点是,一个核函数只能有一个动态分配的共享数组。如果需要多个动态分配的共享内存数组,则必须分配一个足够大、能够容纳所有所需数组的动态共享内存数组,并手动对其进行分区。例如,在 C++ 中,如果希望获得与以下代码等效的形式,
寄存器位于 SM 上,具有线程局部作用域。寄存器的使用由编译器管理,在核函数执行期间用于线程局部存储。可以使用 GPU 的regsPerMultiprocessor和regsPerBlock设备属性查询每个 SM 的寄存器数量以及每个线程块的寄存器数量。
编译 C++ 代码时,NVCC 允许开发者通过-maxrregcount选项为核函数指定寄存器数量上限。使用此选项减少核函数可以使用的寄存器数量,可能会使更多线程块被调度到 SM 上并发执行,但也可能导致更多寄存器溢出。寄存器溢出是指,为了给其他值腾出空间,必须将当前存储在片上寄存器中的值写出到全局内存,然后再在稍后读回。
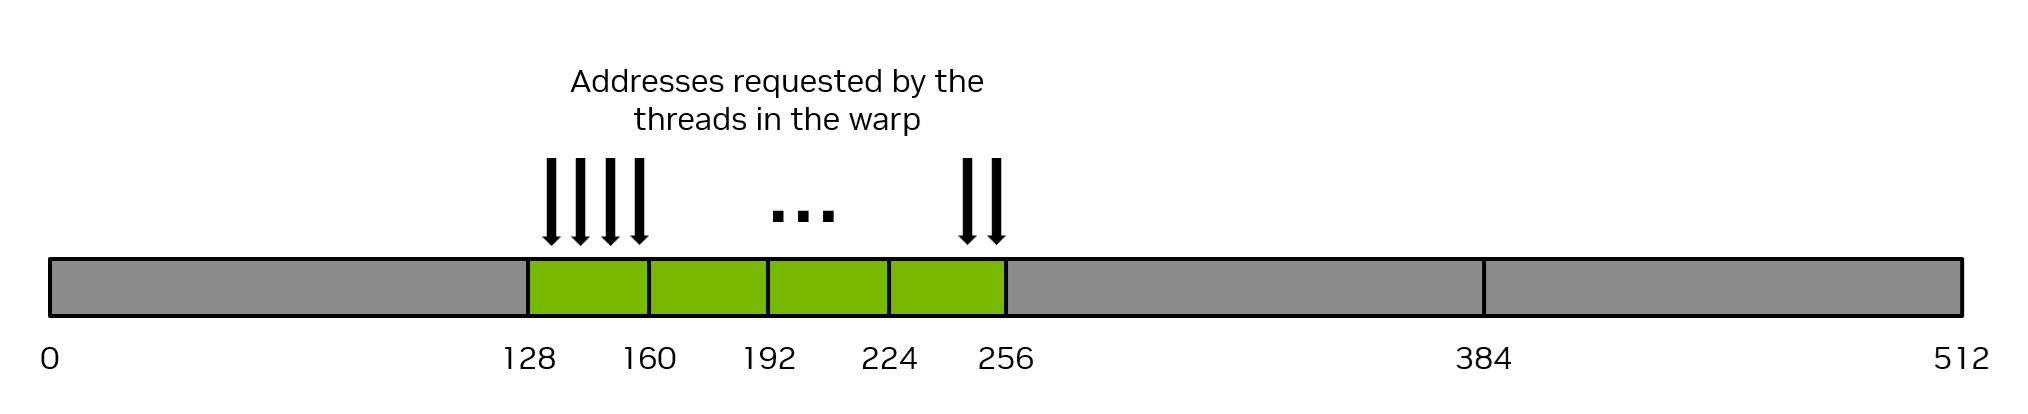
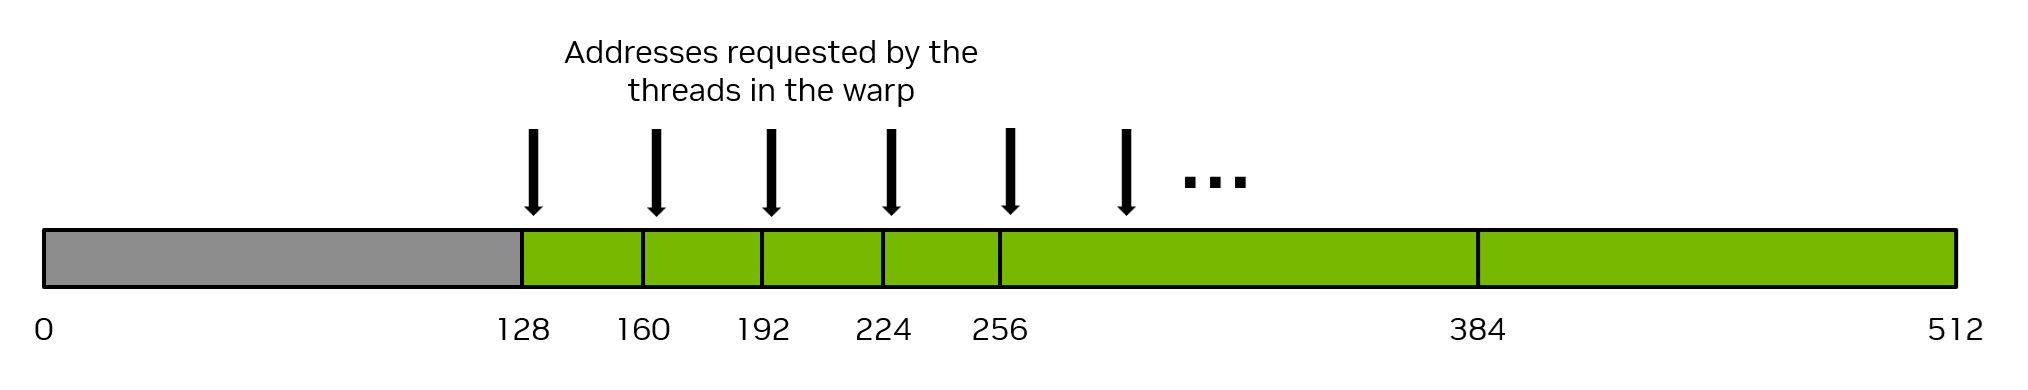
由于局部内存空间位于设备内存中,局部内存访问具有与全局内存访问相同的延迟和带宽,并且受到合并的全局内存访问中所述的相同内存访问合并要求的约束。不过,局部内存的组织方式使得连续的线程 ID 访问连续的 32 位字。因此,只要线程束中的所有线程访问相同的相对地址,例如数组变量中的同一索引或结构体变量中的同一成员,访问就会完全合并。
// In your .cu file__constant__floatcoeffs[4];__global__voidcompute(float*out){intidx=threadIdx.x;out[idx]=coeffs[0]*idx+coeffs[1];}// In your host codefloath_coeffs[4]={1.0f,2.0f,3.0f,4.0f};cudaMemcpyToSymbol(coeffs,h_coeffs,sizeof(h_coeffs));compute<<<1,10>>>(device_out);
fromnumbaimportcudaimportnumpyasnphost_array=np.zeros(128,dtype=np.float32)## fill host_array with other data@cuda.jitdefkernel(args):...const_array=cuda.const.array_like(a)# this access now goes through constant memorya=const_array[cuda.threadIdx.x]
2.3.3.6. 缓存
GPU 设备具有多级缓存结构,其中包括 L2 和 L1 缓存。
L2 缓存位于设备上,由所有 SM 共享。可以通过cudaGetDeviceProperties函数返回的l2CacheSize设备属性成员查询 L2 缓存的大小。
如上文共享内存中所述,L1 缓存在物理上位于每个 SM 上,与共享内存使用的是同一物理空间。如果核函数未使用任何共享内存,则整个物理空间都将由 L1 缓存使用。
#include<cooperative_groups.h>// Distributed Shared memory histogram kernel__global__voidclusterHist_kernel(int*bins,constintnbins,constintbins_per_block,constint*__restrict__input,size_tarray_size){extern__shared__intsmem[];namespacecg=cooperative_groups;inttid=cg::this_grid().thread_rank();// Cluster initialization, size and calculating local bin offsets.cg::cluster_groupcluster=cg::this_cluster();unsignedintclusterBlockRank=cluster.block_rank();intcluster_size=cluster.dim_blocks().x;for(inti=threadIdx.x;i<bins_per_block;i+=blockDim.x){smem[i]=0;//Initialize shared memory histogram to zeros}// cluster synchronization ensures that shared memory is initialized to zero in// all thread blocks in the cluster. It also ensures that all thread blocks// have started executing and they exist concurrently.cluster.sync();for(inti=tid;i<array_size;i+=blockDim.x*gridDim.x){intldata=input[i];//Find the right histogram bin.intbinid=ldata;if(ldata<0)binid=0;elseif(ldata>=nbins)binid=nbins-1;//Find destination block rank and offset for computing//distributed shared memory histogramintdst_block_rank=(int)(binid/bins_per_block);intdst_offset=binid%bins_per_block;//Pointer to target block shared memoryint*dst_smem=cluster.map_shared_rank(smem,dst_block_rank);//Perform atomic update of the histogram binatomicAdd(dst_smem+dst_offset,1);}// cluster synchronization is required to ensure all distributed shared// memory operations are completed and no thread block exits while// other thread blocks are still accessing distributed shared memorycluster.sync();// Perform global memory histogram, using the local distributed memory histogramint*lbins=bins+cluster.block_rank()*bins_per_block;for(inti=threadIdx.x;i<bins_per_block;i+=blockDim.x){atomicAdd(&lbins[i],smem[i]);}}
// Launch via extensible launch{cudaLaunchConfig_tconfig={0};config.gridDim=array_size/threads_per_block;config.blockDim=threads_per_block;// cluster_size depends on the histogram size.// ( cluster_size == 1 ) implies no distributed shared memory, just thread block local shared memoryintcluster_size=2;// size 2 is an example hereintnbins_per_block=nbins/cluster_size;//dynamic shared memory size is per block.//Distributed shared memory size = cluster_size * nbins_per_block * sizeof(int)config.dynamicSmemBytes=nbins_per_block*sizeof(int);CUDA_CHECK(::cudaFuncSetAttribute((void*)clusterHist_kernel,cudaFuncAttributeMaxDynamicSharedMemorySize,config.dynamicSmemBytes));cudaLaunchAttributeattribute[1];attribute[0].id=cudaLaunchAttributeClusterDimension;attribute[0].val.clusterDim.x=cluster_size;attribute[0].val.clusterDim.y=1;attribute[0].val.clusterDim.z=1;config.numAttrs=1;config.attrs=attribute;cudaLaunchKernelEx(&config,clusterHist_kernel,bins,nbins,nbins_per_block,input,array_size);}
2.3.4. 内存性能
确保正确使用内存是 CUDA 核函数实现高性能的关键。本节讨论在 CUDA 核函数中从全局内存和共享内存获得高内存吞吐量的一些一般原则和示例。对于大多数核函数,全局内存性能是首要的性能考虑因素。当线程操作并非由其显式加载或创建的数据时,通常会使用共享内存,因此理解共享内存与性能相关的特征也很重要。
## Defines a CUDA kernel to perform C = A + B vector addition@cuda.jitdefvecadd(A,B,C):work_index=cuda.grid(1)C[work_index]=A[work_index]+B[work_index]
确保全局内存访问正确合并,是编写高性能 CUDA 核函数时最重要的性能考虑因素之一。应用程序必须尽可能高效地使用内存系统。
2.3.4.1.1. 使用全局内存的矩阵转置示例
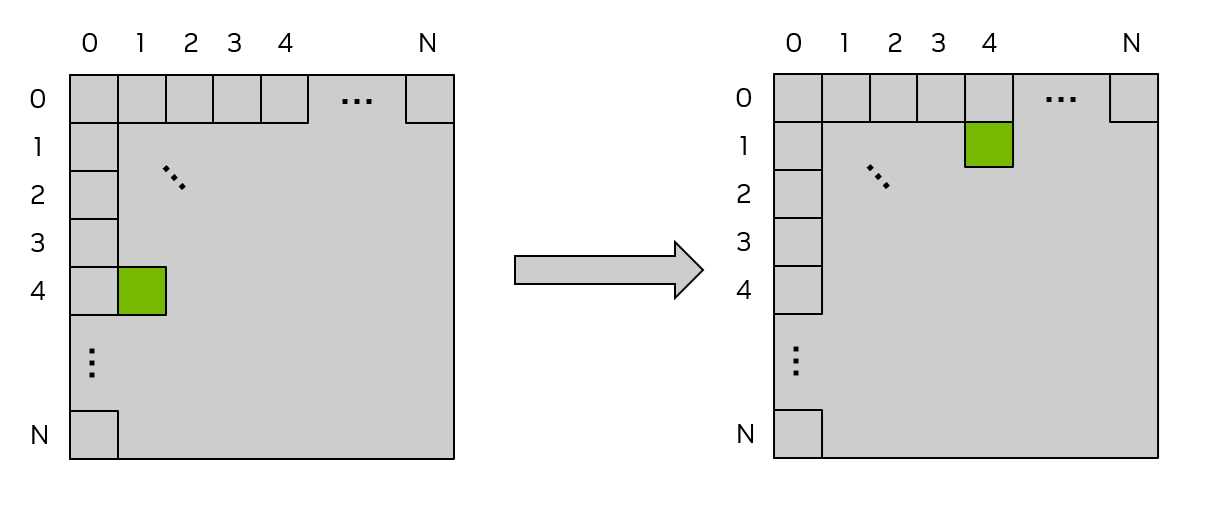
举一个简单的例子,考虑一个非原地矩阵转置核函数,它将一个大小为 N x N 的 32 位浮点方阵从矩阵a转置到矩阵c。此示例使用二维网格,并假设启动大小为 32 x 32 个线程的二维线程块,即blockDim.x=32和blockDim.y=32,因此每个二维线程块将操作矩阵的一个 32 x 32 分块(tile)。每个线程操作矩阵中的一个唯一元素,因此不需要显式地同步线程。图 14展示了这一矩阵转置操作。核函数源代码位于图后。
图 14 使用全局内存的矩阵转置
每个矩阵顶部和左侧的标签是二维线程块索引,也可以视为分块索引,其中每个小方格表示矩阵的一个分块,将由一个二维线程块对其进行操作。在此示例中,分块大小为 32 x 32 个元素,因此每个小方格都代表矩阵的一个 32 x 32 分块。绿色阴影方格显示了一个示例分块在转置操作前后的位置。
/* macro to index a 1D memory array with 2D indices in row-major order *//* ld is the leading dimension, i.e. the number of columns in the matrix */#define INDX( row, col, ld ) ( ( (row) * (ld) ) + (col) )/* CUDA kernel for matrix transpose */__global__voidcuda_transpose(intm,float*a,float*c){intmyCol=blockDim.x*blockIdx.x+threadIdx.x;intmyRow=blockDim.y*blockIdx.y+threadIdx.y;if(myRow<m&&myCol<m){c[INDX(myCol,myRow,m)]=a[INDX(myRow,myCol,m)];}/* end if */return;}/* end cuda_transpose */
importnumpyasnpfromnumbaimportcudaimportcupyascp## Matrix transpose kernel, one thread per matrix element launched with ## 2D thread block on 2D grid to match matrix size@cuda.jitdeftranspose(a,c):col=cuda.blockDim.x*cuda.blockIdx.x+cuda.threadIdx.xrow=cuda.blockDim.y*cuda.blockIdx.y+cuda.threadIdx.yc[(col,row)]=a[(row,col)]
#define THREADS_PER_BLOCK_X 32#define THREADS_PER_BLOCK_Y 32/* macro to index a 1D memory array with 2D indices in column-major order *//* ld is the leading dimension, i.e. the number of rows in the matrix */#define INDX( row, col, ld ) ( ( (col) * (ld) ) + (row) )/* CUDA kernel for shared memory matrix transpose */__global__voidsmem_transpose(intm,float*a,float*c){/* declare a statically allocated shared memory array */__shared__floatsmemArray[THREADS_PER_BLOCK_X][THREADS_PER_BLOCK_Y];/* determine my row and column indices for the error checking code */constintmyRow=blockDim.x*blockIdx.x+threadIdx.x;constintmyCol=blockDim.y*blockIdx.y+threadIdx.y;/* determine my row tile and column tile index */constinttileX=blockDim.x*blockIdx.x;constinttileY=blockDim.y*blockIdx.y;if(myRow<m&&myCol<m){/* read from global memory into shared memory array */smemArray[threadIdx.x][threadIdx.y]=a[INDX(tileX+threadIdx.x,tileY+threadIdx.y,m)];}/* end if *//* synchronize the threads in the thread block */__syncthreads();if(myRow<m&&myCol<m){/* write the result from shared memory to global memory */c[INDX(tileY+threadIdx.x,tileX+threadIdx.y,m)]=smemArray[threadIdx.y][threadIdx.x];}/* end if */return;}
importnumpyasnpfromnumbaimportcudaimportcupyascp## Matrix transpose kernel, one thread per matrix element launched with ## 2D thread block on 2D grid to match matrix size## Stages input to shared memory@cuda.jitdefsmem_transpose(a,c):smemArray=cuda.shared.array(shape=(32,32),dtype=np.float32)tile_col=cuda.blockDim.x*cuda.blockIdx.xtile_row=cuda.blockDim.y*cuda.blockIdx.ysmemArray[(cuda.threadIdx.x,cuda.threadIdx.y)]=a[(tile_row+cuda.threadIdx.y,tile_col+cuda.threadIdx.x)]cuda.syncthreads()c[(tile_col+cuda.threadIdx.y,tile_row+cuda.threadIdx.x)]=smemArray[(cuda.threadIdx.y,cuda.threadIdx.x)]
在 C++ 中,CUDA 提供了与名称相似的 C++ 标准库原子类型cuda::std::atomic和cuda::std::atomic_ref类似的语法与行为。CUDA 还提供了扩展的 C++ 原子类型cuda::atomic和cuda::atomic_ref,允许用户指定原子操作的线程作用域。原子函数的详细信息在原子函数中介绍。
在 Python 中,原子内存操作由numba.cuda.atomic命名空间中可供 GPU 代码使用的函数提供。可用的典型操作包括add、sub、max、min和compare_and_swap。受支持原子操作的完整列表见Numba CUDA 文档。
以下代码展示了一个使用原子内存访问来计算数组中所有值之和的核函数示例。每个线程块都将数组的一个切片加载到共享内存中。每个线程块中的一个线程计算局部和,并对结果数组s执行原子加法。由于数据位于共享内存中,而共享内存靠近 SM 的计算资源,因此让单个线程执行求和通常仍能获得相当不错的性能。
importnumpyasnpfromnumbaimportcudaimportcupyascp@cuda.jitdefsum_reduce(a,s):## create a shared array to support a block size up to 512 threads## even though we'll use fewer in this exampleshared_staging=cuda.shared.array(shape=512,dtype=np.float32)## Load values into shared memory and then synchronize to make sure all loads completedshared_staging[cuda.threadIdx.x]=a[cuda.blockIdx.x*cuda.blockDim.x+cuda.threadIdx.x]cuda.syncthreads()## only thread 0 of each block does the local additions, followed by a single## atomic operation per thread blocklocal_sum=float(0.0)ifcuda.threadIdx.x==0:foriinrange(cuda.blockDim.x):local_sum=local_sum+shared_staging[i]cuda.atomic.add(s,0,local_sum)array_length=2**18a=cp.ones(array_length)s=cp.zeros(1,dtype=np.float32)block_size=256grid_size=int(array_length/block_size)sum_reduce[grid_size,block_size](a,s)s_host=cp.asnumpy(s)print(f"Sum is {int(s_host[0])}, expected {array_length}")
在这个简单示例中,输入数组的元素全为 1,因此正确的总和与array_length相同。
如果将这一行
cuda.atomic.add(s,0,local_sum)
替换为非原子加法
s[0]=s[0]+local_sum
则对s[0]的访问将不是原子的,s[0]的最终值将小于array_length。此外,该值可能会随着每次运行以及在具有不同 SM 数量的 GPU 上运行而变化。这说明了在此代码中,必须使用原子内存访问才能保证正确性。
C++ 中也提供了类似的原子操作,第 5.4.5.1 节对此进行了讨论,但建议使用类似于std::atomic的原子操作,这被视为 CUDA C++ 中的最佳实践。
2.3.6. 协作组
协作组是 CUDA C++ 中提供的一种软件工具,它允许应用程序定义能够相互同步的线程组,即使该线程组跨越多个线程块、单个 GPU 上的多个网格,甚至跨越多个 GPU。CUDA 编程模型通常允许线程块或线程块簇中的线程高效地同步,但不提供指定小于一个线程块或簇的线程组的机制。同样,CUDA 编程模型也不提供支持跨线程块同步的机制或保证。
当 CUDA 核函数启动时,CUDA 线程会根据核函数启动时指定的执行配置,组织为线程块和一个网格。核函数启动后,调度器会将线程块分配给 SM。应用程序无法控制或查询哪些线程块被调度到哪些 SM 上执行的细节,而且调度器不提供任何顺序保证,因此程序不能依赖特定的调度顺序或方案来保证正确执行。
一个 SM 上能够调度的线程块数量取决于给定线程块所需的硬件资源,以及该 SM 上可用的硬件资源。核函数刚启动时,调度器开始将线程块分配给 SM。只要 SM 有足够的、未被其他线程块占用的硬件资源,调度器就会继续向 SM 分配线程块。如果在某个时刻没有任何 SM 有能力接纳另一个线程块,调度器就会等待,直到 SM 完成先前分配的线程块。一旦完成,SM 就可以接纳更多工作,调度器便会向它们分配线程块。这个过程会持续进行,直到所有线程块都已被调度并执行完毕。
cudaGetDeviceProperties函数允许应用程序通过设备属性查询每个 SM 的限制。请注意,每个 SM 和每个线程块都有相应的限制。
maxBlocksPerMultiProcessor:每个 SM 的最大驻留块数。
sharedMemPerMultiprocessor:每个 SM 的可用共享内存量,以字节为单位。
regsPerMultiprocessor:每个 SM 的可用 32 位寄存器数。
maxThreadsPerMultiProcessor:每个 SM 的最大驻留线程数。
sharedMemPerBlock:一个线程块可分配的最大共享内存量,以字节为单位。
regsPerBlock:一个线程块可分配的最大 32 位寄存器数。
maxThreadsPerBlock:每个线程块的最大线程数。
CUDA 核函数的占用率是活跃线程束数与 SM 所支持的最大活跃线程束数之比。一般来说,尽可能提高占用率是一种良好做法,这可以隐藏延迟并提高性能。
要计算占用率,需要了解刚才介绍的 SM 资源限制,还需要了解所考察的 CUDA 核函数需要哪些资源。要确定每个核函数的资源使用情况,可以在程序编译期间使用nvcc的--resource-usage选项,它会显示核函数所需的寄存器数和共享内存量。
目前,不能从__global__或__device__函数中调用__tile__函数。同样,不能从__tile_global__或__tile__函数中调用__device__函数。未来版本的 CUDA 可能会解除这一限制。
在 cuTile Python 中:
@ct.kernel装饰器将一个函数标记为分块核函数入口点
@ct.function装饰器将一个函数标记为可从分块核函数或另一个分块函数中调用的函数。
实际上,从核函数中调用的任何函数都会自动编译为分块代码,因此@ct.function装饰器是可选的。数组参数接受任何驻留在设备上且公开 DLPack 或 CUDA Array Interface 的数组。例如,PyTorch 张量和 CuPy 数组。标量参数直接传递。
#include"cuda_tile.h"// Tile kernel entry point. Cannot be called directly; must be launched.__tile_global__voidmy_kernel(float*a,float*b,float*c){...}// Tile function. Callable from tile kernels and tile functions.__tile__floathelper(floatx,floaty){returnx+y;}
importcuda.tileasct# Tile kernel entry point. Cannot be called directly; must be launched.@ct.kerneldefmy_kernel(a,b,c):...# Tile function. Callable from tile kernels and tile functions.# @ct.function is optional, any function called from tile code# is automatically compiled as tile code.@ct.functiondefhelper(x,y):returnx+y
在 C++ 中,分块核函数复用 SIMT 中熟悉的三重尖括号启动语法。尖括号中的第一个参数是网格形状(分块线程块的数量)。第二个参数是 SIMT 中每个块的线程数;对于分块核函数,编译器在内部确定线程数,第二个参数必须为1。分块核函数也是普通的 CUDA 核函数,因此可以通过运行时现有的 APIcudaLaunchKernel和cudaLaunchKernelEx使用相同的grid,1配置来启动它。当要将分块核函数集成到已经通过这些 API 执行启动的代码库中时,这一点很有用。
在 Python 中,ct.launch接受四个位置参数:一个 CUDA 流、一个指定每个维度上分块线程块数量的网格元组、核函数对象,以及一个核函数参数元组。
my_kernel<<<dim3(num_blocks_x,num_blocks_y),1>>>(a,b,c);// second arg must be 1
importtorchstream=torch.cuda.current_stream()# CUDA stream objectgrid=(num_blocks_x,num_blocks_y,1)# tile-block grid (x, y, z)ct.launch(stream,grid,my_kernel,(a,b,c))
#include"cuda_tile.h"__tile_global__voidmy_kernel(float*a,float*b,float*c){namespacect=cuda::tiles;intbid_x=ct::bid().x;// block index along .xintbid_y=ct::bid().y;// block index along .yintnum_x=ct::num_blocks().x;// total blocks along .x}
@ct.kerneldefmy_kernel(a,b,c):bid_x=ct.bid(0)# block index along axis 0bid_y=ct.bid(1)# block index along axis 1num_x=ct.num_blocks(0)# total blocks along axis 0
importcuda.tileasct@ct.kerneldefmy_kernel(TILE:ct.Constant[int]):# TILE is constant-embedded: wherever TILE appears, the compiler sees its# literal value (e.g., 128) and generates specialized code. Here TILE drives# the shape of a factory-built tile.zeros=ct.zeros((TILE,),dtype=ct.float32)
2.4.5.2. C++ integral_constant 和 _ic 字面量
在 CUDA Tile C++ 中,编译时值通过ct::integral_constant表达,这是一种将数值编码在类型本身中的类型。ct::literals命名空间中的_ic字面量提供了一种简洁的简写形式:0_ic生成一个ct::integral_constant<0>值。
接受编译时值的 API 同时接受非类型模板参数(NTTP)形式和_ic字面量形式。例如,ct::cat沿给定维度拼接两个分块,而该维度必须在编译时已知。下面两行使用相同的编译时轴调用ct::cat;它们唯一的区别在于编译时值写在什么位置:
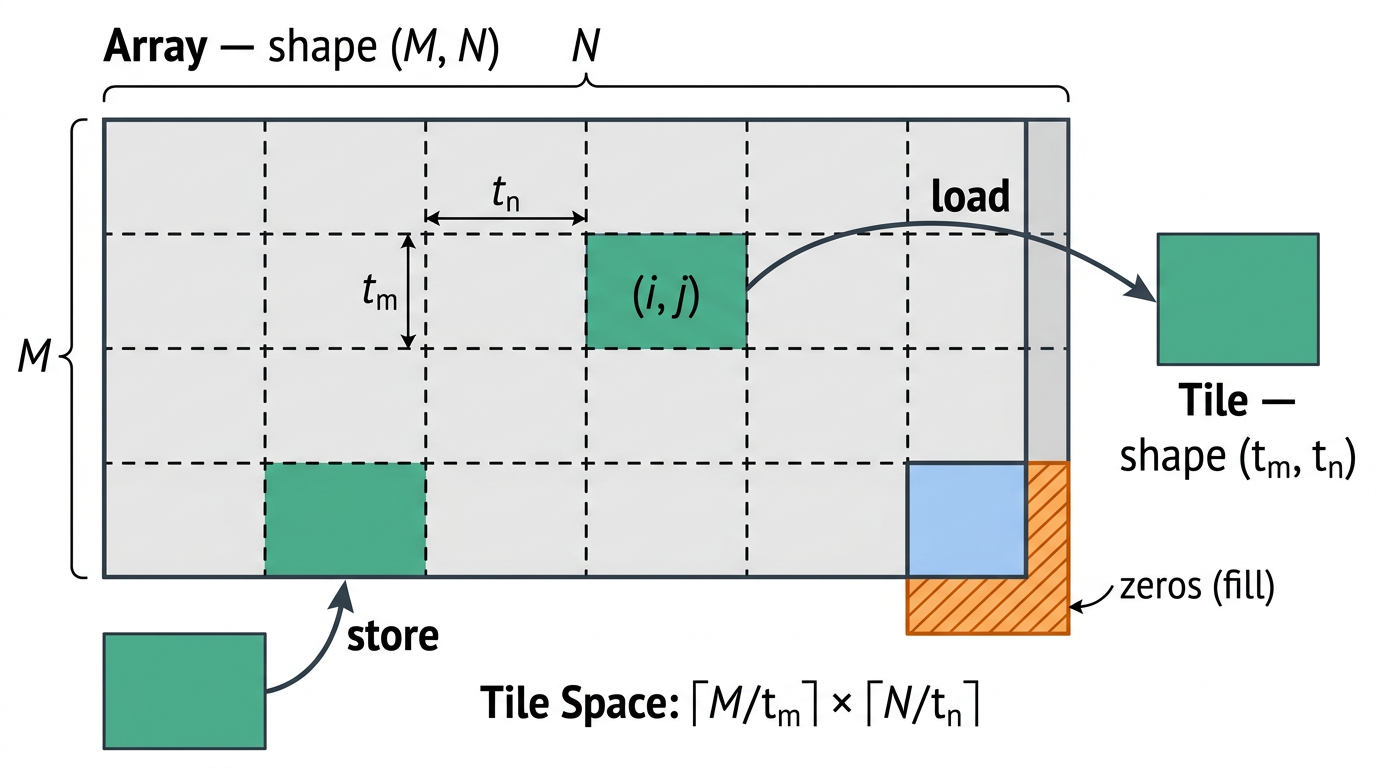
在 Python 中,Array.tiled_view(tile_shape)返回一个TiledView,将数组划分为给定形状的分块。该视图提供接受分块空间索引的.load(index) / .store(index,tile)方法,与 C++ 的partition_view直接对应。
注意
本章中的 C++ 示例代码使用__restrict__标注指针参数,并在核函数体靠近开头的位置调用ct::assume_aligned(ptr,16_ic)。这些都是重要的性能标注,第 2.4.12 节将进一步介绍。数值字面量(例如128_ic、8_ic)上的_ic后缀将其标记为编译期常量,如编译期常量中所介绍的那样。
__tile_global__voidvec_add(float*__restrict__a,float*__restrict__b,float*__restrict__out){namespacect=cuda::tiles;usingnamespacect::literals;a=ct::assume_aligned(a,16_ic);b=ct::assume_aligned(b,16_ic);out=ct::assume_aligned(out,16_ic);// Step 1: attach a shape to each raw pointer. 128_ic marks 128 as a compile-time constant.autoaSpan=ct::tensor_span{a,ct::extents{128_ic}};autobSpan=ct::tensor_span{b,ct::extents{128_ic}};autooSpan=ct::tensor_span{out,ct::extents{128_ic}};// Step 2: partition each span into a tile space of fixed 8-element tiles.autoaView=ct::partition_view{aSpan,ct::shape{8_ic}};autobView=ct::partition_view{bSpan,ct::shape{8_ic}};autooView=ct::partition_view{oSpan,ct::shape{8_ic}};intbx=ct::bid().x;// this block's tile-space index along .xautoaTile=aView.load(bx);// pick the bx-th tile of aautobTile=bView.load(bx);oView.store(aTile+bTile,bx);// write the tile back at the bx-th position of out}
@ct.kerneldefvec_add(a,b,c,TILE:ct.Constant[int]):bid=ct.bid(0)# this block's tile-space index along axis 0a_tile=ct.load(a,index=(bid,),shape=(TILE,))# (index, shape) = pick the bid-th TILE-sized region of ab_tile=ct.load(b,index=(bid,),shape=(TILE,))ct.store(c,index=(bid,),tile=a_tile+b_tile)# write the tile back to the bid-th region of c
@ct.kerneldefedge_safe(arr_in,arr_out,TILE:ct.Constant[int]):bid=ct.bid(0)tile=ct.load(arr_in,index=(bid,),shape=(TILE,),padding_mode=ct.PaddingMode.ZERO)# OOB lanes of a partial edge tile become 0ct.store(arr_out,index=(bid,),tile=tile)# OOB writes are silently discarded
在 C++ 核函数内部,.load_masked()和.store_masked()负责处理边缘处的不完整分块。在 Python 核函数内部,加载操作上的PaddingMode.ZERO确保边缘处的不完整分块用零填充,而ct.store使用其默认的边界检查,静默丢弃超出数组边界的写入。有关完整的填充模式、掩码选项和填充值,请参阅各语言的 API 参考(CUDA Tile C++ 视图填充、cuTile Python 填充模式)。
__tile_global__voidvec_add_gather(int*__restrict__a,int*__restrict__b,int*__restrict__out){namespacect=cuda::tiles;usingnamespacect::literals;usingi32x8=ct::tile<int,ct::shape<8>>;a=ct::assume_aligned(a,16_ic);b=ct::assume_aligned(b,16_ic);out=ct::assume_aligned(out,16_ic);intbx=ct::bid().x;autooffsets=8*bx+ct::iota<i32x8>();// element-level offsets, one per lane// scalar pointer + int tile = tile of pointers (one pointer per offset).autoaPtrs=a+offsets;autobPtrs=b+offsets;autoaTile=ct::load(aPtrs);// gather: one load per pointerautobTile=ct::load(bPtrs);ct::store(out+offsets,aTile+bTile);// scatter: one store per pointer}
@ct.kerneldefvec_add_gather(a,b,c,TILE:ct.Constant[int]):bid=ct.bid(0)indices=bid*TILE+ct.arange(TILE,dtype=ct.int32)# one element index per lanea_tile=ct.gather(a,indices)# load a[indices[i]] per laneb_tile=ct.gather(b,indices)ct.scatter(c,indices,a_tile+b_tile)# store one value per index into c
在 Python 中,ct.gather和ct.scatter默认保证边界安全。越界读取返回填充值(默认为零),越界写入则被静默丢弃。当你能够证明每个索引都在范围内时,可以禁用边界检查;这样做会使越界访问成为未定义行为。有关可选的掩码和填充值设置,请参阅 API 参考(CUDA Tile C++ 加载操作、cuTile Python 加载/存储操作)。
在 C++ 中,边界检查不是自动进行的。程序员构造一个布尔掩码(例如,将偏移量与数组长度进行比较),然后将其传递给ct::load_masked或ct::store_masked:
__tile_global__voidgather_safe(int*__restrict__arr,int*__restrict__out,intN){namespacect=cuda::tiles;usingnamespacect::literals;usingi32x8=ct::tile<int,ct::shape<8>>;arr=ct::assume_aligned(arr,16_ic);out=ct::assume_aligned(out,16_ic);intbx=ct::bid().x;autooffsets=8*bx+ct::iota<i32x8>();// element-level offsets, one per laneautomask=offsets<N;// boolean tile: true where the offset is in-boundsautoptrs=arr+offsets;// tile of pointers, one per offsetautotile=ct::load_masked(ptrs,mask,0);// masked lanes get the pad value 0ct::store_masked(out+offsets,tile,mask);// masked lanes are skipped on the store}
在 C++ 中,ct::irange是一个前向范围,表示从下界开始、到上界但不包含上界的递增整数序列,序列中的整数按可选的步长间隔排列。使用ct::irange可以向编译器提供关于迭代边界的结构化信息,这些信息可用于更好地优化生成的代码。要使该优化生效,循环变量必须通过遍历ct::irange的基于范围的 for 表达式进行绑定。
在 Python 中,分块代码支持内置的range()、for、while以及嵌套循环。
步长参数必须严格大于零;不支持负步长范围。
以下单块核函数对一维数组的所有分块求和:
__tile_global__voidtile_sum(float*__restrict__arr,float*__restrict__out,intnum_tiles){namespacect=cuda::tiles;usingnamespacect::literals;usingf32x8=ct::tile<float,ct::shape<8>>;arr=ct::assume_aligned(arr,16_ic);out=ct::assume_aligned(out,16_ic);autoinView=ct::partition_view{ct::tensor_span{arr,ct::extents{8*num_tiles}},ct::shape{8_ic}};autooutView=ct::partition_view{ct::tensor_span{out,ct::extents{8_ic}},ct::shape{8_ic}};autoacc=ct::full<f32x8>(0.0f);// range-for over ct::irange gives the compiler structured iteration bounds.for(autok:ct::irange(0,num_tiles)){autotile=inView.load(k);acc=acc+tile;// accumulate the k-th tile into acc}outView.store(acc,0);// write the final result as the 0-th tile of out}
@ct.kerneldeftile_sum(arr,out,TILE:ct.Constant[int],N_TILES:ct.Constant[int]):# Intended grid: (1,) -- a single block sums all tiles of arr.acc=ct.zeros((TILE,),dtype=ct.float32)forkinrange(N_TILES):# range() works natively in tile codetile=ct.load(arr,index=(k,),shape=(TILE,))acc=acc+tile# accumulate the k-th tile into accct.store(out,index=(0,),tile=acc)# write the final result as the 0-th tile of out
__tile_global__voidconditional_load(float*__restrict__arr,float*__restrict__out,intN){namespacect=cuda::tiles;usingnamespacect::literals;usingf32x8=ct::tile<float,ct::shape<8>>;arr=ct::assume_aligned(arr,16_ic);out=ct::assume_aligned(out,16_ic);autoinView=ct::partition_view{ct::tensor_span{arr,ct::extents{N}},ct::shape{8_ic}};autooutView=ct::partition_view{ct::tensor_span{out,ct::extents{N}},ct::shape{8_ic}};intbx=ct::bid().x;intnb_x=ct::num_blocks().x;autotile=ct::full<f32x8>(0.0f);// default for the last-block branch// Scalar condition -> one control-flow path per block; no divergence to reason about.if(bx<nb_x-1){tile=inView.load(bx);// all blocks except the last}outView.store_masked(tile,bx);// masked to handle a potentially partial final tile}
@ct.kerneldefconditional_load(arr,out,TILE:ct.Constant[int]):bid=ct.bid(0)# Scalar condition -> one control-flow path per block; no divergence to reason about.ifbid<ct.num_blocks(0)-1:tile=ct.load(arr,index=(bid,),shape=(TILE,))# all blocks except the lastelse:tile=ct.zeros((TILE,),dtype=ct.float32)# last block: emit zerosct.store(out,index=(bid,),tile=tile)
autox=ct::iota<ct::tile<int,ct::shape<8,2>>>();// 8x2 (rank 2)autoy=ct::iota<ct::tile<int,ct::shape<4,1,2>>>();// 4x1x2 (rank 3)autoz=x+y;// x promoted to 1x8x2, then broadcasts to 4x8x2
x=ct.full((8,2),3,dtype=ct.int32)# 8x2 (rank 2)y=ct.full((4,1,2),5,dtype=ct.int32)# 4x1x2 (rank 3)z=x+y# x promoted to 1x8x2, then broadcasts to 4x8x2
usingi32x8=ct::tile<int,ct::shape<8>>;i32x8x=ct::full<i32x8>(3);x+2;// OK - int literal matches int tile element typex+2.5;// ill-formed - 2.5 would narrow to int
x=ct.full((8,),3,dtype=ct.int32)x+2# int32 - int literal matches int32 tile dtypex+2.5# float32 - result promoted to hold both
__tile_global__voidelementwise(float*__restrict__a,float*__restrict__b,float*__restrict__out,intN){namespacect=cuda::tiles;usingnamespacect::literals;a=ct::assume_aligned(a,16_ic);b=ct::assume_aligned(b,16_ic);out=ct::assume_aligned(out,16_ic);autoaView=ct::partition_view{ct::tensor_span{a,ct::extents{N}},ct::shape{8_ic}};autobView=ct::partition_view{ct::tensor_span{b,ct::extents{N}},ct::shape{8_ic}};autocView=ct::partition_view{ct::tensor_span{out,ct::extents{N}},ct::shape{8_ic}};intbx=ct::bid().x;autox=aView.load(bx);autoy=bView.load(bx);// 2.0f matches the float tiles' element type, so no narrowing conversion is required.// The scalar is broadcast across every element; + then runs elementwise.autoz=2.0f*x+y;cView.store(z,bx);}
@ct.kerneldefelementwise(a,b,c,TILE:ct.Constant[int]):bid=ct.bid(0)x=ct.load(a,index=(bid,),shape=(TILE,))y=ct.load(b,index=(bid,),shape=(TILE,))# 2.0 is a loosely typed float constant; with float tiles, the result stays float.# Scalars are broadcast across every element of the tile, then + runs elementwise.z=2.0*x+yct.store(c,index=(bid,),tile=z)
当你需要显式控制舍入模式或次正规数处理时,CUDA Tile API 提供了显式开放这些选项的数学函数,既用于逐元素算术运算(例如ct.add、ct::add),也用于超越函数(例如exp和tanh)。
2.4.9. 分块原语
工厂函数(创建分块)、加载和存储(分块空间加载和存储)以及逐元素算术运算(逐元素算术运算与广播)都是分块原语,即语言组成部分中的操作。程序员以分块为粒度编写这些操作,编译器则将其映射到硬件,包括可用的张量核心。本节介绍 CUDA tile 中可用的其他原语。
2.4.9.1. 矩阵乘法
两个分块的矩阵乘法是实现两个数组之间矩阵乘法的基本操作。CUDA Tile 提供两种形式的分块间矩阵乘法:纯矩阵乘法(matmul)a@b,以及矩阵乘累加(mma)a@b+acc。在 mma 中,累加器将部分乘积从一个 K 分块传递到下一个 K 分块。这有助于分块矩阵乘法的内层循环。matmul和mma都支持二维矩阵乘法和三维批量乘法,也支持混合使用不同数据类型(精度)的操作数和累加器。这些操作的 API 参考文档(CUDA Tile C++ 矩阵乘法、cuTile Python matmul)中记录了秩和元素类型的约束。
下面的核函数采用了一种常见模式:无论输入精度如何,都以 FP32 进行累加,并在存储时转换为输出元素类型。在 Python 中,这使用ct.mma(a,b,acc),并配合 FP32 类型的acc。在 C++ 中,这使用ct::mma(a,b,acc),并显式指定 FP32 累加器类型。K 循环迭代ceil(K/tk)次,以覆盖 A 的右边缘和 B 的下边缘;不完整的 K 分块在加载时用零填充(Python 中为PaddingMode.ZERO,C++ 中为.load_masked()),C 一侧不完整的 M/N 边缘分块则通过存储侧丢弃越界(OOB)元素来处理(Python 中为ct.store,C++ 中为.store_masked())。
__tile_global__voidgemm(const__half*__restrict__A,const__half*__restrict__B,float*__restrict__C,std::size_tM,std::size_tK,std::size_tN){namespacect=cuda::tiles;usingnamespacect::literals;usingf32_acc=ct::tile<float,ct::shape<32,32>>;A=ct::assume_aligned(A,16_ic);B=ct::assume_aligned(B,16_ic);C=ct::assume_aligned(C,16_ic);constexprautotm=32_ic;constexprautotn=32_ic;constexprautotk=16_ic;autoaView=ct::partition_view{ct::tensor_span{A,ct::extents{M,K}},ct::shape{tm,tk}};autobView=ct::partition_view{ct::tensor_span{B,ct::extents{K,N}},ct::shape{tk,tn}};autocView=ct::partition_view{ct::tensor_span{C,ct::extents{M,N}},ct::shape{tm,tn}};auto[bx,by,bz]=ct::bid();autoacc=ct::full<f32_acc>(0.0f);// FP32 accumulatorstd::size_tnum_k=(K+tk-1)/tk;for(autok:ct::irange(std::size_t{0},num_k)){acc=ct::mma(aView.load_masked(bx,k),// zero-pad partial K-tilebView.load_masked(k,by),acc);// acc += a @ b}cView.store_masked(acc,bx,by);// drop OOB edge lanes}
@ct.kerneldefgemm(A,B,C,tm:ct.Constant[int],tn:ct.Constant[int],tk:ct.Constant[int]):bx,by=ct.bid(0),ct.bid(1)num_k=ct.num_tiles(A,axis=1,shape=(tm,tk))# number of K-tilesacc=ct.full((tm,tn),0,dtype=ct.float32)# FP32 accumulatorforkinrange(num_k):a=ct.load(A,index=(bx,k),shape=(tm,tk),padding_mode=ct.PaddingMode.ZERO)# zero-pad partial K-tileb=ct.load(B,index=(k,by),shape=(tk,tn),padding_mode=ct.PaddingMode.ZERO)acc=ct.mma(a,b,acc)# acc += a @ bct.store(C,index=(bx,by),tile=acc.astype(C.dtype))# cast + store
扫描是与归约对应的逐步累积操作,它沿某一轴生成累积结果。例如,前缀和(cumsum)生成的输出与输入维度相同,其中给定索引处的值是沿指定轴从起点到该索引(包含该索引)处所有元素之和。有关每种语言中可用操作的完整集合,请参阅 API 参考文档(CUDA Tile C++ 归约与扫描、cuTile Python 归约和扫描)。
逐元素选择是条件判断的分块形式:给定一个布尔分块和两个操作数分块,根据相应的布尔值,从其中一个操作数分块选取每个输出元素。条件会广播到操作数的形状;操作数类型必须兼容(有关各语言中的确切规则,请参阅 API 参考文档:CUDA Tile C++ select、cuTile Python 选择)。在 Python 中写作ct.where(cond,x,y);在 C++ 中写作ct::select(cond,lhs,rhs)。
__tile_global__voidblock_sum(int*__restrict__arr,int*__restrict__out,std::size_tN){namespacect=cuda::tiles;usingnamespacect::literals;constexprautoTILE=16_ic;arr=ct::assume_aligned(arr,16_ic);out=ct::assume_aligned(out,16_ic);autoaView=ct::partition_view{ct::tensor_span{arr,ct::extents{N}},ct::shape{TILE}};intbid=ct::bid().x;autotile=aView.load_masked(bid);// partial final tile -> OOB lanes default to 0autopartial=ct::sum(tile,0_ic);// reduce to a 1-element tilect::atomic_add(out,(int)partial,// accumulate the scalar into out[0]ct::memory_order_relaxed_t{},// single-location accumulator -> relaxed sufficesct::thread_scope_device_t{});// visible across the device}
@ct.kerneldefblock_sum(arr,out,TILE:ct.Constant[int]):bid=ct.bid(0)# partial final tile -> OOB lanes default to 0tile=ct.load(arr,index=(bid,),shape=(TILE,),padding_mode=ct.PaddingMode.ZERO)partial=ct.sum(tile)# reduce to a scalarout.tiled_view((1,)).atomic_store_add((0,),partial)# atomically accumulate into out[0]
usingi32x16=ct::tile<int,ct::shape<16>>;int*slot=/* pointer to the contended location */;// 16 lanes all aim at the same address. Add is commutative, so the// unspecified ordering doesn't affect this sum; block scope suffices// since contention stays within one block.autoptrs=ct::full<ct::tile<int*,ct::shape<16>>>(slot);ct::atomic_add(ptrs,ct::iota<i32x16>(),ct::memory_order_relaxed_t{},ct::thread_scope_block_t{});
[[cutile::hint(900,num_cta_in_cga=4),// sm_90: prefer 4 CTAs per clustercutile::hint(1000,num_cta_in_cga=8)]]// sm_100: prefer 8 CTAs per cluster__tile_global__voidoptimization_hints(float*__restrict__in,float*__restrict__out){namespacect=cuda::tiles;usingnamespacect::literals;in=ct::assume_aligned(in,16_ic);out=ct::assume_aligned(out,16_ic);autoinSpan=ct::tensor_span{in,ct::extents{128_ic}};autooutSpan=ct::tensor_span{out,ct::extents{128_ic}};autoinView=ct::partition_view{inSpan,ct::shape{8_ic}};autooutView=ct::partition_view{outSpan,ct::shape{8_ic}};intbx=ct::bid().x;// Expression-statement hint: tag this particular load as bandwidth-heavy.ct::tile<float,ct::shape<8>>tile;[[cutile::hint(0,latency=8)]]tile=inView.load(bx);outView.store(tile,bx);}
对于按架构指定的值,将值包装在cuda.tile.ByTarget(*,default=...,sm_XXX=...,sm_YYY=...)中。架构键必须是"sm_<major><minor>"形式的字符串(例如"sm_100"或"sm_120")。普通值(非ByTarget值)适用于所有目标,它在 Python 中等同于 C++ 中使用arch=0的与架构无关的提示。
下面的核函数是上面的 C++ 示例的直接 Python 对应版本:ByTarget携带核函数级提示,latency=8关键字携带逐调用提示,而replace_hints可在不编辑源代码的情况下生成重新调优的核函数。
@ct.kernel(num_ctas=ByTarget(sm_90=4,sm_100=8))defoptimization_hints(in_,out,TILE:ct.Constant[int]):bid=ct.bid(0)# Per-call hint: this particular load is bandwidth-heavy.tile=ct.load(in_,index=(bid,),shape=(TILE,),latency=8)ct.store(out,index=(bid,),tile=tile)# Autotuning: produce a new kernel with overridden hints without editing the# source. The new kernel has its own JIT cache.tuned_kernel=optimization_hints.replace_hints(num_ctas=8)
虽然编程接口是异步的,但实际能否并发执行各种操作取决于 CUDA 的版本和所用硬件的计算能力。这些细节将在本指南后面的章节中介绍(请参阅计算能力)。
在同步 CPU 和 GPU中,介绍了 CUDA 运行时函数cudaDeviceSynchronize(),这是一个阻塞调用,会等待此前发出的所有工作完成。之所以需要调用cudaDeviceSynchronize(),是因为核函数启动是异步的,会立即返回。CUDA 为阻塞和非阻塞这两种同步方式都提供了 API,甚至支持使用主机端回调函数。
CUDA 中用于异步执行的核心 API 组件是CUDA 流和CUDA 事件。在本节余下部分中,我们将解释如何使用这些元素来表达 CUDA 中的异步执行。
在流中执行的 API 函数调用和核函数启动相对于主机线程是异步的。应用程序可以通过等待流中不再有任务来与流同步,也可以在设备级别进行同步。
CUDA 有一个默认流,未指定具体流的操作和核函数启动会排入此默认流。未指定流的代码示例隐式地使用此默认流。默认流具有一些特定语义,将在阻塞流、非阻塞流和默认流小节中讨论。
2.5.2.1. 创建和销毁 CUDA 流
可以使用cudaStreamCreate()函数创建 CUDA 流。该函数调用会初始化流句柄,此句柄可在后续函数调用中用于标识该流。
cudaStream_tstream;// Stream handlecudaStreamCreate(&stream);// Create a new stream// stream based operations ...cudaStreamDestroy(stream);// Destroy the stream
// Wait for the stream to be empty of taskscudaStreamSynchronize(stream);// At this point the stream is done// and we can access the results of stream operations safely
如果不希望阻塞,而只需要快速检查流是否为空,可以使用cudaStreamQuery()函数。
// Have a peek at the stream// returns cudaSuccess if the stream is empty// returns cudaErrorNotReady if the stream is not emptycudaError_tstatus=cudaStreamQuery(stream);switch(status){casecudaSuccess:// The stream is emptystd::cout<<"The stream is empty"<<std::endl;break;casecudaErrorNotReady:// The stream is not emptystd::cout<<"The stream is not empty"<<std::endl;break;default:// An error occurred - we should handle thisbreak;};
2.5.3. CUDA 事件
CUDA 事件是一种向 CUDA 流中插入标记的机制。它们本质上类似于示踪粒子,可用于跟踪流中任务的进度。设想在一个流中启动两个核函数。如果没有这种跟踪事件,我们只能确定流是否为空。如果第三个操作,无论是在 CPU 上还是在另一个流中,依赖于第一个核函数的输出,那么只有在得知流已为空后,才能安全地开始该操作。流为空时,两个核函数都已完成。
使用 CUDA 事件可以做得更好。通过在第一个核函数之后、第二个核函数之前紧接着将一个事件排入流,我们可以让 CPU 线程或另一个流等待该事件到达流的队首。然后,我们就可以在已知第一个核函数完成、而第二个核函数尚未开始的情况下,安全地开始有依赖关系的操作。以这种方式使用 CUDA 事件可以构建操作和流之间的依赖关系图。这种图的类比直接对应于后面对CUDA 图的讨论。
CUDA 事件还会保存时间信息,可用于对核函数启动和内存传输计时。
2.5.3.1. 创建和销毁 CUDA 事件
可以使用cudaEventCreate()和cudaEventDestroy()函数创建和销毁 CUDA 事件。
cudaEvent_tevent;// Create the eventcudaEventCreate(&event);// do some work involving the event// Once the work is done and the event is no longer needed// we can destroy the eventcudaEventDestroy(event);
应用程序负责在不再需要事件时销毁它们。
2.5.3.2. 向 CUDA 流中插入事件
可以使用cudaEventRecord()函数将 CUDA 事件插入流中。
cudaEvent_tevent;cudaStream_tstream;// Create the eventcudaEventCreate(&event);// Insert the event into the streamcudaEventRecord(event,stream);
2.5.3.3. 对 CUDA 流中的操作计时
CUDA 事件可用于对各种流操作的执行计时,包括核函数。当事件到达流的队首时,它会记录一个时间戳。通过在流中的核函数前后各放置一个事件,可以准确测量核函数执行的持续时间,如下面的代码片段所示:
cudaStream_tstream;cudaStreamCreate(&stream);cudaEvent_tstart;cudaEvent_tstop;// create the eventscudaEventCreate(&start);cudaEventCreate(&stop);// record the start eventcudaEventRecord(start,stream);// launch the kernelkernel<<<grid,block,0,stream>>>(...);// record the stop eventcudaEventRecord(stop,stream);// wait for the stream to complete// both events will have been triggeredcudaStreamSynchronize(stream);// get the timingfloatelapsedTime;cudaEventElapsedTime(&elapsedTime,start,stop);std::cout<<"Kernel execution time: "<<elapsedTime<<" ms"<<std::endl;// clean upcudaEventDestroy(start);cudaEventDestroy(stop);cudaStreamDestroy(stream);
cudaEvent_tevent;cudaStream_tstream;// create the streamcudaStreamCreate(&stream);// create the eventcudaEventCreate(&event);// launch a kernel into the streamkernel<<<grid,block,0,stream>>>(...);// Record the eventcudaEventRecord(event,stream);// launch a kernel into the streamkernel2<<<grid,block,0,stream>>>(...);// Wait for the event to complete// Kernel 1 will be guaranteed to have completed// and we can launch the dependent task.cudaEventSynchronize(event);dependentCPUtask();// Wait for the stream to be empty// Kernel 2 is guaranteed to have completedcudaStreamSynchronize(stream);// destroy the eventcudaEventDestroy(event);// destroy the streamcudaStreamDestroy(stream);
可以使用cudaEventQuery()函数以非阻塞方式检查 CUDA 事件是否完成。在下面的示例中,我们在一个流中启动 2 个核函数。第一个核函数kernel1生成一些我们希望复制到主机的数据,但我们也有一些 CPU 端工作要做。在下面的代码中,我们依次将kernel1、一个事件(event)以及kernel2排入流stream1。随后,我们进入 CPU 工作循环,但会偶尔检查一下事件是否完成,这表明kernel1已经完成。如果是,就在流stream2中发起从设备到主机的复制。这种方式允许 CPU 工作与 GPU 核函数执行以及从设备到主机的复制重叠。
cudaEvent_tevent;cudaStream_tstream1;cudaStream_tstream2;size_tsize=LARGE_NUMBER;float*d_data;float*h_data;// Create some datacudaMalloc(&d_data,size);cudaMallocHost(&h_data,size);// create the streamscudaStreamCreate(&stream1);// Processing streamcudaStreamCreate(&stream2);// Copying streamboolcopyStarted=false;// create the eventcudaEventCreate(&event);// launch kernel1 into the streamkernel1<<<grid,block,0,stream1>>>(d_data,size);// enqueue an event following kernel1cudaEventRecord(event,stream1);// launch kernel2 into the streamkernel2<<<grid,block,0,stream1>>>();// while the kernels are running do some work on the CPU// but check if kernel1 has completed because then we will start// a device to host copy in stream2while(notallCPUWorkDone()||notcopyStarted){doNextChunkOfCPUWork();// peek to see if kernel 1 has completed// if so enqueue a non-blocking copy into stream2if(notcopyStarted){if(cudaEventQuery(event)==cudaSuccess){cudaMemcpyAsync(h_data,d_data,size,cudaMemcpyDeviceToHost,stream2);copyStarted=true;}}}// wait for both streams to be donecudaStreamSynchronize(stream1);cudaStreamSynchronize(stream2);// destroy the eventcudaEventDestroy(event);// destroy the streams and free the datacudaStreamDestroy(stream1);cudaStreamDestroy(stream2);cudaFree(d_data);free(h_data);
2.5.4. 来自流的回调函数
CUDA 提供了一种从流内在主机上启动函数的机制。目前有两个函数可用于此目的:cudaLaunchHostFunc()和cudaAddCallback()。不过,cudaAddCallback()已计划弃用,因此应用程序应使用cudaLaunchHostFunc()。
// Some work occurs in streams.cudaStreamSynchronize(stream);// Look at the last error but do not clear itcudaError_terr=cudaPeekAtLastError();if(err!=cudaSuccess){printf("Error with name: %s\n",cudaGetErrorName(err));printf("Error description: %s\n",cudaGetErrorString(err));}// Look at the last error and clear itcudaError_terr2=cudaGetLastError();if(err2!=cudaSuccess){printf("Error with name: %s\n",cudaGetErrorName(err2));printf("Error description: %s\n",cudaGetErrorString(err2));}if(err2!=err){printf("As expected, cudaPeekAtLastError() did not clear the error\n");}// Check againcudaError_terr3=cudaGetLastError();if(err3==cudaSuccess){printf("As expected, cudaGetLastError() cleared the error\n");}
CUDA 中有两种类型的流:阻塞流和非阻塞流。这些名称可能略具误导性,因为阻塞和非阻塞语义仅指这些流如何与默认流同步。默认情况下,通过cudaStreamCreate()创建的流是阻塞流。要创建非阻塞流,必须使用带有cudaStreamNonBlocking标志的cudaStreamCreateWithFlags()函数:
如果在来自不同流的两个操作之间提交了任何 NULL 流上的 CUDA 操作,那么这两个操作就不能并发运行,除非这些流是非阻塞流(使用cudaStreamNonBlocking标志创建)。
应用程序应遵循以下准则,以增加核函数并发执行的可能性:
所有独立操作都应在具有依赖关系的操作之前发出,
任何形式的同步都应尽可能推迟。
2.5.9. 其他主题与高级主题
2.5.9.1. 流优先级设置
如前所述,开发者可以为 CUDA 流分配优先级。带优先级的流需要使用cudaStreamCreateWithPriority()函数创建。该函数接受两个参数:流句柄和优先级。一般规则是,数值越小,优先级越高。可以使用cudaDeviceGetStreamPriorityRange()函数查询给定设备和上下文的优先级范围。流的默认优先级为 0。
intminPriority,maxPriority;// Query the priority range for the devicecudaDeviceGetStreamPriorityRange(&minPriority,&maxPriority);// Create two streams with different priorities// cudaStreamDefault indicates the stream should be created with default flags// in other words they will be blocking streams with respect to the legacy default stream// One could also use the option `cudaStreamNonBlocking` here to create a non-blocking streamscudaStream_tstream1,stream2;cudaStreamCreateWithPriority(&stream1,cudaStreamDefault,minPriority);// Lowest prioritycudaStreamCreateWithPriority(&stream2,cudaStreamDefault,maxPriority);// Highest priority
CUDA 流允许程序按顺序指定一系列操作,即核函数或内存复制。通过使用多个流以及通过cudaStreamWaitEvent建立的跨流依赖关系,应用程序可以指定一个完整的操作有向无环图(DAG)。某些应用程序可能有一个操作序列或操作 DAG,需要在执行过程中运行多次。
对于这种情况,CUDA 提供了一项称为 CUDA 图的功能。本节介绍 CUDA 图,以及一种称为流捕获的图创建机制。CUDA 图中对 CUDA 图进行了更详细的讨论。捕获或创建图有助于减少从主机线程反复调用同一串 API 调用的延迟和 CPU 开销。取而代之的是,可以只调用一次用于指定图操作的 API,然后多次执行所生成的图。
在其余步骤中,根据需要多次执行预先实例化的图。由于执行图操作所需的所有运行时结构都已就绪,因此图执行的 CPU 开销得以最小化。
代码清单 2使用 CUDA 图捕获、实例化和执行简单线性图的各个阶段(摘自CUDA 开发者技术博客,A. Gray,2019 年)
#define N 500000 // tuned such that kernel takes a few microseconds// A very lightweight kernel__global__voidshortKernel(float*out_d,float*in_d){intidx=blockIdx.x*blockDim.x+threadIdx.x;if(idx<N)out_d[idx]=1.23*in_d[idx];}boolgraphCreated=false;cudaGraph_tgraph;cudaGraphExec_tinstance;// The graph will be executed NSTEP timesfor(intistep=0;istep<NSTEP;istep++){if(!graphCreated){// Capture the graphcudaStreamBeginCapture(stream,cudaStreamCaptureModeGlobal);// Launch NKERNEL kernelsfor(intikrnl=0;ikrnl<NKERNEL;ikrnl++){shortKernel<<<blocks,threads,0,stream>>>(out_d,in_d);}// End the capturecudaStreamEndCapture(stream,&graph);// Instantiate the graphcudaGraphInstantiate(&instance,graph,NULL,NULL,0);graphCreated=true;}// Launch the graphcudaGraphLaunch(instance,stream);// Synchronize the streamcudaStreamSynchronize(stream);}
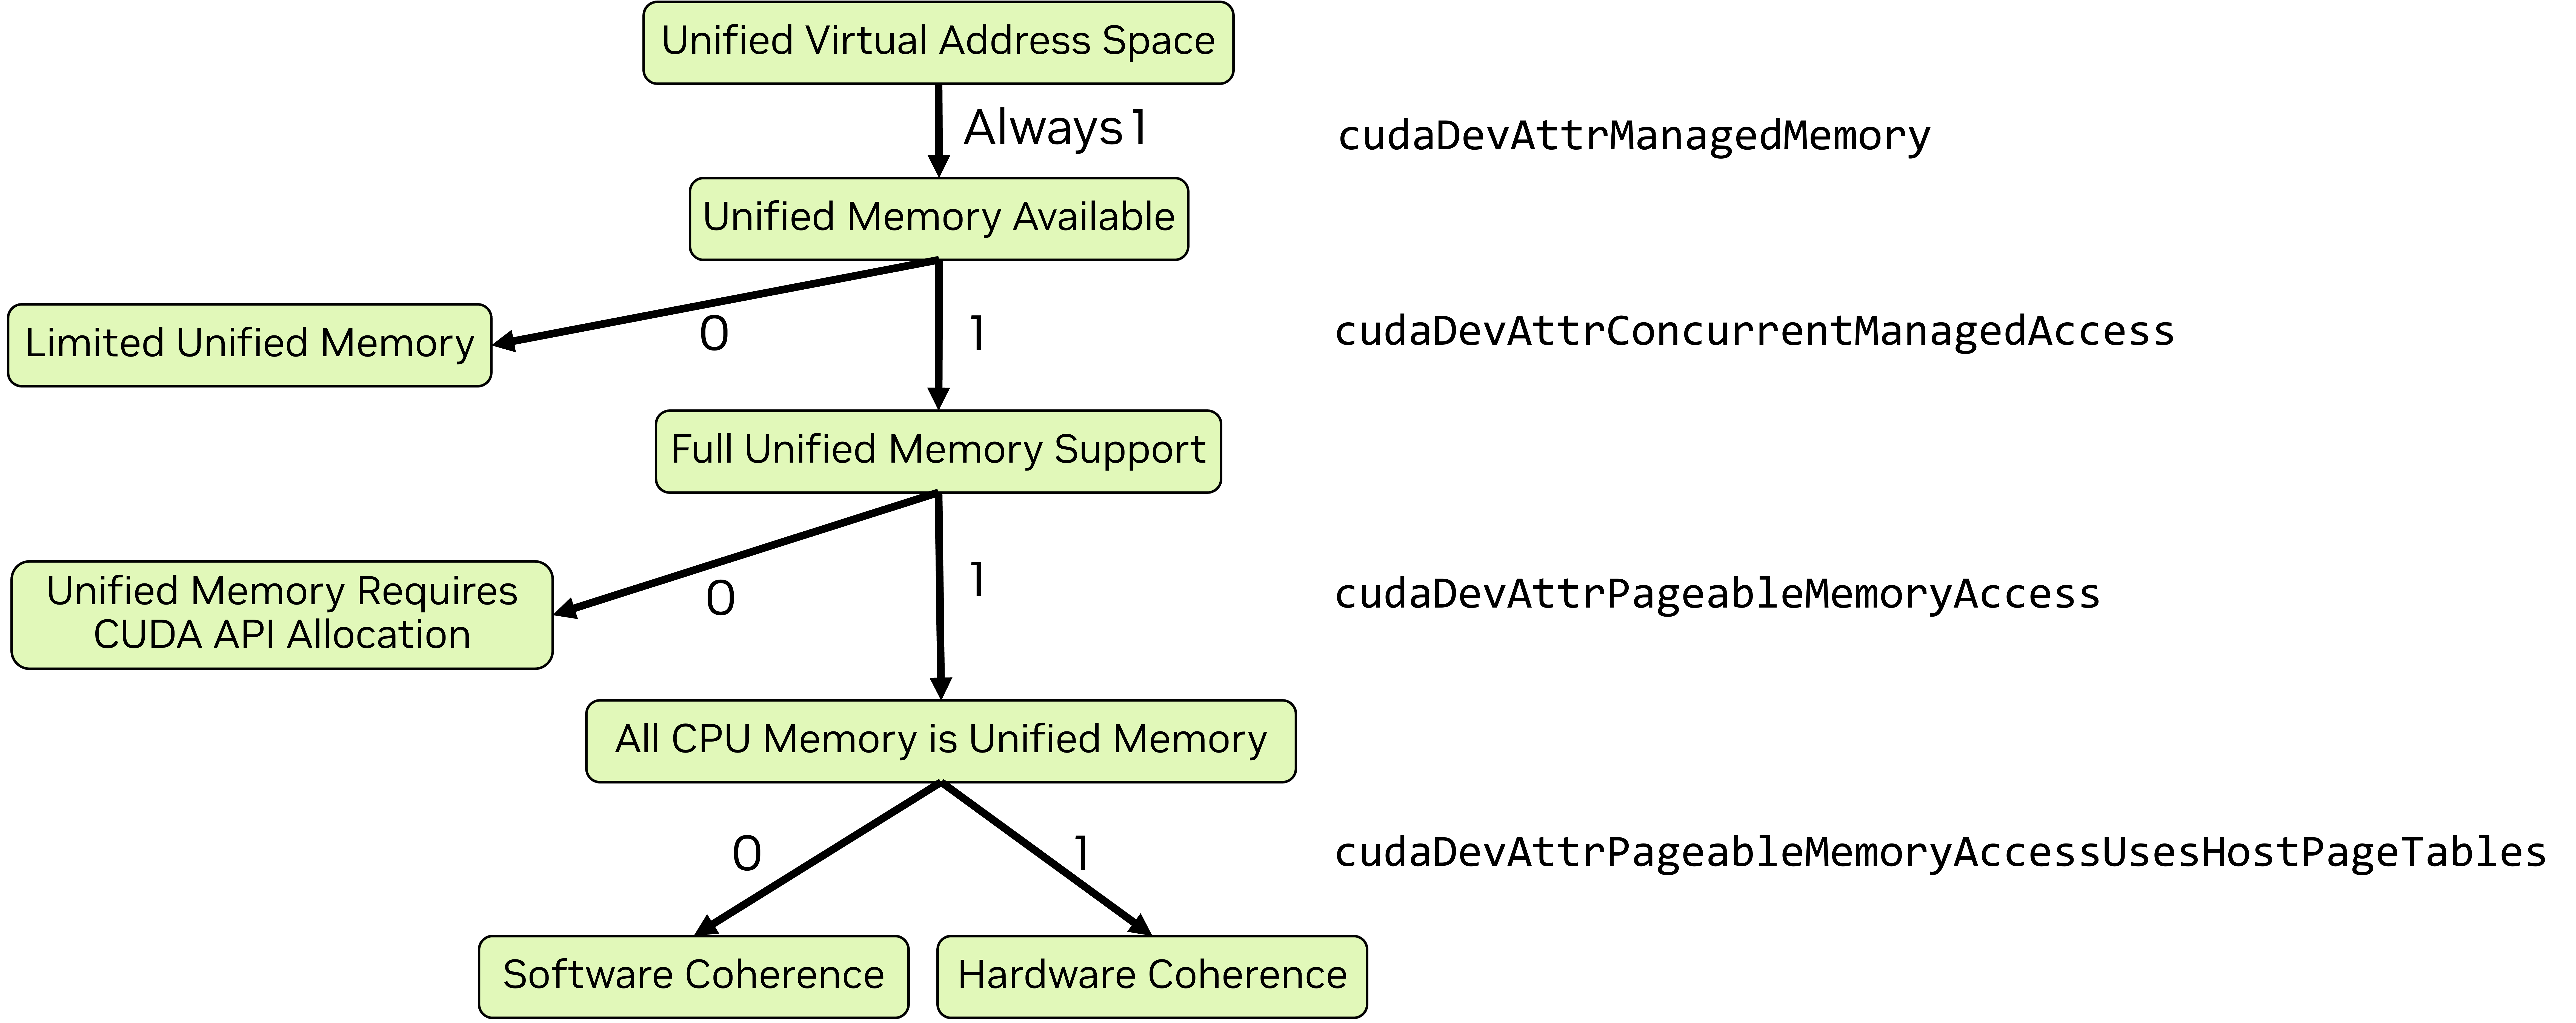
voidqueryDevices(){intnumDevices=0;cudaGetDeviceCount(&numDevices);for(inti=0;i<numDevices;i++){cudaSetDevice(i);cudaInitDevice(0,0,0);intdeviceId=i;intconcurrentManagedAccess=-1;cudaDeviceGetAttribute(&concurrentManagedAccess,cudaDevAttrConcurrentManagedAccess,deviceId);intpageableMemoryAccess=-1;cudaDeviceGetAttribute(&pageableMemoryAccess,cudaDevAttrPageableMemoryAccess,deviceId);intpageableMemoryAccessUsesHostPageTables=-1;cudaDeviceGetAttribute(&pageableMemoryAccessUsesHostPageTables,cudaDevAttrPageableMemoryAccessUsesHostPageTables,deviceId);printf("Device %d has ",deviceId);if(concurrentManagedAccess){if(pageableMemoryAccess){printf("full unified memory support");if(pageableMemoryAccessUsesHostPageTables){printf(" with hardware coherency\n");}else{printf(" with software coherency\n");}}else{printf("full unified memory support for CUDA-made managed allocations\n");}}else{printf("limited unified memory support: Windows, WSL, or Tegra\n");}}}
2.6.2.2. 统一内存功能的完整支持
大多数 Linux 系统都完整支持统一内存。如果设备属性cudaDevAttrPageableMemoryAccess为 1,则所有系统内存,无论是通过 CUDA API 还是系统 API 分配的,都作为具有完整功能支持的统一内存运行。这包括使用mmap创建的文件后备内存分配。
如果cudaDevAttrPageableMemoryAccess为 0,则只有由 CUDA 分配为托管内存的内存才具有统一内存的行为。通过系统 API 分配的内存不是托管内存,GPU 核函数不一定能够访问它。
当 ATS 和 HMM 不可用时,仍可使用cudaHostRegister对系统分配器分配的内存进行映射,以便 GPU 核函数直接访问。不过,与使用 CUDA API 创建的内存不同,核函数不能使用主机指针访问这类内存。必须使用cudaHostGetDevicePointer()获取设备内存区域中的指针,并且必须使用该指针在核函数代码中进行访问。
nvcc--list-gpu-code# list all supported real GPU architectures
nvcc--list-gpu-arch# list all supported virtual GPU architectures
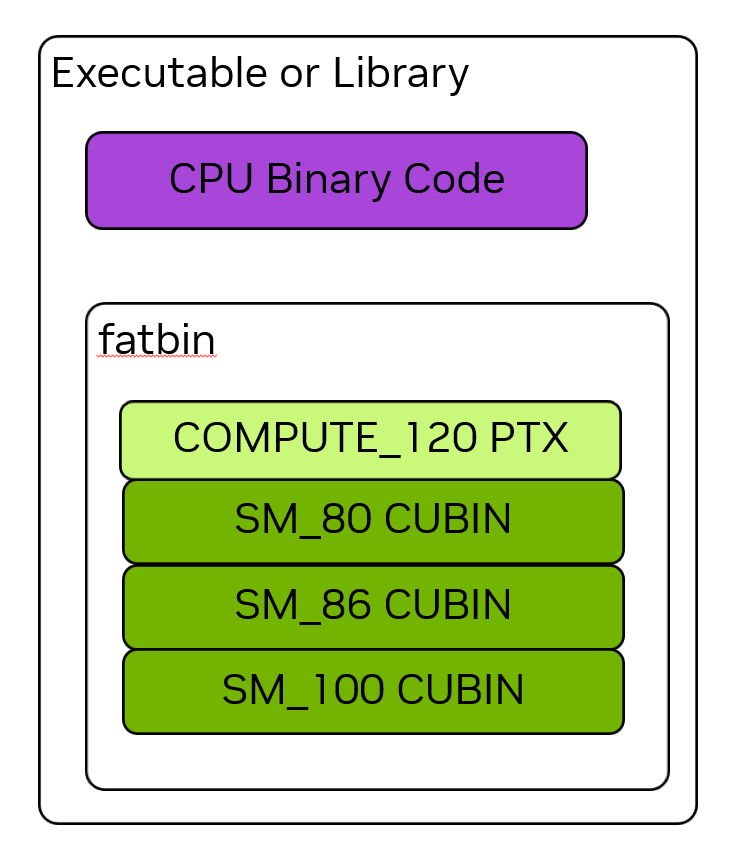
nvccexample.cu-arch=compute_<XY># e.g. -arch=compute_80 for NVIDIA Ampere GPUs and later# PTX-only, GPU forward compatible
nvccexample.cu-arch=sm_<XY># e.g. -arch=sm_80 for NVIDIA Ampere GPUs and later# PTX and Cubin, GPU forward compatible
nvccexample.cu-arch=native# automatically detects and generates Cubin for the current GPU# no PTX, no GPU forward compatibility
nvccexample.cu-arch=all# generate Cubin for all supported GPU architectures# also includes the latest PTX for GPU forward compatibility
nvccexample.cu-arch=all-major# generate Cubin for all major supported GPU architectures, e.g. sm_80, sm_90,# also includes the latest PTX for GPU forward compatibility
更高级的用法允许分别指定 PTX 和 Cubin 目标:
# generate PTX for virtual architecture compute_80 and compile it to Cubin for real architecture sm_86, keep compute_80 PTX
nvccexample.cu-arch=compute_80-gpu-code=sm_86,compute_80# (PTX and Cubin)# generate PTX for virtual architecture compute_80 and compile it to Cubin for real architecture sm_86, sm_89
nvccexample.cu-arch=compute_80-gpu-code=sm_86,sm_89# (no PTX)
nvccexample.cu-gencode=arch=compute_80,code=sm_86,sm_89# same as above# (1) generate PTX for virtual architecture compute_80 and compile it to Cubin for real architecture sm_86, sm_89# (2) generate PTX for virtual architecture compute_90 and compile it to Cubin for real architecture sm_90
nvccexample.cu-gencode=arch=compute_80,code=sm_86,sm_89-gencode=arch=compute_90,code=sm_90
不包含设备代码或符号的编译单元(即一个源文件及其头文件)可以直接使用主机编译器编译。如果任何编译单元使用 CUDA 运行时 API 函数,则应用程序必须链接 CUDA 运行时库。CUDA 运行时同时提供静态库和共享库,分别为libcudart_static和libcudart。默认情况下,nvcc链接静态 CUDA 运行时库。要使用 CUDA 运行时的共享库版本,请在编译或链接命令中向nvcc传递--cudart=shared标志。
某些 CUDA 特性可以受益于随核函数启动一起提供的附加属性和提示。cudaLaunchKernelEx使程序能够通过cudaLaunchConfig_t结构设置上述执行配置参数。此外,cudaLaunchConfig_t结构允许程序传入零个或多个cudaLaunchAttributes,以控制核函数启动的其他参数或为这些参数提供建议。例如,本章稍后讨论的cudaLaunchAttributePreferredSharedMemoryCarveout(请参阅配置 L1/共享内存平衡)使用cudaLaunchKernelEx指定。本章稍后讨论的cudaLaunchAttributeClusterDimension属性用于指定核函数启动所需的簇大小。
// Kernel definition// No compile time attribute attached to the kernel__global__voidcluster_kernel(float*input,float*output){}intmain(){float*input,*output;dim3threadsPerBlock(16,16);dim3numBlocks(N/threadsPerBlock.x,N/threadsPerBlock.y);// Kernel invocation with runtime cluster size{cudaLaunchConfig_tconfig={0};// The grid dimension is not affected by cluster launch, and is still enumerated// using number of blocks.// The grid dimension should be a multiple of cluster size.config.gridDim=numBlocks;config.blockDim=threadsPerBlock;cudaLaunchAttributeattribute[1];attribute[0].id=cudaLaunchAttributeClusterDimension;attribute[0].val.clusterDim.x=2;// Cluster size in X-dimensionattribute[0].val.clusterDim.y=1;attribute[0].val.clusterDim.z=1;config.attrs=attribute;config.numAttrs=1;cudaLaunchKernelEx(&config,cluster_kernel,input,output);}}
// Implementation detail of how many threads per block and blocks per cluster// is handled as an attribute of the kernel.__block_size__((1024,1,1),(2,2,2))__global__voidfoo();// 8x8x8 clusters.foo<<<dim3(8,8,8)>>>();
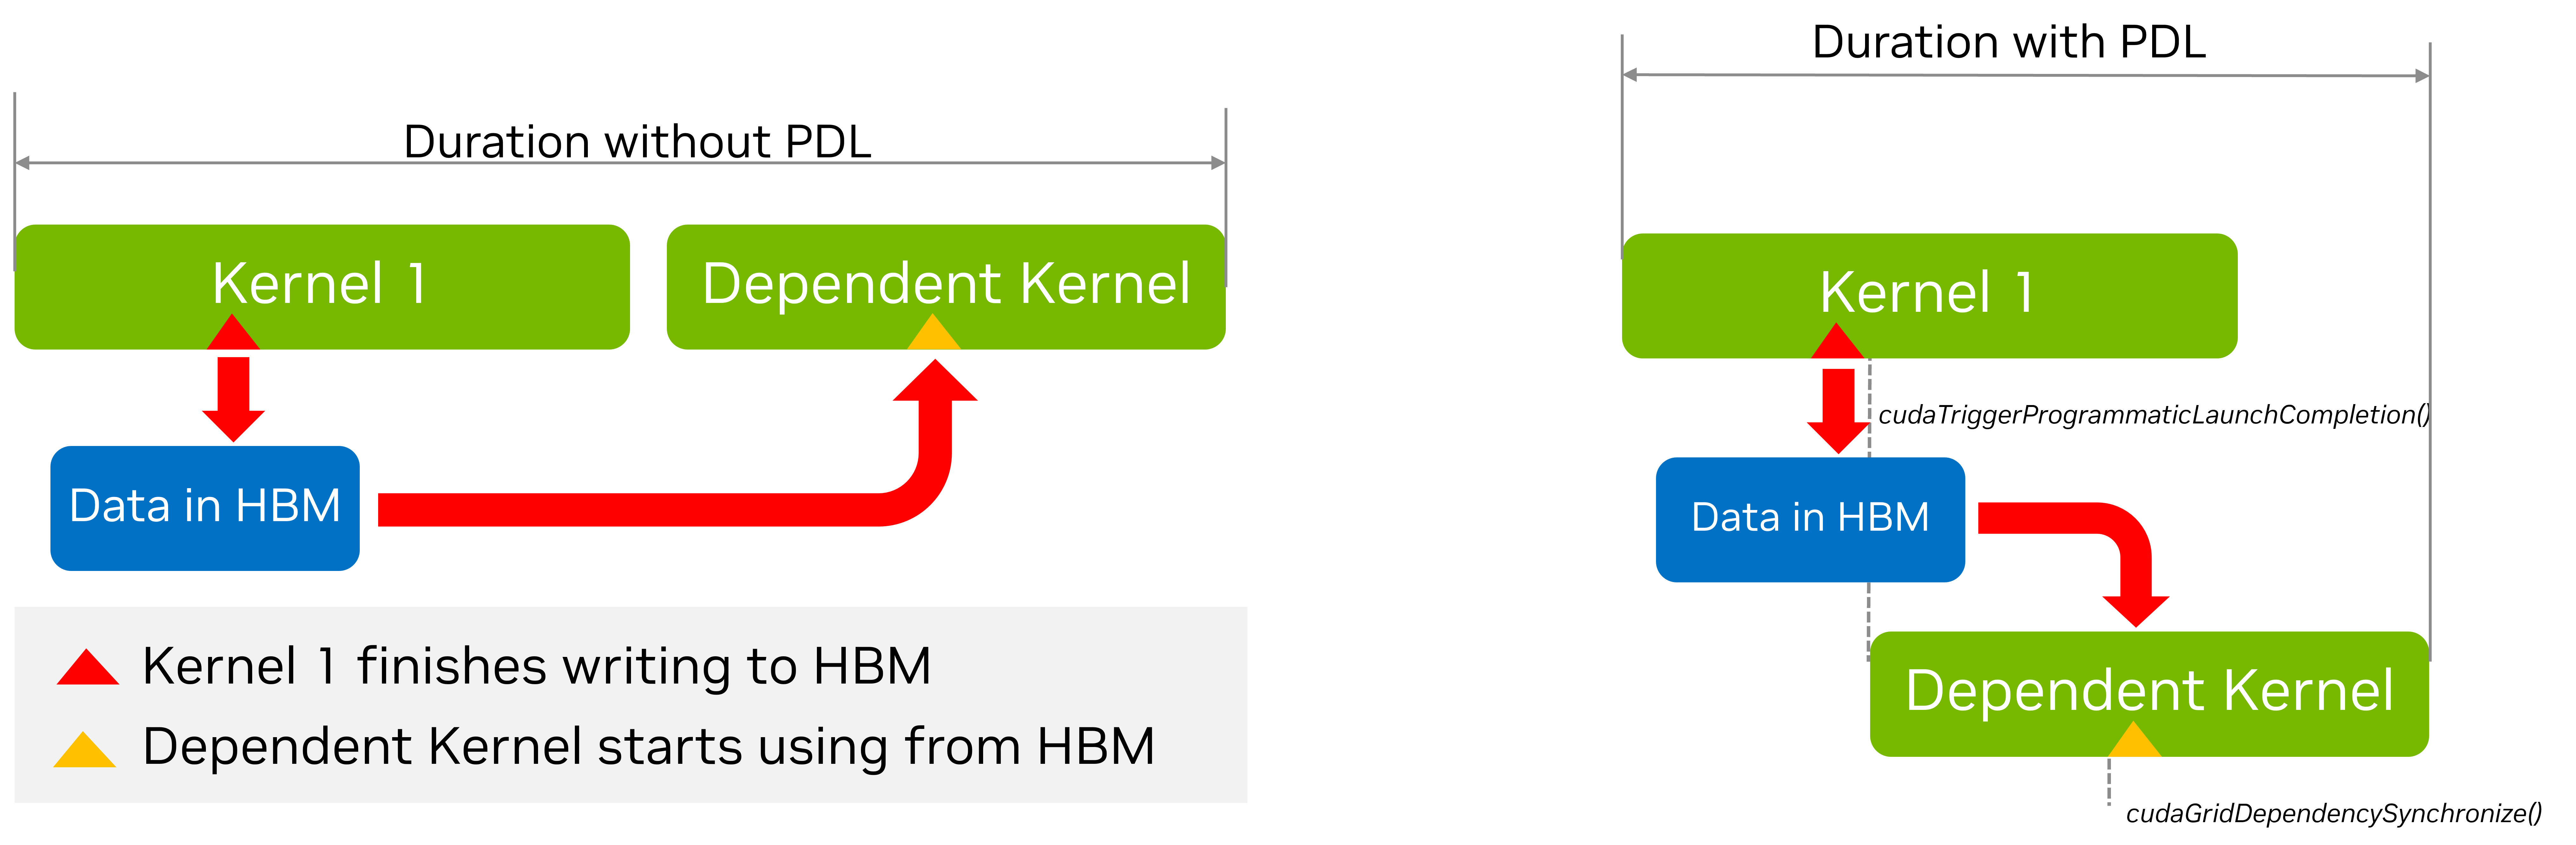
CUDA 流介绍了 CUDA 流的基础知识。默认情况下,在给定 CUDA 流上提交的操作是串行化的:一个操作必须等到前一个操作完成后才能开始执行。唯一的例外是最近添加的程序化依赖启动与同步特性。使用多个 CUDA 流是启用并发执行的一种方式;另一种方式是使用CUDA 图。这两种方法也可以结合使用。
在不同 CUDA 流上提交的工作,在特定情况下可能会并发执行,例如,不存在事件依赖、不存在隐式同步、资源充足等。
如果在来自不同 CUDA 流的独立操作之间向 NULL 流提交了任何 CUDA 操作,则这些独立操作无法并发运行,除非这些流是非阻塞 CUDA 流。非阻塞 CUDA 流是使用带有cudaStreamNonBlocking标志的cudaStreamCreateWithFlags()运行时 API 创建的流。为了提高 GPU 工作并发执行的可能性,建议用户创建非阻塞 CUDA 流。
还建议用户选择足以解决其问题且适用范围最小的同步选项。例如,如果要求 CPU 等待(阻塞),直到特定 CUDA 流上的所有工作完成,那么对该流使用cudaStreamSynchronize()会优于使用cudaDeviceSynchronize(),因为后者会不必要地等待该设备所有 CUDA 流上的 GPU 工作完成。如果要求 CPU 以非阻塞方式等待,那么使用cudaStreamQuery()并在轮询循环中检查其返回值可能更为合适。
使用 CUDA 事件(CUDA 事件)也可以实现类似的同步效果,例如,在该流上记录一个事件,然后调用cudaEventSynchronize()以阻塞方式等待该事件所捕获的工作完成。同样,与使用cudaDeviceSynchronize()相比,这样做更合适,也更有针对性。调用cudaEventQuery()并检查其返回值(例如在轮询循环中)则是一种非阻塞的替代方式。
对于 CUDA 流之间的同步,即表达依赖关系,建议使用不计时的 CUDA 事件,如CUDA 事件中所述。用户可以调用cudaStreamWaitEvent(),强制以后在特定流上提交的操作等待先前记录的事件(例如,在另一个流上记录的事件)完成。注意,对于任何等待或查询事件的 CUDA API,用户都有责任确保已经调用了 cudaEventRecord API,因为未记录的事件将始终返回成功。
CUDA 事件默认带有计时信息,因为它们可以用于cudaEventElapsedTime()API 调用。然而,仅用于表达跨流依赖关系的 CUDA 事件不需要计时信息。对于此类情况,建议在创建事件时禁用计时信息,以提高性能。可以通过使用带有cudaEventDisableTiming标志的cudaEventCreateWithFlags()API 来实现这一点。
以下代码示例获取当前设备允许的优先级范围,并创建两个非阻塞 CUDA 流,分别具有可用的最高和最低优先级。
// get the range of stream priorities for this deviceintleastPriority,greatestPriority;cudaDeviceGetStreamPriorityRange(&leastPriority,&greatestPriority);// create streams with highest and lowest available prioritiescudaStream_tst_high,st_low;cudaStreamCreateWithPriority(&st_high,cudaStreamNonBlocking,greatestPriority));cudaStreamCreateWithPriority(&st_low,cudaStreamNonBlocking,leastPriority);
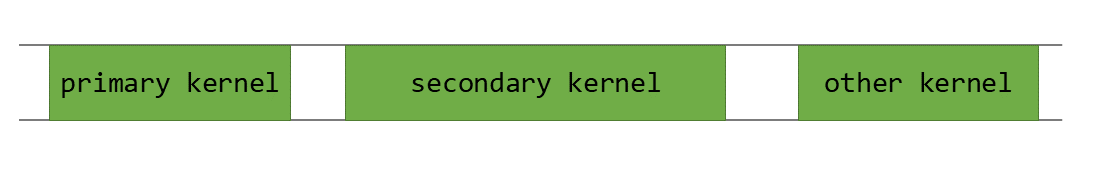
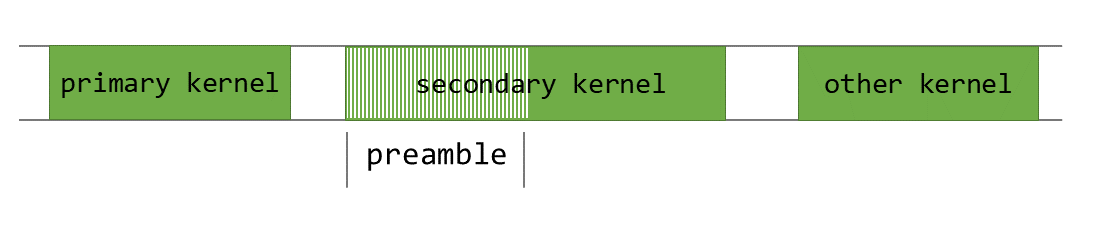
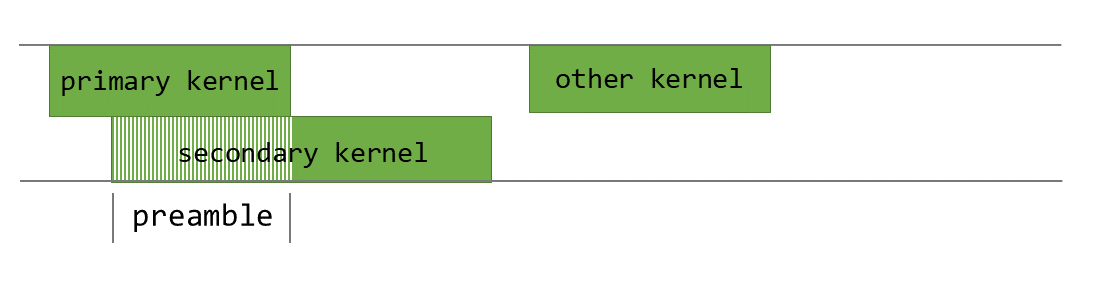
__global__voidprimary_kernel(){// Initial work that should finish before starting secondary kernel// Trigger the secondary kernelcudaTriggerProgrammaticLaunchCompletion();// Work that can coincide with the secondary kernel}__global__voidsecondary_kernel(){// Initialization, Independent work, etc.// Will block until all primary kernels the secondary kernel is dependent on have// completed and flushed results to global memorycudaGridDependencySynchronize();// Dependent work}// Launch the secondary kernel with the special attribute// Set Up the attributecudaLaunchAttributeattribute[1];attribute[0].id=cudaLaunchAttributeProgrammaticStreamSerialization;attribute[0].val.programmaticStreamSerializationAllowed=1;// Set the attribute in a kernel launch configurationcudaLaunchConfig_tconfig={0};// Base launch configurationconfig.gridDim=grid_dim;config.blockDim=block_dim;config.dynamicSmemBytes=0;config.stream=stream;// Add special attribute for PDLconfig.attrs=attribute;config.numAttrs=1;// Launch primary kernelprimary_kernel<<<grid_dim,block_dim,0,stream>>>();// Launch secondary (dependent) kernel using the configuration with// the attributecudaLaunchKernelEx(&config,secondary_kernel);
3.1.5. 批量内存传输
CUDA 开发中的一种常见模式是使用批处理技术。宽泛地说,批处理是指将若干个(通常较小的)任务组合成一个(通常较大的)操作。一批任务中的各个组成部分不一定都必须相同,尽管它们通常是相同的。cuBLAS 提供的批量矩阵乘法操作就是这一思路的一个示例。
一般而言,与 CUDA Graphs 和 PDL 一样,批处理的目的是减少分别调度一批任务中的各个任务所带来的开销。对于内存传输,启动一次内存传输可能会产生一些 CPU 和驱动程序开销。此外,当前形式的常规cudaMemcpyAsync()函数不一定能为驱动程序提供足够的信息来优化传输,例如有关源和目标的提示。在 Tegra 平台上,可以选择使用 SM 或复制引擎(CE)执行传输。目前,具体选择哪一种由驱动程序中的启发式方法决定。这可能很重要,因为使用 SM 可能会使传输更快,但也会占用一部分可用的计算能力。另一方面,使用 CE 可能会使传输较慢,但应用程序的整体性能更高,因为这样可让 SM 空闲出来执行其他工作。
这些考虑促成了cudaMemcpyBatchAsync()函数(及其相关函数cudaMemcpyBatch3DAsync())的设计。这些函数允许优化批量内存传输。除了源指针和目标指针列表外,该 API 还使用内存复制属性来指定对顺序的预期,并提供源位置和目标位置的提示,以及是否倾向于使传输与计算重叠的提示(目前仅在具有 CE 的 Tegra 平台上支持这一点)。
首先考虑最简单的情况,即将数据从页锁定主机内存简单地批量传输到页锁定设备内存
代码清单 4 从页锁定主机内存到页锁定设备内存的同构批量内存传输示例
std::vector<void*>srcs(batch_size);std::vector<void*>dsts(batch_size);std::vector<size_t>sizes(batch_size);// Allocate the source and destination buffers// initialize with the stream numberfor(size_ti=0;i<batch_size;i++){cudaMallocHost(&srcs[i],sizes[i]);cudaMalloc(&dsts[i],sizes[i]);cudaMemsetAsync(srcs[i],sizes[i],stream);}// Setup attributes for this batch of copiescudaMemcpyAttributesattrs={};attrs.srcAccessOrder=cudaMemcpySrcAccessOrderStream;// All copies in the batch have same copy attributes.size_tattrsIdxs=0;// Index of the attributes// Launch the batched memory transfercudaMemcpyBatchAsync(&dsts[0],&srcs[0],&sizes[0],batch_size,&attrs,&attrsIdxs,1/*numAttrs*/,nullptr/*failIdx*/,stream);
std::vector<void*>srcs(batch_size);std::vector<void*>dsts(batch_size);std::vector<size_t>sizes(batch_size);// Allocate the src and dst buffersfor(size_ti=0;i<batch_size-10;i++){cudaMallocHost(&srcs[i],sizes[i]);cudaMalloc(&dsts[i],sizes[i]);}intbuffer[10];for(size_ti=batch_size-10;i<batch_size;i++){srcs[i]=&buffer[10-(batch_size-i];cudaMalloc(&dsts[i],sizes[i]);}// Setup attributes for this batch of copiescudaMemcpyAttributesattrs[2]={};attrs[0].srcAccessOrder=cudaMemcpySrcAccessOrderStream;attrs[1].srcAccessOrder=cudaMemcpySrcAccessOrderDuringApiCall;size_tattrsIdxs[2];attrsIdxs[0]=0;attrsIdxs[1]=batch_size-10;// Launch the batched memory transfercudaMemcpyBatchAsync(&dsts[0],&srcs[0],&sizes[0],batch_size,&attrs,&attrsIdxs,2/*numAttrs*/,nullptr/*failIdx*/,stream);
这里有两种传输:从页锁定主机内存到页锁定设备内存的batch_size-10次传输,以及从主机数组到页锁定设备内存的 10 次传输。此外,buffer数组不仅位于主机上,而且仅存在于当前作用域内,其地址就是所谓的临时指针。此指针在 API 调用完成后可能不再有效(该调用是异步的)。要使用此类临时指针执行复制,必须将属性中的srcAccessOrder设置为cudaMemcpySrcAccessOrderDuringApiCall。
cudaMemcpyBatchAsync函数还允许程序员提供有关源位置和目标位置的提示。这通过设置cudaMemcpyAttributes结构的srcLocation和dstLocation字段来完成。这两个srcLocation``and``dstLocation字段的类型均为cudaMemLocation,它是一个包含位置类型和位置 ID 的结构。这与使用cudaMemPrefetchAsync()时可用于向运行时提供预取提示的cudaMemLocation结构相同。下面的代码示例展示了如何为从设备到主机特定 NUMA 节点的传输设置提示:
代码清单 6 设置源位置和目标位置提示的示例
// Allocate the source and destination buffersstd::vector<void*>srcs(batch_size);std::vector<void*>dsts(batch_size);std::vector<size_t>sizes(batch_size);// cudaMemLocation structures we will use tp provide location hints// Device device_idcudaMemLocationsrcLoc={cudaMemLocationTypeDevice,dev_id};// Host with numa Node numa_idcudaMemLocationdstLoc={cudaMemLocationTypeHostNuma,numa_id};// Allocate the src and dst buffersfor(size_ti=0;i<batch_size;i++){cudaMallocManaged(&srcs[i],sizes[i]);cudaMallocManaged(&dsts[i],sizes[i]);cudaMemPrefetchAsync(srcs[i],sizes[i],srcLoc,0,stream);cudaMemPrefetchAsync(dsts[i],sizes[i],dstLoc,0,stream);cudaMemsetAsync(srcs[i],sizes[i],stream);}// Setup attributes for this batch of copiescudaMemcpyAttributesattrs={};// These are managed memory pointers so Stream Order is appropriateattrs.srcAccessOrder=cudaMemcpySrcAccessOrderStream;// Now we can specify the location hints here.attrs.srcLocHint=srcLoc;attrs.dstlocHint=dstLoc;// All copies in the batch have same copy attributes.size_tattrsIdxs=0;// Launch the batched memory transfercudaMemcpyBatchAsync(&dsts[0],&srcs[0],&sizes[0],batch_size,&attrs,&attrsIdxs,1/*numAttrs*/,nullptr/*failIdx*/,stream);
最后要介绍的是用于提示我们希望使用 SM 还是 CE 进行传输的标志。用于此目的的字段是cudaMemcpyAttributesflags::flags,可能的取值如下:
cudaMemcpyFlagDefault:默认行为
cudaMemcpyFlagPreferOverlapWithCompute:这提示系统应优先使用 CE 进行传输,使传输与计算重叠。
总之,关于“cudaMemcpyBatchAsync”的要点如下:
cudaMemcpyBatchAsync函数(及其 3D 变体)允许程序员指定一批内存传输,从而分摊传输设置开销。
除了源指针、目标指针和传输大小之外,该函数还可以接受一个或多个内存复制属性,用于提供有关所传输内存的类型及源指针对应的流顺序行为的信息、有关源位置和目标位置的提示,以及是否优先选择让传输与计算重叠(如果可能),或者是否使用 SM 进行传输的提示。
根据上述信息,运行时可以尝试尽最大可能优化传输。
3.1.6. 环境变量
CUDA 提供了各种环境变量(参见第 5.2 节),这些变量可能会影响执行和性能。如果未显式设置它们,CUDA 会为其使用合理的默认值,但可能需要根据具体情况进行特殊处理,例如用于调试或提高性能。
例如,可能需要增大CUDA_DEVICE_MAX_CONNECTIONS环境变量的值,以降低来自不同 CUDA 流的独立工作因伪依赖而被串行化的可能性。当使用相同的底层资源时,可能会引入此类伪依赖。建议先使用默认值,仅在出现性能问题时才探索此环境变量的影响(例如,不同 CUDA 流中的独立工作出现了意外的串行化,而且无法归因于缺少可用 SM 资源等其他因素)。值得注意的是,在 MPS 情况下,此环境变量的默认值有所不同(更低)。
并行线程执行(PTX)是 CUDA 用于抽象硬件 ISA 的虚拟机指令集架构(ISA),已在第 1.3.3 节中介绍。直接使用 PTX 编写代码是一项非常高级的优化技术,对大多数开发者而言并无必要,应将其视为最后才使用的手段。尽管如此,在某些情况下,直接编写 PTX 所提供的细粒度控制能够提高特定应用程序的性能。这些情况通常出现在应用程序中对性能非常敏感的部分,在这些部分中,任何不足百分之一的性能提升都会带来显著收益。所有可用的 PTX 指令均列于PTX ISA 文档中。
cuda::ptx命名空间
在代码中直接使用 PTX 的一种方法是使用libcu++中的cuda::ptx命名空间。该命名空间提供了直接映射到 PTX 指令的 C++ 函数,从而简化了在 C++ 应用程序中使用这些指令的方式。有关更多信息,请参阅cuda::ptx 命名空间文档。
内联 PTX
在代码中包含 PTX 的另一种方法是使用内联 PTX。相应的文档中详细描述了此方法。这与在 CPU 上编写汇编代码非常相似。
3.2.2. 硬件实现
流式多处理器(SM,参见GPU 硬件模型)旨在并发执行数百个线程。为了管理如此大量的线程,它采用了一种独特的并行计算模型,称为单指令、多线程,或SIMT,该模型在SIMT 执行模型中进行了说明。指令采用流水线执行,既利用单个线程内的指令级并行性,也通过同时硬件多线程利用广泛的线程级并行性,详见硬件多线程。与 CPU 核心不同,SM 按顺序发出指令,不执行分支预测或推测执行。
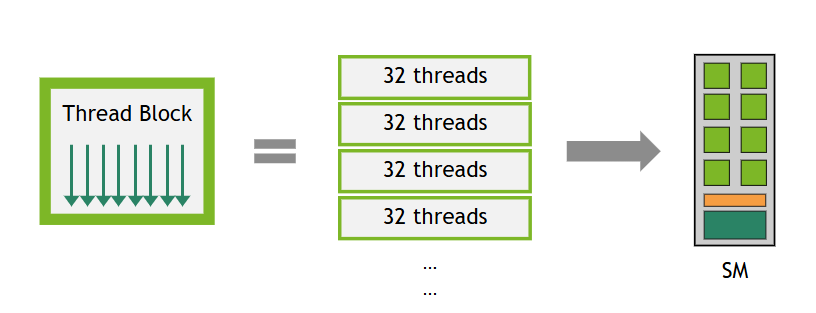
每个 SM 都以一组 32 个并行线程为单位创建、管理、调度和执行线程,这样的一组线程称为线程束。组成一个线程束的各个线程从相同的程序地址一起开始执行,但它们具有各自的指令地址计数器和寄存器状态,因此可以自由地独立分支和执行。线程束一词源于编织,这是最早的并行线技术。半线程束是一个线程束的前半部分或后半部分。四分之一线程束是一个线程束的第一个、第二个、第三个或第四个四分之一部分。
当一个 SM 被分配一个或多个线程块来执行时,它会将这些线程块划分为线程束,每个线程束由一个线程束调度器调度执行。线程块划分为线程束的方式始终相同;每个线程束包含线程 ID 连续递增的线程,第一个线程束包含线程 0。线程层次结构介绍了线程 ID 与线程块内线程索引之间的关系。
线程块中的线程束总数定义如下:
T是每个线程块中的线程数,
Wsize是线程束大小,等于 32,
ceil(x, y) 等于将 x 向上舍入到最近的 y 的整数倍。
图 22一个线程块被划分为多个各含 32 个线程的线程束。
图内文字中文对照
Thread Block
线程块
32 threads
32 个线程
SM
流式多处理器
SM 所处理的每个线程束的执行上下文(程序计数器、寄存器等)在该线程束的整个生命周期内都保留在芯片上。因此,在线程束之间切换不会产生任何开销。在每个指令发射周期,线程束调度器选择一个线程束,该线程束中有线程已准备好执行下一条指令(即线程束中的活跃线程),并向这些线程发射该指令。
每个 SM 都有一组在线程束之间分配的 32 位寄存器,以及一块在线程块之间分配的共享内存。对于给定的核函数,能够驻留在 SM 上并被并发处理的线程块数和线程束数,取决于核函数使用的寄存器和共享内存的数量,以及 SM 上可用的寄存器和共享内存的数量。每个 SM 上的驻留线程块数和线程束数也有最大值。这些限制以及 SM 上可用的寄存器和共享内存数量都取决于设备的计算能力,具体规定见计算能力。如果每个 SM 上没有足够的可用资源来处理至少一个线程块,核函数将无法启动。可以通过占用率一节中介绍的几种方式来确定为一个线程块分配的寄存器总数和共享内存总量。
3.2.2.3. 异步执行特性
近几代 NVIDIA GPU 都包含了异步执行能力,以便在 GPU 内部实现更多的数据移动、计算和同步重叠。这些能力使从 GPU 代码中调用的某些操作能够相对于同一线程块中的其他 GPU 代码异步执行。不应将这种异步执行与第 2.5 节中讨论的异步 CUDA API 混淆,后者使 GPU 核函数启动或内存操作能够相对于彼此或相对于 CPU 异步进行。
在通用代理中运行的异步线程。发起异步操作时,该操作会与一个异步线程关联,该线程不同于发起操作的 CUDA 线程。保证对同一地址的先前通用代理(普通)加载和存储在顺序上位于该异步操作之前。但是,不保证对同一地址的后续普通加载和存储保持其顺序,因此在异步线程完成之前,可能产生竞争条件。
在异步代理中运行的异步线程。发起异步操作时,该操作会与一个异步线程关联,该线程不同于发起操作的 CUDA 线程。不保证对同一地址的先前和后续普通加载和存储保持其顺序。需要使用代理栅栏在不同代理之间同步这些操作,以确保正确的内存顺序。使用张量内存加速器(TMA)一节展示了如何使用代理栅栏,确保使用 TMA 执行异步复制时的正确性。
CUDA 线程构成了一个线程层次结构,利用这一层次结构对于编写既正确又高性能的 CUDA 核函数至关重要。在这一层次结构中,内存操作的可见性和同步作用域可能各不相同。为处理这种非均一性,CUDA 编程模型引入了线程作用域的概念。线程作用域定义了哪些线程能够观察到某个线程的加载和存储,并规定了哪些线程能够使用原子操作和屏障等同步原语相互同步。每个作用域在内存层次结构中都有一个关联的相干点。
#include<cuda/atomic>__global__voidblock_scoped_counter(){// Shared atomic counter visible only within this block__shared__cuda::atomic<int,cuda::thread_scope_block>counter;// Initialize counter (only one thread should do this)if(threadIdx.x==0){counter.store(0,cuda::memory_order_relaxed);}__syncthreads();// All threads in block atomically incrementintold_value=counter.fetch_add(1,cuda::memory_order_relaxed);// Use old_value...}
__global__voidblock_scoped_counter(){// Shared counter visible only within this block__shared__intcounter;// Initialize counter (only one thread should do this)if(threadIdx.x==0){__nv_atomic_store_n(&counter,0,__NV_ATOMIC_RELAXED,__NV_THREAD_SCOPE_BLOCK);}__syncthreads();// All threads in block atomically incrementintold_value=__nv_atomic_fetch_add(&counter,1,__NV_ATOMIC_RELAXED,__NV_THREAD_SCOPE_BLOCK);// Use old_value...}
__global__voidproducer_consumer(){__shared__intdata;__shared__cuda::atomic<bool,cuda::thread_scope_block>ready;if(threadIdx.x==0){// Producer: write data then signal readydata=42;ready.store(true,cuda::memory_order_release);// Release ensures data write is visible}else{// Consumer: wait for ready signal then read datawhile(!ready.load(cuda::memory_order_acquire)){// Acquire ensures data read sees the write// spin wait}intvalue=data;// Process value...}}
__global__voidproducer_consumer(){__shared__intdata;__shared__boolready;// Only ready flag needs atomic operationsif(threadIdx.x==0){// Producer: write data then signal readydata=42;__nv_atomic_store_n(&ready,true,__NV_ATOMIC_RELEASE,__NV_THREAD_SCOPE_BLOCK);// Release ensures data write is visible}else{// Consumer: wait for ready signal then read datawhile(!__nv_atomic_load_n(&ready,__NV_ATOMIC_ACQUIRE,__NV_THREAD_SCOPE_BLOCK)){// Acquire ensures data read sees the write// spin wait}intvalue=data;// Process value...}}
3.2.4.1.2. 性能注意事项
尽可能使用最小的作用域:线程块作用域的原子操作比系统作用域的原子操作快得多。
优先使用较弱的顺序约束:只有在确保正确性所必需时,才使用更强的顺序约束。
考虑内存位置:共享内存原子操作比全局内存原子操作更快。
3.2.4.2. 异步屏障
异步屏障与典型的单阶段屏障(__syncthreads())的区别在于,线程发出其已到达屏障的通知(“到达”)与等待其他线程到达屏障的操作(“等待”)是分离的。这种分离允许线程执行与屏障无关的其他操作,从而更有效地利用等待时间,提高执行效率。异步屏障可用于通过 CUDA 线程实现生产者-消费者模式,也可以让复制操作在完成时向屏障发出信号(“到达”屏障),从而支持内存层次结构中的异步数据复制。
计算能力为 7.0 或更高的设备支持异步屏障。计算能力为 8.0 或更高的设备为共享内存中的异步屏障提供硬件加速,并且允许对线程块内 CUDA 线程的任意子集进行硬件加速同步,从而显著提升了同步粒度。此前的架构只能在整个线程束(__syncwarp())或整个线程块(__syncthreads())级别加速同步。
CUDA 编程模型通过cuda::std::barrier提供异步屏障,它是libcu++库中提供的、符合 ISO C++ 标准的屏障。除了实现std::barrier之外,该库还提供了 CUDA 专用扩展,可选择屏障的线程作用域以提升性能,并公开了更底层的cuda::ptx API。cuda::barrier可以通过使用friend函数cuda::device::barrier_native_handle()获取屏障的原生句柄并将其传递给cuda::ptx函数,来与cuda::ptx互操作。CUDA 还为线程块作用域下共享内存中的异步屏障提供了原语 API。
#include<cooperative_groups.h>__global__voidsimple_sync(intiteration_count){autoblock=cooperative_groups::this_thread_block();for(inti=0;i<iteration_count;++i){/* code before arrive */// Wait for all threads to arrive here.block.sync();/* code after wait */}}
#include<cuda/barrier>#include<cooperative_groups.h>__device__voidcompute(float*data,intiteration);__global__voidsplit_arrive_wait(intiteration_count,float*data){usingbarrier_t=cuda::barrier<cuda::thread_scope_block>;__shared__barrier_tbar;autoblock=cooperative_groups::this_thread_block();if(block.thread_rank()==0){// Initialize barrier with expected arrival count.init(&bar,block.size());}block.sync();for(inti=0;i<iteration_count;++i){/* code before arrive */// This thread arrives. Arrival does not block a thread.barrier_t::arrival_tokentoken=bar.arrive();compute(data,i);// Wait for all threads participating in the barrier to complete bar.arrive().bar.wait(std::move(token));/* code after wait */}}
#include<cuda/ptx>#include<cooperative_groups.h>__device__voidcompute(float*data,intiteration);__global__voidsplit_arrive_wait(intiteration_count,float*data){__shared__uint64_tbar;autoblock=cooperative_groups::this_thread_block();if(block.thread_rank()==0){// Initialize barrier with expected arrival count.cuda::ptx::mbarrier_init(&bar,block.size());}block.sync();for(inti=0;i<iteration_count;++i){/* code before arrive */// This thread arrives. Arrival does not block a thread.uint64_ttoken=cuda::ptx::mbarrier_arrive(&bar);compute(data,i);// Wait for all threads participating in the barrier to complete mbarrier_arrive().while(!cuda::ptx::mbarrier_try_wait(&bar,token)){}/* code after wait */}}
#include<cuda_awbarrier_primitives.h>#include<cooperative_groups.h>__device__voidcompute(float*data,intiteration);__global__voidsplit_arrive_wait(intiteration_count,float*data){__shared____mbarrier_tbar;autoblock=cooperative_groups::this_thread_block();if(block.thread_rank()==0){// Initialize barrier with expected arrival count.__mbarrier_init(&bar,block.size());}block.sync();for(inti=0;i<iteration_count;++i){/* code before arrive */// This thread arrives. Arrival does not block a thread.__mbarrier_token_ttoken=__mbarrier_arrive(&bar);compute(data,i);// Wait for all threads participating in the barrier to complete __mbarrier_arrive().while(!__mbarrier_try_wait(&bar,token,1000)){}/* code after wait */}}
#include<cooperative_groups.h>__device__voidcompute(int*global_out,intconst*shared_in){// Computes using all values of current batch from shared memory.// Stores this thread's result back to global memory.}__global__voidwithout_async_copy(int*global_out,intconst*global_in,size_tsize,size_tbatch_sz){autogrid=cooperative_groups::this_grid();autoblock=cooperative_groups::this_thread_block();assert(size==batch_sz*grid.size());// Exposition: input size fits batch_sz * grid_sizeextern__shared__intshared[];// block.size() * sizeof(int) bytessize_tlocal_idx=block.thread_rank();for(size_tbatch=0;batch<batch_sz;++batch){// Compute the index of the current batch for this block in global memory.size_tblock_batch_idx=block.group_index().x*block.size()+grid.size()*batch;size_tglobal_idx=block_batch_idx+threadIdx.x;shared[local_idx]=global_in[global_idx];// Wait for all copies to complete.block.sync();// Compute and write result to global memory.compute(global_out+block_batch_idx,shared);// Wait for compute using shared memory to finish.block.sync();}}
#include<cooperative_groups.h>#include<cooperative_groups/memcpy_async.h>__device__voidcompute(int*global_out,intconst*shared_in){// Computes using all values of current batch from shared memory.// Stores this thread's result back to global memory.}__global__voidwith_async_copy(int*global_out,intconst*global_in,size_tsize,size_tbatch_sz){autogrid=cooperative_groups::this_grid();autoblock=cooperative_groups::this_thread_block();assert(size==batch_sz*grid.size());// Exposition: input size fits batch_sz * grid_sizeextern__shared__intshared[];// block.size() * sizeof(int) bytessize_tlocal_idx=block.thread_rank();for(size_tbatch=0;batch<batch_sz;++batch){// Compute the index of the current batch for this block in global memory.size_tblock_batch_idx=block.group_index().x*block.size()+grid.size()*batch;// Whole thread-group cooperatively copies whole batch to shared memory.cooperative_groups::memcpy_async(block,shared,global_in+block_batch_idx,block.size());// Compute on different data while waiting.// Wait for all copies to complete.cooperative_groups::wait(block);// Compute and write result to global memory.compute(global_out+block_batch_idx,shared);// Wait for compute using shared memory to finish.block.sync();}}
此示例展示了所有异步复制操作背后的基本概念:它们将内存传输的发起与完成分离开来,允许线程在数据于后台移动的同时执行其他工作。CUDA 编程模型提供了多种 API 来使用这些功能,包括协作组和libcu++库中提供的memcpy_async函数,以及更底层的cuda::ptx和原语 API。这些 API 具有相似的语义:它们将对象从源位置复制到目标位置,如同由另一个线程执行一样,并且在复制完成后,可以通过不同的完成机制与该线程同步。
另一个 CUDA APIcudaFuncSetCacheConfig也允许应用程序调整核函数的 L1 与共享内存之间的平衡。不过,此 API 对核函数启动时共享内存与 L1 之间的平衡设置了硬性要求。因此,交错执行具有不同共享内存配置的核函数,会不必要地使启动操作串行化,排在共享内存重新配置之后。更推荐使用cudaFuncSetAttribute,因为驱动程序可以在执行该函数所需时或为了避免抖动而选择不同的配置。
本指南前面的各节介绍了 CUDA 运行时。如CUDA 运行时 API 和 CUDA 驱动程序 API中所述,CUDA 运行时是在更底层的 CUDA 驱动程序 API 之上编写的。本节介绍 CUDA 运行时 API 与驱动程序 API 之间的一些差异,以及如何混合使用它们。大多数应用程序无需与 CUDA 驱动程序 API 交互即可获得全部性能。不过,新的接口有时会先在驱动程序 API 中提供,之后才在运行时 API 中提供;某些高级接口(例如虚拟内存管理)则仅通过驱动程序 API 公开。
驱动程序 API 在cuda动态库(cuda.dll或cuda.so)中实现,该库会在安装设备驱动程序时复制到系统上。它的所有入口点均以 cu 为前缀。
intmain(){intN=...;size_tsize=N*sizeof(float);// Allocate input vectors h_A and h_B in host memoryfloat*h_A=(float*)malloc(size);float*h_B=(float*)malloc(size);// Initialize input vectors...// InitializecuInit(0);// Get number of devices supporting CUDAintdeviceCount=0;cuDeviceGetCount(&deviceCount);if(deviceCount==0){printf("There is no device supporting CUDA.\n");exit(0);}// Get handle for device 0CUdevicecuDevice;cuDeviceGet(&cuDevice,0);// Create contextCUcontextcuContext;cuCtxCreate(&cuContext,0,cuDevice);// Create module from binary fileCUmodulecuModule;cuModuleLoad(&cuModule,"VecAdd.ptx");// Allocate vectors in device memoryCUdeviceptrd_A;cuMemAlloc(&d_A,size);CUdeviceptrd_B;cuMemAlloc(&d_B,size);CUdeviceptrd_C;cuMemAlloc(&d_C,size);// Copy vectors from host memory to device memorycuMemcpyHtoD(d_A,h_A,size);cuMemcpyHtoD(d_B,h_B,size);// Get function handle from moduleCUfunctionvecAdd;cuModuleGetFunction(&vecAdd,cuModule,"VecAdd");// Invoke kernelintthreadsPerBlock=256;intblocksPerGrid=(N+threadsPerBlock-1)/threadsPerBlock;void*args[]={&d_A,&d_B,&d_C,&N};cuLaunchKernel(vecAdd,blocksPerGrid,1,1,threadsPerBlock,1,1,0,0,args,0);...}
完整代码可在vectorAddDrvCUDA 示例中找到。
3.3.1. 上下文
CUDA 上下文类似于 CPU 进程。驱动程序 API 中的所有资源以及执行的操作都封装在 CUDA 上下文内,系统会在上下文销毁时自动清理这些资源。除模块以及纹理引用或表面引用等对象外,每个上下文还有自己独立的地址空间。因此,不同上下文中的CUdeviceptr值引用不同的内存位置。
一个主机线程在任一时刻只能有一个当前设备上下文。使用cuCtxCreate()创建上下文时,该上下文会被设为调用方主机线程的当前上下文。如果线程没有有效的当前上下文,则在上下文中操作的 CUDA 函数(大多数不涉及设备枚举或上下文管理的函数)将返回CUDA_ERROR_INVALID_CONTEXT。
驱动程序 API 可与运行时互操作,并且可以从驱动程序 API 通过cuDevicePrimaryCtxRetain()访问由运行时管理的主上下文(参见运行时初始化)。
使用计数有助于在同一上下文中运行的第三方编写的代码之间实现互操作。例如,如果加载了三个库以使用同一个上下文,则每个库都会调用cuCtxAttach()来增加使用计数,并在库使用完该上下文后调用cuCtxDetach()来减少使用计数。对于大多数库,预期应用程序会在加载或初始化库之前创建上下文;这样,应用程序就可以使用自己的启发式策略来创建上下文,而库只需在传递给它的上下文上操作。如果库希望在其 API 客户端不知情的情况下创建自己的上下文(这些客户端可能已经创建了自己的上下文,也可能没有),则会使用cuCtxPushCurrent()和cuCtxPopCurrent(),如下图所示。
图 23 库的上下文管理
图内文字中文对照
Library Initialization Call
库初始化调用
Initialize context
初始化上下文
Library Call
库调用
Use context
使用上下文
3.3.2. 模块
模块是可动态加载的设备代码和数据包,类似于 Windows 中的 DLL,由 nvcc 输出(参见使用 NVCC 编译)。所有符号的名称(包括函数、全局变量以及纹理引用或表面引用)都在模块作用域内维护,因此,由独立第三方编写的模块可以在同一个 CUDA 上下文中互操作。
#define BUFFER_SIZE 8192CUmodulecuModule;CUjit_optionoptions[3];void*values[3];char*cubinCode="some cubin code";charerror_log[BUFFER_SIZE];interr;options[0]=CU_JIT_ERROR_LOG_BUFFER;values[0]=(void*)error_log;options[1]=CU_JIT_ERROR_LOG_BUFFER_SIZE_BYTES;values[1]=(void*)BUFFER_SIZE;options[2]=CU_JIT_BINARY_LOADER_THREAD_COUNT;values[2]=0;// Use as many threads as CPUs on the machineerr=cuModuleLoadDataEx(&cuModule,cubinCode,3,options,values);if(err!=CUDA_SUCCESS)printf("Link error:\n%s\n",error_log);
完整代码可在ptxjitCUDA 示例中找到。
3.3.3. 核函数执行
cuLaunchKernel()使用给定的执行配置启动核函数。
参数可以作为指针数组(cuLaunchKernel()的倒数第二个参数)传递,其中第 n 个指针对应于第 n 个参数,并指向用于复制该参数的源内存区域;也可以作为额外选项之一(cuLaunchKernel()的最后一个参数)传递。
如果通过驱动程序 API 创建上下文并将其设为当前上下文,则后续的运行时调用将使用此上下文,而不是创建新的上下文。
如果运行时已初始化,则可使用cuCtxGetCurrent()获取初始化期间创建的上下文。后续的驱动程序 API 调用可以使用此上下文。
由运行时隐式创建的上下文称为主上下文(参见运行时初始化)。可以从驱动程序 API 使用主上下文管理函数来管理它。
使用任一 API 都可以分配和释放设备内存。CUdeviceptr可以强制转换为普通指针,反之亦然:
CUdeviceptrdevPtr;float*d_data;// Allocation using driver APIcuMemAlloc(&devPtr,size);d_data=(float*)devPtr;// Allocation using runtime APIcudaMalloc(&d_data,size);devPtr=(CUdeviceptr)d_data;
具体而言,这意味着使用驱动程序 API 编写的应用程序可以调用使用运行时 API 编写的库(如 cuFFT、cuBLAS 等)。
size_tsize=1024*sizeof(float);cudaSetDevice(0);// Set device 0 as currentfloat*p0;cudaMalloc(&p0,size);// Allocate memory on device 0MyKernel<<<1000,128>>>(p0);// Launch kernel on device 0cudaSetDevice(1);// Set device 1 as currentfloat*p1;cudaMalloc(&p1,size);// Allocate memory on device 1MyKernel<<<1000,128>>>(p1);// Launch kernel on device 1
3.4.1.3. 多设备流、事件和内存复制行为
如果向一个不与当前设备关联的流发出核函数启动请求,则启动将失败,如以下代码示例所示。
cudaSetDevice(0);// Set device 0 as currentcudaStream_ts0;cudaStreamCreate(&s0);// Create stream s0 on device 0MyKernel<<<100,64,0,s0>>>();// Launch kernel on device 0 in s0cudaSetDevice(1);// Set device 1 as currentcudaStream_ts1;cudaStreamCreate(&s1);// Create stream s1 on device 1MyKernel<<<100,64,0,s1>>>();// Launch kernel on device 1 in s1// This kernel launch will fail, since stream s0 is not associated to device 1:MyKernel<<<100,64,0,s0>>>();// Launch kernel on device 1 in s0
cudaSetDevice(0);// Set device 0 as currentfloat*p0;size_tsize=1024*sizeof(float);cudaMalloc(&p0,size);// Allocate memory on device 0cudaSetDevice(1);// Set device 1 as currentfloat*p1;cudaMalloc(&p1,size);// Allocate memory on device 1cudaSetDevice(0);// Set device 0 as currentMyKernel<<<1000,128>>>(p0);// Launch kernel on device 0cudaSetDevice(1);// Set device 1 as currentcudaMemcpyPeer(p1,1,p0,0,size);// Copy p0 to p1MyKernel<<<1000,128>>>(p1);// Launch kernel on device 1
cudaSetDevice(0);// Set device 0 as currentfloat*p0;size_tsize=1024*sizeof(float);cudaMalloc(&p0,size);// Allocate memory on device 0MyKernel<<<1000,128>>>(p0);// Launch kernel on device 0cudaSetDevice(1);// Set device 1 as currentcudaDeviceEnablePeerAccess(0,0);// Enable peer-to-peer access// with device 0// Launch kernel on device 1// This kernel launch can access memory on device 0 at address p0MyKernel<<<1000,128>>>(p0);
与为所有设备内存分配启用对等内存访问相比,一种可扩展性更好的替代方法是使用 CUDA 虚拟内存管理 API,仅在需要时,在分配期间显式分配可供对等设备访问的内存区域。通过在内存分配期间显式请求对等可访问性,不可供对等设备访问的内存分配的运行时开销不会受到影响,同时可供对等设备访问的数据结构也能被正确限定作用域,从而改善软件调试并提高可靠性(参见 ref::virtual-memory-management)。
在 CUDA 核函数代码中,异步数据复制是指在共享内存与 GPU DRAM 之间移动数据的同时仍能进行计算的能力。不应将其与 CPU 和 GPU 之间的异步内存复制混淆。此功能使用异步屏障。第 4.12 节详细介绍了异步复制的使用。
3.5.1.3. 流水线
流水线是一种用于将工作分阶段并协调多缓冲区生产者-消费者模式的机制,通常用于使计算与异步数据复制重叠执行。第 4.11 节提供了在 CUDA 中使用流水线的详细信息和示例。
3.5.1.4. 通过簇启动控制进行工作窃取
工作窃取是一种在不均衡工作负载中维持利用率的技术,已完成工作的工作者可以从其他工作者那里“窃取”任务。簇启动控制是计算能力 10.0(Blackwell)中引入的一项功能,它使核函数能够直接控制在途线程块调度,从而实时适应不均衡的工作负载。一个线程块可以取消另一个尚未开始的线程块或簇的启动,认领其索引,并立即开始执行窃取的工作。这种工作窃取流程可在数据不规则或运行时存在变化的情况下使 SM 保持忙碌并缩短空闲时间,实现更细粒度的负载均衡,而不必仅依赖硬件调度器。
绿色上下文也称为执行上下文,是一项 CUDA 功能的名称,该功能使程序能够创建仅在 GPU 的一部分 SM 上执行工作的CUDA 上下文。默认情况下,一次核函数启动的线程块会被分派到 GPU 内任何能够满足该核函数资源要求的 SM 上。许多因素会影响哪些 SM 可以执行某个线程块,包括但不一定限于:共享内存使用量、寄存器使用量、簇的使用以及线程块中的线程总数。
执行上下文允许将核函数启动到专门创建的上下文中,该上下文会进一步限制可用于执行核函数的 SM 数量。重要的是,当程序创建使用某一组 SM 的绿色上下文时,GPU 上的其他上下文不会将线程块调度到分配给该绿色上下文的 SM 上。这也包括主上下文,即 CUDA 运行时使用的默认上下文。这使得这些 SM 可以为高优先级或延迟敏感的工作负载预留。
CUDA 应用程序最常见的做法是从 CPU 上运行的代码中启动核函数。也可以从 GPU 上运行的核函数中创建新的核函数调用。这项特性称为CUDA 动态并行。第 4.20 节详细介绍了如何从 GPU 上运行的代码中创建新的 GPU 核函数启动。
3.5.4. CUDA 互操作性
3.5.4.1. CUDA 与其他 API 的互操作性
除了 CUDA 之外,还有其他在 GPU 上运行代码的机制。GPU 最初为之提供加速的应用领域,即计算机图形学,使用自己的一套 API,例如 Direct3D 和 Vulkan。应用程序可能希望在使用 CUDA 进行计算的同时,使用某个图形 API 进行 3D 渲染。CUDA 提供了在 CUDA 上下文与 3D API 所用的 GPU 上下文之间交换 GPU 上存储的数据的机制。例如,应用程序可以使用 CUDA 进行仿真,然后使用 3D API 对结果进行可视化。这是通过使某些缓冲区能够同时由 CUDA 和图形 API 读取和/或写入来实现的。
允许与图形 API 共享缓冲区的相同机制,也用于与通信机制共享缓冲区,这些通信机制可以在多节点环境中实现快速、直接的 GPU 到 GPU 通信。
第 4.21 节介绍了 CUDA 如何与其他 GPU API 互操作,以及如何在 CUDA 与其他 API 之间共享数据,并针对多种不同的 API 提供了具体示例。
驱动入口点访问是指从 CUDA 11.3 开始提供的获取 CUDA 驱动 API 和 CUDA 运行时 API 函数指针的能力。它还允许开发者获取驱动函数特定变体的函数指针,以及访问比 CUDA 工具包中可用的驱动更新的驱动所提供的驱动函数。第 4.22 节介绍了驱动入口点访问。
3.5.5.4. 错误日志管理
错误日志管理提供了用于处理和记录 CUDA API 错误的实用工具。只需设置一个环境变量CUDA_LOG_FILE,即可将 CUDA 错误直接捕获到 stderr、stdout 或文件中。错误日志管理还允许应用程序注册一个回调,在 CUDA 遇到错误时触发该回调。第 4.9 节提供了有关错误日志管理的更多详细信息。
完全支持 CUDA 统一内存的系统允许设备访问与该设备交互的主机进程所拥有的任何内存,请参见统一内存范式概览表。
本节展示几个高级用例,使用的核函数只是将输入字符数组的前 8 个字符打印到标准输出流:
__global__voidkernel(constchar*type,constchar*data){staticconstintn_char=8;printf("%s - first %d characters: '",type,n_char);for(inti=0;i<n_char;++i)printf("%c",data[i]);printf("'\n");}
以下选项卡展示了使用系统分配的内存调用此核函数的各种方式:
voidtest_malloc(){constchartest_string[]="Hello World";char*heap_data=(char*)malloc(sizeof(test_string));strncpy(heap_data,test_string,sizeof(test_string));kernel<<<1,1>>>("malloc",heap_data);ASSERT(cudaDeviceSynchronize()==cudaSuccess,"CUDA failed with '%s'",cudaGetErrorString(cudaGetLastError()));free(heap_data);}
voidtest_managed(){constchartest_string[]="Hello World";char*data;cudaMallocManaged(&data,sizeof(test_string));strncpy(data,test_string,sizeof(test_string));kernel<<<1,1>>>("managed",data);ASSERT(cudaDeviceSynchronize()==cudaSuccess,"CUDA failed with '%s'",cudaGetErrorString(cudaGetLastError()));cudaFree(data);}
voidtest_stack(){constchartest_string[]="Hello World";kernel<<<1,1>>>("stack",test_string);ASSERT(cudaDeviceSynchronize()==cudaSuccess,"CUDA failed with '%s'",cudaGetErrorString(cudaGetLastError()));}
voidtest_static(){staticconstchartest_string[]="Hello World";kernel<<<1,1>>>("static",test_string);ASSERT(cudaDeviceSynchronize()==cudaSuccess,"CUDA failed with '%s'",cudaGetErrorString(cudaGetLastError()));}
constcharglobal_string[]="Hello World";voidtest_global(){kernel<<<1,1>>>("global",global_string);ASSERT(cudaDeviceSynchronize()==cudaSuccess,"CUDA failed with '%s'",cudaGetErrorString(cudaGetLastError()));}
// declared in separate file, see belowexternchar*ext_data;voidtest_extern(){kernel<<<1,1>>>("extern",ext_data);ASSERT(cudaDeviceSynchronize()==cudaSuccess,"CUDA failed with '%s'",cudaGetErrorString(cudaGetLastError()));}
/** This may be a non-CUDA file */char*ext_data;staticconstcharglobal_string[]="Hello World";void__attribute__((constructor))setup(void){ext_data=(char*)malloc(sizeof(global_string));strncpy(ext_data,global_string,sizeof(global_string));}void__attribute__((destructor))tear_down(void){free(ext_data);}
请注意,extern 变量可以由完全不与 CUDA 交互的第三方库声明,其内存也可以由该库拥有和管理。
// this variable is declared at global scopeintglobal_variable;__global__voidkernel_uncompilable(){// this causes a compilation error: global (__host__) variables must not// be accessed from __device__ / __global__ codeprintf("%d\n",global_variable);}// On systems with pageableMemoryAccess set to 1, we can access the address// of a global variable. The below kernel takes that address as an argument__global__voidkernel(int*global_variable_addr){printf("%d\n",*global_variable_addr);}intmain(){kernel<<<1,1>>>(&global_variable);...return0;}
性能调优的一个重要方面是,与 CPU 相比,GPU 上 TLB 未命中的开销通常要大得多。这意味着,如果 GPU 线程频繁访问使用足够小的页大小映射的统一内存中的随机位置,那么与对使用足够大的页大小映射的统一内存进行相同访问相比,其速度可能会慢得多。虽然当 CPU 线程随机访问使用小页大小映射的大块内存区域时,也可能出现类似的影响,但速度下降没有那么明显,因此应用程序可能希望在这种速度下降与减少内存碎片之间进行权衡。
为了获得最佳性能,应限制两个 GPU 之间的数据共享,或通过显式复制进行共享。或者,应采取调用cudaMemAdviseSetPreferredLocation等措施,以确保频繁共享的数据在物理上仍驻留于 CPU 内存或相干 GPU 内存中,因为默认情况下,访问软件相干内存需要发生缺页异常并迁移数据。
在混合相干性系统上,对于软件相干 GPU,cudaHostRegister及其他主机内存访问 API 的行为也会发生变化。混合相干性系统上的软件相干 GPU 不使用页锁定映射,而是使用 CPU 页表的软件镜像。这意味着某些 GPU 访问可能发生缺页异常,而在非混合相干性系统上则不会,尽管此类缺页异常很少见,并且应仅在内存压力下发生。
4.1.1.2.2. 从主机直接访问统一内存
某些设备在硬件上支持主机对驻留于 GPU 的统一内存进行相干的读取、存储和原子访问。这些设备的属性cudaDevAttrDirectManagedMemAccessFromHost设置为 1。请注意,所有硬件相干系统都会为通过 NVLink 连接的设备设置此属性。在这些系统上,主机可以直接访问驻留于 GPU 的内存,而不会发生缺页异常和数据迁移。请注意,对于 CUDA 托管内存,必须使用位置类型为cudaMemLocationTypeHost的cudaMemAdviseSetAccessedBy提示,才能启用这种不发生缺页异常的直接访问,请参见下面的示例。
__global__voidwrite(int*ret,inta,intb){ret[threadIdx.x]=a+b+threadIdx.x;}__global__voidappend(int*ret,inta,intb){ret[threadIdx.x]+=a+b+threadIdx.x;}voidtest_malloc(){int*ret=(int*)malloc(1000*sizeof(int));// for shared page table systems, the following hint is not necesarycudaMemLocationlocation={.type=cudaMemLocationTypeHost};cudaMemAdvise(ret,1000*sizeof(int),cudaMemAdviseSetAccessedBy,location);write<<<1,1000>>>(ret,10,100);// pages populated in GPU memorycudaDeviceSynchronize();for(inti=0;i<1000;i++)printf("%d: A+B = %d\n",i,ret[i]);// directManagedMemAccessFromHost=1: CPU accesses GPU memory directly without migrations// directManagedMemAccessFromHost=0: CPU faults and triggers device-to-host migrationsappend<<<1,1000>>>(ret,10,100);// directManagedMemAccessFromHost=1: GPU accesses GPU memory without migrationscudaDeviceSynchronize();// directManagedMemAccessFromHost=0: GPU faults and triggers host-to-device migrationsfree(ret);}
__global__voidwrite(int*ret,inta,intb){ret[threadIdx.x]=a+b+threadIdx.x;}__global__voidappend(int*ret,inta,intb){ret[threadIdx.x]+=a+b+threadIdx.x;}voidtest_managed(){int*ret;cudaMallocManaged(&ret,1000*sizeof(int));cudaMemLocationlocation={.type=cudaMemLocationTypeHost};cudaMemAdvise(ret,1000*sizeof(int),cudaMemAdviseSetAccessedBy,location);// set direct access hintwrite<<<1,1000>>>(ret,10,100);// pages populated in GPU memorycudaDeviceSynchronize();for(inti=0;i<1000;i++)printf("%d: A+B = %d\n",i,ret[i]);// directManagedMemAccessFromHost=1: CPU accesses GPU memory directly without migrations// directManagedMemAccessFromHost=0: CPU faults and triggers device-to-host migrationsappend<<<1,1000>>>(ret,10,100);// directManagedMemAccessFromHost=1: GPU accesses GPU memory without migrationscudaDeviceSynchronize();// directManagedMemAccessFromHost=0: GPU faults and triggers host-to-device migrationscudaFree(ret);
某些设备(包括硬件相干系统中通过 NVLink 连接的设备)支持对驻留于 CPU 的内存进行硬件加速的原子访问。这意味着,对主机内存的原子访问不必通过缺页异常来模拟。对于这些设备,属性cudaDevAttrHostNativeAtomicSupported设置为 1。
4.1.1.2.4. 原子访问和同步原语
CUDA 统一内存支持主机线程和设备线程可用的所有原子操作,使所有线程都能通过并发访问同一共享内存位置来协作。libcu++库提供了许多针对主机线程与设备线程之间的并发使用而调优的异构同步原语,其中包括cuda::atomic、cuda::atomic_ref、cuda::barrier、cuda::semaphore等许多原语。
#include<cuda/atomic>#include<cstdio>#include<fcntl.h>#include<sys/mman.h>#define ERR(msg, ...) { fprintf(stderr, msg, ##__VA_ARGS__); return EXIT_FAILURE; }__global__voidkernel(int*ptr){cuda::atomic_ref{*ptr}.store(2);}intmain(){// this will be closed/deleted by default on exitFILE*tmp_file=tmpfile64();// need to allocate space in the file, we do this with posix_fallocate hereintstatus=posix_fallocate(fileno(tmp_file),0,4096);if(status!=0)ERR("Failed to allocate space in temp file\n");int*ptr=(int*)mmap(NULL,4096,PROT_READ|PROT_WRITE,MAP_PRIVATE,fileno(tmp_file),0);if(ptr==MAP_FAILED)ERR("Failed to map temp file\n");// initialize the value in our file-backed memory*ptr=1;printf("Atom value: %d\n",*ptr);// device and host thread access ptr concurrently, using cuda::atomic_refkernel<<<1,1>>>(ptr);while(cuda::atomic_ref{*ptr}.load()!=2);// this will always be 2printf("Atom value: %d\n",*ptr);returnEXIT_SUCCESS;}
在软件相干系统上,对统一内存的原子访问可能引发缺页异常,从而导致显著的延迟。请注意,在这些系统上,并非所有对 CPU 内存的 GPU 原子操作都会出现这种情况:nvidia-smi-q|grep"AtomicCapsOutbound"列出的操作可能避免缺页异常。
在设备内存作为 NUMA 域向系统公开的硬件相干系统上,可以使用numa_alloc_on_node等特殊分配器将内存固定到给定的 NUMA 节点,该节点可以是主机或设备。主机和设备都可以访问此内存,并且此内存不会迁移。同样,mbind可用于将内存固定到给定的一个或多个 NUMA 节点,并且可以使文件后备内存在首次被访问之前就放置到给定的一个或多个 NUMA 节点上。
在硬件相干系统上,访问计数器功能会跟踪 GPU 对位于其他处理器上的内存的访问频率。这是确保将内存页移动到最频繁访问这些页的处理器的物理内存中所必需的。它可以指导 CPU 与 GPU 之间以及对等 GPU 之间的迁移,这一过程称为访问计数器迁移。
从 CUDA 12.4 开始,系统分配的内存支持访问计数器。请注意,文件后备内存不会根据访问情况迁移。对于系统分配的内存,可以通过使用cudaMemAdviseSetAccessedBy提示,以相应的设备 id 指定设备,来启用访问计数器迁移。如果访问计数器已启用,可以使用设置为主机的cudaMemAdviseSetPreferredLocation来防止迁移。默认情况下,cudaMallocManaged基于缺页异常后迁移的机制进行迁移。[7]
驱动程序也可能使用访问计数器,以便在抖动缓解或内存超额订用场景中提高效率。
4.1.1.2.9. 避免从 CPU 频繁写入驻留于 GPU 的内存
如果主机访问统一内存,缓存未命中可能会在主机与设备之间产生比预期更多的流量。许多 CPU 架构要求所有内存操作(包括写入)都经过缓存层次结构。如果系统内存驻留于 GPU,这意味着 CPU 对该内存的频繁写入可能导致缓存未命中,从而在将实际值写入所请求的内存范围之前,先将数据从 GPU 传输到 CPU。在软件相干系统上,这可能引入额外的缺页异常,而在硬件相干系统上,这可能导致 CPU 操作之间的延迟更高。因此,为了与设备共享主机生成的数据,可以考虑写入驻留于 CPU 的内存,并由设备直接读取这些值。下面的代码展示了如何使用统一内存实现这一点。
size_tdata_size=sizeof(int);int*data=(int*)malloc(data_size);// ensure that data stays local to the host and avoid faultscudaMemLocationlocation={.type=cudaMemLocationTypeHost};cudaMemAdvise(data,data_size,cudaMemAdviseSetPreferredLocation,location);cudaMemAdvise(data,data_size,cudaMemAdviseSetAccessedBy,location);// frequent exchanges of small data: if the CPU writes to CPU-resident memory,// and GPU directly accesses that data, we can avoid the CPU caches re-loading// data if it was evicted in between writesfor(inti=0;i<10;++i){*data=42+i;kernel<<<1,1>>>(data);cudaDeviceSynchronize();// CPU cache potentially evicted data here}free(data);
int*data;size_tdata_size=sizeof(int);cudaMallocManaged(&data,data_size);// ensure that data stays local to the host and avoid faultscudaMemLocationlocation={.type=cudaMemLocationTypeHost};cudaMemAdvise(data,data_size,cudaMemAdviseSetPreferredLocation,location);cudaMemAdvise(data,data_size,cudaMemAdviseSetAccessedBy,location);// frequent exchanges of small data: if the CPU writes to CPU-resident memory,// and GPU directly accesses that data, we can avoid the CPU caches re-loading// data if it was evicted in between writesfor(inti=0;i<10;++i){*data=42+i;kernel<<<1,1>>>(data);cudaDeviceSynchronize();// CPU cache potentially evicted data here}cudaFree(data);
voidexchange_explicit_copy(cudaStream_tstream){int*data,*host_data;size_tn_bytes=sizeof(int)*16;// allocate receiving bufferhost_data=(int*)malloc(n_bytes);// allocate, since we touch on the device first, will be GPU-residentcudaMallocManaged(&data,n_bytes);kernel<<<1,16,0,stream>>>(data);// launch independent work on the device// other_kernel<<<1024, 256, 0, stream>>>(other_data, ...);// transfer to hostcudaMemcpyAsync(host_data,data,n_bytes,cudaMemcpyDeviceToHost,stream);// sync stream to ensure data has been transferredcudaStreamSynchronize(stream);// read transferred dataprintf("Got values %d - %d from GPU\n",host_data[0],host_data[15]);cudaFree(data);free(host_data);}
voidexchange_device_direct_write(cudaStream_tstream){int*data;size_tn_bytes=sizeof(int)*16;// allocate receiving buffercudaMallocManaged(&data,n_bytes);// ensure that data is mapped and resident on the hostcudaMemLocationlocation={.type=cudaMemLocationTypeHost};cudaMemAdvise(data,n_bytes,cudaMemAdviseSetPreferredLocation,location);cudaMemAdvise(data,n_bytes,cudaMemAdviseSetAccessedBy,location);kernel<<<1,16,0,stream>>>(data);// sync stream to ensure data has been transferredcudaStreamSynchronize(stream);// read transferred dataprintf("Got values %d - %d from GPU\n",data[0],data[15]);cudaFree(data);}
voidexchange_host_direct_read(cudaStream_tstream){int*data;size_tn_bytes=sizeof(int)*16;// allocate receiving buffercudaMallocManaged(&data,n_bytes);// ensure that data is mapped and resident on the devicecudaMemLocationdevice_loc={};cudaGetDevice(&device_loc.id);device_loc.type=cudaMemLocationTypeDevice;cudaMemAdvise(data,n_bytes,cudaMemAdviseSetPreferredLocation,device_loc);cudaMemAdvise(data,n_bytes,cudaMemAdviseSetAccessedBy,device_loc);kernel<<<1,16,0,stream>>>(data);// launch independent work on the GPU// other_kernel<<<1024, 256, 0, stream>>>(other_data, ...);// sync stream to ensure data may be accessed (has been written by device)cudaStreamSynchronize(stream);// read data directly from hostprintf("Got values %d - %d from GPU\n",data[0],data[15]);cudaFree(data);
最后,在上面的显式复制示例中,可以使用主机或设备核函数来显式执行此传输,而不是使用cudaMemcpy*来传输数据。对于连续数据,优先使用 CUDA 复制引擎,因为复制引擎执行的操作可以与主机和设备上的工作重叠。cudaMemcpy*和cudaMemPrefetchAsyncAPI 可能会使用复制引擎,但不能保证cudaMemcpy*API 调用会使用复制引擎。出于同样的原因,对于足够大的数据,显式复制优于主机直接读取:如果主机和设备所执行的工作都没有使其各自的内存系统达到饱和,复制引擎就可以在主机和设备执行工作的同时并发执行传输。
在 Windows 上,如果对等映射不可用(例如,在架构不同的 GPU 之间),那么系统将自动回退到使用映射内存,而不论程序是否实际使用这两个 GPU。如果实际只会使用一个 GPU,就必须在启动程序之前设置CUDA_VISIBLE_DEVICES环境变量。这会限制可见的 GPU,并允许在 GPU 内存中分配托管内存。
或者,在 Windows 上,用户也可以将CUDA_MANAGED_FORCE_DEVICE_ALLOC设为非零值,以强制驱动程序始终使用设备内存进行物理存储。当此环境变量设为非零值时,该进程中使用的所有支持托管内存的设备都必须彼此具备对等兼容性。如果使用了一个支持托管内存的设备,而它与该进程先前使用过的、支持托管内存的其他设备中的任意一个不具备对等兼容性,则会返回错误::cudaErrorInvalidDevice,即使已经在那些设备上调用过::cudaDeviceReset也是如此。CUDA 环境变量中介绍了这些环境变量。
4.1.3.2. 相干性和并发性
为了确保相干性,统一内存编程模型对 CPU 和 GPU 并发执行时的数据访问施加了约束。实际上,在执行任何核函数操作期间,GPU 都独占访问所有托管数据,CPU 不允许访问这些数据,无论具体的核函数是否正在使用这些数据。CPU/GPU 的并发访问,即使访问的是不同的托管内存分配,也会导致段错误,因为该页被视为 CPU 不可访问。
例如,以下代码在计算能力为 6.x 的设备上可以成功运行,因为 GPU 的缺页故障功能消除了对同时访问的所有限制,但在 6.x 之前的架构和 Windows 平台上会失败,因为当 CPU 访问y时,GPU 程序核函数仍处于活动状态:
__device____managed__intx,y=2;__global__voidkernel(){x=10;}intmain(){kernel<<<1,1>>>();y=20;// Error on GPUs not supporting concurrent accesscudaDeviceSynchronize();return0;}
程序在访问y之前必须显式地与 GPU 同步(无论 GPU 核函数是否实际访问y(或任何托管数据):
__device____managed__intx,y=2;__global__voidkernel(){x=10;}intmain(){kernel<<<1,1>>>();cudaDeviceSynchronize();y=20;// Success on GPUs not supporting concurrent accessreturn0;}
intmain(){cudaStream_tstream1,stream2;cudaStreamCreate(&stream1);cudaStreamCreate(&stream2);int*non_managed,*managed,*also_managed;cudaMallocHost(&non_managed,4);// Non-managed, CPU-accessible memorycudaMallocManaged(&managed,4);cudaMallocManaged(&also_managed,4);// Point 1: CPU can access non-managed data.kernel<<<1,1,0,stream1>>>(managed);*non_managed=1;// Point 2: CPU cannot access any managed data while GPU is busy,// unless concurrentManagedAccess = 1// Note we have not yet synchronized, so "kernel" is still active.*also_managed=2;// Will issue segmentation fault// Point 3: Concurrent GPU kernels can access the same data.kernel<<<1,1,0,stream2>>>(managed);// Point 4: Multi-GPU concurrent access is also permitted.cudaSetDevice(1);kernel<<<1,1>>>(managed);return0;}
4.1.3.3.2. 与流关联的托管内存允许更细粒度的控制
统一内存建立在流独立性模型之上,允许 CUDA 程序显式地将托管分配与 CUDA 流关联。这样,程序员便可根据核函数是否启动到指定流中来指示核函数对数据的使用情况。这使得可以根据程序特定的数据访问模式来实现并发。用于控制此行为的函数是:
以下示例展示了如何显式地将y与主机可访问性关联,从而使 CPU 在任何时候都能够访问。(请注意,核函数调用之后没有cudaDeviceSynchronize()。)现在,在 GPU 上运行的核函数对y的访问将产生未定义的结果。
__device____managed__intx,y=2;__global__voidkernel(){x=10;}intmain(){cudaStream_tstream1;cudaStreamCreate(&stream1);cudaStreamAttachMemAsync(stream1,&y,0,cudaMemAttachHost);cudaDeviceSynchronize();// Wait for Host attachment to occur.kernel<<<1,1,0,stream1>>>();// Note: Launches into stream1.y=20;// Success – a kernel is running but “y”// has been associated with no stream.return0;}
4.1.3.3.3. 关于多线程主机程序的一个更详细的示例
cudaStreamAttachMemAsync()的主要用途是利用 CPU 线程实现独立任务的并行执行。在这样的程序中,CPU 线程通常会为其生成的所有工作创建自己的流,因为使用 CUDA 的 NULL 流会导致线程之间产生依赖关系。托管数据默认对任何 GPU 流都具有全局可见性,这可能使得多线程程序难以避免 CPU 线程之间的相互影响。因此,使用函数cudaStreamAttachMemAsync()将线程的托管分配与该线程自己的流关联,而且这种关联通常在线程的整个生命周期内都不会改变。这样的程序只需增加一次对cudaStreamAttachMemAsync()的调用,就可以使用统一内存进行数据访问:
// This function performs some task, in its own , in its own private stream and can be run in parallelvoidrun_task(int*in,int*out,intlength){// Create a stream for us to use.cudaStream_tstream;cudaStreamCreate(&stream);// Allocate some managed data and associate with our stream.// Note the use of the host-attach flag to cudaMallocManaged();// we then associate the allocation with our stream so that// our GPU kernel launches can access it.int*data;cudaMallocManaged((void**)&data,length,cudaMemAttachHost);cudaStreamAttachMemAsync(stream,data);cudaStreamSynchronize(stream);// Iterate on the data in some way, using both Host & Device.for(inti=0;i<N;i++){transform<<<100,256,0,stream>>>(in,data,length);cudaStreamSynchronize(stream);host_process(data,length);// CPU uses managed data.convert<<<100,256,0,stream>>>(out,data,length);}cudaStreamSynchronize(stream);cudaStreamDestroy(stream);cudaFree(data);}
通过cudaMemcpy*或cudaMemset*从设备访问数据时,该操作所在的流被视为在 GPU 上处于活动状态。在此期间,如果 GPU 的设备属性concurrentManagedAccess的值为零,则 CPU 对与该流关联的数据或具有全局可见性的数据的任何访问都会导致段错误。程序必须进行适当的同步,以确保在从 CPU 访问任何关联数据之前,该操作已完成。
能够在给定流中从主机以相干方式访问,意味着该内存既不具有全局可见性,也不与给定流关联。
能够在给定流中从设备以相干方式访问,意味着该内存具有全局可见性或与给定流关联。
4.1.4. 性能提示
性能提示允许程序员向 CUDA 提供有关统一内存使用情况的更多信息。CUDA 使用性能提示来更高效地管理内存并提高应用程序性能。性能提示绝不会影响应用程序的正确性。性能提示只影响性能。
注意
只有在统一内存性能提示能够提高性能时,应用程序才应使用它们。
性能提示可用于任何统一内存分配,包括 CUDA 托管内存。在完全支持 CUDA 统一内存的系统上,性能提示可应用于所有由系统分配的内存。
在给定的stream中执行预取任务时,如果location.type为cudaMemLocationTypeDevice,则包含[devPtr,devPtr+count)的内存区域可能会被迁移到目标设备location.id;如果location.type为cudaMemLocationTypeHost,则可能会被迁移到 CPU。有关flags的详细信息,请参阅当前的CUDA 运行时 API 文档。
请考虑下面这个简单的代码示例:
voidtest_prefetch_sam(constcudaStream_t&s){// initialize data on CPUchar*data=(char*)malloc(dataSizeBytes);init_data(data,dataSizeBytes);cudaMemLocationlocation={.type=cudaMemLocationTypeDevice,.id=myGpuId};// encourage data to move to GPU before useconstunsignedintflags=0;cudaMemPrefetchAsync(data,dataSizeBytes,location,flags,s);// use data on GPUconstunsignednum_blocks=(dataSizeBytes+threadsPerBlock-1)/threadsPerBlock;mykernel<<<num_blocks,threadsPerBlock,0,s>>>(data,dataSizeBytes);// encourage data to move back to CPUlocation={.type=cudaMemLocationTypeHost};cudaMemPrefetchAsync(data,dataSizeBytes,location,flags,s);cudaStreamSynchronize(s);// use data on CPUuse_data(data,dataSizeBytes);free(data);}
voidtest_prefetch_managed(constcudaStream_t&s){// initialize data on CPUchar*data;cudaMallocManaged(&data,dataSizeBytes);init_data(data,dataSizeBytes);cudaMemLocationlocation={.type=cudaMemLocationTypeDevice,.id=myGpuId};// encourage data to move to GPU before useconstunsignedintflags=0;cudaMemPrefetchAsync(data,dataSizeBytes,location,flags,s);// use data on GPUconstuinsignednum_blocks=(dataSizeBytes+threadsPerBlock-1)/threadsPerBlock;mykernel<<<num_blocks,threadsPerBlock,0,s>>>(data,dataSizeBytes);// encourage data to move back to CPUlocation={.type=cudaMemLocationTypeHost};cudaMemPrefetchAsync(data,dataSizeBytes,location,flags,s);cudaStreamSynchronize(s);// use data on CPUuse_data(data,dataSizeBytes);cudaFree(data);}
init_data(data,dataSizeBytes);cudaMemLocationlocation={.type=cudaMemLocationTypeDevice,.id=myGpuId};// encourage data to move to GPU before useconstunsignedintflags=0;cudaMemPrefetchAsync(data,dataSizeBytes,location,flags,s);// use data on GPUconstuinsignednum_blocks=(dataSizeBytes+threadsPerBlock-1)/threadsPerBlock;mykernel<<<num_blocks,threadsPerBlock,0,s>>>(data,dataSizeBytes);// encourage data to move back to CPUlocation={.type=cudaMemLocationTypeHost};cudaMemPrefetchAsync(data,dataSizeBytes,location,flags,s);cudaStreamSynchronize(s);// use data on CPUuse_data(data,dataSizeBytes);cudaFree(data);}// test-prefetch-managed-endstaticconstintmaxDevices=1;staticconstintmaxOuterLoopIter=3;staticconstintmaxInnerLoopIter=4;// test-advise-managed-beginvoidtest_advise_managed(cudaStream_tstream){char*dataPtr;size_tdataSize=64*threadsPerBlock;// 16 KiB
其中,advice可取以下值:
cudaMemAdviseSetReadMostly:
这意味着该数据主要用于读取,仅偶尔进行写入。通常,它允许在该区域上以读取带宽为代价换取写入带宽。
cudaMemAdviseSetPreferredLocation:
此提示将数据的首选位置设置为指定设备的物理内存。此提示鼓励系统将数据保留在首选位置,但并不保证这一点。为 location.type 传入cudaMemLocationTypeHost值会将首选位置设置为 CPU 内存。其他提示(如cudaMemPrefetchAsync)可能会覆盖此提示,并允许内存迁移到其首选位置之外。
voidtest_advise_sam(cudaStream_tstream){char*dataPtr;size_tdataSize=64*threadsPerBlock;// 16 KiB// Allocate memory using malloc or cudaMallocManageddataPtr=(char*)malloc(dataSize);// Set the advice on the memory regioncudaMemLocationloc={.type=cudaMemLocationTypeDevice,.id=myGpuId};cudaMemAdvise(dataPtr,dataSize,cudaMemAdviseSetReadMostly,loc);intouterLoopIter=0;while(outerLoopIter<maxOuterLoopIter){// The data is written by the CPU each outer loop iterationinit_data(dataPtr,dataSize);// The data is made available to all GPUs by prefetching.// Prefetching here causes read duplication of data instead// of data migrationcudaMemLocationlocation;location.type=cudaMemLocationTypeDevice;for(intdevice=0;device<maxDevices;device++){location.id=device;constunsignedintflags=0;cudaMemPrefetchAsync(dataPtr,dataSize,location,flags,stream);}// The kernel only reads this data in the inner loopintinnerLoopIter=0;while(innerLoopIter<maxInnerLoopIter){mykernel<<<32,threadsPerBlock,0,stream>>>((constchar*)dataPtr,dataSize);innerLoopIter++;}outerLoopIter++;}free(dataPtr);}
voidtest_advise_managed(cudaStream_tstream){char*dataPtr;size_tdataSize=64*threadsPerBlock;// 16 KiB// Allocate memory using cudaMallocManaged// (malloc may be used on systems with full CUDA Unified memory support)cudaMallocManaged(&dataPtr,dataSize);// Set the advice on the memory regioncudaMemLocationloc={.type=cudaMemLocationTypeDevice,.id=myGpuId};cudaMemAdvise(dataPtr,dataSize,cudaMemAdviseSetReadMostly,loc);intouterLoopIter=0;while(outerLoopIter<maxOuterLoopIter){// The data is written by the CPU each outer loop iterationinit_data(dataPtr,dataSize);// The data is made available to all GPUs by prefetching.// Prefetching here causes read duplication of data instead// of data migrationcudaMemLocationlocation;location.type=cudaMemLocationTypeDevice;for(intdevice=0;device<maxDevices;device++){location.id=device;constunsignedintflags=0;cudaMemPrefetchAsync(dataPtr,dataSize,location,flags,stream);}// The kernel only reads this data in the inner loopintinnerLoopIter=0;while(innerLoopIter<maxInnerLoopIter){mykernel<<<32,threadsPerBlock,0,stream>>>((constchar*)dataPtr,dataSize);innerLoopIter++;}outerLoopIter++;}cudaFree(dataPtr);}
4.1.4.3. 内存丢弃
cudaMemDiscardBatchAsyncAPI 允许应用程序通知 CUDA 运行时,指定内存范围中的内容已不再有用。统一内存驱动程序会因基于缺页的迁移或为支持设备内存超额使用而进行的内存逐出,执行自动内存传输。这些自动内存传输有时可能是多余的,这会严重降低性能。将一个地址范围标记为“丢弃”,会告知统一内存驱动程序,应用程序已使用完该范围中的内容,在预取时或为了给其他分配腾出空间而逐出页时,无需迁移这些数据。如果丢弃后没有进行写入访问或预取,读取被丢弃的页将得到不确定的值。而丢弃操作之后的任何新写入都保证能够被后续读取访问看到。对正在被丢弃的地址范围进行并发访问或预取将导致未定义行为。
cudaMemRangeAttributePreferredLocation:如果整个内存范围都以相应的处理器作为首选位置,则返回的结果为 GPU 设备 ID 或cudaCpuDeviceId,否则返回cudaInvalidDeviceId。应用程序可以使用此查询 API,根据托管指针的首选位置属性,决定通过 CPU 还是 GPU 来暂存数据。请注意,查询时该内存范围的实际位置可能与首选位置不同。
cudaMemRangeAttributePreferredLocationId:如果对同一地址范围的cudaMemRangeAttributePreferredLocationType查询返回cudaMemLocationTypeDevice,则返回设备序号。如果首选位置类型为主机 NUMA 节点,则返回主机 NUMA 节点 ID。否则,应忽略该 ID。
cudaMemRangeAttributeLastPrefetchLocationId:如果对同一地址范围的cudaMemRangeAttributeLastPrefetchLocationType查询返回cudaMemLocationTypeDevice,它将是有效的设备序号;如果查询返回cudaMemLocationTypeHostNuma,它将是有效的主机 NUMA 节点 ID。否则,应忽略该 ID。
CUDA 图提供了 CUDA 中用于提交工作的另一种模型。图是一系列通过依赖关系连接的操作,例如核函数启动、数据移动等。图的定义与其执行彼此分离。这使得图可以只定义一次,然后重复启动。将图的定义与其执行分离,可以实现多项优化:首先,与流相比,CPU 启动开销降低,因为大部分设置工作都是提前完成的;其次,将整个工作流呈现给 CUDA,可实现流的逐项工作提交机制可能无法实现的优化。
要了解图所能实现的优化,请考虑流中发生的情况:当你将一个核函数放入流中时,主机驱动程序会执行一系列操作,为该核函数在 GPU 上执行做好准备。这些操作是设置和启动核函数所必需的,是每个发出的核函数都必须承担的额外开销。对于执行时间较短的 GPU 核函数,这种额外开销可能占总体端到端执行时间的很大一部分。通过创建一个包含将被多次启动的工作流的 CUDA 图,可以在实例化期间为整个图一次性承担这些额外开销,随后就能以很小的额外开销重复启动图本身。
在各种图 API 中,可以通过与关联节点一一对应的数组来选择性地指定边数据。如果将其作为输入参数省略,则使用零初始化的数据。如果将其作为输出(查询)参数省略,那么当被忽略的边数据全部为零初始化时,API 会接受这种做法;如果该调用会丢失信息,则返回cudaErrorLossyQuery。
某些流捕获 API 也支持边数据:cudaStreamBeginCaptureToGraph()、cudaStreamGetCaptureInfo()和cudaStreamUpdateCaptureDependencies()。在这些情况下,下游节点尚不存在。数据与一条悬空边(半边)关联,该边将连接到今后捕获的节点,或者在流捕获终止时被丢弃。请注意,某些边类型不会等待上游节点完全完成。在判断流捕获是否已完全重新汇入原始流时,这些边会被忽略,并且不能在捕获结束时被丢弃。请参阅流捕获。
以下示例展示了如何创建下图(省略了声明及其他样板代码)。请注意,示例使用cudaGraphCreate()创建图,使用cudaGraphAddNode()添加核函数节点及其依赖项。CUDA Runtime API 文档列出了可用于添加节点和依赖项的所有函数。
图 25 使用图 API 创建图的示例
// Create the graph - it starts out emptycudaGraphCreate(&graph,0);// Create the nodes and their dependenciescudaGraphNode_tnodes[4];cudaGraphNodeParamskParams={cudaGraphNodeTypeKernel};kParams.kernel.func=(void*)kernelName;kParams.kernel.gridDim.x=kParams.kernel.gridDim.y=kParams.kernel.gridDim.z=1;kParams.kernel.blockDim.x=kParams.kernel.blockDim.y=kParams.kernel.blockDim.z=1;cudaGraphAddNode(&nodes[0],graph,NULL,NULL,0,&kParams);cudaGraphAddNode(&nodes[1],graph,&nodes[0],NULL,1,&kParams);cudaGraphAddNode(&nodes[2],graph,&nodes[0],NULL,1,&kParams);cudaGraphAddNode(&nodes[3],graph,&nodes[1],NULL,2,&kParams);
上面的示例展示了四个核函数节点及它们之间的依赖关系,以说明如何创建一个非常简单的图。典型的应用程序还会包含为内存操作(如 memcpy 和 memset)添加的节点。有关用于添加节点的所有图 API 函数的完整参考信息,请参阅CUDA Runtime API 文档。
注意
CUDA 图 API 最初使用单独的 API 函数来添加每种不同类型的节点。例如,cudaGraphAddKernelNode()或cudaGraphAddMemcpyNode()。这些 API 已被单一的多态 APIcudaGraphAddNode()取代,后者使用节点参数的.type字段来确定所添加节点的类型。非多态 API 将在未来弃用。使用 CUDA 图 API 向图中添加节点时,推荐使用cudaGraphAddNode()。
4.2.2.1.2. 流捕获
流捕获提供了一种利用现有的基于流的 API 创建图的机制。对于一段将工作启动到流中的代码(包括现有代码),可以在其前后分别调用cudaStreamBeginCapture()和cudaStreamEndCapture()。如下所示。
// stream1 is the origin streamcudaStreamBeginCapture(stream1);kernel_A<<<...,stream1>>>(...);// Fork into stream2cudaEventRecord(event1,stream1);cudaStreamWaitEvent(stream2,event1);kernel_B<<<...,stream1>>>(...);kernel_C<<<...,stream2>>>(...);// Join stream2 back to origin stream (stream1)cudaEventRecord(event2,stream2);cudaStreamWaitEvent(stream1,event2);kernel_D<<<...,stream1>>>(...);// End capture in the origin streamcudaStreamEndCapture(stream1,&graph);// stream1 and stream2 no longer in capture mode
图 25中的示例是一个简化示例,旨在从概念上展示一个小型图。在使用 CUDA 图的应用程序中,无论使用图 API 还是流捕获,情况都会更加复杂。以下代码片段并列比较了使用图 API 和流捕获来创建 CUDA 图,以执行一个简单的两阶段归约算法。
图 26展示了这个 CUDA 图。它是通过对以下代码应用cudaGraphDebugDotPrint函数生成的,经过少量调整以提高可读性后,再使用Graphviz渲染而成。
图 26 使用两阶段归约核函数的 CUDA 图示例
图内文字中文对照
CUDA graph
CUDA 图
MEMSET
内存设置
MEMCPY
内存复制
HOST
主机
voidcudaGraphsManual(float*inputVec_h,float*inputVec_d,double*outputVec_d,double*result_d,size_tinputSize,size_tnumOfBlocks){cudaStream_tstreamForGraph;cudaGraph_tgraph;std::vector<cudaGraphNode_t>nodeDependencies;cudaGraphNode_tmemcpyNode,kernelNode;doubleresult_h=0.0;cudaStreamCreate(&streamForGraph);// cudaGraphAddNode is the unified node-creation API: one call for every node type,// driven by a cudaGraphNodeParams struct (a .type tag + a union of per-type params).// It replaces the previously used cudaGraphAddMemcpyNode/cudaGraphAddKernelNode calls. The struct// has reserved fields that must be zero, so it is re-zeroed with "= {}" before each node below.cudaGraphNodeParamsnodeParams={};cudaMemcpy3DParmsmemcpyParams={0};memcpyParams.srcArray=NULL;memcpyParams.srcPos=make_cudaPos(0,0,0);memcpyParams.srcPtr=make_cudaPitchedPtr(inputVec_h,sizeof(float)*inputSize,inputSize,1);memcpyParams.dstArray=NULL;memcpyParams.dstPos=make_cudaPos(0,0,0);memcpyParams.dstPtr=make_cudaPitchedPtr(inputVec_d,sizeof(float)*inputSize,inputSize,1);memcpyParams.extent=make_cudaExtent(sizeof(float)*inputSize,1,1);memcpyParams.kind=cudaMemcpyHostToDevice;// Create an empty graph; nodes and edges will be added below.cudaGraphCreate(&graph,0);// Node 1: H2D memcpy — no dependencies (NULL, 0), so it can start immediately.// For a memcpy node the cudaMemcpy3DParms goes into nodeParams.memcpy.copyParams// (the .memcpy union member is a wrapper struct, so the copy descriptor nests one level deeper).nodeParams={};nodeParams.type=cudaGraphNodeTypeMemcpy;nodeParams.memcpy.copyParams=memcpyParams;cudaGraphAddNode(&memcpyNode,graph,NULL,/*dependencyData=*/NULL,0,&nodeParams);// Make the next node wait for this memcpy to finish before starting.nodeDependencies.push_back(memcpyNode);void*kernelArgs[4]={(void*)&inputVec_d,(void*)&outputVec_d,&inputSize,&numOfBlocks};// Node 2: first reduction kernel — depends on the H2D memcpy completing.// Kernel params are set directly on the .kernel union member.nodeParams={};nodeParams.type=cudaGraphNodeTypeKernel;nodeParams.kernel.func=(void*)reduce;nodeParams.kernel.gridDim=dim3(numOfBlocks,1,1);nodeParams.kernel.blockDim=dim3(THREADS_PER_BLOCK,1,1);nodeParams.kernel.sharedMemBytes=0;nodeParams.kernel.kernelParams=(void**)kernelArgs;nodeParams.kernel.extra=NULL;cudaGraphAddNode(&kernelNode,graph,nodeDependencies.data(),/*dependencyData=*/NULL,nodeDependencies.size(),&nodeParams);// Move dependency forward: the next node waits for this kernel.nodeDependencies.clear();nodeDependencies.push_back(kernelNode);void*kernelArgs2[3]={(void*)&outputVec_d,(void*)&result_d,&numOfBlocks};// Node 3: final reduction kernel — depends on Node 2.nodeParams={};nodeParams.type=cudaGraphNodeTypeKernel;nodeParams.kernel.func=(void*)reduceFinal;nodeParams.kernel.gridDim=dim3(1,1,1);nodeParams.kernel.blockDim=dim3(THREADS_PER_BLOCK,1,1);nodeParams.kernel.sharedMemBytes=0;nodeParams.kernel.kernelParams=kernelArgs2;nodeParams.kernel.extra=NULL;cudaGraphAddNode(&kernelNode,graph,nodeDependencies.data(),/*dependencyData=*/NULL,nodeDependencies.size(),&nodeParams);nodeDependencies.clear();nodeDependencies.push_back(kernelNode);memset(&memcpyParams,0,sizeof(memcpyParams));memcpyParams.srcArray=NULL;memcpyParams.srcPos=make_cudaPos(0,0,0);memcpyParams.srcPtr=make_cudaPitchedPtr(result_d,sizeof(double),1,1);memcpyParams.dstArray=NULL;memcpyParams.dstPos=make_cudaPos(0,0,0);memcpyParams.dstPtr=make_cudaPitchedPtr(&result_h,sizeof(double),1,1);memcpyParams.extent=make_cudaExtent(sizeof(double),1,1);memcpyParams.kind=cudaMemcpyDeviceToHost;// Node 4: D2H memcpy — copies the scalar result back to the host.// Again the copy descriptor nests in nodeParams.memcpy.copyParams.nodeParams={};nodeParams.type=cudaGraphNodeTypeMemcpy;nodeParams.memcpy.copyParams=memcpyParams;cudaGraphAddNode(&memcpyNode,graph,nodeDependencies.data(),/*dependencyData=*/NULL,nodeDependencies.size(),&nodeParams);nodeDependencies.clear();nodeDependencies.push_back(memcpyNode);cudaGraphNode_thostNode;callBackData_thostFnData;hostFnData.data=&result_h;hostFnData.fn_name="cudaGraphsManual";// Node 5: host callback — runs on the CPU after the D2H copy completes.// The .host member is cudaHostNodeParamsV2 (fn + userData, plus a syncMode field// left at 0 by the zero-init above).nodeParams={};nodeParams.type=cudaGraphNodeTypeHost;nodeParams.host.fn=myHostNodeCallback;nodeParams.host.userData=&hostFnData;cudaGraphAddNode(&hostNode,graph,nodeDependencies.data(),/*dependencyData=*/NULL,nodeDependencies.size(),&nodeParams);size_tnumNodes=0;cudaGraphGetNodes(graph,NULL,&numNodes);printf("Graph node count: %zu\n",numNodes);// Instantiate: compile the graph into an executable form (one-time cost).// This is where CUDA optimizes the schedule; repeated launches reuse this.cudaGraphExec_tgraphExec;cudaGraphInstantiate(&graphExec,graph,NULL,NULL,0);// Demonstrates cudaGraphClone — in practice, cloning is useful when multiple CPU// threads need to launch the same graph concurrently, each with its own independent graphExec.cudaGraph_tclonedGraph;cudaGraphExec_tclonedGraphExec;cudaGraphClone(&clonedGraph,graph);cudaGraphInstantiate(&clonedGraphExec,clonedGraph,NULL,NULL,0);// Refill the host input before each launch so the graph's H2D copy processes// new data every time — one instantiated graph reused for different data.// The per-iteration sync ensures that copy finishes before we overwrite the buffer.for(inti=0;i<GRAPH_LAUNCH_ITERATIONS;i++){init_input(inputVec_h,inputSize);cudaGraphLaunch(graphExec,streamForGraph);cudaStreamSynchronize(streamForGraph);}printf("\nCloned graph:\n");for(inti=0;i<GRAPH_LAUNCH_ITERATIONS;i++){init_input(inputVec_h,inputSize);cudaGraphLaunch(clonedGraphExec,streamForGraph);cudaStreamSynchronize(streamForGraph);}cudaGraphExecDestroy(graphExec);cudaGraphExecDestroy(clonedGraphExec);cudaGraphDestroy(graph);cudaGraphDestroy(clonedGraph);cudaStreamDestroy(streamForGraph);}
voidcudaGraphsUsingStreamCapture(float*inputVec_h,float*inputVec_d,double*outputVec_d,double*result_d,size_tinputSize,size_tnumOfBlocks){cudaStream_tstream1,streamForGraph;cudaGraph_tgraph;doubleresult_h=0.0;cudaStreamCreate(&stream1);cudaStreamCreate(&streamForGraph);// Begin capture: operations issued to stream1 are recorded, not executed.cudaStreamBeginCapture(stream1,cudaStreamCaptureModeGlobal);cudaMemcpyAsync(inputVec_d,inputVec_h,sizeof(float)*inputSize,cudaMemcpyDefault,stream1);reduce<<<numOfBlocks,THREADS_PER_BLOCK,0,stream1>>>(inputVec_d,outputVec_d,inputSize,numOfBlocks);reduceFinal<<<1,THREADS_PER_BLOCK,0,stream1>>>(outputVec_d,result_d,numOfBlocks);cudaMemcpyAsync(&result_h,result_d,sizeof(double),cudaMemcpyDefault,stream1);callBackData_thostFnData={0};hostFnData.data=&result_h;hostFnData.fn_name="cudaGraphsUsingStreamCapture";cudaLaunchHostFunc(stream1,myHostNodeCallback,&hostFnData);// End capture: the runtime builds a graph from everything recorded above.// The resulting graph is structurally identical to the one built manually.cudaStreamEndCapture(stream1,&graph);size_tnumNodes=0;cudaGraphGetNodes(graph,NULL,&numNodes);printf("Graph node count: %zu\n",numNodes);// Instantiate the captured graph into an executable form.cudaGraphExec_tgraphExec;cudaGraphInstantiate(&graphExec,graph,NULL,NULL,0);// Demonstrates cudaGraphClone — in practice, cloning is useful when multiple CPU// threads need to launch the same graph concurrently, each with its own independent graphExec.cudaGraph_tclonedGraph;cudaGraphExec_tclonedGraphExec;cudaGraphClone(&clonedGraph,graph);cudaGraphInstantiate(&clonedGraphExec,clonedGraph,NULL,NULL,0);// Refill the host input before each launch so the graph's H2D copy processes// new data every time — one instantiated graph reused for different data.// The per-iteration sync ensures that copy finishes before we overwrite the buffer.for(inti=0;i<GRAPH_LAUNCH_ITERATIONS;i++){init_input(inputVec_h,inputSize);cudaGraphLaunch(graphExec,streamForGraph);cudaStreamSynchronize(streamForGraph);}printf("\nCloned graph:\n");for(inti=0;i<GRAPH_LAUNCH_ITERATIONS;i++){init_input(inputVec_h,inputSize);cudaGraphLaunch(clonedGraphExec,streamForGraph);cudaStreamSynchronize(streamForGraph);}cudaGraphExecDestroy(graphExec);cudaGraphExecDestroy(clonedGraphExec);cudaGraphDestroy(graph);cudaGraphDestroy(clonedGraph);cudaStreamDestroy(stream1);cudaStreamDestroy(streamForGraph);}
4.2.2.2. 图的实例化
无论是使用图 API 还是流捕获,创建图后,都必须通过实例化该图来创建可执行图,然后才能启动它。假设已成功创建cudaGraph_tgraph,以下代码将实例化该图并创建可执行图cudaGraphExec_tgraphExec:
CUDA 提供了两种更新已实例化图参数的机制:整图更新和单个节点更新。整图更新允许用户提供一个拓扑相同的cudaGraph_t对象,其节点包含更新后的参数。单个节点更新允许用户显式更新各个节点的参数。当需要更新大量节点,或者调用方不知道图拓扑时(即该图是对库调用进行流捕获的结果),使用更新后的cudaGraph_t更为方便。当更改数量较少,并且用户持有需要更新的节点的句柄时,首选单个节点更新。单个节点更新会跳过对未更改节点的拓扑检查和比较,因此在许多情况下可以更加高效。
CUDA 还提供了一种机制,可以在不影响节点当前参数的情况下启用和禁用单个节点。
以下各节将更详细地说明每种方法。
4.2.3.1. 整图更新
cudaGraphExecUpdate()允许使用一个拓扑相同的图(“更新图”)中的参数来更新已实例化的图(“原始图”)。更新图的拓扑必须与用于实例化cudaGraphExec_t的原始图完全相同。此外,指定依赖项的顺序也必须匹配。最后,CUDA 需要以一致的顺序排列汇节点(没有依赖项的节点)。CUDA 依赖于特定 API 调用的顺序来实现一致的汇节点排序。
cudaGraphExec_tgraphExec=NULL;for(inti=0;i<10;i++){cudaGraph_tgraph;cudaGraphExecUpdateResultupdateResult;cudaGraphNode_terrorNode;// In this example we use stream capture to create the graph.// You can also use the Graph API to produce a graph.cudaStreamBeginCapture(stream,cudaStreamCaptureModeGlobal);// Call a user-defined, stream based workload, for exampledo_cuda_work(stream);cudaStreamEndCapture(stream,&graph);// If we've already instantiated the graph, try to update it directly// and avoid the instantiation overheadif(graphExec!=NULL){// If the graph fails to update, errorNode will be set to the// node causing the failure and updateResult will be set to a// reason code.cudaGraphExecUpdate(graphExec,graph,&errorNode,&updateResult);}// Instantiate during the first iteration or whenever the update// fails for any reasonif(graphExec==NULL||updateResult!=cudaGraphExecUpdateSuccess){// If a previous update failed, destroy the cudaGraphExec_t// before re-instantiating itif(graphExec!=NULL){cudaGraphExecDestroy(graphExec);}// Instantiate graphExec from graph. The error node and// error message parameters are unused here.cudaGraphInstantiate(&graphExec,graph,0);}cudaGraphDestroy(graph);cudaGraphLaunch(graphExec,stream);cudaStreamSynchronize(stream);}
典型的工作流程是使用流捕获或图 API 创建初始cudaGraph_t。然后照常对cudaGraph_t进行实例化并启动。在初次启动之后,使用与初始图相同的方法创建新的cudaGraph_t,并调用cudaGraphExecUpdate()。如果图更新成功(由上述示例中的updateResult参数指示),则启动更新后的cudaGraphExec_t。如果更新因任何原因失败,则调用cudaGraphExecDestroy()和cudaGraphInstantiate(),以销毁原始cudaGraphExec_t并实例化一个新的对象。
也可以直接更新cudaGraph_t节点(即使用cudaGraphKernelNodeSetParams()),随后再更新cudaGraphExec_t,但是使用下一节介绍的显式节点更新 API 更加高效。
如果 IF 节点执行时条件非零,则其主体图将执行一次。下图描绘了一个包含 3 个节点的图,其中中间节点 B 是条件节点:
图 27 条件 IF 节点
图内文字中文对照
IF
如果
以下代码展示了如何创建包含 IF 条件节点的图。条件的默认值使用上游核函数设置。条件主体使用图 API填充。
__global__voidsetHandle(cudaGraphConditionalHandlehandle,intvalue){...// Set the condition value to the value passed to the kernelcudaGraphSetConditional(handle,value);...}voidgraphSetup(){cudaGraph_tgraph;cudaGraphExec_tgraphExec;cudaGraphNode_tnode;void*kernelArgs[2];intvalue=1;// Create the graphcudaGraphCreate(&graph,0);// Create the conditional handle; because no default value is provided, the condition value is undefined at the start of each graph executioncudaGraphConditionalHandlehandle;cudaGraphConditionalHandleCreate(&handle,graph);// Use a kernel upstream of the conditional to set the handle valuecudaGraphNodeParamsparams={cudaGraphNodeTypeKernel};params.kernel.func=(void*)setHandle;params.kernel.gridDim.x=params.kernel.gridDim.y=params.kernel.gridDim.z=1;params.kernel.blockDim.x=params.kernel.blockDim.y=params.kernel.blockDim.z=1;params.kernel.kernelParams=kernelArgs;kernelArgs[0]=&handle;kernelArgs[1]=&value;cudaGraphAddNode(&node,graph,nullptr,nullptr,0,¶ms);// Create and add the conditional nodecudaGraphNodeParamscParams={cudaGraphNodeTypeConditional};cParams.conditional.handle=handle;cParams.conditional.type=cudaGraphCondTypeIf;cParams.conditional.size=1;// There is only an "if" body graphcudaGraphAddNode(&node,graph,&node,nullptr,1,&cParams);// Get the body graph of the conditional nodecudaGraph_tbodyGraph=cParams.conditional.phGraph_out[0];// Populate the body graph of the IF conditional node...cudaGraphAddNode(&node,bodyGraph,nullptr,nullptr,0,¶ms);// Instantiate and launch the graphcudaGraphInstantiate(&graphExec,graph,0);cudaGraphLaunch(graphExec,0);cudaDeviceSynchronize();// Clean upcudaGraphExecDestroy(graphExec);cudaGraphDestroy(graph);}
IF 节点还可以有一个可选的第二个主体图,如果节点执行时条件值为零,则该主体图执行一次。
voidgraphSetup(){cudaGraph_tgraph;cudaGraphExec_tgraphExec;cudaGraphNode_tnode;void*kernelArgs[2];intvalue=1;// Create the graphcudaGraphCreate(&graph,0);// Create the conditional handle; because no default value is provided, the condition value is undefined at the start of each graph executioncudaGraphConditionalHandlehandle;cudaGraphConditionalHandleCreate(&handle,graph);// Use a kernel upstream of the conditional to set the handle valuecudaGraphNodeParamsparams={cudaGraphNodeTypeKernel};params.kernel.func=(void*)setHandle;params.kernel.gridDim.x=params.kernel.gridDim.y=params.kernel.gridDim.z=1;params.kernel.blockDim.x=params.kernel.blockDim.y=params.kernel.blockDim.z=1;params.kernel.kernelParams=kernelArgs;kernelArgs[0]=&handle;kernelArgs[1]=&value;cudaGraphAddNode(&node,graph,nullptr,nullptr,0,¶ms);// Create and add the IF conditional nodecudaGraphNodeParamscParams={cudaGraphNodeTypeConditional};cParams.conditional.handle=handle;cParams.conditional.type=cudaGraphCondTypeIf;cParams.conditional.size=2;// There is both an "if" and an "else" body graphcudaGraphAddNode(&node,graph,&node,nullptr,1,&cParams);// Get the body graphs of the conditional nodecudaGraph_tifBodyGraph=cParams.conditional.phGraph_out[0];cudaGraph_telseBodyGraph=cParams.conditional.phGraph_out[1];// Populate the body graphs of the IF conditional node...cudaGraphAddNode(&node,ifBodyGraph,nullptr,nullptr,0,¶ms);...cudaGraphAddNode(&node,elseBodyGraph,nullptr,nullptr,0,¶ms);// Instantiate and launch the graphcudaGraphInstantiate(&graphExec,graph,0);cudaGraphLaunch(graphExec,0);cudaDeviceSynchronize();// Clean upcudaGraphExecDestroy(graphExec);cudaGraphDestroy(graph);}
4.2.4.4. 条件 WHILE 节点
只要条件非零,WHILE 节点的主体图就会执行。条件将在节点执行时以及主体图完成后求值。下图描绘了一个包含 3 个节点的图,其中中间节点 B 是条件节点:
图 28 条件 WHILE 节点
图内文字中文对照
WHILE
当条件成立时
以下代码展示了如何创建包含 WHILE 条件节点的图。创建句柄时使用cudaGraphCondAssignDefault,以避免需要上游核函数。条件主体使用图 API填充。
__global__voidloopKernel(cudaGraphConditionalHandlehandle,char*dPtr){// Decrement the value of dPtr and set the condition value to 0 once dPtr is 0if(--(*dPtr)==0){cudaGraphSetConditional(handle,0);}}voidgraphSetup(){cudaGraph_tgraph;cudaGraphExec_tgraphExec;cudaGraphNode_tnode;void*kernelArgs[2];// Allocate a byte of device memory to use as inputchar*dPtr;cudaMalloc((void**)&dPtr,1);// Create the graphcudaGraphCreate(&graph,0);// Create the conditional handle with a default value of 1cudaGraphConditionalHandlehandle;cudaGraphConditionalHandleCreate(&handle,graph,1,cudaGraphCondAssignDefault);// Create and add the WHILE conditional nodecudaGraphNodeParamscParams={cudaGraphNodeTypeConditional};cParams.conditional.handle=handle;cParams.conditional.type=cudaGraphCondTypeWhile;cParams.conditional.size=1;cudaGraphAddNode(&node,graph,nullptr,nullptr,0,&cParams);// Get the body graph of the conditional nodecudaGraph_tbodyGraph=cParams.conditional.phGraph_out[0];// Populate the body graph of the conditional nodecudaGraphNodeParamsparams={cudaGraphNodeTypeKernel};params.kernel.func=(void*)loopKernel;params.kernel.gridDim.x=params.kernel.gridDim.y=params.kernel.gridDim.z=1;params.kernel.blockDim.x=params.kernel.blockDim.y=params.kernel.blockDim.z=1;params.kernel.kernelParams=kernelArgs;kernelArgs[0]=&handle;kernelArgs[1]=&dPtr;cudaGraphAddNode(&node,bodyGraph,nullptr,nullptr,0,¶ms);// Initialize device memory, instantiate, and launch the graphcudaMemset(dPtr,10,1);// Set dPtr to 10; the loop will run until dPtr is 0cudaGraphInstantiate(&graphExec,graph,0);cudaGraphLaunch(graphExec,0);cudaDeviceSynchronize();// Clean upcudaGraphExecDestroy(graphExec);cudaGraphDestroy(graph);cudaFree(dPtr);}
4.2.4.5. 条件 SWITCH 节点
如果 SWITCH 节点执行时条件等于 n,则其从零开始编号的第 n 个主体图将执行一次。下图描绘了一个包含 3 个节点的图,其中中间节点 B 是条件节点:
__global__voidsetHandle(cudaGraphConditionalHandlehandle,intvalue){...// Set the condition value to the value passed to the kernelcudaGraphSetConditional(handle,value);...}voidgraphSetup(){cudaGraph_tgraph;cudaGraphExec_tgraphExec;cudaGraphNode_tnode;void*kernelArgs[2];intvalue=1;// Create the graphcudaGraphCreate(&graph,0);// Create the conditional handle; because no default value is provided, the condition value is undefined at the start of each graph executioncudaGraphConditionalHandlehandle;cudaGraphConditionalHandleCreate(&handle,graph);// Use a kernel upstream of the conditional to set the handle valuecudaGraphNodeParamsparams={cudaGraphNodeTypeKernel};params.kernel.func=(void*)setHandle;params.kernel.gridDim.x=params.kernel.gridDim.y=params.kernel.gridDim.z=1;params.kernel.blockDim.x=params.kernel.blockDim.y=params.kernel.blockDim.z=1;params.kernel.kernelParams=kernelArgs;kernelArgs[0]=&handle;kernelArgs[1]=&value;cudaGraphAddNode(&node,graph,nullptr,nullptr,0,¶ms);// Create and add the conditional SWITCH nodecudaGraphNodeParamscParams={cudaGraphNodeTypeConditional};cParams.conditional.handle=handle;cParams.conditional.type=cudaGraphCondTypeSwitch;cParams.conditional.size=5;cudaGraphAddNode(&node,graph,&node,nullptr,1,&cParams);// Get the body graphs of the conditional nodecudaGraph_t*bodyGraphs=cParams.conditional.phGraph_out;// Populate the body graphs of the SWITCH conditional node...cudaGraphAddNode(&node,bodyGraphs[0],nullptr,nullptr,0,¶ms);...cudaGraphAddNode(&node,bodyGraphs[4],NULL,0,¶ms);// Instantiate and launch the graphcudaGraphInstantiate(&graphExec,graph,0);cudaGraphLaunch(graphExec,0);cudaDeviceSynchronize();// Clean upcudaGraphExecDestroy(graphExec);cudaGraphDestroy(graph);}
4.2.5. 图内存节点
4.2.5.1. 简介
图内存节点允许图创建并拥有内存分配。图内存节点具有 GPU 有序的生命周期语义,该语义规定何时允许在设备上访问内存。这种 GPU 有序的生命周期语义支持由驱动程序管理的内存复用,并且与流有序分配 APIcudaMallocAsync和cudaFreeAsync的语义一致,这些 API 可以在创建图时被捕获。
图分配在图的整个生命周期内都具有固定地址,包括重复实例化和启动。这使得图中的其他操作可以直接引用该内存,而无需更新图,即使 CUDA 更改其后备物理内存也是如此。在一个图内,按图排序的生命周期不重叠的分配可以使用同一底层物理内存。
CUDA 可以为多个图中的分配复用同一物理内存,根据 GPU 有序的生命周期语义为虚拟地址映射设置别名。例如,当不同的图启动到同一个流中时,CUDA 可以为同一物理内存设置虚拟别名,以满足生命周期限于单个图的分配的需求。
// Create the graph - it starts out emptycudaGraphCreate(&graph,0);// parameters for a basic allocationcudaGraphNodeParamsparams={cudaGraphNodeTypeMemAlloc};params.alloc.poolProps.allocType=cudaMemAllocationTypePinned;params.alloc.poolProps.location.type=cudaMemLocationTypeDevice;// specify device 0 as the resident deviceparams.alloc.poolProps.location.id=0;params.alloc.bytesize=size;cudaGraphAddNode(&allocNode,graph,NULL,NULL,0,¶ms);// create a kernel node that uses the graph allocationcudaGraphNodeParamsnodeParams={cudaGraphNodeTypeKernel};nodeParams.kernel.kernelParams[0]=params.alloc.dptr;// ...set other kernel node parameters...// add the kernel node to the graphcudaGraphAddNode(&a,graph,&allocNode,NULL,1,&nodeParams);cudaGraphAddNode(&b,graph,&a,NULL,1,&nodeParams);cudaGraphAddNode(&c,graph,&a,NULL,1,&nodeParams);cudaGraphNode_tdependencies[2];// kernel nodes b and c are using the graph allocation, so the freeing node must depend on them. Since the dependency of node b on node a establishes an indirect dependency, the free node does not need to explicitly depend on node a.dependencies[0]=b;dependencies[1]=c;cudaGraphNodeParamsfreeNodeParams={cudaGraphNodeTypeMemFree};freeNodeParams.free.dptr=params.alloc.dptr;cudaGraphAddNode(&freeNode,graph,dependencies,NULL,2,freeNodeParams);// free node does not depend on kernel node d, so it must not access the freed graph allocation.cudaGraphAddNode(&d,graph,&c,NULL,1,&nodeParams);// node e does not depend on the allocation node, so it must not access the allocation. This would be true even if the freeNode depended on kernel node e.cudaGraphAddNode(&e,graph,NULL,NULL,0,&nodeParams);
4.2.5.2.2. 流捕获
可以通过捕获相应的流有序分配和释放调用cudaMallocAsync与cudaFreeAsync来创建图内存节点。在这种情况下,被捕获的分配 API 返回的虚拟地址可供图内的其他操作使用。由于流有序依赖关系将被捕获到图中,因此流有序分配 API 的排序要求可保证图内存节点相对于被捕获的流操作具有正确的顺序(对于正确编写的流代码而言)。
为清晰起见,忽略核函数节点d和e,以下代码片段展示了如何使用流捕获来创建上一幅图中的图:
cudaMallocAsync(&dptr,size,stream1);kernel_A<<<...,stream1>>>(dptr,...);// Fork into stream2cudaEventRecord(event1,stream1);cudaStreamWaitEvent(stream2,event1);kernel_B<<<...,stream1>>>(dptr,...);// event dependencies translated into graph dependencies, so the kernel node created by the capture of kernel C will depend on the allocation node created by capturing the cudaMallocAsync call.kernel_C<<<...,stream2>>>(dptr,...);// Join stream2 back to origin stream (stream1)cudaEventRecord(event2,stream2);cudaStreamWaitEvent(stream1,event2);// Free depends on all work accessing the memory.cudaFreeAsync(dptr,stream1);// End capture in the origin streamcudaStreamEndCapture(stream1,&graph);
4.2.5.2.3. 在执行分配的图之外访问和释放图内存
图分配不一定要由执行分配的图来释放。当图不释放某项分配时,该分配会在图执行结束后继续存在,并且可以由后续 CUDA 操作访问。只要通过 CUDA 事件和其他流排序机制,使访问操作在顺序上位于分配之后,就可以在另一个图中访问这些分配,也可以直接使用流操作访问。随后可以通过常规调用cudaFree、cudaFreeAsync来释放分配,也可以通过启动另一个具有相应释放节点的图来释放,或者通过随后再次启动执行分配的图来释放(如果该图使用cudaGraphInstantiateFlagAutoFreeOnLaunch标志进行了实例化)。在内存释放后访问它是非法的,必须使用图依赖关系、CUDA 事件及其他流排序机制,使释放操作在顺序上位于所有访问该内存的操作之后。
// Contents of allocating graphvoid*dptr;cudaGraphNodeParamsparams={cudaGraphNodeTypeMemAlloc};params.alloc.poolProps.allocType=cudaMemAllocationTypePinned;params.alloc.poolProps.location.type=cudaMemLocationTypeDevice;params.alloc.bytesize=size;cudaGraphAddNode(&allocNode,allocGraph,NULL,NULL,0,¶ms);dptr=params.alloc.dptr;cudaGraphInstantiate(&allocGraphExec,allocGraph,0);cudaGraphLaunch(allocGraphExec,stream);kernel<<<...,stream>>>(dptr,...);cudaFreeAsync(dptr,stream);
第二,通过记录和等待 CUDA 事件建立顺序:
// Contents of allocating graphvoid*dptr;// Contents of allocating graphcudaGraphAddNode(&allocNode,allocGraph,NULL,NULL,0,&allocNodeParams);dptr=allocNodeParams.alloc.dptr;// contents of consuming/freeing graphkernelNodeParams.kernel.kernelParams[0]=allocNodeParams.alloc.dptr;cudaGraphAddNode(&freeNode,freeGraph,NULL,NULL,1,dptr);cudaGraphInstantiate(&allocGraphExec,allocGraph,0);cudaGraphInstantiate(&freeGraphExec,freeGraph,0);cudaGraphLaunch(allocGraphExec,allocStream);// establish the dependency of stream2 on the allocation node// note: the dependency could also have been established with a stream synchronize operationcudaEventRecord(allocEvent,allocStream);cudaStreamWaitEvent(stream2,allocEvent);kernel<<<...,stream2>>>(dptr,...);// establish the dependency between the stream 3 and the allocation usecudaStreamRecordEvent(streamUseDoneEvent,stream2);cudaStreamWaitEvent(stream3,streamUseDoneEvent);// it is now safe to launch the freeing graph, which may also access the memorycudaGraphLaunch(freeGraphExec,stream3);
第三,通过使用图外部事件节点建立顺序:
// Contents of allocating graphvoid*dptr;cudaEvent_tallocEvent;// event indicating when the allocation will be ready for use.cudaEvent_tstreamUseDoneEvent;// event indicating when the stream operations are done with the allocation.// Contents of allocating graph with event record nodecudaGraphAddNode(&allocNode,allocGraph,NULL,NULL,0,&allocNodeParams);dptr=allocNodeParams.alloc.dptr;// note: this event record node depends on the alloc nodecudaGraphNodeParamsallocEventNodeParams={cudaGraphNodeTypeEventRecord};allocEventNodeParams.eventRecord.event=allocEvent;cudaGraphAddNode(&recordNode,allocGraph,&allocNode,NULL,1,allocEventNodeParams);cudaGraphInstantiate(&allocGraphExec,allocGraph,0);// contents of consuming/freeing graph with event wait nodescudaGraphNodeParamsstreamWaitEventNodeParams={cudaGraphNodeTypeEventWait};streamWaitEventNodeParams.eventWait.event=streamUseDoneEvent;cudaGraphAddNode(&streamUseDoneEventNode,waitAndFreeGraph,NULL,NULL,0,streamWaitEventNodeParams);cudaGraphNodeParamsallocWaitEventNodeParams={cudaGraphNodeTypeEventWait};allocWaitEventNodeParams.eventWait.event=allocEvent;cudaGraphAddNode(&allocReadyEventNode,waitAndFreeGraph,NULL,NULL,0,allocWaitEventNodeParams);kernelNodeParams->kernelParams[0]=allocNodeParams.alloc.dptr;// The allocReadyEventNode provides ordering with the alloc node for use in a consuming graph.cudaGraphAddNode(&kernelNode,waitAndFreeGraph,&allocReadyEventNode,NULL,1,&kernelNodeParams);// The free node has to be ordered after both external and internal users.// Thus the node must depend on both the kernelNode and the streamUseDoneEventNode.dependencies[0]=kernelNode;dependencies[1]=streamUseDoneEventNode;cudaGraphNodeParamsfreeNodeParams={cudaGraphNodeTypeMemFree};freeNodeParams.free.dptr=dptr;cudaGraphAddNode(&freeNode,waitAndFreeGraph,&dependencies,NULL,2,freeNodeParams);cudaGraphInstantiate(&waitAndFreeGraphExec,waitAndFreeGraph,0);cudaGraphLaunch(allocGraphExec,allocStream);// establish the dependency of stream2 on the event node satisfies the ordering requirementcudaStreamWaitEvent(stream2,allocEvent);kernel<<<...,stream2>>>(dptr,...);cudaStreamRecordEvent(streamUseDoneEvent,stream2);// the event wait node in the waitAndFreeGraphExec establishes the dependency on the "readyForFreeEvent" that is needed to prevent the kernel running in stream two from accessing the allocation after the free node in execution order.cudaGraphLaunch(waitAndFreeGraphExec,stream3);
// Create producer graph which allocates memory and populates it with datacudaStreamBeginCapture(cudaStreamPerThread,cudaStreamCaptureModeGlobal);cudaMallocAsync(&data1,blocks*threads,cudaStreamPerThread);cudaMallocAsync(&data2,blocks*threads,cudaStreamPerThread);produce<<<blocks,threads,0,cudaStreamPerThread>>>(data1,data2);...cudaStreamEndCapture(cudaStreamPerThread,&graph);cudaGraphInstantiateWithFlags(&producer,graph,cudaGraphInstantiateFlagAutoFreeOnLaunch);cudaGraphDestroy(graph);// Create first consumer graph by capturing an asynchronous library callcudaStreamBeginCapture(cudaStreamPerThread,cudaStreamCaptureModeGlobal);consumerFromLibrary(data1,cudaStreamPerThread);cudaStreamEndCapture(cudaStreamPerThread,&graph);cudaGraphInstantiateWithFlags(&consumer1,graph,0);//regular instantiationcudaGraphDestroy(graph);// Create second consumer graphcudaStreamBeginCapture(cudaStreamPerThread,cudaStreamCaptureModeGlobal);consume2<<<blocks,threads,0,cudaStreamPerThread>>>(data2);...cudaStreamEndCapture(cudaStreamPerThread,&graph);cudaGraphInstantiateWithFlags(&consumer2,graph,0);cudaGraphDestroy(graph);// Launch in a loopboollaunchConsumer2=false;do{cudaGraphLaunch(producer,myStream);cudaGraphLaunch(consumer1,myStream);if(launchConsumer2){cudaGraphLaunch(consumer2,myStream);}}while(determineAction(&launchConsumer2));cudaFreeAsync(data1,myStream);cudaFreeAsync(data2,myStream);cudaGraphExecDestroy(producer);cudaGraphExecDestroy(consumer1);cudaGraphExecDestroy(consumer2);
4.2.5.2.5. 子图中的内存节点
CUDA 12.9 引入了将子图所有权移交给父图的功能。移交给父图的子图允许包含内存分配和释放节点。这使得包含分配或释放节点的子图可以在添加到父图之前独立构建。
子图移交后适用以下限制:
不能独立实例化或销毁。
不能作为子图添加到另一个父图中。
不能用作 cuGraphExecUpdate 的参数。
不能再向其中添加内存分配或释放节点。
// Create the child graphcudaGraphCreate(&child,0);// parameters for a basic allocationcudaGraphNodeParamsallocNodeParams={cudaGraphNodeTypeMemAlloc};allocNodeParams.alloc.poolProps.allocType=cudaMemAllocationTypePinned;allocNodeParams.alloc.poolProps.location.type=cudaMemLocationTypeDevice;// specify device 0 as the resident deviceallocNodeParams.alloc.poolProps.location.id=0;allocNodeParams.alloc.bytesize=size;cudaGraphAddNode(&allocNode,child,NULL,NULL,0,&allocNodeParams);// Additional nodes using the allocation could be added herecudaGraphNodeParamsfreeNodeParams={cudaGraphNodeTypeMemFree};freeNodeParams.free.dptr=allocNodeParams.alloc.dptr;cudaGraphAddNode(&freeNode,child,&allocNode,NULL,1,freeNodeParams);// Create the parent graphcudaGraphCreate(&parent,0);// Move the child graph to the parent graphcudaGraphNodeParamschildNodeParams={cudaGraphNodeTypeGraph};childNodeParams.graph.graph=child;childNodeParams.graph.ownership=cudaGraphChildGraphOwnershipMove;cudaGraphAddNode(&parentNode,parent,NULL,NULL,0,&childNodeParams);
4.2.5.3. 优化的内存复用
CUDA 通过两种方式复用内存:
图内虚拟内存和物理内存的复用基于虚拟地址分配,与流有序分配器中的方式类似。
图之间物理内存的复用通过虚拟别名实现:不同的图可以将同一物理内存映射到各自唯一的虚拟地址。
4.2.5.3.1. 图内地址复用
CUDA 可以将相同的虚拟地址范围分配给生命周期不重叠的不同内存分配,从而在图内复用内存。由于虚拟地址可能被复用,因此不能保证指向生命周期互不重叠的不同内存分配的指针是唯一的。
CUDA 负责在 GPU 执行顺序到达分配节点之前,将物理内存映射到虚拟地址。为了优化内存占用和映射开销,如果多个图不会同时运行,它们可以将同一物理内存用于不同的内存分配;但是,如果物理页同时绑定到多个正在执行的图,或绑定到尚未释放的图内存分配,则不能复用这些物理页。
CUDA 可以在图实例化、启动或执行期间的任何时刻更新物理内存映射。CUDA 还可以在后续图启动之间引入同步,以防止仍然存续的图内存分配引用同一物理内存。与任何分配、释放、再分配模式一样,如果程序在某次内存分配的生命周期之外访问指针,那么该错误访问可能会在不报错的情况下读取或写入另一内存分配所拥有的有效数据(即使该内存分配的虚拟地址是唯一的)。使用 compute sanitizer 工具可以捕获此错误。
下图展示了在同一流中依次启动的图。在此示例中,每个图都会释放其分配的全部内存。由于同一流中的图从不并发运行,因此 CUDA 可以而且应该使用同一物理内存来满足所有内存分配。
图 33 依次启动的图
图内文字中文对照
Graph1
图 1
Graph2
图 2
Graph3
图 3
Physical memory
物理内存
4.2.5.4. 性能注意事项
当多个图被启动到同一流中时,CUDA 会尝试为它们分配相同的物理内存,因为这些图的执行不可能重叠。作为一种优化,图的物理映射会在各次启动之间保留,以避免重新映射的开销。如果稍后某个图以其执行可能与其他图重叠的方式启动(例如,被启动到另一个流中),那么 CUDA 就必须执行一些重新映射,因为并发图需要不同的内存以避免数据损坏。
cudaDeviceGraphMemTrim将取消映射并释放图内存节点预留的、当前未被使用的所有物理内存。尚未释放的内存分配以及已调度或正在运行的图被视为正在使用物理内存,因此不会受到影响。使用裁剪 API 将使物理内存可供其他分配 API 以及其他应用程序或进程使用,但会导致 CUDA 在下次启动经过裁剪的图时重新分配并重新映射内存。请注意,cudaDeviceGraphMemTrim与cudaMemPoolTrimTo()操作的是不同的内存池。图内存池不向 steam 有序内存分配器开放。CUDA 允许应用程序通过cudaDeviceGetGraphMemAttributeAPI 查询其图内存占用。查询属性cudaGraphMemAttrReservedMemCurrent会返回驱动程序为当前进程中的图内存分配预留的物理内存量。查询cudaGraphMemAttrUsedMemCurrent会返回当前至少被一个图映射的物理内存量。这两个属性中的任意一个都可用于跟踪 CUDA 何时为执行分配的图获取了新的物理内存。这两个属性都有助于检查共享机制节省了多少内存。
cudaGraphNodeParamsallocNodeParams={cudaGraphNodeTypeMemAlloc};allocNodeParams.alloc.poolProps.allocType=cudaMemAllocationTypePinned;allocNodeParams.alloc.poolProps.location.type=cudaMemLocationTypeDevice;// specify device 1 as the resident deviceallocNodeParams.alloc.poolProps.location.id=1;allocNodeParams.alloc.bytesize=size;// allocate an allocation resident on device 1 accessible from device 1cudaGraphAddNode(&allocNode,graph,NULL,NULL,0,&allocNodeParams);cudaMemAccessDescaccessDescs[2];// boilerplate for the access descs (only ReadWrite and Device access supported by the add node api)accessDescs[0].flags=cudaMemAccessFlagsProtReadWrite;accessDescs[0].location.type=cudaMemLocationTypeDevice;accessDescs[1].flags=cudaMemAccessFlagsProtReadWrite;accessDescs[1].location.type=cudaMemLocationTypeDevice;// access being requested for device 0 & 2. Device 1 access requirement left implicit.accessDescs[0].location.id=0;accessDescs[1].location.id=2;// access request array has 2 entries.allocNodeParams.accessDescCount=2;allocNodeParams.accessDescs=accessDescs;// allocate an allocation resident on device 1 accessible from devices 0, 1 and 2. (0 & 2 from the descriptors, 1 from it being the resident device).cudaGraphAddNode(&allocNode,graph,NULL,NULL,0,&allocNodeParams);
// boilerplate for the access descs (only ReadWrite and Device access supported by the add node api)accessDesc.flags=cudaMemAccessFlagsProtReadWrite;accessDesc.location.type=cudaMemLocationTypeDevice;accessDesc.location.id=1;// let memPool be resident and accessible on device 0cudaStreamBeginCapture(stream);cudaMallocFromPoolAsync(&dptr1,size,memPool,stream);cudaStreamEndCapture(stream,&graph1);cudaMemPoolSetAccess(memPool,&accessDesc,1);cudaStreamBeginCapture(stream);cudaMallocFromPoolAsync(&dptr2,size,memPool,stream);cudaStreamEndCapture(stream,&graph2);//The graph node allocating dptr1 would only have the device 0 accessibility even though memPool now has device 1 accessibility.//The graph node allocating dptr2 will have device 0 and device 1 accessibility, since that was the pool accessibility at the time of the cudaMallocFromPoolAsync call.
// Explicit upload after instantiationcudaGraphInstantiate(&deviceGraphExec1,deviceGraph1,cudaGraphInstantiateFlagDeviceLaunch);cudaGraphUpload(deviceGraphExec1,stream);// Explicit upload as part of instantiationcudaGraphInstantiateParamsinstantiateParams={0};instantiateParams.flags=cudaGraphInstantiateFlagDeviceLaunch|cudaGraphInstantiateFlagUpload;instantiateParams.uploadStream=stream;cudaGraphInstantiateWithParams(&deviceGraphExec2,deviceGraph2,&instantiateParams);// Implicit upload via host launchcudaGraphInstantiate(&deviceGraphExec3,deviceGraph3,cudaGraphInstantiateFlagDeviceLaunch);cudaGraphLaunch(deviceGraphExec3,stream);
__global__voidlaunchFireAndForgetGraph(cudaGraphExec_tgraph){cudaGraphLaunch(graph,cudaStreamGraphFireAndForget);}voidgraphSetup(){cudaGraphExec_tgExec1,gExec2;cudaGraph_tg1,g2;// Create, instantiate, and upload the device graph.create_graph(&g2);cudaGraphInstantiate(&gExec2,g2,cudaGraphInstantiateFlagDeviceLaunch);cudaGraphUpload(gExec2,stream);// Create and instantiate the launching graph.cudaStreamBeginCapture(stream,cudaStreamCaptureModeGlobal);launchFireAndForgetGraph<<<1,1,0,stream>>>(gExec2);cudaStreamEndCapture(stream,&g1);cudaGraphInstantiate(&gExec1,g1,0);// Launch the host graph, which will in turn launch the device graph.cudaGraphLaunch(gExec1,stream);}
__global__voidlaunchTailGraph(cudaGraphExec_tgraph){cudaGraphLaunch(graph,cudaStreamGraphTailLaunch);}voidgraphSetup(){cudaGraphExec_tgExec1,gExec2;cudaGraph_tg1,g2;// Create, instantiate, and upload the device graph.create_graph(&g2);cudaGraphInstantiate(&gExec2,g2,cudaGraphInstantiateFlagDeviceLaunch);cudaGraphUpload(gExec2,stream);// Create and instantiate the launching graph.cudaStreamBeginCapture(stream,cudaStreamCaptureModeGlobal);launchTailGraph<<<1,1,0,stream>>>(gExec2);cudaStreamEndCapture(stream,&g1);cudaGraphInstantiate(&gExec1,g1,0);// Launch the host graph, which will in turn launch the device graph.cudaGraphLaunch(gExec1,stream);}
__global__voidlaunchSiblingGraph(cudaGraphExec_tgraph){cudaGraphLaunch(graph,cudaStreamGraphFireAndForgetAsSibling);}voidgraphSetup(){cudaGraphExec_tgExec1,gExec2;cudaGraph_tg1,g2;// Create, instantiate, and upload the device graph.create_graph(&g2);cudaGraphInstantiate(&gExec2,g2,cudaGraphInstantiateFlagDeviceLaunch);cudaGraphUpload(gExec2,stream);// Create and instantiate the launching graph.cudaStreamBeginCapture(stream,cudaStreamCaptureModeGlobal);launchSiblingGraph<<<1,1,0,stream>>>(gExec2);cudaStreamEndCapture(stream,&g1);cudaGraphInstantiate(&gExec1,g1,0);// Launch the host graph, which will in turn launch the device graph.cudaGraphLaunch(gExec1,stream);}
CUDA 用户对象可用于帮助管理 CUDA 中异步工作所使用的资源的生命周期。特别是,此功能对CUDA 图和流捕获很有用。
各种资源管理方案与 CUDA 图并不兼容。例如,考虑基于事件的池,或同步创建、异步销毁的方案。
// Library API with pool allocationvoidlibraryWork(cudaStream_tstream){auto&resource=pool.claimTemporaryResource();resource.waitOnReadyEventInStream(stream);launchWork(stream,resource);resource.recordReadyEvent(stream);}
// Library API with asynchronous resource deletionvoidlibraryWork(cudaStream_tstream){Resource*resource=newResource(...);launchWork(stream,resource);cudaLaunchHostFunc(stream,[](void*resource){deletestatic_cast<Resource*>(resource);},resource,0);// Error handling considerations not shown}
这些方案很难与 CUDA 图配合使用,因为资源的指针或句柄并不固定,需要间接寻址或图更新,而且每次提交工作时都需要同步的 CPU 代码。如果这些考量对库的调用方是隐藏的,这些方案也无法与流捕获配合使用;在捕获期间使用了不允许的 API 也使它们无法与流捕获配合使用。存在多种解决方案,例如向调用方公开资源。CUDA 用户对象提供了另一种方法。
CUDA 用户对象将用户指定的析构回调与内部引用计数关联起来,类似于 C++ 的shared_ptr。引用可以由 CPU 上的用户代码持有,也可以由 CUDA 图持有。请注意,对于用户持有的引用,与 C++ 智能指针不同,没有表示该引用的对象;用户必须手动跟踪用户持有的引用。典型用例是在创建用户对象后,立即将用户持有的唯一引用移交给 CUDA 图。
当引用与 CUDA 图关联时,CUDA 将自动管理图操作。克隆得到的cudaGraph_t会保留源cudaGraph_t持有的每个引用的副本,且重数相同。实例化得到的cudaGraphExec_t会保留源cudaGraph_t中的每个引用的副本。当cudaGraphExec_t在未同步的情况下被销毁时,这些引用会一直保留到执行完成。
以下是一个使用示例。
cudaGraph_tgraph;// Preexisting graphObject*object=newObject;// C++ object with possibly nontrivial destructorcudaUserObject_tcuObject;cudaUserObjectCreate(&cuObject,object,// Here we use a CUDA-provided template wrapper for this API,// which supplies a callback to delete the C++ object pointer1,// Initial refcountcudaUserObjectNoDestructorSync// Acknowledge that the callback cannot be// waited on via CUDA);cudaGraphRetainUserObject(graph,cuObject,1,// Number of referencescudaGraphUserObjectMove// Transfer a reference owned by the caller (do// not modify the total reference count));// No more references owned by this thread; no need to call release APIcudaGraphExec_tgraphExec;cudaGraphInstantiate(&graphExec,graph,0);// Will retain a// new referencecudaGraphDestroy(graph);// graphExec still owns a referencecudaGraphLaunch(graphExec,0);// Async launch has access to the user objectscudaGraphExecDestroy(graphExec);// Launch is not synchronized; the release// will be deferred if neededcudaStreamSynchronize(0);// After the launch is synchronized, the remaining// reference is released and the destructor will// execute. Note this happens asynchronously.// If the destructor callback had signaled a synchronization object, it would// be safe to wait on it at this point.
目前没有通过 CUDA API 等待用户对象析构函数的机制。用户可以从析构函数代码中手动向同步对象发送信号。此外,不允许从析构函数中调用 CUDA API,这与对cudaLaunchHostFunc的限制类似。这是为了避免阻塞 CUDA 内部的共享线程并阻碍执行继续推进。如果依赖关系是单向的,而且执行调用的线程不会阻碍 CUDA 工作继续推进,则允许向另一个线程发送信号,让其执行 API 调用。
用户对象通过cudaUserObjectCreate创建,这是浏览相关 API 的一个良好起点。
4.3. 流有序内存分配器
4.3.1. 简介
使用cudaMalloc和cudaFree管理内存分配会导致 GPU 在所有正在执行的 CUDA 流之间进行同步。流有序内存分配器使应用程序能够确定内存分配和释放与启动到 CUDA 流中的其他工作之间的先后顺序,这些工作包括核函数启动和异步复制。它利用流有序语义复用已分配的内存,从而改善应用程序的内存使用。分配器还允许应用程序控制分配器的内存缓存行为。设置适当的释放阈值后,当应用程序表示愿意接受更大的内存占用量时,缓存行为使分配器能够避免开销高昂的操作系统调用。该分配器还支持在进程之间轻松、安全地共享已分配的内存。
流有序内存分配器:
减少了对自定义内存管理抽象的需求,并使有需要的应用程序能够更轻松地创建高性能的自定义内存管理。
使多个库能够共享由驱动程序管理的公共内存池。这可以减少多余的内存消耗。
允许驱动程序基于其对分配器和其他流管理 API 的了解来执行优化。
注意
自 CUDA 11.3 起,Nsight Compute 和 Next-Gen CUDA 调试器能够感知该分配器。
4.3.2. 内存管理
cudaMallocAsync和cudaFreeAsync是实现流有序内存管理的 API。cudaMallocAsync返回一块分配的内存,而cudaFreeAsync释放一块分配的内存。这两个 API 都接受流参数,以定义所分配的内存何时开始可用以及何时停止可用。这些函数允许将内存操作绑定到特定的 CUDA 流,使这些操作能够在不阻塞主机或其他流的情况下进行。通过避免cudaMalloc和cudaFree可能开销高昂的同步,可以提高应用程序性能。
这些 API 可通过内存池进一步优化性能,内存池管理和复用大块内存,以实现更高效的分配和释放。内存池有助于减少开销并防止碎片化,从而提高频繁进行内存分配操作的场景中的性能。
4.3.2.1. 分配内存
cudaMallocAsync函数在 GPU 上触发异步内存分配,并将其关联到特定的 CUDA 流。cudaMallocAsync允许在不妨碍主机或其他流的情况下进行内存分配,从而消除开销高昂的同步的必要性。
void*ptr;size_tsize=512;cudaMallocAsync(&ptr,size,cudaStreamPerThread);// do work using the allocationkernel<<<...,cudaStreamPerThread>>>(ptr,...);// An asynchronous free can be specified without synchronizing the cpu and GPUcudaFreeAsync(ptr,cudaStreamPerThread);
注意
从执行分配的流以外的流访问所分配的内存时,用户必须保证访问发生在分配操作之后,否则行为未定义。
4.3.2.2. 释放内存
cudaFreeAsync()以流有序的方式异步释放设备内存,这意味着内存释放被分配给特定的 CUDA 流,并且不会阻塞主机或其他流。
cudaMallocAsync(&ptr,size,stream1);cudaEventRecord(event1,stream1);//stream2 must wait for the allocation to be ready before accessingcudaStreamWaitEvent(stream2,event1);kernel<<<...,stream2>>>(ptr,...);cudaEventRecord(event2,stream2);// stream3 must wait for stream2 to finish accessing the allocation before// freeing the allocationcudaStreamWaitEvent(stream3,event2);cudaFreeAsync(ptr,stream3);
cudaMallocAsync(&ptr,size,stream);kernel<<<...,stream>>>(ptr,...);// synchronize is needed to avoid prematurely freeing the memorycudaStreamSynchronize(stream);cudaFree(ptr);
APIcudaMallocFromPoolAsync和cudaMallocAsync 的 c++ 重载允许用户指定一次分配所使用的池,而无需将其设为当前池。APIcudaDeviceGetDefaultMempool和cudaMemPoolCreate返回内存池的句柄。cudaMemPoolSetAttribute和cudaMemPoolGetAttribute控制内存池的属性。
cudaMemPoolCreate创建一个显式池。这允许应用程序为其内存分配请求默认/隐式池所提供的特性之外的特性。这些特性包括 IPC 能力、最大池大小、在支持的平台上使所分配的内存驻留在特定 CPU NUMA 节点上等。
// create a pool similar to the implicit pool on device 0intdevice=0;cudaMemPoolPropspoolProps={};poolProps.allocType=cudaMemAllocationTypePinned;poolProps.location.id=device;poolProps.location.type=cudaMemLocationTypeDevice;cudaMemPoolCreate(&memPool,&poolProps));
以下代码片段展示了在有效的 CPU NUMA 节点上创建支持 IPC 的内存池的示例。
// create a pool resident on a CPU NUMA node that is capable of IPC sharing (via a file descriptor).intcpu_numa_id=0;cudaMemPoolPropspoolProps={};poolProps.allocType=cudaMemAllocationTypePinned;poolProps.location.id=cpu_numa_id;poolProps.location.type=cudaMemLocationTypeHostNuma;poolProps.handleType=cudaMemHandleTypePosixFileDescriptor;cudaMemPoolCreate(&ipcMemPool,&poolProps));
4.3.3.3. 用于多 GPU 支持的设备可访问性
与通过虚拟内存管理 API 控制的内存分配可访问性一样,内存池分配的内存的可访问性不遵循cudaDeviceEnablePeerAccess或cuCtxEnablePeerAccess。对于内存池,APIcudaMemPoolSetAccess用于修改哪些设备可以访问从池中分配的内存。默认情况下,只有所分配内存所在的设备可以访问这些内存。此访问权限无法撤销。要启用其他设备的访问,进行访问的设备必须与内存池所在的设备具有对等访问能力。这可以通过cudaDeviceCanAccessPeer进行验证。如果未检查对等访问能力,设置访问权限的操作可能会失败并返回cudaErrorInvalidDevice。但是,如果尚未从该池进行过任何分配,则即使设备不具备对等访问能力,cudaMemPoolSetAccess调用也可能成功。在这种情况下,下一次从该池进行的分配将失败。
// snippet showing usage of cudaMemPoolSetAccess:cudaError_tsetAccessOnDevice(cudaMemPool_tmemPool,intresidentDevice,intaccessingDevice){cudaMemAccessDescaccessDesc={};accessDesc.location.type=cudaMemLocationTypeDevice;accessDesc.location.id=accessingDevice;accessDesc.flags=cudaMemAccessFlagsProtReadWrite;intcanAccess=0;cudaError_terror=cudaDeviceCanAccessPeer(&canAccess,accessingDevice,residentDevice);if(error!=cudaSuccess){returnerror;}elseif(canAccess==0){returncudaErrorPeerAccessUnsupported;}// Make the address accessiblereturncudaMemPoolSetAccess(memPool,&accessDesc,1);}
4.3.3.4. 为 IPC 启用内存池
可以为内存池启用进程间通信(IPC),以便在进程之间轻松、高效且安全地共享 GPU 内存。CUDA 的 IPC 内存池提供了与 CUDA 的虚拟内存管理 API相同的安全优势。
// in exporting process// create an exportable IPC capable pool on device 0cudaMemPoolPropspoolProps={};poolProps.allocType=cudaMemAllocationTypePinned;poolProps.location.id=0;poolProps.location.type=cudaMemLocationTypeDevice;// Setting handleTypes to a non zero value will make the pool exportable (IPC capable)poolProps.handleTypes=CU_MEM_HANDLE_TYPE_POSIX_FILE_DESCRIPTOR;cudaMemPoolCreate(&memPool,&poolProps));// FD based handles are integer typesintfdHandle=0;// Retrieve an OS native handle to the pool.// Note that a pointer to the handle memory is passed in here.cudaMemPoolExportToShareableHandle(&fdHandle,memPool,CU_MEM_HANDLE_TYPE_POSIX_FILE_DESCRIPTOR,0);// The handle must be sent to the importing process with the appropriate// OS-specific APIs.
// in importing processintfdHandle;// The handle needs to be retrieved from the exporting process with the// appropriate OS-specific APIs.// Create an imported pool from the shareable handle.// Note that the handle is passed by value here.cudaMemPoolImportFromShareableHandle(&importedMemPool,(void*)fdHandle,CU_MEM_HANDLE_TYPE_POSIX_FILE_DESCRIPTOR,0);
// preparing an allocation in the exporting processcudaMemPoolPtrExportDataexportData;cudaEvent_treadyIpcEvent;cudaIpcEventHandle_treadyIpcEventHandle;// ipc event for coordinating between processes// cudaEventInterprocess flag makes the event an ipc event// cudaEventDisableTiming is set for performance reasonscudaEventCreate(&readyIpcEvent,cudaEventDisableTiming|cudaEventInterprocess)// allocate from the exporting mem poolcudaMallocAsync(&ptr,size,exportMemPool,stream);// event for sharing when the allocation is ready.cudaEventRecord(readyIpcEvent,stream);cudaMemPoolExportPointer(&exportData,ptr);cudaIpcGetEventHandle(&readyIpcEventHandle,readyIpcEvent);// Share IPC event and pointer export data with the importing process using// any mechanism. Here we copy the data into shared memoryshmem->ptrData=exportData;shmem->readyIpcEventHandle=readyIpcEventHandle;// signal consumers data is ready
// Importing an allocationcudaMemPoolPtrExportData*importData=&shmem->prtData;cudaEvent_treadyIpcEvent;cudaIpcEventHandle_t*readyIpcEventHandle=&shmem->readyIpcEventHandle;// Need to retrieve the ipc event handle and the export data from the// exporting process using any mechanism. Here we are using shmem and just// need synchronization to make sure the shared memory is filled in.cudaIpcOpenEventHandle(&readyIpcEvent,readyIpcEventHandle);// import the allocation. The operation does not block on the allocation being ready.cudaMemPoolImportPointer(&ptr,importedMemPool,importData);// Wait for the prior stream operations in the allocating stream to complete before// using the allocation in the importing process.cudaStreamWaitEvent(stream,readyIpcEvent);kernel<<<...,stream>>>(ptr,...);
释放内存分配时,必须先在导入进程中释放该内存分配,然后才能在导出进程中释放。以下代码片段演示了如何使用 CUDA IPC 事件,在两个进程的cudaFreeAsync操作之间提供所需的同步。显然,从导入进程对内存分配的访问受到导入进程一侧的释放操作的限制。值得注意的是,可以使用cudaFree在两个进程中释放该内存分配,也可以使用其他流同步 API 来代替 CUDA IPC 事件。
// The free must happen in importing process before the exporting processkernel<<<...,stream>>>(ptr,...);// Last access in importing processcudaFreeAsync(ptr,stream);// Access not allowed in the importing process after the freecudaIpcEventRecord(finishedIpcEvent,stream);
// Exporting process// The exporting process needs to coordinate its free with the stream order// of the importing process’s free.cudaStreamWaitEvent(stream,finishedIpcEvent);kernel<<<...,stream>>>(ptrInExportingProcess,...);// The free in the importing process doesn’t stop the exporting process// from using the allocation.cudFreeAsync(ptrInExportingProcess,stream);
可以使用cudaDevAttrMemoryPoolSupportedHandleTypes设备属性查询 IPC 内存池的支持情况。此属性是在 CUDA 11.3 中添加的,旧版驱动程序在查询此属性时将返回cudaErrorInvalidValue。
intdriverVersion=0;intdeviceSupportsMemoryPools=0;intpoolSupportedHandleTypes=0;cudaDriverGetVersion(&driverVersion);if(driverVersion>=11020){cudaDeviceGetAttribute(&deviceSupportsMemoryPools,cudaDevAttrMemoryPoolsSupported,device);}if(deviceSupportsMemoryPools!=0){// `device` supports the Stream-Ordered Memory Allocator}if(driverVersion>=11030){cudaDeviceGetAttribute(&poolSupportedHandleTypes,cudaDevAttrMemoryPoolSupportedHandleTypes,device);}if(poolSupportedHandleTypes&cudaMemHandleTypePosixFileDescriptor){// Pools on the specified device can be created with posix file descriptor-based IPC}
Cuuint64_tsetVal=UINT64_MAX;cudaMemPoolSetAttribute(memPool,cudaMemPoolAttrReleaseThreshold,&setVal);// application phase needing a lot of memory from the stream-ordered allocatorfor(i=0;i<10;i++){for(j=0;j<10;j++){cudaMallocAsync(&ptrs[j],size[j],stream);}kernel<<<...,stream>>>(ptrs,...);for(j=0;j<10;j++){cudaFreeAsync(ptrs[j],stream);}}// Process does not need as much memory for the next phase.// Synchronize so that the trim operation will know that the allocations are no// longer in use.cudaStreamSynchronize(stream);cudaMemPoolTrimTo(mempool,0);// Some other process/allocation mechanism can now use the physical memory// released by the trimming operation.
// sample helper functions for getting the usage statistics in bulkstructusageStatistics{cuuint64_treserved;cuuint64_treservedHigh;cuuint64_tused;cuuint64_tusedHigh;};voidgetUsageStatistics(cudaMemoryPool_tmemPool,structusageStatistics*statistics){cudaMemPoolGetAttribute(memPool,cudaMemPoolAttrReservedMemCurrent,statistics->reserved);cudaMemPoolGetAttribute(memPool,cudaMemPoolAttrReservedMemHigh,statistics->reservedHigh);cudaMemPoolGetAttribute(memPool,cudaMemPoolAttrUsedMemCurrent,statistics->used);cudaMemPoolGetAttribute(memPool,cudaMemPoolAttrUsedMemHigh,statistics->usedHigh);}// resetting the watermarks will make them take on the current value.voidresetStatistics(cudaMemoryPool_tmemPool){cuuint64_tvalue=0;cudaMemPoolSetAttribute(memPool,cudaMemPoolAttrReservedMemHigh,&value);cudaMemPoolSetAttribute(memPool,cudaMemPoolAttrUsedMemHigh,&value);}
4.3.4.4. 内存重用策略
为了满足分配请求,驱动程序在尝试从操作系统分配更多内存之前,会先尝试重用此前通过cudaFreeAsync()释放的内存。例如,在某个流中释放的内存可以立即用于该流中的后续分配请求。当流与 CPU 同步时,此前在该流中释放的内存就可供任意流中的分配重用。重用策略既可应用于默认内存池,也可应用于显式内存池。
流有序分配器具有几种可控制的分配策略。池属性cudaMemPoolReuseFollowEventDependencies、cudaMemPoolReuseAllowOpportunistic和cudaMemPoolReuseAllowInternalDependencies控制这些策略,具体说明见下文。可以通过调用cudaMemPoolSetAttribute来启用或禁用这些策略。升级到更新的 CUDA 驱动程序可能会更改、增强、扩充和/或重新排序所枚举的重用策略。
在分配更多物理 GPU 内存之前,分配器会检查由 CUDA 事件建立的依赖关系信息,并尝试从另一个流中释放的内存进行分配。
cudaMallocAsync(&ptr,size,originalStream);kernel<<<...,originalStream>>>(ptr,...);cudaFreeAsync(ptr,originalStream);cudaEventRecord(event,originalStream);// waiting on the event that captures the free in another stream// allows the allocator to reuse the memory to satisfy// a new allocation request in the other stream when// cudaMemPoolReuseFollowEventDependencies is enabled.cudaStreamWaitEvent(otherStream,event);cudaMallocAsync(&ptr2,size,otherStream);
4.3.4.4.2. cudaMemPoolReuseAllowOpportunistic
启用cudaMemPoolReuseAllowOpportunistic策略时,分配器会检查已释放的内存分配,以确定释放操作的流顺序语义是否已得到满足,例如流是否已越过释放操作所指示的执行点。禁用此策略时,分配器仍会重用流与 CPU 同步时变为可用的内存。禁用此策略不会阻止cudaMemPoolReuseFollowEventDependencies的应用。
cudaMallocAsync(&ptr,size,originalStream);kernel<<<...,originalStream>>>(ptr,...);cudaFreeAsync(ptr,originalStream);// after some time, the kernel finishes runningwait(10);// When cudaMemPoolReuseAllowOpportunistic is enabled this allocation request// can be fulfilled with the prior allocation based on the progress of originalStream.cudaMallocAsync(&ptr2,size,otherStream);
cudaMallocAsync(&ptr,size,originalStream);kernel<<<...,originalStream>>>(ptr,...);cudaFreeAsync(ptr,originalStream);// When cudaMemPoolReuseAllowInternalDependencies is enabled// and the driver fails to allocate more physical memory, the driver may// effectively perform a cudaStreamWaitEvent in the allocating stream// to make sure that future work in ‘otherStream’ happens after the work// in the original stream that would be allowed to access the original allocation.cudaMallocAsync(&ptr2,size,otherStream);
4.3.4.4.4. 禁用重用策略
虽然可控制的重用策略可以改善内存重用,但用户可能希望禁用它们。允许机会性重用(例如cudaMemPoolReuseAllowOpportunistic)会使分配模式基于 CPU 和 GPU 执行的交错情况,在各次运行之间产生差异。当用户更愿意在分配失败时显式同步事件或流时,内部依赖关系插入(例如cudaMemPoolReuseAllowInternalDependencies)可能会以出乎意料且可能不确定的方式使工作串行化。
4.3.4.5. 同步 API 的操作
分配器作为 CUDA 驱动程序的一部分所带来的一项优化是与同步 API 的集成。当用户请求 CUDA 驱动程序执行同步时,驱动程序会等待异步工作完成。在返回之前,驱动程序将确定哪些释放操作已由此次同步保证完成。无论指定了哪个流或禁用了哪些分配策略,这些内存分配都会变为可供分配的内存。驱动程序还会在此处检查cudaMemPoolAttrReleaseThreshold,并尽可能释放所有多余的物理内存。
4.3.5. 补充说明
4.3.5.1. cudaMemcpyAsync 对当前上下文/设备的敏感性
在当前的 CUDA 驱动程序中,任何涉及来自cudaMallocAsync的内存的异步memcpy操作,都应使用指定流的上下文作为调用线程的当前上下文来执行。对于cudaMemcpyPeerAsync,则不必如此,因为它引用的是 API 中指定的设备主上下文,而不是当前上下文。
namespacecg=cooperative_groups;// Obtain the current thread's cooperative groupcg::thread_blockmy_group=cg::this_thread_block();// Partition the cooperative group into tiles of size 8cg::thread_block_tile<8>my_subgroup=cg::tiled_partition<8>(my_group);// do work as my_subgroup
namespacecg=cooperative_groups;cg::thread_blockmy_group=this_block();cg::cluster_groupcluster=this_cluster();autotoken=cluster.barrier_arrive();// Optional: Do some local processing to hide the synchronization latencylocal_processing(my_group);// Make sure all other blocks in the cluster are running and initialized shared data before accessing dsmemcluster.barrier_wait(std::move(token));
namespacecg=cooperative_groups;cg::thread_blockmy_group=cg::this_thread_block();intval=data[threadIdx.x];intsum=cg::reduce(my_group,val,cg::plus<int>());// Store the result from the reductionif(my_group.thread_rank()==0){result[blockIdx.x]=sum;}
namespacecg=cooperative_groups;cg::thread_blockmy_group=cg::this_thread_block();// Ensure only one thread in the thread block prints the messagecg::invoke_one(my_group,[](){printf("Hello from one thread in the block!");});// Synchronize to make sure all threads wait until the message is printedcg::sync(my_group);
可调用函数内部不允许在调用组内进行通信或同步。允许与调用组之外的线程进行通信。
4.4.7. 异步数据移动
CUDA 中协作组的memcpy_async功能提供了一种在全局内存与共享内存之间执行异步内存复制的方法。memcpy_async尤其适合优化内存传输,并使计算与数据传输重叠,从而提高性能。
namespacecg=cooperative_groups;cg::thread_groupmy_group=cg::this_thread_block();__shared__intshared_data[];// Perform an asynchronous copy from global memory to shared memorycg::memcpy_async(my_group,shared_data+my_group.rank(),input+my_group.rank(),sizeof(int));// Hide latency by doing work here. Cannot use shared_data// Wait for the asynchronous copy to completecg::wait(my_group);// Prefetched data is now available
cudaLaunchCooperativeKernel是一个 CUDA 运行时 API 函数,用于启动使用协作组的单设备核函数,专为执行需要线程块间同步的核函数而设计。此函数确保核函数中的所有线程都能在整个网格范围内同步并协作,而传统 CUDA 核函数只允许在各个线程块内部同步,无法做到这一点。cudaLaunchCooperativeKernel确保核函数启动是原子的,即如果 API 调用成功,则指定数量的线程块将在指定设备上启动。
编程式依赖启动对 CUDA 核函数启动 API 引入了更改,下一节将对此进行说明。这些 API 要求计算能力至少为 9.0 才能提供重叠执行。
4.5.2. API 说明
在编程式依赖启动中,主核函数和次级核函数在同一 CUDA 流中启动。当主核函数准备好让次级核函数启动时,其所有线程块都应执行cudaTriggerProgrammaticLaunchCompletion。次级核函数必须使用所示的可扩展启动 API 来启动。
__global__voidprimary_kernel(){// Initial work that should finish before starting secondary kernel// Trigger the secondary kernelcudaTriggerProgrammaticLaunchCompletion();// Work that can coincide with the secondary kernel}__global__voidsecondary_kernel(){// Independent work// Will block until all primary kernels the secondary kernel is dependent on have completed and flushed results to global memorycudaGridDependencySynchronize();// Dependent work}cudaLaunchAttributeattribute[1];attribute[0].id=cudaLaunchAttributeProgrammaticStreamSerialization;attribute[0].val.programmaticStreamSerializationAllowed=1;configSecondary.attrs=attribute;configSecondary.numAttrs=1;primary_kernel<<<grid_dim,block_dim,0,stream>>>();cudaLaunchKernelEx(&configSecondary,secondary_kernel);
可以通过流捕获,或直接通过边数据,在CUDA 图中使用编程式依赖启动。要在 CUDA 图中通过边数据编程实现此功能,请在连接两个核函数节点的边上将cudaGraphDependencyType的值设为cudaGraphDependencyTypeProgrammatic。这种边类型使上游核函数对下游核函数中的cudaGridDependencySynchronize()可见。此类型必须与cudaGraphKernelNodePortLaunchCompletion或cudaGraphKernelNodePortProgrammatic出端口一起使用。
绿色上下文(GC)是一种轻量级上下文,从创建时起就与一组特定的 GPU 资源相关联。用户可以在创建绿色上下文时划分 GPU 资源,目前包括流式多处理器(SM)和工作队列(WQ),这样,以某个绿色上下文为目标的 GPU 工作就只能使用为其分配的 SM 和工作队列。这样做有助于减少或更好地控制因使用共同资源而造成的干扰。一个应用程序可以有多个绿色上下文。
使用绿色上下文无需更改任何 GPU 代码(核函数),只需在主机端进行少量更改(例如,创建绿色上下文并为此绿色上下文创建流)。绿色上下文功能在多种场景中都很有用。例如,在没有其他约束的前提下,它可以帮助确保始终有一些 SM 可供延迟敏感的核函数开始执行,或者提供一种无需修改任何核函数即可快速测试使用较少 SM 的效果的方法。
绿色上下文支持最初通过CUDA 驱动程序 API提供。从 CUDA 13.1 开始,CUDA 运行时通过执行上下文(EC)抽象来暴露上下文。目前,执行上下文可以对应于主上下文(运行时 API 用户一直隐式与之交互的上下文),也可以对应于绿色上下文。本节在指代绿色上下文时,将交替使用执行上下文和绿色上下文这两个术语。
随着绿色上下文在运行时中暴露,强烈建议直接使用 CUDA 运行时 API。本节也将仅使用 CUDA 运行时 API。
启动 CUDA 核函数时,用户无法直接控制该核函数将在多少个 SM 上执行。只能通过更改核函数的启动几何配置,或更改任何可能影响该核函数在每个 SM 上的最大活跃线程块数的因素,来间接影响这一点。此外,当多个核函数在 GPU 上并行执行时(核函数在不同的 CUDA 流中运行,或作为 CUDA 图的一部分运行),它们也可能争用相同的 SM 资源。
然而,在某些使用场景中,用户需要确保始终有可用的 GPU 资源,使延迟敏感的工作能够尽快开始,并由此尽快完成。绿色上下文通过对 SM 资源进行分区,提供了一种实现这一目标的方法,因此,给定的绿色上下文只能使用特定的 SM(即在创建该上下文时为其配置的那些 SM)。
图 45展示了这样一个示例。假设有一个应用程序,其中两个独立的核函数 A 和 B 在两个不同的非阻塞 CUDA 流上运行。核函数 A 先启动,并开始执行,占用所有可用的 SM 资源。随后,当延迟敏感的核函数 B 启动时,已没有可用的 SM 资源。因此,核函数 B 只能在核函数 A 逐渐结束,即核函数 A 中的线程块完成执行后,才能开始执行。第一幅图展示了关键工作 B 被延迟的这一场景。y 轴表示被占用的 SM 的百分比,x 轴表示时间。
图 45 动机:绿色上下文(GC)的静态资源分区使延迟敏感的工作 B 能够更早开始和完成
图内文字中文对照
Critical work B gets delayed
关键工作 B 被延迟
GPU utilization (%)
GPU 利用率(%)
independent + critical work B launched
启动独立且关键的工作 B
No resources available.
无可用资源。
time
时间
Work B complete
工作 B 完成
kernel A
核函数 A
kernel B (time critical)
核函数 B(时间关键)
Using 2 green contexts with 80% - 20% SM split
使用 2 个绿色上下文,按 80% - 20% 划分流式多处理器
At most 20%
最多 20%
At most 80%
最多 80%
使用绿色上下文,可以对 GPU 的 SM 进行分区,使核函数 A 所面向的绿色上下文 A 能够访问 GPU 的一部分 SM,而核函数 B 所面向的绿色上下文 B 能够访问其余 SM。在此设置下,无论核函数 A 的启动配置如何,它都只能使用为绿色上下文 A 配置的 SM。因此,当关键核函数 B 启动时,只要没有其他资源限制,就能保证有可用的 SM 供其立即开始执行。正如图 45中的第二幅图所示,尽管核函数 A 的持续时间可能增加,但延迟敏感的工作 B 将不再因没有可用的 SM 而被延迟。为了便于说明,图中为绿色上下文 A 配置的 SM 数量相当于 GPU 的 SM 总数的 80%。
无需对核函数 A 和 B 的代码进行任何修改,就可以实现这种行为。只需确保它们在属于相应绿色上下文的 CUDA 流上启动即可。每个绿色上下文能够访问的 SM 数量应由用户在创建绿色上下文时根据具体情况决定。
在前一个示例的基础上,假设工作 B 与工作 A 映射到同一个工作队列。在这种情况下,即使有可用的 SM 资源(绿色上下文的情况),工作 B 仍可能需要等待工作 A 全部完成。与 SM 类似,用户无法直接控制底层可能使用的具体工作队列。但是,绿色上下文允许用户通过预期的并发流有序工作负载数量,表达其期望的最大并发度。驱动程序随后可以将此值用作提示,尝试避免来自不同执行上下文的工作使用同一个或同一组工作队列,从而防止执行上下文之间出现不必要的干扰。
注意
即使为每个绿色上下文配置了不同的 SM 资源和工作队列,也不能保证独立的 GPU 工作能够并发执行。最好将绿色上下文一节中介绍的所有技术理解为消除可能阻止并发执行的因素(即减少潜在干扰)。
但是,使用 MIG 无法解决前面描述的问题场景,即由于同一应用程序中的其他 GPU 工作占用了所有 SM 资源,关键工作 B 被延迟。对于在单个 MIG 实例上运行的应用程序,这一问题仍可能存在。为解决此问题,可以将绿色上下文与 MIG 一起使用。在这种情况下,可用于分区的 SM 资源将是给定 MIG 实例的资源。
MPS 主要面向不同的进程(例如 MPI 程序),使它们无需时间分片就能同时在 GPU 上运行。它要求 MPS 守护进程在应用程序启动之前就已运行。默认情况下,MPS 客户端将争用其所运行的 GPU 或 MIG 实例的所有可用 SM 资源。在这种具有多个客户端进程的设置中,MPS 可以使用活动线程百分比选项支持 SM 资源的动态分区,该选项对 MPS 客户端进程可使用的 SM 百分比设置上限。与绿色上下文不同,MPS 中的活动线程百分比分区是在进程级别进行的,并且该百分比通常在应用程序启动之前通过环境变量指定。MPS 活动线程百分比表示,给定客户端应用程序使用的 SM 不得超过 GPU 的 SM 总数的x%,设此数量为 N 个 SM。然而,这些 SM 可以是 GPU 上的任意 N 个 SM,并且也可以随时间变化。另一方面,在创建时配置了 N 个 SM 的绿色上下文只能使用这 N 个特定的 SM。
从 CUDA 13.1 开始,如果在启动 MPS 控制守护进程时显式启用静态分区,MPS 也支持静态分区。使用静态分区时,用户必须在应用程序启动时指定 MPS 客户端进程可以使用的静态分区。在这种情况下,使用活动线程百分比的动态共享不再适用。静态分区模式下的 MPS 与绿色上下文之间的一个关键区别在于,MPS 面向不同的进程,而绿色上下文也适用于单个进程内部。此外,与绿色上下文不同,使用静态分区的 MPS 不允许超额订阅 SM 资源。
使用 MPS 时,对于通过cuCtxCreate驱动程序 API 创建并具有执行亲和性的 CUDA 上下文,还可以通过编程方式对 SM 资源进行分区。这种编程式分区允许来自一个或多个进程的不同客户端 CUDA 上下文各自使用不超过指定数量的 SM。与活动线程百分比分区一样,这些 SM 可以是 GPU 上的任意 SM,并且可以随时间变化,这与绿色上下文的情况不同。即使存在静态 MPS 分区,也可以使用此选项。请注意,与 MPS 上下文相比,创建绿色上下文要轻量得多,因为许多底层结构由主上下文拥有,因而是共享的。
4.6.2. 绿色上下文:易用性
为了突出绿色上下文的易用性,假设您有以下代码片段,它创建两个 CUDA 流,然后调用一个函数,通过<<<>>>在这些 CUDA 流上启动核函数。如前所述,除了更改核函数的启动几何配置之外,无法影响这些核函数可以使用的 SM 数量。
intgpu_device_index=0;// GPU ordinalCUDA_CHECK(cudaSetDevice(gpu_device_index));cudaStream_tstrm1,strm2;CUDA_CHECK(cudaStreamCreateWithFlags(&strm1,cudaStreamNonBlocking));CUDA_CHECK(cudaStreamCreateWithFlags(&strm2,cudaStreamNonBlocking));// No control over how many SMs kernel(s) running on each stream can usecode_that_launches_kernels_on_streams(strm1,strm2);// what is abstracted in this function + the kernels is the vast majority of your code// cleanup code not shown
从 CUDA 13.1 开始,可以使用绿色上下文控制给定核函数能够访问的 SM 数量。下面的代码片段展示了实现这一点有多么简单。只需增加几行代码,而无需对核函数进行任何修改,就可以控制在这些不同流上启动的核函数能够使用的 SM 资源。
intgpu_device_index=0;// GPU ordinalCUDA_CHECK(cudaSetDevice(gpu_device_index));/* ------------------ Code required to create green contexts --------------------------- */// Get all available GPU SM resourcescudaDevResourceinitial_GPU_SM_resources{};CUDA_CHECK(cudaDeviceGetDevResource(gpu_device_index,&initial_GPU_SM_resources,cudaDevResourceTypeSm));// Split SM resources. This example creates one group with 16 SMs and one with 8. Assuming your GPU has >= 24 SMscudaDevSmResourceresult[2]{{},{}};cudaDevSmResourceGroupParamsgroup_params[2]={{.smCount=16,.coscheduledSmCount=0,.preferredCoscheduledSmCount=0,.flags=0},{.smCount=8,.coscheduledSmCount=0,.preferredCoscheduledSmCount=0,.flags=0}};CUDA_CHECK(cudaDevSmResourceSplit(&result[0],2,&initial_GPU_SM_resources,nullptr,0,&group_params[0]));// Generate resource descriptors for each resourcecudaDevResourceDesc_tresource_desc1{};cudaDevResourceDesc_tresource_desc2{};CUDA_CHECK(cudaDevResourceGenerateDesc(&resource_desc1,&result[0],1));CUDA_CHECK(cudaDevResourceGenerateDesc(&resource_desc2,&result[1],1));// Create green contextscudaExecutionContext_tmy_green_ctx1{};cudaExecutionContext_tmy_green_ctx2{};CUDA_CHECK(cudaGreenCtxCreate(&my_green_ctx1,resource_desc1,gpu_device_index,0));CUDA_CHECK(cudaGreenCtxCreate(&my_green_ctx2,resource_desc2,gpu_device_index,0));/* ------------------ Modified code --------------------------- */// You just need to use a different CUDA API to create the streamscudaStream_tstrm1,strm2;CUDA_CHECK(cudaExecutionCtxStreamCreate(&strm1,my_green_ctx1,cudaStreamDefault,0));CUDA_CHECK(cudaExecutionCtxStreamCreate(&strm2,my_green_ctx2,cudaStreamDefault,0));/* ------------------ Unchanged code --------------------------- */// No need to modify any code in this function or in your kernel(s).// Reminder: what is abstracted in this function + kernels is the vast majority of your code// Now kernel(s) running on stream strm1 will use at most 16 SMs and kernel(s) on strm2 at most 8 SMs.code_that_launches_kernels_on_streams(strm1,strm2);// cleanup code not shown
各种执行上下文 API(其中一些已在前面的示例中展示)接受显式的cudaExecutionContext_t句柄,因此会忽略调用线程的当前上下文。在此之前,不使用驱动程序 API 的 CUDA 运行时用户默认情况下只会与主上下文交互,该主上下文通过cudaSetDevice()被隐式设置为线程的当前上下文。转向这种基于显式上下文的编程方式,可以提供更易于理解的语义,并且相比于此前依赖线程局部状态(TLS)的基于隐式上下文的编程方式,还可以带来其他好处。
可以分别使用cudaExecutionCtxGetDevResource和cudaStreamGetDevResource API,查询给定执行上下文或 CUDA 流是否与给定类型的cudaDevResource资源相关联。执行上下文也可以与不同类型的设备资源(例如 SM 和工作队列)相关联,而流只能与 SM 类型的资源相关联。
默认情况下,给定 GPU 设备具有全部三种设备资源类型:包含 GPU 上所有 SM 的 SM 类型资源、包含所有可用工作队列的工作队列配置资源,以及其对应的工作队列资源。可以通过cudaDeviceGetDevResource API 获取这些资源。
相关设备资源结构体概述
不同资源类型的结构体具有由用户显式设置或由相关 CUDA API 调用设置的字段。建议对所有设备资源结构体进行零初始化。
SM 类型的设备资源(cudaDevSmResource)具有以下相关字段:
unsignedintsmCount:此资源中可用的 SM 数量
unsignedintminSmPartitionSize:对此资源进行分区所需的最小 SM 数量
unsignedintsmCoscheduledAlignment:资源中保证被协同调度到同一个 GPU 处理簇上的 SM 数量,这与线程块簇有关。当flags为零时,smCount是此值的倍数。
上述字段将通过用于创建此 SM 类型资源的相应拆分 API(cudaDevSmResourceSplitByCount或cudaDevSmResourceSplit)来设置,或由获取给定 GPU 设备的 SM 资源的cudaDeviceGetDevResource API 填充。用户绝不应直接设置这些字段。有关更多详细信息,请参阅下一节。
这些 API 都允许使用所有有效的cudaDevResourceType类型,但cudaStreamGetDevResource除外,它仅支持 SM 类型的资源。
通常,起点是 GPU 设备。下面的代码片段展示了如何获取给定 GPU 设备的可用 SM 资源。成功调用cudaDeviceGetDevResource后,用户可以查看此资源中可用的 SM 数量。
intcurrent_device=0;// assume device ordinal of 0CUDA_CHECK(cudaSetDevice(current_device));cudaDevResourceinitial_SM_resources={};CUDA_CHECK(cudaDeviceGetDevResource(current_device/* GPU device */,&initial_SM_resources/* device resource to populate */,cudaDevResourceTypeSm/* resource type*/));std::cout<<"Initial SM resources: "<<initial_SM_resources.sm.smCount<<" SMs"<<std::endl;// number of available SMs// Special fields relevant for partitioning (see Step 3 below)std::cout<<"Min. SM partition size: "<<initial_SM_resources.sm.minSmPartitionSize<<" SMs"<<std::endl;std::cout<<"SM co-scheduled alignment: "<<initial_SM_resources.sm.smCoscheduledAlignment<<" SMs"<<std::endl;
创建绿色上下文的第二步是将可用的cudaDevResourceSM 资源静态拆分为一个或多个分区,可能会有一些 SM 留在一个剩余分区中。可以使用cudaDevSmResourceSplitByCount()或cudaDevSmResourceSplit()API 进行这种划分。cudaDevSmResourceSplitByCount()API 只能创建一个或多个同构分区,以及一个可能存在的剩余分区,而cudaDevSmResourceSplit()API 还可以创建异构分区,以及一个可能存在的剩余分区。后续各节将详细介绍这两个 API 的功能。这两个 API 都仅适用于 SM 类型的设备资源。
图 46 使用 cudaDevSmResourceSplitByCount API 拆分 SM 资源
图内文字中文对照
input cudaDevResource
输入 cudaDevResource
split into *nbGroups partitions
划分为 *nbGroups 个分区
N SMs
N 个流式多处理器
remaining SMs
剩余流式多处理器
remaining
剩余部分
result
结果
表 30列出了在默认useFlags=0情况下,所有当前支持的计算能力的最小 SM 分区大小以及 SM 协同调度的对齐要求。还可以通过cudaDevSmResource的minSmPartitionSize和smCoscheduledAlignment字段获取这些值,如步骤 1:获取可用的 GPU 资源所示。通过使用不同的useFlags值,可以降低其中一些要求。表 14提供了一些相关示例,突出展示了请求与最终结果之间的差异,并附有说明。该表重点介绍计算能力(CC 9.0),在该计算能力下,如果useFlags为零,则每个分区的 SM 数量最少为 8,且 SM 数量必须是 8 的倍数。
表 14 拆分功能
请求的结果
实际结果(对于具有 132 个 SM 的 GH200)
*nbGroups
minCount
useFlags
*nbGroupswithNSMs
剩余 SM
原因
2
72
0
1 组,包含 72 个 SM
60
不能超过 132 个 SM
6
11
0
6 组,每组包含 16 个 SM
36
必须为 8 的倍数的要求
6
11
CU_DEV_SM_RESOURCE_SPLIT_IGNORE_SM_COSCHEDULING
6 组,每组包含 12 个 SM
60
要求降低为必须是 2 的倍数
2
1
0
2 组,每组包含 8 个 SM
116
至少包含 8 个 SM 的要求
以下代码片段请求将可用的 SM 资源拆分为五组,每组包含8 个 SM:
cudaDevResourceavail_resources={};// Code that has populated avail_resources not shownunsignedintmin_SM_count=8;unsignedintactual_split_groups=5;// may be updatedcudaDevResourceactual_split_result[5]={{},{},{},{},{}};cudaDevResourceremaining_partition={};CUDA_CHECK(cudaDevSmResourceSplitByCount(&actual_split_result[0],&actual_split_groups,&avail_resources,&remaining_partition,0/*useFlags */,min_SM_count));std::cout<<"Split "<<avail_resources.sm.smCount<<" SMs into "<<actual_split_groups<<" groups "\
<<"with "<<actual_split_result[0].sm.smCount<<" each "\
<<"and a remaining group with "<<remaining_partition.sm.smCount<<" SMs"<<std::endl;
如前所述,单次cudaDevSmResourceSplitByCountAPI 调用只能创建同构分区,即具有相同 SM 数量的分区,以及剩余分区。这可能会限制异构工作负载,在这类工作负载中,在不同绿色上下文上运行的工作对 SM 数量有不同的要求。要使用按数量拆分的 API 实现异构分区,通常需要通过(多次)重复步骤 1 至 4 来重新划分现有资源。或者,在某些情况下,可以在步骤 2 中创建同构分区,使每个分区的 SM 数量等于所有异构分区 SM 数量的 GCD(最大公约数),然后在步骤 3 中将所需数量的这些分区合并在一起。不过,不建议采用后一种方法,因为如果一开始就请求较大的分区大小,CUDA 驱动程序可能能够创建更好的分区。
cudaDevSmResourceSplitAPI 旨在解决这些限制,它允许用户在单次调用中创建不重叠的异构分区。cudaDevSmResourceSplit运行时 API 的签名为:
此 API 将尝试根据groupParams数组中为每个资源指定的要求,将inputSM 类型资源划分为nbGroups个有效设备资源(组),并将其放入result数组中。也可以选择创建一个剩余分区。拆分成功后,如图 47所示,result中的每个资源可以具有不同数量的 SM,但 SM 数量绝不会为零。
图 47 使用 cudaDevSmResourceSplit API 拆分 SM 资源
图内文字中文对照
input cudaDevResource
输入 cudaDevResource
split into nbGroups partitions
划分为 nbGroups 个分区
X SMs
X 个流式多处理器
Y SMs
Y 个流式多处理器
Z SMs
Z 个流式多处理器
remaining SMs
剩余流式多处理器
remaining
剩余部分
result
结果
请求异构拆分时,需要为result中的每个资源指定 SM 数量(相应groupParams条目的smCount字段)。此 SM 数量应始终为 2 的倍数。对于上一幅图中的情形,groupParams[0].smCount将为X,groupParams[1].smCount将为Y,依此类推。但是,如果应用程序使用线程块簇,仅指定 SM 数量是不够的。由于一个簇中的所有线程块都保证会被协同调度,因此用户还需要指定给定资源组应支持的最大簇大小(如果支持簇)。这可以通过相应groupParams条目的coscheduledSmCount字段实现。对于计算能力为 10.0 及更高版本(CC 10.0+)的 GPU,簇还可以具有首选维度,该维度是其默认簇维度的倍数。在受支持系统上的单次核函数启动期间,如果能够使用这个较大的首选簇维度,就会尽可能使用它,否则使用较小的默认簇维度。用户可以通过相应groupParams条目的preferredCoscheduledSmCount字段表达此首选簇维度提示。最后,在某些情况下,用户可能希望放宽 SM 数量要求,将更多可用的 SM 纳入给定组中;用户可以将相应groupParams条目的flags字段设置为其非默认标志值,来表达此回填选项。
此 API 允许一个组以某个局部性域为目标。在cudaDevSmResourceGroupParams.flags字段中设置cudaDevSmResourceGroupLocalityDomainId,并将cudaDevSmResourceGroupParams.localityDomainId设置为该资源的有效局部性域 ID。随后,cudaDevSmResourceSplit会从该局部性域中选择 SM。如果还设置了cudaDevSmResourceGroupBackfill,CUDA 可能会在优先使用目标域之后,使用来自所请求局部性域之外的 SM 填充该组。
result!=nullptr:只有在拆分成功且已创建nbGroups个满足指定要求的有效cudaDevResource组时,此 API 才会返回cudaSuccess;否则,它将返回错误。由于不同类型的错误可能返回相同的错误代码(例如cudaErrorInvalidResourceConfiguration),因此建议在开发期间使用CUDA_LOG_FILE环境变量来获取更详尽的错误描述。
result==nullptr:即使某个组产生的smCount为零,此 API 也可能返回cudaSuccess,而在result不为 nullptr 时,这种情况会返回错误。可以将此模式视为探索所支持功能时可使用的试运行测试,尤其是在发现模式下。
当 result != nullptr 且调用成功时,产生的result[i]设备资源(其中 i 位于[0,nbGroups)中)将具有cudaDevResourceTypeSm类型,并具有一个result[i].sm.smCount,其值将是用户指定的非零groupParams[i].smCount值或发现的值。无论哪种情况,result[i].sm.smCount都将满足以下全部约束:
将coscheduledSmCount和preferredCoscheduledSmCount字段中的任意一个指定为零,表示应使用该字段的默认值;这些默认值可能因 GPU 而异。这两个默认值都等于通过cudaDeviceGetDevResourceAPI 为给定设备获取的 SM 资源的smCoscheduledAlignment(而不是任意 SM 资源的该值)。要查看这些默认值,可以先将它们设置为 0,然后在成功调用cudaDevSmResourceSplit后,检查相应groupParams条目中它们更新后的值;请参阅下文。
intgpu_device_index=0;cudaDevResourceinitial_GPU_SM_resources{};CUDA_CHECK(cudaDeviceGetDevResource(gpu_device_index,&initial_GPU_SM_resources,cudaDevResourceTypeSm));std::cout<<"Default value will be equal to "<<initial_GPU_SM_resources.sm.smCoscheduledAlignment<<std::endl;intdefault_split_flags=0;cudaDevSmResourceGroupParamsgroup_params_tmp={.smCount=0,.coscheduledSmCount=0,.preferredCoscheduledSmCount=0,.flags=0};CUDA_CHECK(cudaDevSmResourceSplit(nullptr,1,&initial_GPU_SM_resources,nullptr/*remainder*/,default_split_flags,&group_params_tmp));std::cout<<"coscheduledSmcount default value: "<<group_params.coscheduledSmCount<<std::endl;std::cout<<"preferredCoscheduledSmcount default value: "<<group_params.preferredCoscheduledSmCount<<std::endl;
intnbGroups=2;// update as neededunsignedintdefault_split_flags=0;cudaDevResourceremainder{};// update as neededcudaDevResourceresult_use_case[2]={{},{}};// Update depending on number of groups planned. Increase size if you plan to also use a workqueue resourcecudaDevSmResourceGroupParamsgroup_params_use_case[2]={{.smCount=X,.coscheduledSmCount=0,.preferredCoscheduledSmCount=0,.flags=0},{.smCount=Y,.coscheduledSmCount=0,.preferredCoscheduledSmCount=0,.flags=0}}CUDA_CHECK(cudaDevSmResourceSplit(&result_use_case[0],nbGroups,&initial_GPU_SM_resources,remainder,default_split_flags,&group_params_use_case[0]));
用作给驱动程序的提示,使其在可能的情况下尝试将每组实际包含coscheduledSmCount个 SM 的组,合并为包含preferredCoscheduledSmCount个 SM 的更大组。这样可以让代码利用计算能力(CC)为 10.0 及更高版本的设备上提供的首选簇维度功能)。请参阅cudaLaunchAttributeValue::preferredClusterDim。
cudaDevResourcesplit_result[2]={{},{}};// code to populate split_result[0] not shown; used split API with nbGroups=1// The last resource will be a workqueue resource.split_result[1].type=cudaDevResourceTypeWorkqueueConfig;split_result[1].wqConfig.device=0;// assume device ordinal of 0split_result[1].wqConfig.sharingScope=cudaDevWorkqueueConfigScopeGreenCtxBalanced;split_result[1].wqConfig.wqConcurrencyLimit=4;
cudaDevResourceactual_split_result[5]={};// code to populate actual_split_result not shown// Generate resource desc. to encapsulate 3 resources: actual_split_result[2] to [4]cudaDevResourceDesc_tresource_desc;CUDA_CHECK(cudaDevResourceGenerateDesc(&resource_desc,&actual_split_result[2],3));
也支持组合不同类型的资源。例如,可以生成一个同时包含 SM 资源和工作队列资源的描述符。
要使cudaDevResourceGenerateDesc调用成功,需满足以下条件:
所有nbResources资源都应属于同一 GPU 设备。
如果组合多个 SM 类型的资源,它们应由同一次拆分 API 调用生成,并具有相同的coscheduledSmCount值(如果不属于剩余部分)
flags参数应设置为 0。此外,建议在创建绿色上下文之前,通过cudaInitDevice API 或cudaSetDevice API 显式初始化设备的主上下文,这也会将主上下文设置为调用线程的当前上下文。这样可确保在创建绿色上下文期间不会产生额外的主上下文初始化开销。
请参见下面的代码片段。
intcurrent_device=0;// assume single GPUCUDA_CHECK(cudaSetDevice(current_device));// Or cudaInitDevicecudaDevResourceDesc_tresource_desc{};// Code to generate resource_desc not shown// Create a green_ctx on GPU with current_device ID with access to resources from resource_desccudaExecutionContext_tgreen_ctx{};CUDA_CHECK(cudaGreenCtxCreate(&green_ctx,resource_desc,current_device,0));
不过,SM 超额订阅也是可能的,并且在某些情况下可以使用。例如,让第二个绿色上下文的描述符封装 actual_split_result[0] 到 [2] 可能是可以接受的。在这种情况下,actual_split_resource[2]cudaDevResource的所有 SM 都将被超额订阅,即为两个绿色上下文同时配置,而资源 actual_split_resource[0] 到 [1] 以及 actual_split_resource[3] 到 [4] 只能由这两个绿色上下文之一使用。应根据具体情况审慎使用 SM 超额订阅。
4.6.5. 绿色上下文:启动工作
要针对使用前述步骤创建的绿色上下文启动核函数,首先需要通过cudaExecutionCtxStreamCreate API 为该绿色上下文创建一个流。使用<<<>>>或cudaLaunchKernel API 在该流上启动核函数,将确保核函数只能使用通过该流的执行上下文向其提供的资源(SM、工作队列)。例如:
// Create green_ctx_stream CUDA stream for previously created green_ctx green contextcudaStream_tgreen_ctx_stream;intpriority=0;CUDA_CHECK(cudaExecutionCtxStreamCreate(&green_ctx_stream,green_ctx,cudaStreamDefault,priority));// Kernel my_kernel will only use the resources (SMs, work queues, as applicable) available to green_ctx_stream's execution contextmy_kernel<<<grid_dim,block_dim,0,green_ctx_stream>>>();CUDA_CHECK(cudaGetLastError());
鉴于green_ctx是绿色上下文,传递给上述流创建 API 的默认流创建标志等同于cudaStreamNonBlocking。
CUDA 图
对于作为 CUDA 图的一部分启动的核函数(参见CUDA 图),还有一些细微之处需要注意。与核函数不同,启动 CUDA 图所用的 CUDA 流并不决定所使用的 SM 资源,因为该流仅用于依赖关系跟踪。
核函数节点(以及其他适用的节点类型)将在哪个执行上下文上执行,是在创建节点时设置的。如果将使用流捕获来创建 CUDA 图,那么参与捕获的流的执行上下文将决定相关图节点的执行上下文。如果将使用图 API 来创建图,那么用户应为每个相关节点显式设置执行上下文。例如,要添加核函数节点,用户应使用多态cudaGraphAddNode API,将节点类型指定为cudaGraphNodeTypeKernel,并显式指定.kernel下的cudaKernelNodeParamsV2结构体的.ctx字段。cudaGraphAddKernelNode不允许用户指定执行上下文,因此应避免使用。请注意,同一图中的不同图节点可以属于不同的执行上下文。
要以编程方式进行验证,可以考虑使用 CUDA 驱动程序 APIcuGraphKernelNodeGetParams(graph_node,&node_params),并将node_params.ctx上下文句柄字段与该图节点的预期上下文句柄进行比较。由于CUgraphNode和cudaGraphNode_t可以互换使用,因此可以使用驱动程序 API,但用户需要包含相关的cuda.h头文件,并直接链接驱动程序(-lcuda)。
线程块簇
包含线程块簇的核函数(参见第 1.2.2.1.1 节)也可以像其他任何核函数一样,在绿色上下文流上启动,从而使用为该绿色上下文配置的资源。第 4.6.4.2 节展示了如何在拆分设备资源时指定需要协同调度的 SM 数量,以便支持簇。不过,与任何使用簇的核函数一样,用户应利用相关的占用率 API 来确定核函数的最大潜在簇大小(通过cudaOccupancyMaxPotentialClusterSize),并在需要时确定最大活跃簇数(cudaOccupancyMaxActiveClusters)。如果用户将绿色上下文流指定为相关cudaLaunchConfig的stream字段,则这些占用率 API 会将为该绿色上下文配置的 SM 资源纳入考虑。这一用例尤其适用于可能由用户传入绿色上下文 CUDA 流的库,以及使用剩余设备资源创建绿色上下文的情况。
下面的代码片段展示了如何使用这些 API。
// Assume cudaStream_t gc_stream has already been created and a __global__ void cluster_kernel exists.// Uncomment to support non portable cluster size, if possible// CUDA_CHECK(cudaFuncSetAttribute(cluster_kernel, cudaFuncAttributeNonPortableClusterSizeAllowed, 1))cudaLaunchConfig_tconfig={0};config.gridDim=grid_dim;// has to be a multiple of cluster dim.config.blockDim=block_dim;config.dynamicSmemBytes=expected_dynamic_shared_mem;cudaLaunchAttributeattribute[1];attribute[0].id=cudaLaunchAttributeClusterDimension;attribute[0].val.clusterDim.x=1;attribute[0].val.clusterDim.y=1;attribute[0].val.clusterDim.z=1;config.attrs=attribute;config.numAttrs=1;config.stream=gc_stream;// Need to pass the CUDA stream that will be used for that kernelintmax_potential_cluster_size=0;// the next call will ignore cluster dims in launch configCUDA_CHECK(cudaOccupancyMaxPotentialClusterSize(&max_potential_cluster_size,cluster_kernel,&config));std::cout<<"max potential cluster size is "<<max_potential_cluster_size<<" for CUDA stream gc_stream"<<std::endl;// Could choose to update launch config's clusterDim with max_potential_cluster_size.// Doing so would result in a successful cudaLaunchKernelEx call for the same kernel and launch config.intnum_clusters=0;CUDA_CHECK(cudaOccupancyMaxActiveClusters(&num_clusters,cluster_kernel,&config));std::cout<<"Potential max. active clusters count is "<<num_clusters<<std::endl;
例如,在属于不同绿色上下文的 CUDA 流上启动的核函数,将显示在Nsight Systems报告的 CUDA 硬件时间线部分下不同的绿色上下文行中。Nsight Compute在其会话页面中提供绿色上下文资源概览,并在详细信息部分的启动统计信息下提供更新后的SM 数量。前者提供已配置资源的可视化位掩码。如果应用程序使用不同的绿色上下文,这一点尤其有用,因为用户可以确认不同 GC 之间的重叠情况是否符合预期(没有重叠,或者在 SM 被超额订阅时存在预期的非零重叠)。
图 48以一个示例描绘了这些资源,其中有两个绿色上下文,分别配置了 112 个和 16 个 SM,彼此之间没有 SM 重叠。所提供的视图可以帮助用户验证为每个绿色上下文配置的 SM 资源数量。它还有助于确认没有任何 SM 被超额订阅,因为没有任何方框在两个绿色上下文中都被标记为绿色(表示为该 GC 配置)。
图 48Nsight Compute 中的绿色上下文资源部分
图内文字中文对照
Green Context Resources
绿色上下文资源
Overview of all Green Contexts with their respective resources included in the report.
报告中包含的所有绿色上下文及其各自资源的概览。
Green Context ID
绿色上下文 ID
Result IDs
结果 ID
# TPCs
TPC 数量
Enabled TPCs
已启用的 TPC
启动统计信息部分还显式列出了为该绿色上下文配置的 SM 数量,因此这些 SM 可供该核函数使用。请注意,这些是给定核函数在执行期间可以访问的 SM,而不是该核函数实际运行所用的 SM 数量。前面展示的资源概览也是如此。核函数实际使用的 SM 数量可能取决于多种因素,包括核函数本身(启动的几何配置等)、同时在 GPU 上运行的其他工作等。
4.6.6. 其他执行上下文 API
本节简要介绍一些其他绿色上下文 API。有关完整列表,请参阅 CUDA 运行时 API 的相关章节。
要使用 CUDA 事件进行同步,可以利用cudaError_tcudaExecutionCtxRecordEvent(cudaExecutionContext_tctx,cudaEvent_tevent)和cudaError_tcudaExecutionCtxWaitEvent(cudaExecutionCtxWaitEvent(cudaExecutionContext_tctx,cudaEvent_tevent) API。cudaExecutionCtxRecordEvent记录一个 CUDA 事件,捕获指定执行上下文在此调用时的所有工作/活动,而cudaExecutionCtxWaitEvent则使今后提交到该执行上下文的所有工作等待指定事件中捕获的工作。
如果执行上下文具有多个 CUDA 流,使用cudaExecutionCtxRecordEvent比cudaEventRecord更方便。若不使用此执行上下文 API 而要实现等效行为,则需要在该执行上下文的每个流上通过cudaEventRecord记录一个单独的 CUDA 事件,然后让依赖这些工作的工作分别等待所有这些事件。同样,如果需要该执行上下文的所有流等待某个事件完成,则cudaExecutionCtxWaitEvent比cudaStreamWaitEvent更方便。替代方法是为此执行上下文中的每个流分别调用cudaStreamWaitEvent。
要在 CPU 端进行阻塞同步,可以使用cudaError_tcudaExecutionCtxSynchronize(cudaExecutionContext_tctx)。此调用将一直阻塞,直到指定的执行上下文完成其所有工作。如果指定的执行上下文不是通过cudaGreenCtxCreate创建的,而是通过cudaDeviceGetExecutionCtx获取的,因此是设备的主上下文,则调用该函数还将同步在同一设备上创建的所有绿色上下文。
最后,可以通过cudaError_tcudaExecutionCtxDestroy(cudaExecutionContext_tctx) API 销毁显式创建的执行上下文。
4.6.7. 绿色上下文示例
本节说明绿色上下文如何使关键工作更早开始和完成。与第 4.6.1 节中使用的场景类似,该应用程序有两个核函数,将在两个不同的非阻塞 CUDA 流上运行。从 CPU 端来看,时间线如下。首先在 CUDA 流strm1上启动一个长时间运行的核函数(delay_kernel_us),它在整个 GPU 上需要多个波次才能完成。然后,在短暂等待(短于该核函数的持续时间)之后,在流strm2上启动一个持续时间较短但很关键的核函数(critical_kernel)。测量这两个核函数的 GPU 持续时间以及从 CPU 启动到完成的时间。
使用一个延迟核函数来代替长时间运行的核函数,其中每个线程块运行固定的微秒数,并且线程块数量超过 GPU 可用的 SM 数量。
起初不使用绿色上下文,但关键核函数会在优先级高于长时间运行的核函数所用流的 CUDA 流上启动。由于其流具有较高优先级,长时间运行的核函数的某些线程块一旦完成,关键核函数就可以开始执行。但是,它仍然需要等待一些可能长时间运行的线程块完成,这将推迟其开始执行的时间。
为了利用绿色上下文功能,创建了两个绿色上下文,并为每个上下文配置了一组彼此独立、互不重叠的 SM。在本例中,为了便于说明,对具有 132 个 SM 的 H100 采用的具体 SM 拆分方式是:为关键核函数(绿色上下文 3)配置 16 个 SM,为长时间运行的核函数(绿色上下文 2)配置 112 个 SM。如图 50所示,关键核函数现在几乎可以立即开始,因为有一些 SM 只能由绿色上下文 3 使用。
与单独运行时的持续时间相比,短核函数的持续时间可能会增加,因为它现在可使用的 SM 数量受到了限制。长时间运行的核函数也是如此,它无法再使用 GPU 的所有 SM,而是受到其绿色上下文所配置资源的约束。不过,关键结果在于,与之前相比,关键核函数的工作现在可以显著更早地开始和完成。这是在没有其他任何限制的前提下而言的,因为如前所述,无法保证并行执行。
图 50使用绿色上下文时的 Nsight Systems 时间线
图内文字中文对照
Timeline View
时间线视图
Options...
选项
0.1% Stream 15
0.1% 流 15
22.1% Green Context 2
22.1% 绿色上下文 2
0.2% Green Context 3
0.2% 绿色上下文 3
100.0% Kernels
100.0% 核函数
Threads (9)
线程(9)
OS runtime libraries
操作系统运行时库
~12ms duration (+2ms from before)
持续时间约 12 毫秒(比之前增加 2 毫秒)
~95us duration; almost no lost time!
持续时间约 95 微秒;几乎没有时间损失!
delay_kernel launch
启动 delay_kernel
critical_kernel launch
启动 critical_kernel
在所有情况下,都应在实验之后,根据具体情况决定确切的 SM 拆分方式。
4.7. 局部性域
局部性域是 GPU 的一部分,其中包含流式多处理器(SM)和设备内存。应用程序可以在某个局部性域中分配设备内存,并创建一个具有同一局部性域中 SM 资源的绿色上下文。将计算放置在其所访问的内存附近,可以提高具有多个局部性域的设备上的性能。计算局部化 API 在计算资源局部化中介绍,内存局部化在分配局部化设备内存中介绍。
CUDA 通过从零开始的局部性域 ID标识设备的局部性域。局部性域 ID 只有与其设备 ID 结合使用时才有意义。对 SM 资源和内存进行局部化时使用相同的 ID,使应用程序能够请求将两者放置在匹配的位置。
4.7.1. 发现局部性域
使用cudaDeviceGetAttribute,并指定以下cudaDeviceAttr值:
cudaDevAttrLocalityDomainCount返回设备上的局部性域数量。
cudaDevAttrLocalityDomainMultiprocessorCount返回每个局部性域中的 SM 数量。
应用程序应查询这些属性,而不是假定某种特定的拓扑结构。设备上可用的局部性域数量受系统配置影响。在不同情形下,相同类型的设备可能呈现不同数量的局部性域(第 4.7.5.3 节)。所有设备,包括仅有一个可用局部性域的设备,都可以使用局部性域 API。在仅有一个局部性域的设备上,这些 API 与面向整个设备的操作相同。使用设备属性以编程方式查询设备的局部性域属性:
典型的绿色上下文创建过程在第 4.6.2 节中介绍。为使 SM 资源局部化而必须添加的内容如下所示:
要描述局部化 SM 组,请在flags中设置cudaDevSmResourceGroupLocalityDomainId,并在localityDomainId中设置 ID。有效 ID 介于0和cudaDevAttrLocalityDomainCount-1之间。
cudaDevResourcesmResource;cudaDeviceGetDevResource(device,&smResource,cudaDevResourceTypeSm);{cudaDevSmResourceGroupParamsparams={};// all fields in params must be zero-initializedparams.flags=cudaDevSmResourceGroupLocalityDomainId;params.localityDomainId=localityDomainId;cudaDevResourceresult;cudaDevSmResourceSplit(&result,1,&smResource,nullptr,0,¶ms);}
可以在请求局部性域的同时,在params中指定多个约束。例如:
smCount约束可以为0(发现模式)或正值。在发现模式下,API 在params.smCount中返回该局部性域中的 SM 数量。对于完整、未分区的设备资源,此值与cudaDevAttrLocalityDomainMultiprocessorCount相同。当smCount为正值时,API 最多分配cudaDevAttrLocalityDomainMultiprocessorCount所指定的数量。更大的smCount请求将失败。
默认情况下,result中的所有 SM 都必须满足局部性域约束以及指定的任何附加约束。要放宽此行为,请将cudaDevSmResourceGroupBackfill添加到params.flags。启用回填后,API 首先从所请求的局部性域填充该组,然后使用不归属于任何局部性域的 SM,最后使用其他局部性域中的 SM。如果在所请求的局部性域中找不到任何 SM,该调用将失败并返回cudaErrorInvalidResourceConfiguration。
所有未在result中返回的未使用 SM 都会在 API 的remainder参数中返回。
result的cudaDevResource.sm.flags和cudaDevResource.sm.localityDomainId报告资源的放置情况。将 SM 资源组合到一个描述符中时,这些资源的约束必须匹配,包括flags和localityDomainId的值。
以下代码查询局部性域的数量,并为每个局部性域构建一个流。
std::vector<cudaExecutionContext_t>contexts(localityDomainCount);std::vector<cudaStream_t>streams(localityDomainCount);{std::vector<cudaDevSmResourceGroupParams>params(localityDomainCount);std::vector<cudaDevResource>result(localityDomainCount);for(inti=0;i<localityDomainCount;i++){params[i]={};params[i].flags=cudaDevSmResourceGroupLocalityDomainId;params[i].localityDomainId=i;}// A single split produces non-overlapping resources for all domains.cudaDevSmResourceSplit(result.data(),localityDomainCount,&smResource,nullptr,0,params.data());for(inti=0;i<localityDomainCount;i++){cudaDevResourceDesc_tdesc;cudaDevResourceGenerateDesc(&desc,&result[i],1);cudaGreenCtxCreate(&contexts[i],desc,device,0);cudaExecutionCtxStreamCreate(&streams[i],contexts[i],cudaStreamDefault,0);}}
streams中的每个流都在具有对应索引的局部性域中的 SM 上执行。不再需要这些流时,使用cudaStreamDestroy销毁流,然后使用cudaExecutionCtxDestroy销毁其上下文。
4.7.3. 分配局部化设备内存
CUDA 使用type为cudaMemLocationTypeDeviceLocalityDomain的cudaMemLocation来表示局部化内存位置。对于这种位置类型,请初始化cudaMemLocation.localized的两个成员:
deviceId标识 GPU。
localityDomainId标识该 GPU 上的一个局部性域。
运行时 API 将此位置用于流有序内存池(第 4.3 节)。驱动程序 API 还将相应的CUmemLocation用于虚拟内存管理分配(第 4.17 节)。
produceInputs<<<grid,block,0,parentStream>>>(...);cudaEventRecord(forkEvent,parentStream);// localizedStreams[i] belongs to the green context for locality domain i.for(inti=0;i<localityDomainCount;i++){cudaStreamWaitEvent(localizedStreams[i],forkEvent);processPartition<<<grid,block,0,localizedStreams[i]>>>(...);cudaEventRecord(joinEvents[i],localizedStreams[i]);}for(inti=0;i<localityDomainCount;i++){cudaStreamWaitEvent(parentStream,joinEvents[i]);}consumeResults<<<grid,block,0,parentStream>>>(...);
4.7.5.2. CUDA 图
CUDA 图(第 4.2 节)通过流捕获和手动图构建来支持局部化。对于某些应用程序,CUDA 图可能比基于流的编程提供更好的性能。
4.7.5.2.1. 流捕获
可以将分叉/汇合模式捕获为 CUDA 图。在父流上开始捕获,记录分叉事件,并在每个局部化流中等待该分叉事件。等待分叉事件会将局部化流纳入与父流相同的捕获图。提交到局部化流的操作成为并行的图分支。在局部化流上启动所有工作后,记录汇合事件,并在父流中等待所有汇合事件。这些等待会将所有分支重新连接到父流。在调用cudaStreamEndCapture之前,每个参与的流都必须汇合回起始流。
cudaStreamBeginCapture(parentStream,cudaStreamCaptureModeGlobal);// Record forkEvent, submit work to each localized stream, record the// joinEvents, and make parentStream wait as in the fork/join example above.cudaGraph_tgraph;cudaStreamEndCapture(parentStream,&graph);
CUDA Checkpoint 不保证局部化绿色上下文在另一台设备上恢复时仍保留其局部化属性。应用程序在恢复后可能出现性能下降。
MLOPart 模式下的MPS(多进程服务)将每个 MLOPart 设备呈现为具有单个局部性域的 CUDA 设备。MPS 静态分区将整个设备视为单个局部性域。
4.8. 延迟加载
4.8.1. 简介
延迟加载通过等到需要 CUDA 模块时才加载它们,来减少程序初始化时间。对于仅使用其所包含核函数中一小部分的程序,延迟加载尤其有效,使用库时通常就是这种情况。延迟加载的设计目标是,在遵循 CUDA 编程模型时,用户无法察觉它的存在。潜在风险对此进行了详细说明。从 CUDA 12.3 起,所有平台都默认启用延迟加载,但可以通过CUDA_MODULE_LOADING环境变量进行控制。
4.8.2. 变更历史
表 17 按 CUDA 版本列出的部分延迟加载变更
CUDA 版本
变更
12.3
延迟加载性能得到改进。现在 Windows 默认启用延迟加载。
12.2
Linux 默认启用延迟加载。
11.7
首次引入延迟加载,默认禁用。
4.8.3. 延迟加载的要求
延迟加载是 CUDA 运行时和驱动程序共同提供的功能。只有满足运行时和驱动程序版本要求时,才能使用延迟加载。
4.8.3.1. CUDA 运行时版本要求
从 CUDA 运行时版本 11.7 开始提供延迟加载。由于 CUDA 运行时通常以静态方式链接到程序和库中,因此只有来自 CUDA 11.7 及更高版本工具包或使用这些工具包编译的程序和库才能受益于延迟加载。使用较旧 CUDA 运行时版本编译的库会立即加载所有模块。
4.8.3.2. CUDA 驱动程序版本要求
延迟加载要求驱动程序版本为 515 或更高。对于低于 515 的驱动程序版本,即使使用 CUDA 工具包 11.7 或更高版本,也无法使用延迟加载。
高级同步原语中介绍的异步屏障将 CUDA 的同步能力扩展到了__syncthreads()和__syncwarp()之外,能够实现细粒度的非阻塞协调,并使通信与计算更好地重叠。
本节详细介绍如何主要通过cuda::barrier API 使用异步屏障(在适用之处提供指向cuda::ptx及原语的参考)。
4.10.1. 初始化
初始化必须在任何线程开始参与屏障之前完成。
#include<cuda/barrier>#include<cooperative_groups.h>__global__voidinit_barrier(){__shared__cuda::barrier<cuda::thread_scope_block>bar;autoblock=cooperative_groups::this_thread_block();if(block.thread_rank()==0){// A single thread initializes the total expected arrival count.init(&bar,block.size());}block.sync();}
#include<cuda/ptx>#include<cooperative_groups.h>__global__voidinit_barrier(){__shared__uint64_tbar;autoblock=cooperative_groups::this_thread_block();if(block.thread_rank()==0){// A single thread initializes the total expected arrival count.cuda::ptx::mbarrier_init(&bar,block.size());}block.sync();}
#include<cuda_awbarrier_primitives.h>#include<cooperative_groups.h>__global__voidinit_barrier(){__shared__uint64_tbar;autoblock=cooperative_groups::this_thread_block();if(block.thread_rank()==0){// A single thread initializes the total expected arrival count.__mbarrier_init(&bar,block.size());}block.sync();}
#include<cuda/ptx>#include<cooperative_groups.h>__device__voidcompute(float*data,intiteration);__global__voidsplit_arrive_wait(intiteration_count,float*data){usingbarrier_t=cuda::barrier<cuda::thread_scope_block>;__shared__barrier_tbar;intparity=0;// Initial phase parity is 0.autoblock=cooperative_groups::this_thread_block();if(block.thread_rank()==0){// Initialize barrier with expected arrival count.init(&bar,block.size());}block.sync();for(inti=0;i<iteration_count;++i){/* code before arrive */// This thread arrives. Arrival does not block a thread.// Get a handle to the native barrier to use with cuda::ptx API.(void)cuda::ptx::mbarrier_arrive(cuda::device::barrier_native_handle(bar));compute(data,i);// Wait for all threads participating in the barrier to complete mbarrier_arrive().// Get a handle to the native barrier to use with cuda::ptx API.while(!cuda::ptx::mbarrier_try_wait_parity(cuda::device::barrier_native_handle(bar),parity)){}// Flip parity.parity^=1;/* code after wait */}}
#include<cuda/ptx>#include<cooperative_groups.h>__device__voidcompute(float*data,intiteration);__global__voidsplit_arrive_wait(intiteration_count,float*data){__shared__uint64_tbar;intparity=0;// Initial phase parity is 0.autoblock=cooperative_groups::this_thread_block();if(block.thread_rank()==0){// Initialize barrier with expected arrival count.cuda::ptx::mbarrier_init(&bar,block.size());}block.sync();for(inti=0;i<iteration_count;++i){/* code before arrive */// This thread arrives. Arrival does not block a thread.(void)cuda::ptx::mbarrier_arrive(&bar);compute(data,i);// Wait for all threads participating in the barrier to complete mbarrier_arrive().while(!cuda::ptx::mbarrier_try_wait_parity(&bar,parity)){}// Flip parity.parity^=1;/* code after wait */}}
#include<cuda_awbarrier_primitives.h>#include<cooperative_groups.h>__device__voidcompute(float*data,intiteration);__global__voidsplit_arrive_wait(intiteration_count,float*data){__shared____mbarrier_tbar;boolparity=false;// Initial phase parity is false.autoblock=cooperative_groups::this_thread_block();if(block.thread_rank()==0){// Initialize barrier with expected arrival count.__mbarrier_init(&bar,block.size());}block.sync();for(inti=0;i<iteration_count;++i){/* code before arrive */// This thread arrives. Arrival does not block a thread.(void)__mbarrier_arrive(&bar);compute(data,i);// Wait for all threads participating in the barrier to complete __mbarrier_arrive().while(!__mbarrier_try_wait_parity(&bar,parity,1000)){}parity^=1;/* code after wait */}}
#include<cuda/barrier>#include<cooperative_groups.h>__device__boolcondition_check();__global__voidearly_exit_kernel(intN){__shared__cuda::barrier<cuda::thread_scope_block>bar;autoblock=cooperative_groups::this_thread_block();if(block.thread_rank()==0){init(&bar,block.size());}block.sync();for(inti=0;i<N;++i){if(condition_check()){bar.arrive_and_drop();return;}// Other threads can proceed normally.autotoken=bar.arrive();/* code between arrive and wait */// Wait for all threads to arrive.bar.wait(std::move(token));/* code after wait */}}
#include<cuda_awbarrier_primitives.h>#include<cooperative_groups.h>__device__boolcondition_check();__global__voidearly_exit_kernel(intN){__shared____mbarrier_tbar;autoblock=cooperative_groups::this_thread_block();if(block.thread_rank()==0){__mbarrier_init(&bar,block.size());}block.sync();for(inti=0;i<N;++i){if(condition_check()){__mbarrier_token_ttoken=__mbarrier_arrive_and_drop(&bar);return;}// Other threads can proceed normally.__mbarrier_token_ttoken=__mbarrier_arrive(&bar);/* code between arrive and wait */// Wait for all threads to arrive.while(!__mbarrier_try_wait(&bar,token,1000)){}/* code after wait */}}
cuda::barrier API 支持一个可选的完成函数。cuda::barrier<Scope,CompletionFunction>的CompletionFunction在每个阶段执行一次,时间是在最后一个线程到达之后、任何线程从wait解除阻塞之前。在该阶段到达barrier的线程所执行的内存操作,对执行CompletionFunction的线程可见;在CompletionFunction内执行的所有内存操作,则对所有在barrier处等待的线程可见,前提是这些线程已从wait解除阻塞。
#include<cuda/barrier>#include<cooperative_groups.h>#include<functional>namespacecg=cooperative_groups;__device__intdivergent_compute(int*,int);__device__intindependent_computation(int*,int);__global__voidpsum(int*data,intn,int*acc){autoblock=cg::this_thread_block();constexprintBlockSize=128;__shared__intsmem[BlockSize];assert(BlockSize==block.size());assert(n%BlockSize==0);autocompletion_fn=[&]{intsum=0;for(inti=0;i<BlockSize;++i){sum+=smem[i];}*acc+=sum;};/* Barrier storage. Note: the barrier is not default-constructible because completion_fn is not default-constructible due to the capture. */usingcompletion_fn_t=decltype(completion_fn);usingbarrier_t=cuda::barrier<cuda::thread_scope_block,completion_fn_t>;__shared__std::aligned_storage<sizeof(barrier_t),alignof(barrier_t)>bar_storage;// Initialize barrier.barrier_t*bar=(barrier_t*)&bar_storage;if(block.thread_rank()==0){assert(*acc==0);assert(blockDim.x==blockDim.y==blockDim.y==1);new(bar)barrier_t{block.size(),completion_fn};/* equivalent to: init(bar, block.size(), completion_fn); */}block.sync();// Main loop.for(inti=0;i<n;i+=block.size()){smem[block.thread_rank()]=data[i]+*acc;autotoken=bar->arrive();// We can do independent computation here.bar->wait(std::move(token));// Shared-memory is safe to re-use in the next iteration// since all threads are done with it, including the one// that did the reduction.}}
#include<cuda/barrier>usingbarrier_t=cuda::barrier<cuda::thread_scope_block>;__device__voidproduce(barrier_tready[],barrier_tfilled[],float*buffer,intbuffer_len,float*in,intN){for(inti=0;i<N/buffer_len;++i){ready[i%2].arrive_and_wait();/* wait for buffer_(i%2) to be ready to be filled *//* produce, i.e., fill in, buffer_(i%2) */barrier_t::arrival_tokentoken=filled[i%2].arrive();/* buffer_(i%2) is filled */}}__device__voidconsume(barrier_tready[],barrier_tfilled[],float*buffer,intbuffer_len,float*out,intN){barrier_t::arrival_tokentoken1=ready[0].arrive();/* buffer_0 is ready for initial fill */barrier_t::arrival_tokentoken2=ready[1].arrive();/* buffer_1 is ready for initial fill */for(inti=0;i<N/buffer_len;++i){filled[i%2].arrive_and_wait();/* wait for buffer_(i%2) to be filled *//* consume buffer_(i%2) */barrier_t::arrival_tokentoken3=ready[i%2].arrive();/* buffer_(i%2) is ready to be re-filled */}}__global__voidproducer_consumer_pattern(intN,float*in,float*out,intbuffer_len){constexprintwarpSize=32;/* Shared memory buffer declared below is of size 2 * buffer_len so that we can alternatively work between two buffers. buffer_0 = buffer and buffer_1 = buffer + buffer_len */__shared__externfloatbuffer[];/* bar[0] and bar[1] track if buffers buffer_0 and buffer_1 are ready to be filled, while bar[2] and bar[3] track if buffers buffer_0 and buffer_1 are filled-in respectively */#pragma nv_diag_suppress static_var_with_dynamic_init__shared__barrier_tbar[4];if(threadIdx.x<4){init(bar+threadIdx.x,blockDim.x);}__syncthreads();if(threadIdx.x<warpSize){produce(bar,bar+2,buffer,buffer_len,in,N);}else{consume(bar,bar+2,buffer,buffer_len,out,N);}}
#include<cuda/ptx>__device__voidproduce(barrierready[],barrierfilled[],float*buffer,intbuffer_len,float*in,intN){for(inti=0;i<N/buffer_len;++i){uint64_ttoken1=cuda::ptx::mbarrier_arrive(ready[i%2]);while(!cuda::ptx::mbarrier_try_wait(&ready[i%2],token1)){}/* wait for buffer_(i%2) to be ready to be filled *//* produce, i.e., fill in, buffer_(i%2) */uint64_ttoken2=cuda::ptx::mbarrier_arrive(&filled[i%2]);/* buffer_(i%2) is filled */}}__device__voidconsume(barrierready[],barrierfilled[],float*buffer,buffer_len,float*out,intN){uint64_ttoken1=cuda::ptx::mbarrier_arrive(&ready[0]);/* buffer_0 is ready for initial fill */uint64_ttoken2=cuda::ptx::mbarrier_arrive(&ready[1]);/* buffer_1 is ready for initial fill */for(inti=0;i<N/buffer_len;++i){uint64_ttoken3=cuda::ptx::mbarrier_arrive(&filled[i%2]);while(!cuda::ptx::mbarrier_try_wait(&filled[i%2],token3x)){}/* wait for buffer_(i%2) to be filled *//* consume buffer_(i%2) */uint64_ttoken4=cuda::ptx::mbarrier_arrive(&ready[i%2]);/* buffer_(i%2) is ready to be re-filled */}}__global__voidproducer_consumer_pattern(intN,float*in,float*out,intbuffer_len){constexprintwarpSize=32;/* Shared memory buffer declared below is of size 2 * buffer_len so that we can alternatively work between two buffers. buffer_0 = buffer and buffer_1 = buffer + buffer_len */__shared__externfloatbuffer[];/* bar[0] and bar[1] track if buffers buffer_0 and buffer_1 are ready to be filled, while bar[2] and bar[3] track if buffers buffer_0 and buffer_1 are filled-in respectively */#pragma nv_diag_suppress static_var_with_dynamic_init__shared__uint64_tbar[4];if(threadIdx.x<4){cuda::ptx::mbarrier_init(bar+block.thread_rank(),block.size());}__syncthreads();if(threadIdx.x<warpSize){produce(bar,bar+2,buffer,buffer_len,in,N);}else{consume(bar,bar+2,buffer,buffer_len,out,N);}}
#include<cuda_awbarrier_primitives.h>__device__voidproduce(__mbarrier_tready[],__mbarrier_tfilled[],float*buffer,intbuffer_len,float*in,intN){for(inti=0;i<N/buffer_len;++i){__mbarrier_token_ttoken1=__mbarrier_arrive(&ready[i%2]);/* wait for buffer_(i%2) to be ready to be filled */while(!__mbarrier_try_wait(&ready[i%2],token1,1000)){}/* produce, i.e., fill in, buffer_(i%2) */__mbarrier_token_ttoken2=__mbarrier_arrive(filled[i%2]);/* buffer_(i%2) is filled */}}__device__voidconsume(__mbarrier_tready[],__mbarrier_tfilled[],float*buffer,intbuffer_len,float*out,intN){__mbarrier_token_ttoken1=__mbarrier_arrive(&ready[0]);/* buffer_0 is ready for initial fill */__mbarrier_token_ttoken2=__mbarrier_arrive(&ready[1]);/* buffer_1 is ready for initial fill */for(inti=0;i<N/buffer_len;++i){__mbarrier_token_ttoken3=__mbarrier_arrive(&filled[i%2]);while(!__mbarrier_try_wait(&filled[i%2],token3,1000)){}/* consume buffer_(i%2) */__mbarrier_token_ttoken4=__mbarrier_arrive(&ready[i%2]);/* buffer_(i%2) is ready to be re-filled */}}__global__voidproducer_consumer_pattern(intN,float*in,float*out,intbuffer_len){constexprintwarpSize=32;/* Shared memory buffer declared below is of size 2 * buffer_len so that we can alternatively work between two buffers. buffer_0 = buffer and buffer_1 = buffer + buffer_len */__shared__externfloatbuffer[];/* bar[0] and bar[1] track if buffers buffer_0 and buffer_1 are ready to be filled, while bar[2] and bar[3] track if buffers buffer_0 and buffer_1 are filled-in respectively */#pragma nv_diag_suppress static_var_with_dynamic_init__shared____mbarrier_tbar[4];if(threadIdx.x<4){__mbarrier_init(bar+threadIdx.x,blockDim.x);}__syncthreads();if(threadIdx.x<warpSize){produce(bar,bar+2,buffer,buffer_len,in,N);}else{consume(bar,bar+2,buffer,buffer_len,out,N);}}
// Create a pipeline at thread scopeconstexprautoscope=cuda::thread_scope_thread;cuda::pipeline<scope>pipeline=cuda::make_pipeline();
// Create a pipeline at block scopeconstexprautoscope=cuda::thread_scope_block;constexprautostages_count=2;__shared__cuda::pipeline_shared_state<scope,stages_count>shared_state;autopipeline=cuda::make_pipeline(group,&shared_state);
// Create a partitioned pipeline at block scope where only thread 0 is a producerconstexprautoscope=cuda::thread_scope_block;constexprautostages_count=2;__shared__cuda::pipeline_shared_state<scope,stages_count>shared_state;autothread_role=(group.thread_rank()==0)?cuda::pipeline_role::producer:cuda::pipeline_role::consumer;autopipeline=cuda::make_pipeline(group,&shared_state,thread_role);
使用cuda::pipeline<cuda:thread_scope_thread>时,还可以使用cuda::pipeline_consumer_wait_prior<N>()友元函数,等待除最后 N 个阶段以外的所有阶段完成,这类似于原语 API 中的__pipeline_wait_prior(N)。
4.11.4. 线程束纠缠
同一线程束中的 CUDA 线程共享流水线机制。这种共享会导致线程束内已提交操作的序列相互纠缠,在某些情况下可能影响性能。
#include<cuda/pipeline>__global__voidexample_kernel(constfloat*in){constexprintblock_size=128;__shared____align__(sizeof(float))floatbuffer[4*block_size];// Create a unified pipeline per threadcuda::pipeline<cuda::thread_scope_thread>pipeline=cuda::make_pipeline();// First stage of memory copiespipeline.producer_acquire();// Every thread fetches one element of the first blockcuda::memcpy_async(buffer,in,sizeof(float),pipeline);pipeline.producer_commit();// Second stage of memory copiespipeline.producer_acquire();// Every thread fetches one element of the second and third blockcuda::memcpy_async(buffer+block_size,in+block_size,sizeof(float),pipeline);cuda::memcpy_async(buffer+2*block_size,in+2*block_size,sizeof(float),pipeline);pipeline.producer_commit();// Third stage of memory copiespipeline.producer_acquire();// Every thread fetches one element of the last blockcuda::memcpy_async(buffer+3*block_size,in+3*block_size,sizeof(float),pipeline);pipeline.producer_commit();// Wait for the oldest stage (waits for first stage)pipeline.consumer_wait();pipeline.consumer_release();// __syncthreads();// Use data from the first stage// Wait for the oldest stage (waits for second stage)pipeline.consumer_wait();pipeline.consumer_release();// __syncthreads();// Use data from the second stage// Wait for the oldest stage (waits for third stage)pipeline.consumer_wait();pipeline.consumer_release();// __syncthreads();// Use data from the third stage}
#include<cuda_pipeline.h>__global__voidexample_kernel(constfloat*in){constexprintblock_size=128;__shared____align__(sizeof(float))floatbuffer[4*block_size];// First batch of memory copies// Every thread fetches one element of the first block__pipeline_memcpy_async(buffer,in,sizeof(float));__pipeline_commit();// Second batch of memory copies// Every thread fetches one element of the second and third block__pipeline_memcpy_async(buffer+block_size,in+block_size,sizeof(float));__pipeline_memcpy_async(buffer+2*block_size,in+2*block_size,sizeof(float));__pipeline_commit();// Third batch of memory copies// Every thread fetches one element of the last block__pipeline_memcpy_async(buffer+3*block_size,in+3*block_size,sizeof(float));__pipeline_commit();// Wait for all except the last two batches of memory copies (waits for first batch)__pipeline_wait_prior(2);// __syncthreads();// Use data from the first batch// Wait for all except the last batch of memory copies (waits for second batch)__pipeline_wait_prior(1);// __syncthreads();// Use data from the second batch// Wait for all batches of memory copies (waits for third batch)__pipeline_wait_prior(0);// __syncthreads();// Use data from the last batch}
#include<cuda/pipeline>#include<cooperative_groups.h>#pragma nv_diag_suppress static_var_with_dynamic_initusingpipeline=cuda::pipeline<cuda::thread_scope_block>;__device__voidproduce(pipeline&pipe,intnum_stages,intstage,intnum_batches,intbatch,float*buffer,intbuffer_len,float*in,intN){if(batch<num_batches){pipe.producer_acquire();/* copy data from in(batch) to buffer(stage) using asynchronous memory copies */pipe.producer_commit();}}__device__voidconsume(pipeline&pipe,intnum_stages,intstage,intnum_batches,intbatch,float*buffer,intbuffer_len,float*out,intN){pipe.consumer_wait();/* consume buffer(stage) and update out(batch) */pipe.consumer_release();}__global__voidproducer_consumer_pattern(float*in,float*out,intN,intbuffer_len){autoblock=cooperative_groups::this_thread_block();/* Shared memory buffer declared below is of size 2 * buffer_len so that we can alternatively work between two buffers. buffer_0 = buffer and buffer_1 = buffer + buffer_len */__shared__externfloatbuffer[];constintnum_batches=N/buffer_len;// Create a partitioned pipeline with 2 stages where half the threads are producers and the other half are consumers.constexprautoscope=cuda::thread_scope_block;constexprintnum_stages=2;cuda::std::size_tproducer_count=block.size()/2;__shared__cuda::pipeline_shared_state<scope,num_stages>shared_state;pipelinepipe=cuda::make_pipeline(block,&shared_state,producer_count);// Fill the pipelineif(block.thread_rank()<producer_count){for(ints=0;s<num_stages;++s){produce(pipe,num_stages,s,num_batches,s,buffer,buffer_len,in,N);}}// Process the batchesintstage=0;for(size_tb=0;b<num_batches;++b){if(block.thread_rank()<producer_count){// Prefetch the next batchproduce(pipe,num_stages,stage,num_batches,b+num_stages,buffer,buffer_len,in,N);}else{// Consume the oldest batchconsume(pipe,num_stages,stage,num_batches,b,buffer,buffer_len,out,N);}stage=(stage+1)%num_stages;}}
__global__voidstencil_kernel(constfloat*left,constfloat*center,constfloat*right){// Left halo (8 elements) - center (32 elements) - right halo (8 elements)__shared__floatbuffer[8+32+8];constinttid=threadIdx.x;if(tid<8){buffer[tid]=left[tid];// Left halo}elseif(tid>=32-8){buffer[tid+16]=right[tid];// Right halo}if(tid<32){buffer[tid+8]=center[tid];// Center}__syncthreads();// Compute stencil}
#include<cooperative_groups.h>#include<cuda/barrier>__global__voidstencil_kernel(constfloat*left,constfloat*center,constfloat*right){autoblock=cooperative_groups::this_thread_block();autothread=cooperative_groups::this_thread();usingbarrier_t=cuda::barrier<cuda::thread_scope_block>;__shared__barrier_tbarrier;__shared__floatbuffer[8+32+8];// Initialize synchronization object.if(block.thread_rank()==0){init(&barrier,block.size());}__syncthreads();// Version 1: Issue the copies in individual threads.if(tid<8){cuda::memcpy_async(buffer+tid,left+tid,cuda::aligned_size_t<4>(sizeof(float)),barrier);// Left halo// or cuda::memcpy_async(thread, buffer + tid, left + tid, cuda::aligned_size_t<4>(sizeof(float)), barrier);}elseif(tid>=32-8){cuda::memcpy_async(buffer+tid+16,right+tid,cuda::aligned_size_t<4>(sizeof(float)),barrier);// Right halo// or cuda::memcpy_async(thread, buffer + tid + 16, right + tid, cuda::aligned_size_t<4>(sizeof(float)), barrier);}if(tid<32){cuda::memcpy_async(buffer+40,right+tid,cuda::aligned_size_t<4>(sizeof(float)),barrier);// Center// or cuda::memcpy_async(thread, buffer + 40, right + tid, cuda::aligned_size_t<4>(sizeof(float)), barrier);}// Version 2: Cooperatively issue the copies across all threads.cuda::memcpy_async(block,buffer,left,cuda::aligned_size_t<4>(8*sizeof(float)),barrier);// Left halocuda::memcpy_async(block,buffer+8,center,cuda::aligned_size_t<4>(32*sizeof(float)),barrier);// Centercuda::memcpy_async(block,buffer+40,right,cuda::aligned_size_t<4>(8*sizeof(float)),barrier);// Right halo// Wait for all copies to complete.barrier.arrive_and_wait();__syncthreads();// Compute stencil }
#include<cooperative_groups.h>#include<cooperative_groups/memcpy_async.h>namespacecg=cooperative_groups;__global__voidstencil_kernel(constfloat*left,constfloat*center,constfloat*right){cg::thread_blockblock=cg::this_thread_block();// Left halo (8 elements) - center (32 elements) - right halo (8 elements). __shared__floatbuffer[8+32+8];// Cooperatively issue the copies across all threads.cg::memcpy_async(block,buffer,left,8*sizeof(float));// Left halocg::memcpy_async(block,buffer+8,center,32*sizeof(float));// Centercg::memcpy_async(block,buffer+40,right,8*sizeof(float));// Right halocg::wait(block);// Waits for all copies to complete.__syncthreads();// Compute stencil.}
#include<cuda_pipeline.h>__global__voidstencil_kernel(constfloat*left,constfloat*center,constfloat*right){// Left halo (8 elements) - center (32 elements) - right halo (8 elements).__shared__floatbuffer[8+32+8];constinttid=threadIdx.x;if(tid<8){__pipeline_memcpy_async(buffer+tid,left+tid,sizeof(float));// Left halo}elseif(tid>=32-8){__pipeline_memcpy_async(buffer+tid+16,right+tid,sizeof(float));// Right halo}if(tid<32){__pipeline_memcpy_async(buffer+tid+8,center+tid,sizeof(float));// Center}__pipeline_commit();__pipeline_wait_prior(0);__syncthreads();// Compute stencil.}
基于低级原语的实现使用__pipeline_memcpy_async()发起逐元素内存传输,使用__pipeline_commit()提交这一批复制,并使用__pipeline_wait_prior(0)等待流水线中的所有操作完成。这提供了最直接的控制,但与更高级别的 API 相比,代价是代码更加冗长。它还确保底层会使用 LDGSTS,而更高级别的 API 并不提供这一保证。
注意
在此示例中,cooperative_groups::memcpy_async API 的效率低于其他 API,因为它会在每次复制操作启动后立即自动提交该操作,从而无法像其他 API 那样,通过在一次提交操作之前批量执行多次复制来进行优化。
#include<cooperative_groups.h>#include<cuda/pipeline>template<size_tnum_stages=2/* Pipeline with num_stages stages */>__global__voidprefetch_kernel(int*global_out,intconst*global_in,size_tsize,size_tbatch_size){autogrid=cooperative_groups::this_grid();autoblock=cooperative_groups::this_thread_block();autothread=cooperative_groups::this_thread();assert(size==batch_size*grid.size());// Assume input size fits batch_size * grid_sizeextern__shared__intshared[];// num_stages * block.size() * sizeof(int) bytessize_tshared_offset[num_stages];for(ints=0;s<num_stages;++s)shared_offset[s]=s*block.size();cuda::pipeline<cuda::thread_scope_thread>pipeline=cuda::make_pipeline();autoblock_batch=[&](size_tbatch)->int{returnblock.group_index().x*block.size()+grid.size()*batch;};// Fill the pipeline with the first ``num_stages`` batches.for(ints=0;s<num_stages;++s){pipeline.producer_acquire();cuda::memcpy_async(shared+shared_offset[s]+tid,global_in+block_batch(s)+tid,cuda::aligned_size_t<4>(sizeof(int)),pipeline);pipeline.producer_commit();}intstage=0;// compute_batch: next batch to process// fetch_batch: next batch to fetch from global memoryfor(size_tcompute_batch=0,fetch_batch=num_stages;compute_batch<batch_size;++compute_batch,++fetch_batch){// Wait for the first requested stage to complete.constexprsize_tpending_batches=num_stages-1;cuda::pipeline_consumer_wait_prior<pending_batches>(pipeline);__syncthreads();// Not required if each thread works on the data it copied.// Compute on the current batchcompute(global_out+block_batch(compute_batch)+tid,shared+shared_offset[stage]+tid);// Release the current stage.pipeline.consumer_release();__syncthreads();// Not required if each thread works on the data it copied.// Load future stage ``num_stages`` ahead of current compute batch.pipeline.producer_acquire();if(fetch_batch<batch_size){cuda::memcpy_async(shared+shared_offset[stage]+tid,global_in+block_batch(fetch_batch)+tid,cuda::aligned_size_t<4>(sizeof(int)),pipeline);}pipeline.producer_commit();stage=(stage+1)%num_stages;}}
#include<cooperative_groups.h>#include<cooperative_groups/memcpy_async.h>namespacecg=cooperative_groups;template<size_tnum_stages=2/* Pipeline with num_stages stages */>__global__voidprefetch_kernel(int*global_out,intconst*global_in,size_tsize,size_tbatch_size){autogrid=cooperative_groups::this_grid();autoblock=cooperative_groups::this_thread_block();assert(size==batch_size*grid.size());// Assume input size fits batch_size * grid_sizeextern__shared__intshared[];// num_stages * block.size() * sizeof(int) bytessize_tshared_offset[num_stages];for(ints=0;s<num_stages;++s)shared_offset[s]=s*block.size();cuda::pipeline<cuda::thread_scope_thread>pipeline=cuda::make_pipeline();autoblock_batch=[&](size_tbatch)->int{returnblock.group_index().x*block.size()+grid.size()*batch;};// Fill the pipeline with the first ``num_stages`` batches.for(ints=0;s<num_stages;++s){size_tblock_batch_idx=block_batch(s);cg::memcpy_async(block,shared+shared_offset[s],global_in+block_batch_idx,cuda::aligned_size_t<4>(sizeof(int));}intstage=0;// compute_batch: next batch to process// fetch_batch: next batch to fetch from global memoryfor(size_tcompute_batch=0,fetch_batch=num_stages;compute_batch<batch_size;++compute_batch,++fetch_batch){// Wait for the first requested stage to complete.size_tpending_batches=(fetch_batch<batch_size-num_stages)?num_stages-1:batch_size-fetch_batch-1;cg::wait_prior(pending_batches);__syncthreads();// Not required if each thread works on the data it copied.// Compute on the current batch.compute(global_out+block_batch(compute_batch)+tid,shared+shared_offset[stage]+tid);__syncthreads();// Not required if each thread works on the data it copied.// Load future stage ``num_stages`` ahead of current compute batch.size_tfetch_batch_idx=block_batch(fetch_batch);if(fetch_batch<batch_size){cg::memcpy_async(block,shared+shared_offset[stage],global_in+block_batch(fetch_batch),cuda::aligned_size_t<4>(sizeof(int))*block.size());}stage=(stage+1)%num_stages;}}
#include<cooperative_groups.h>#include<cuda_awbarrier_primitives.h>template<size_tnum_stages=2/* Pipeline with num_stages stages */>__global__voidprefetch_kernel(int*global_out,intconst*global_in,size_tsize,size_tbatch_size){autogrid=cooperative_groups::this_grid();autoblock=cooperative_groups::this_thread_block();assert(size==batch_size*grid.size());// Assume input size fits batch_size * grid_sizeextern__shared__intshared[];// num_stages * block.size() * sizeof(int) bytessize_tshared_offset[num_stages];for(ints=0;s<num_stages;++s)shared_offset[s]=s*block.size();autoblock_batch=[&](size_tbatch)->int{returnblock.group_index().x*block.size()+grid.size()*batch;};// Fill the pipeline with the first ``num_stages`` batches.for(ints=0;s<num_stages;++s){__pipeline_memcpy_async(shared+shared_offset[s]+tid,global_in+block_batch(s)+tid,cuda::aligned_size_t<4>(sizeof(int)));__pipeline_commit();}// compute_batch: next batch to process// fetch_batch: next batch to fetch from global memoryfor(size_tcompute_batch=0,fetch_batch=num_stages;compute_batch<batch_size;++compute_batch,++fetch_batch){// Wait for the first requested stage to complete.constexprsize_tpending_batches=num_stages-1;__pipeline_wait_prior<pending_batches>();__syncthreads();// Not required if each thread works on the data it copied.// Compute on the current batch.compute(global_out+block_batch(compute_batch)+tid,shared+shared_offset[stage]+tid);__syncthreads();// Not required if each thread works on the data it copied.// Load future stage ``num_stages`` ahead of current compute batch.if(fetch_batch<batch_size){__pipeline_memcpy_async(shared+shared_offset[stage]+tid,global_in+block_batch(fetch_batch)+tid,cuda::aligned_size_t<4>(sizeof(int)));}__pipeline_commit();stage=(stage+1)%num_stages;}}
在此示例中,实现高效代码生成的一个重要细节是,即使没有更多批次需要获取,也要在流水线中保持num_stages个批次。实现方法是,即使没有更多批次需要获取,也向流水线提交(pipeline.producer_commit()或__pipeline_commit())。注意,使用协作组 API 无法做到这一点,因为我们无法访问内部流水线。
#include<cooperative_groups.h>#include<cuda/pipeline>#pragma nv_diag_suppress static_var_with_dynamic_initusingpipeline=cuda::pipeline<cuda::thread_scope_block>;__device__voidproduce(pipeline&pipe,intnum_stages,intstage,intnum_batches,intbatch,float*buffer,intbuffer_len,float*in,intN){if(batch<num_batches){pipe.producer_acquire();/* copy data from in(batch) to buffer(stage) using asynchronous memory copies */cuda::memcpy_async(buffer+stage*buffer_len+threadIdx.x,in+batch*buffer_len+threadIdx.x,cuda::aligned_size_t<4>(sizeof(float)),pipe);pipe.producer_commit();}}__device__voidconsume(pipeline&pipe,intnum_stages,intstage,intnum_batches,intbatch,float*buffer,intbuffer_len,float*out,intN){pipe.consumer_wait();/* consume buffer(stage) and update out(batch) */pipe.consumer_release();}__global__voidproducer_consumer_pattern(float*in,float*out,intN,intbuffer_len){autoblock=cooperative_groups::this_thread_block();constexprintwarpSize=32;/* Shared memory buffer declared below is of size 2 * buffer_len so that we can alternatively work between two buffers. buffer_0 = buffer and buffer_1 = buffer + buffer_len */__shared__externfloatbuffer[];constintnum_batches=N/buffer_len;// Create a partitioned pipeline with 2 stages where the first warp is the producer and the other warps are consumers.constexprautoscope=cuda::thread_scope_block;constexprintnum_stages=2;cuda::std::size_tproducer_count=warpSize;__shared__cuda::pipeline_shared_state<scope,num_stages>shared_state;pipelinepipe=cuda::make_pipeline(block,&shared_state,producer_count);// Producer fills the pipelineif(block.thread_rank()<producer_count)for(ints=0;s<num_stages;++s)produce(pipe,num_stages,s,num_batches,s,buffer,buffer_len,in,N);// Process the batchesintstage=0;for(size_tb=0;b<num_batches;++b){if(block.thread_rank()<producer_count){// Producers prefetch the next batchproduce(pipe,num_stages,stage,num_batches,b+num_stages,buffer,buffer_len,in,N);}else{// Consumers consume the oldest batchconsume(pipe,num_stages,stage,num_batches,b,buffer,buffer_len,out,N);}stage=(stage+1)%num_stages;}}
#include<cooperative_groups.h>#include<cuda_awbarrier_primitives.h>__device__voidproduce(__mbarrier_tready[],__mbarrier_tfilled[],float*buffer,intbuffer_len,float*in,intN){for(inti=0;i<N/buffer_len;++i){__mbarrier_token_ttoken=__mbarrier_arrive(&ready[i%2]);/* wait for buffer_(i%2) to be ready to be filled */while(!__mbarrier_try_wait(&ready[i%2],token,1000)){}/* produce, i.e., fill in, buffer_(i%2) */__pipeline_memcpy_async(buffer+i*buffer_len+threadIdx.x,in+i*buffer_len+threadIdx.x,cuda::aligned_size_t<4>(sizeof(float)));__pipeline_arrive_on(filled[i%2]);__mbarrier_arrive(filled[i%2]);/* buffer_(i%2) is filled */}}__device__voidconsume(__mbarrier_tready[],__mbarrier_tfilled[],float*buffer,intbuffer_len,float*out,intN){__mbarrier_arrive(&ready[0]);/* buffer_0 is ready for initial fill */__mbarrier_arrive(&ready[1]);/* buffer_1 is ready for initial fill */for(inti=0;i<N/buffer_len;++i){__mbarrier_token_ttoken=__mbarrier_arrive(&filled[i%2]);while(!__mbarrier_try_wait(&filled[i%2],token,1000)){}/* consume buffer_(i%2) */__mbarrier_arrive(&ready[i%2]);/* buffer_(i%2) is ready to be re-filled */}}__global__voidproducer_consumer_pattern(intN,float*in,float*out,intbuffer_len){/* Shared memory buffer declared below is of size 2 * buffer_len so that we can alternatively work between two buffers. buffer_0 = buffer and buffer_1 = buffer + buffer_len */__shared__externfloatbuffer[];/* bar[0] and bar[1] track if buffers buffer_0 and buffer_1 are ready to be filled, while bar[2] and bar[3] track if buffers buffer_0 and buffer_1 are filled-in respectively */__shared____mbarrier_tbar[4];// Initialize the barriersautoblock=cooperative_groups::this_thread_block();if(block.thread_rank()<4)__mbarrier_init(bar+block.thread_rank(),block.size());__syncthreads();if(block.thread_rank()<warpSize)produce(bar,bar+2,buffer,buffer_len,in,N);elseconsume(bar,bar+2,buffer,buffer_len,out,N);}
基于原语的 CUDA C 原语实现将__pipeline_memcpy_async()与用作完成机制的共享内存屏障结合,以协调异步内存传输。__pipeline_arrive_on()函数将内存复制与屏障关联起来。它将屏障到达计数加一,当顺序排在它之前的所有异步操作都完成后,到达计数会自动减一,因此对到达计数的净影响为零。出于这一原因,我们还需要使用__mbarrier_arrive()显式到达屏障。
某些功能需要内联 PTX,目前这些功能通过CUDA Standard C++库中的cuda::ptx命名空间提供。可以使用以下代码检查这些封装的可用性:
#if defined(__CUDA_MINIMUM_ARCH__) && __CUDA_MINIMUM_ARCH__ < 900static_assert(false,"Device code is being compiled with older architectures that are incompatible with TMA.");#endif // __CUDA_MINIMUM_ARCH__
#include<cuda/barrier>#include<cuda/ptx>usingbarrier=cuda::barrier<cuda::thread_scope_block>;namespaceptx=cuda::ptx;staticconstexprsize_tbuf_len=1024;__device__inlineboolis_elected(){unsignedinttid=threadIdx.x;unsignedintwarp_id=tid/32;unsignedintuniform_warp_id=__shfl_sync(0xFFFFFFFF,warp_id,0);// Broadcast from lane 0.return(uniform_warp_id==0&&ptx::elect_sync(0xFFFFFFFF));// Elect a leader thread among warp 0.}__global__voidadd_one_kernel(int*data,size_toffset){// Shared memory buffer. The destination shared memory buffer of// a bulk operation should be 16 byte aligned.__shared__alignas(16)intsmem_data[buf_len];// 1. Initialize shared memory barrier with the number of threads participating in the barrier.#pragma nv_diag_suppress static_var_with_dynamic_init__shared__barrierbar;if(threadIdx.x==0){init(&bar,blockDim.x);}__syncthreads();// 2. Initiate TMA transfer to copy global to shared memory from a single thread.if(is_elected()){// Launch the async copy and communicate how many bytes are expected to come in (the transaction count).// Version 1: cuda::memcpy_asynccuda::memcpy_async(smem_data,data+offset,cuda::aligned_size_t<16>(sizeof(smem_data)),bar);// Version 2: cuda::device::memcpy_async_tx// cuda::device::memcpy_async_tx(// smem_data, data + offset, // cuda::aligned_size_t<16>(sizeof(smem_data)),// bar);// cuda::device::barrier_expect_tx(// cuda::device::barrier_native_handle(bar),// sizeof(smem_data));// Version 3: cuda::ptx::cp_async_bulk// ptx::cp_async_bulk(// ptx::space_shared, ptx::space_global,// smem_data, data + offset, // sizeof(smem_data), // cuda::device::barrier_native_handle(bar));// cuda::device::barrier_expect_tx(// cuda::device::barrier_native_handle(bar),// sizeof(smem_data));}// 3a. All threads arrive on the barrier.barrier::arrival_tokentoken=bar.arrive();// 3b. Wait for the data to have arrived.bar.wait(std::move(token));// 4. Compute saxpy and write back to shared memory.for(inti=threadIdx.x;i<buf_len;i+=blockDim.x){smem_data[i]+=1;}// 5. Wait for shared memory writes to be visible to TMA engine.ptx::fence_proxy_async(ptx::space_shared);__syncthreads();// After syncthreads, writes by all threads are visible to TMA engine.// 6. Initiate TMA transfer to copy shared memory to global memory.if(is_elected()){ptx::cp_async_bulk(ptx::space_global,ptx::space_shared,data+offset,smem_data,sizeof(smem_data));// 7. Wait for TMA transfer to have finished reading shared memory.// Create a "bulk async-group" out of the previous bulk copy operation.ptx::cp_async_bulk_commit_group();// Wait for the group to have completed reading from shared memory.ptx::cp_async_bulk_wait_group_read(ptx::n32_t<0>());}}
TMA 写入与同步。从共享内存到全局内存的写入同样由单个线程发起。写入的完成情况不由共享内存屏障跟踪,而是使用线程局部机制。可以将多个写入合并到一个所谓的批量异步组中。之后,该线程可以等待此组中的所有操作完成对共享内存的读取(如上面的代码所示),也可以等待它们完成对全局内存的写入,使这些写入对发起线程可见。有关更多信息,请参阅cp.async.bulk.wait_group的 PTX ISA 文档。注意,批量异步复制指令与非批量异步复制指令具有不同的异步组:cp.async.wait_group和cp.async.bulk.wait_group指令同时存在。
#include<cooperative_groups.h>#include<cuda/barrier>#include<cuda/ptx>namespaceptx=cuda::ptx;namespacecg=cooperative_groups;__device__inlineboolis_elected(){unsignedinttid=threadIdx.x;unsignedintwarp_id=tid/32;unsignedintuniform_warp_id=__shfl_sync(0xFFFFFFFF,warp_id,0);// Broadcast from lane 0.return(uniform_warp_id==0&&ptx::elect_sync(0xFFFFFFFF));// Elect a leader thread among warp 0.}template<intblock_size,intnum_stages>__global__voidprefetch_kernel(int*global_out,intconst*global_in,size_tsize,size_tbatch_size){autogrid=cg::this_grid();autoblock=cg::this_thread_block();constinttid=threadIdx.x;assert(size==batch_size*grid.size());// Assume input size fits batch_size * grid_size// 1. Initialization Phase__shared__intshared[num_stages*block_size];size_tshared_offset[num_stages];for(ints=0;s<num_stages;++s)shared_offset[s]=s*block.size();autoblock_batch=[&](size_tbatch)->int{returnblock.group_index().x*block.size()+grid.size()*batch;};// Initialize shared memory barrier with the number of threads participating in the barrier.// We will use explicit phase tracking for the barrier, which allows us to have only one // thread arrive on the barrier to set the transaction count and other threads wait for // a parity-based phase flip.#pragma nv_diag_suppress static_var_with_dynamic_init__shared__cuda::barrier<cuda::thread_scope_block>bar[num_stages];if(tid==0){#pragma unroll num_stagesfor(inti=0;i<num_stages;i++){init(&bar[i],1);}}__syncthreads();// Fill the pipeline with the first ``num_stages`` batches.if(is_elected()){size_tnum_bytes=block_size*sizeof(int);#pragma unroll num_stagesfor(ints=0;s<num_stages;++s){cuda::device::memcpy_async_tx(&shared[shared_offset[s]],&global_in[block_batch(s)],cuda::aligned_size_t<16>(num_bytes),bar[s]);(void)cuda::device::barrier_arrive_tx(bar[s],1,num_bytes);}}// 2. Main Processing Loop.// compute_batch: next batch to process.// fetch_batch: next batch to fetch from global memory.intstage=0;// current stage in the shared memory buffer.uint32_tparity=0;// barrierparityfor(size_tcompute_batch=0,fetch_batch=num_stages;compute_batch<batch_size;++compute_batch,++fetch_batch){// (a) Wait on current batch.while(!ptx::mbarrier_try_wait_parity(ptx::sem_acquire,ptx::scope_cta,cuda::device::barrier_native_handle(bar[stage]),parity)){}// (b) Compute on the current batch.compute(global_out+block_batch(compute_batch)+tid,shared+shared_offset[stage]+tid);__syncthreads();// (c) Load next stage ``num_stages`` ahead of current compute batch.if(is_elected()&&fetch_batch<batch_size){size_tnum_bytes=block_size*sizeof(int);cuda::device::memcpy_async_tx(&shared[shared_offset[stage]],&global_in[block_batch(fetch_batch)],cuda::aligned_size_t<16>(num_bytes),bar[stage]);(void)cuda::device::barrier_arrive_tx(bar[stage],1,num_bytes);}// (d) Stage management.stage++;if(stage==num_stages){stage=0;parity^=1;}}}
#include<cudaTypedefs.h> // PFN_cuTensorMapEncodeTiled, CUtensorMapPFN_cuTensorMapEncodeTiled_v12000get_cuTensorMapEncodeTiled(){// Get pointer to cuTensorMapEncodeTiledcudaDriverEntryPointQueryResultdriver_status;void*cuTensorMapEncodeTiled_ptr=nullptr;CUDA_CHECK(cudaGetDriverEntryPointByVersion("cuTensorMapEncodeTiled",&cuTensorMapEncodeTiled_ptr,12000,cudaEnableDefault,&driver_status));assert(driver_status==cudaDriverEntryPointSuccess);returnreinterpret_cast<PFN_cuTensorMapEncodeTiled_v12000>(cuTensorMapEncodeTiled_ptr);}
CUtensorMaptensor_map{};// rank is the number of dimensions of the array.constexpruint32_trank=2;uint64_tsize[rank]={GMEM_WIDTH,GMEM_HEIGHT};// The stride is the number of bytes to traverse from the first element of one row to the next.// It must be a multiple of 16.uint64_tstride[rank-1]={GMEM_WIDTH*sizeof(int)};// The box_size is the size of the shared memory buffer that is used as the// destination of a TMA transfer.uint32_tbox_size[rank]={SMEM_WIDTH,SMEM_HEIGHT};// The distance between elements in units of sizeof(element). A stride of 2// can be used to load only the real component of a complex-valued tensor, for instance.uint32_telem_stride[rank]={1,1};// Get a function pointer to the cuTensorMapEncodeTiled driver API.autocuTensorMapEncodeTiled=get_cuTensorMapEncodeTiled();// Create the tensor descriptor.CUresultres=cuTensorMapEncodeTiled(&tensor_map,// CUtensorMap *tensorMap,CUtensorMapDataType::CU_TENSOR_MAP_DATA_TYPE_INT32,rank,// cuuint32_t tensorRank,tensor_ptr,// void *globalAddress,size,// const cuuint64_t *globalDim,stride,// const cuuint64_t *globalStrides,box_size,// const cuuint32_t *boxDim,elem_stride,// const cuuint32_t *elementStrides,// Interleave patterns can be used to accelerate loading of values that// are less than 4 bytes long.CUtensorMapInterleave::CU_TENSOR_MAP_INTERLEAVE_NONE,// Swizzling can be used to avoid shared memory bank conflicts.CUtensorMapSwizzle::CU_TENSOR_MAP_SWIZZLE_NONE,// L2 Promotion can be used to widen the effect of a cache-policy to a wider// set of L2 cache lines.CUtensorMapL2promotion::CU_TENSOR_MAP_L2_PROMOTION_NONE,// Any element that is outside of bounds will be set to zero by the TMA transfer.CUtensorMapFloatOOBfill::CU_TENSOR_MAP_FLOAT_OOB_FILL_NONE);
从主机到设备的传输。有三种方式可让设备代码访问张量映射。建议将张量映射作为 const__grid_constant__参数传递给核函数。其他可选方式是使用cudaMemcpyToSymbol将张量映射复制到设备的__constant__内存中,或者通过全局内存访问它。将张量映射作为参数传递时,某些版本的 GCC C++ 编译器会发出警告:“用于传递 64 字节对齐参数的 ABI 在 GCC 4.6 中已更改”。此警告可以忽略。
#include<cuda.h>__global__voidkernel(const__grid_constant__CUtensorMaptensor_map){// Use tensor_map here.}intmain(){CUtensorMapmap;// [ ..Initialize map.. ]kernel<<<1,1>>>(map);}
#include<cuda.h>#include<cuda/ptx>namespaceptx=cuda::ptx;__device__CUtensorMapglobal_tensor_map;__global__voidkernel(CUtensorMap*tensor_map){// Fence acquire tensor map:ptx::n32_t<128>size_bytes;// Since the tensor map was modified from the host using cudaMemcpy,// the scope should be .sys.ptx::fence_proxy_tensormap_generic(ptx::sem_acquire,ptx::scope_sys,tensor_map,size_bytes);// Safe to use tensor_map after fence inside this thread.}intmain(){CUtensorMaplocal_tensor_map;// [ ..Initialize map.. ]cudaMemcpy(&global_tensor_map,&local_tensor_map,sizeof(CUtensorMap),cudaMemcpyHostToDevice);kernel<<<1,1>>>(global_tensor_map);}
#include<cuda.h> // CUtensormap#include<cuda/barrier>usingbarrier=cuda::barrier<cuda::thread_scope_block>;namespaceptx=cuda::ptx;__device__inlineboolis_elected(){unsignedinttid=threadIdx.x;unsignedintwarp_id=tid/32;unsignedintuniform_warp_id=__shfl_sync(0xFFFFFFFF,warp_id,0);// Broadcast from lane 0.return(uniform_warp_id==0&&ptx::elect_sync(0xFFFFFFFF));// Elect a leader thread among warp 0.}__global__voidkernel(const__grid_constant__CUtensorMaptensor_map,intx,inty){// The destination shared memory buffer of a bulk tensor operation should be// 128 byte aligned.__shared__alignas(128)intsmem_buffer[SMEM_HEIGHT][SMEM_WIDTH];// Initialize shared memory barrier with the number of threads participating in the barrier.#pragma nv_diag_suppress static_var_with_dynamic_init__shared__barrierbar;if(threadIdx.x==0){// Initialize barrier. All `blockDim.x` threads in block participate.init(&bar,blockDim.x);}// Syncthreads so initialized barrier is visible to all threads.__syncthreads();barrier::arrival_tokentoken;if(is_elected()){// Initiate bulk tensor copy.int32_ttensor_coords[2]={x,y};ptx::cp_async_bulk_tensor(ptx::space_shared,ptx::space_global,&smem_buffer,&tensor_map,tensor_coords,cuda::device::barrier_native_handle(bar));// Arrive on the barrier and tell how many bytes are expected to come in.token=cuda::device::barrier_arrive_tx(bar,1,sizeof(smem_buffer));}else{// Other threads just arrive.token=bar.arrive();}// Wait for the data to have arrived.bar.wait(std::move(token));// Symbolically modify a value in shared memory.smem_buffer[0][threadIdx.x]+=threadIdx.x;// Wait for shared memory writes to be visible to TMA engine.ptx::fence_proxy_async(ptx::space_shared);__syncthreads();// After syncthreads, writes by all threads are visible to TMA engine.// Initiate TMA transfer to copy shared memory to global memoryif(is_elected()){int32_ttensor_coords[2]={x,y};ptx::cp_async_bulk_tensor(ptx::space_global,ptx::space_shared,&tensor_map,tensor_coords,&smem_buffer);// Wait for TMA transfer to have finished reading shared memory.// Create a "bulk async-group" out of the previous bulk copy operation.ptx::cp_async_bulk_commit_group();// Wait for the group to have completed reading from shared memory.ptx::cp_async_bulk_wait_group_read(ptx::n32_t<0>());}// Destroy barrier. This invalidates the memory region of the barrier. If// further computations were to take place in the kernel, this allows the// memory location of the shared memory barrier to be reused.if(threadIdx.x==0){(&bar)->~barrier();}}
// Initialize device context:CUDA_CHECK(cudaDeviceSynchronize());// Create a tensor map template using the cuTensorMapEncodeTiled driver functionCUtensorMaptemplate_tensor_map=make_tensormap_template();// Allocate tensor map and tensor in global memoryCUtensorMap*global_tensor_map;CUDA_CHECK(cudaMalloc(&global_tensor_map,sizeof(CUtensorMap)));char*global_buf;CUDA_CHECK(cudaMalloc(&global_buf,8*256));// Fill global buffer with data.fill_global_buf<<<1,1>>>(global_buf);// Define the parameters of the tensor map that will be created on device.tensormap_paramsp{};p.global_address=global_buf;p.rank=2;p.box_dim[0]=128;// The box in shared memory has half the width of the full bufferp.box_dim[1]=4;// The box in shared memory has half the height of the full bufferp.global_dim[0]=256;//p.global_dim[1]=8;//p.global_stride[0]=256;//p.element_stride[0]=1;//p.element_stride[1]=1;//// Encode global_tensor_map on device:encode_tensor_map<<<1,32>>>(template_tensor_map,p,global_tensor_map);// Use it from another kernel:consume_tensor_map<<<1,1>>>(global_tensor_map);// Check for errors:CUDA_CHECK(cudaDeviceSynchronize());
在 sm_90a 上,也可以使用共享内存中以零初始化的缓冲区作为张量映射的初始值。这使得张量映射可以完全在设备上编码,而无需使用驱动程序 API 来编码template_tensor_mapvalue。
注意
仅分块类型的张量映射支持在设备上修改;其他类型的张量映射无法在设备上修改。有关张量映射类型的更多信息,请参阅驱动程序 API 参考。
#include<cuda/ptx>namespaceptx=cuda::ptx;// launch with 1 warp.__launch_bounds__(32)__global__voidencode_tensor_map(const__grid_constant__CUtensorMaptemplate_tensor_map,tensormap_paramsp,CUtensorMap*out){__shared__alignas(128)CUtensorMapsmem_tmap;if(threadIdx.x==0){// Copy template to shared memory:smem_tmap=template_tensor_map;constautospace_shared=ptx::space_shared;ptx::tensormap_replace_global_address(space_shared,&smem_tmap,p.global_address);// For field .rank, the operand new_val must be ones less than the desired// tensor rank as this field uses zero-based numbering.ptx::tensormap_replace_rank(space_shared,&smem_tmap,p.rank-1);// Set box dimensions:if(0<p.rank){ptx::tensormap_replace_box_dim(space_shared,&smem_tmap,ptx::n32_t<0>{},p.box_dim[0]);}if(1<p.rank){ptx::tensormap_replace_box_dim(space_shared,&smem_tmap,ptx::n32_t<1>{},p.box_dim[1]);}if(2<p.rank){ptx::tensormap_replace_box_dim(space_shared,&smem_tmap,ptx::n32_t<2>{},p.box_dim[2]);}if(3<p.rank){ptx::tensormap_replace_box_dim(space_shared,&smem_tmap,ptx::n32_t<3>{},p.box_dim[3]);}if(4<p.rank){ptx::tensormap_replace_box_dim(space_shared,&smem_tmap,ptx::n32_t<4>{},p.box_dim[4]);}// Set global dimensions:if(0<p.rank){ptx::tensormap_replace_global_dim(space_shared,&smem_tmap,ptx::n32_t<0>{},(uint32_t)p.global_dim[0]);}if(1<p.rank){ptx::tensormap_replace_global_dim(space_shared,&smem_tmap,ptx::n32_t<1>{},(uint32_t)p.global_dim[1]);}if(2<p.rank){ptx::tensormap_replace_global_dim(space_shared,&smem_tmap,ptx::n32_t<2>{},(uint32_t)p.global_dim[2]);}if(3<p.rank){ptx::tensormap_replace_global_dim(space_shared,&smem_tmap,ptx::n32_t<3>{},(uint32_t)p.global_dim[3]);}if(4<p.rank){ptx::tensormap_replace_global_dim(space_shared,&smem_tmap,ptx::n32_t<4>{},(uint32_t)p.global_dim[4]);}// Set global stride:if(1<p.rank){ptx::tensormap_replace_global_stride(space_shared,&smem_tmap,ptx::n32_t<0>{},p.global_stride[0]);}if(2<p.rank){ptx::tensormap_replace_global_stride(space_shared,&smem_tmap,ptx::n32_t<1>{},p.global_stride[1]);}if(3<p.rank){ptx::tensormap_replace_global_stride(space_shared,&smem_tmap,ptx::n32_t<2>{},p.global_stride[2]);}if(4<p.rank){ptx::tensormap_replace_global_stride(space_shared,&smem_tmap,ptx::n32_t<3>{},p.global_stride[3]);}// Set element stride:if(0<p.rank){ptx::tensormap_replace_element_size(space_shared,&smem_tmap,ptx::n32_t<0>{},p.element_stride[0]);}if(1<p.rank){ptx::tensormap_replace_element_size(space_shared,&smem_tmap,ptx::n32_t<1>{},p.element_stride[1]);}if(2<p.rank){ptx::tensormap_replace_element_size(space_shared,&smem_tmap,ptx::n32_t<2>{},p.element_stride[2]);}if(3<p.rank){ptx::tensormap_replace_element_size(space_shared,&smem_tmap,ptx::n32_t<3>{},p.element_stride[3]);}if(4<p.rank){ptx::tensormap_replace_element_size(space_shared,&smem_tmap,ptx::n32_t<4>{},p.element_stride[4]);}// These constants are documented in this table:// https://docs.nvidia.com/cuda/parallel-thread-execution/index.html#tensormap-new-val-validityautou8_elem_type=ptx::n32_t<0>{};ptx::tensormap_replace_elemtype(space_shared,&smem_tmap,u8_elem_type);autono_interleave=ptx::n32_t<0>{};ptx::tensormap_replace_interleave_layout(space_shared,&smem_tmap,no_interleave);autono_swizzle=ptx::n32_t<0>{};ptx::tensormap_replace_swizzle_mode(space_shared,&smem_tmap,no_swizzle);autozero_fill=ptx::n32_t<0>{};ptx::tensormap_replace_fill_mode(space_shared,&smem_tmap,zero_fill);}// Synchronize the modifications with other threads in warp__syncwarp();// Copy the tensor map to global memory collectively with threads in the warp.// In addition: make the updated tensor map visible to other threads on device that// for use with cp.async.bulk.ptx::n32_t<128>bytes_128;ptx::tensormap_cp_fenceproxy(ptx::sem_release,ptx::scope_gpu,out,&smem_tmap,bytes_128);}
获取部分通过cuda::ptx::fence_proxy_tensormap_generic函数实现,该函数封装了fence.proxy.tensormap::generic.acquire指令。如果参与释放-获取模式的两个线程位于同一设备上,使用.gpu作用域即可。如果这些线程位于不同设备上,则必须使用.sys作用域。一旦某个线程获取了张量映射,在经过充分同步后(例如使用__syncthreads()),线程块中的其他线程就可以使用它。使用张量映射的线程和执行栅栏的线程必须位于同一线程块中。也就是说,如果这些线程分别位于不同线程块中,例如位于同一簇、同一网格或不同核函数的两个不同线程块中,那么cooperative_groups::cluster或grid_group::sync()之类的同步 API 或流顺序同步不足以为张量映射更新建立顺序关系,也就是说,这些其他线程块中的线程在使用更新后的张量映射之前,仍需要在正确的作用域获取张量映射代理。如果中间没有发生修改,则不必在每条cp.async.bulk.tensor指令之前重复执行栅栏。
以下示例展示了fence以及张量映射的后续使用。
// Consumer of tensor map in global memory:__global__voidconsume_tensor_map(CUtensorMap*tensor_map){// Fence acquire tensor map:ptx::n32_t<128>size_bytes;ptx::fence_proxy_tensormap_generic(ptx::sem_acquire,ptx::scope_sys,tensor_map,size_bytes);// Safe to use tensor_map after fence.__shared__uint64_tbar;__shared__alignas(128)charsmem_buf[4][128];if(threadIdx.x==0){// Initialize barrierptx::mbarrier_init(&bar,1);// Issue TMA requestptx::cp_async_bulk_tensor(ptx::space_cluster,ptx::space_global,smem_buf,tensor_map,{0,0},&bar);// Arrive on barrier. Expect 4 * 128 bytes.ptx::mbarrier_arrive_expect_tx(ptx::sem_release,ptx::scope_cta,ptx::space_shared,&bar,sizeof(smem_buf));}constintparity=0;// Wait for load to have completedwhile(!ptx::mbarrier_try_wait_parity(&bar,parity)){}// print items:printf("Got:\n\n");for(intj=0;j<4;++j){for(inti=0;i<128;++i){printf("%3d ",smem_buf[j][i]);if(i%32==31){printf("\n");};}printf("\n");}}
__global__voidkernel_tma(const__grid_constant__CUtensorMaptensor_map){// The destination shared memory buffer of a bulk tensor operation// with the 128-byte swizzle mode, it should be 1024 bytes aligned.__shared__alignas(1024)int4smem_buffer[8][8];__shared__alignas(1024)int4smem_buffer_tr[8][8];// Initialize shared memory barrier#pragma nv_diag_suppress static_var_with_dynamic_init__shared__barrierbar;if(threadIdx.x==0){init(&bar,blockDim.x);}__syncthreads();barrier::arrival_tokentoken;if(is_elected()){// Initiate bulk tensor copy from global to shared memory,// in the same way as without swizzle.int32_ttensor_coords[2]={0,0};ptx::cp_async_bulk_tensor(ptx::space_shared,ptx::space_global,&smem_buffer,&tensor_map,tensor_coords,cuda::device::barrier_native_handle(bar));token=cuda::device::barrier_arrive_tx(bar,1,sizeof(smem_buffer));}else{token=bar.arrive();}bar.wait(std::move(token));/* Matrix transpose * When using the normal shared memory layout, there are eight * 8-way shared memory bank conflict when storing to the transpose. * When enabling the 128-byte swizzle pattern and using the according access pattern, * they are eliminated both for load and store. */for(intsidx_j=threadIdx.x;sidx_j<8;sidx_j+=blockDim.x){for(intsidx_i=0;sidx_i<8;++sidx_i){constintswiz_j_idx=(sidx_i%8)^sidx_j;constintswiz_i_idx_tr=(sidx_j%8)^sidx_i;smem_buffer_tr[sidx_j][swiz_i_idx_tr]=smem_buffer[sidx_i][swiz_j_idx];}}// Wait for shared memory writes to be visible to TMA engine.ptx::fence_proxy_async(ptx::space_shared);__syncthreads();/* Initiate TMA transfer to copy the transposed shared memory buffer back to global memory, * it will 'unswizzle' the data. */if(is_elected()){int32_ttensor_coords[2]={x,y};ptx::cp_async_bulk_tensor(ptx::space_global,ptx::space_shared,&tensor_map,tensor_coords,&smem_buffer_tr);ptx::cp_async_bulk_commit_group();ptx::cp_async_bulk_wait_group_read(ptx::n32_t<0>());}// Destroy barrierif(threadIdx.x==0){(&bar)->~barrier();}}// --------------------------------- main ----------------------------------------intmain(){...void*tensor_ptr=d_data;CUtensorMaptensor_map{};// rank is the number of dimensions of the array.constexpruint32_trank=2;// global memory sizeuint64_tsize[rank]={4*8,8};// global memory stride, must be a multiple of 16.uint64_tstride[rank-1]={8*sizeof(int4)};// The inner shared memory box dimension in bytes, equal to the swizzle span.uint32_tbox_size[rank]={4*8,8};uint32_telem_stride[rank]={1,1};// Create the tensor descriptor.CUresultres=cuTensorMapEncodeTiled(&tensor_map,// CUtensorMap *tensorMap,CUtensorMapDataType::CU_TENSOR_MAP_DATA_TYPE_INT32,rank,// cuuint32_t tensorRank,tensor_ptr,// void *globalAddress,size,// const cuuint64_t *globalDim,stride,// const cuuint64_t *globalStrides,box_size,// const cuuint32_t *boxDim,elem_stride,// const cuuint32_t *elementStrides,CUtensorMapInterleave::CU_TENSOR_MAP_INTERLEAVE_NONE,// Using a swizzle pattern of 128 bytes.CUtensorMapSwizzle::CU_TENSOR_MAP_SWIZZLE_128B,CUtensorMapL2promotion::CU_TENSOR_MAP_L2_PROMOTION_NONE,CUtensorMapFloatOOBfill::CU_TENSOR_MAP_FLOAT_OOB_FILL_NONE);kernel_tma<<<1,8>>>(tensor_map);...}
#include<cooperative_groups.h>#include<cuda/barrier>#include<cuda/ptx>__global____cluster_dims__(8,1,1)voidproducer_consumer_kernel(){usingnamespacecooperative_groups;usingnamespacecuda::device;usingnamespacecuda::ptx;usingbarrier_t=cuda::barrier<cuda::thread_scope_block>;autocluster=this_cluster();#pragma nv_diag_suppress static_var_with_dynamic_init__shared__intbuffer[BLOCK_SIZE];__shared__barrier_tfilled;__shared__barrier_tready;// Initialize shared memory barriers.if(threadIdx.x==0){init(&filled,1);init(&ready,BLOCK_SIZE);}// Sync cluster to ensure remote barriers are initialized.cluster.sync();// Define my own and my neighbor's ranks.intrk=cluster.block_rank();intrk_next=(rk+1)%8;intrk_prev=(rk+7)%8;// Get addresses of remote buffer we are writing to and remote barriers of previous and next blocks.autobuffer_next=cluster.map_shared_rank(buffer,rk_next);autobar_next=cluster.map_shared_rank(barrier_native_handle(filled),rk_next);autobar_prev=cluster.map_shared_rank(barrier_native_handle(ready),rk_prev);intphase=0;for(intit=0;it<1000;++it){// As producers, send data to our right neighbor.st_async(&buffer_next[threadIdx.x],rk,bar_next);if(threadIdx.x==0){// Thread 0 arrives on local barrier and indicates it expects to receive a certain number of bytes.mbarrier_arrive_expect_tx(sem_release,scope_cluster,space_shared,barrier_native_handle(filled),sizeof(buffer));}// As consumers, wait on local barrier for data from left neighbor to arrive.while(!mbarrier_try_wait_parity(barrier_native_handle(filled),phase,1000)){}// At this point, the data has been copied to our local buffer.intr=buffer[threadIdx.x];// Use the data to do something.// As consumers, notify our left neighbor that we are done with the data.mbarrier_arrive(sem_release,scope_cluster,space_cluster,bar_prev);// As producers, wait on local barrier until the right neighbor is ready to receive new data.while(!mbarrier_try_wait_parity(barrier_native_handle(ready),phase,1000)){}phase^=1;}}
boolsuccess=ptx::clusterlaunchcontrol_query_cancel_is_canceled(result);if(success){// Don't need all three for 1D/2D thread blocks:intbx=ptx::clusterlaunchcontrol_query_cancel_get_first_ctaid_x(result);intby=ptx::clusterlaunchcontrol_query_cancel_get_first_ctaid_y(result);intbz=ptx::clusterlaunchcontrol_query_cancel_get_first_ctaid_z(result);}
// First request:ptx::clusterlaunchcontrol_try_cancel(&result0,&bar0);// First request query:[Synchronizebar0codehere.]boolsuccess0=ptx::clusterlaunchcontrol_query_cancel_is_canceled(result0);assert(!success0);// Observed failure; second cancellation will be invalid.// Second request - next line is Undefined Behavior:ptx::clusterlaunchcontrol_try_cancel(&result1,&bar1);
有效代码:
// First request:ptx::clusterlaunchcontrol_try_cancel(&result0,&bar0);// Second request:ptx::clusterlaunchcontrol_try_cancel(&result1,&bar1);// First request query:[Synchronizebar0codehere.]boolsuccess0=ptx::clusterlaunchcontrol_query_cancel_is_canceled(result0);assert(!success0);// Observed failure; second cancellation was valid.
#include<cooperative_groups.h>#include<cuda/ptx>namespacecg=cooperative_groups;namespaceptx=cuda::ptx;__global__voidkernel_cluster_launch_control(float*data,intn){// Cluster launch control initialization:__shared__uint4result;__shared__uint64_tbar;intphase=0;if(cg::thread_block::thread_rank()==0)ptx::mbarrier_init(&bar,1);// Prologue:floatalpha=compute_scalar();// Device function not shown in this code snippet.// Work-stealing loop:intbx=blockIdx.x;// Assuming 1D x-axis thread blocks.while(true){// Protect result from overwrite in the next iteration,// (also ensure barrier initialization at 1st iteration):__syncthreads();// Cancellation request:if(cg::thread_block::thread_rank()==0){// Acquire write of result in the async proxy:ptx::fence_proxy_async_generic_sync_restrict(ptx::sem_acquire,ptx::space_cluster,ptx::scope_cluster);cg::invoke_one(cg::coalesced_threads(),[&](){ptx::clusterlaunchcontrol_try_cancel(&result,&bar);});ptx::mbarrier_arrive_expect_tx(ptx::sem_relaxed,ptx::scope_cta,ptx::space_shared,&bar,sizeof(uint4));}// Computation:inti=bx*blockDim.x+threadIdx.x;if(i<n)data[i]*=alpha;// Cancellation request synchronization:while(!ptx::mbarrier_try_wait_parity(ptx::sem_acquire,ptx::scope_cta,&bar,phase)){}phase^=1;// Cancellation request decoding:boolsuccess=ptx::clusterlaunchcontrol_query_cancel_is_canceled(result);if(!success)break;bx=ptx::clusterlaunchcontrol_query_cancel_get_first_ctaid_x<int>(result);// Release read of result to the async proxy:ptx::fence_proxy_async_generic_sync_restrict(ptx::sem_release,ptx::space_shared,ptx::scope_cluster);}}// Launch: kernel_cluster_launch_control<<<(n + 1023) / 1024, 1024>>>(data, n);
在簇的情况下,取消操作要求所有线程块都存在。用户可以通过使用sync API 中的cg::cluster_group::sync()来保证所有线程块都在运行。
下面的核函数演示了使用线程块簇的簇启动控制方法。
#include<cooperative_groups.h>#include<cuda/ptx>namespacecg=cooperative_groups;namespaceptx=cuda::ptx;__global____cluster_dims__(2,1,1)voidkernel_cluster_launch_control(float*data,intn){// Cluster launch control initialization:__shared__uint4result;__shared__uint64_tbar;intphase=0;if(cg::thread_block::thread_rank()==0){ptx::mbarrier_init(&bar,1);ptx::fence_mbarrier_init(ptx::sem_release,ptx::scope_cluster);// CGA-level fence.}// Prologue:floatalpha=compute_scalar();// Device function not shown in this code snippet.// Work-stealing loop:intbx=blockIdx.x;// Assuming 1D x-axis thread blocks.while(true){// Protect result from overwrite in the next iteration,// (also ensure all thread blocks have started at 1st iteration):cg::cluster_group::sync();// Cancellation request by a single cluster thread:if(cg::cluster_group::thread_rank()==0){// Acquire write of result in the async proxy:ptx::fence_proxy_async_generic_sync_restrict(ptx::sem_acquire,ptx::space_cluster,ptx::scope_cluster);cg::invoke_one(cg::coalesced_threads(),[&](){ptx::clusterlaunchcontrol_try_cancel_multicast(&result,&bar);});}// Cancellation completion tracked by each thread block:if(cg::thread_block::thread_rank()==0)ptx::mbarrier_arrive_expect_tx(ptx::sem_relaxed,ptx::scope_cluster,ptx::space_shared,&bar,sizeof(uint4));// Computation:inti=bx*blockDim.x+threadIdx.x;if(i<n)data[i]*=alpha;// Cancellation request synchronization:while(!ptx::mbarrier_try_wait_parity(ptx::sem_acquire,ptx::scope_cluster,&bar,phase)){}phase^=1;// Cancellation request decoding:boolsuccess=ptx::clusterlaunchcontrol_query_cancel_is_canceled(result);if(!success)break;bx=ptx::clusterlaunchcontrol_query_cancel_get_first_ctaid_x<int>(result);bx+=cg::cluster_group::block_index().x;// Add local offset.// Release read of result to the async proxy:ptx::fence_proxy_async_generic_sync_restrict(ptx::sem_release,ptx::space_shared,ptx::scope_cluster);}}// Launch: kernel_cluster_launch_control<<<(n + 1023) / 1024, 1024>>>(data, n);
4.14. L2 缓存控制
当 CUDA 核函数反复访问全局内存中的某个数据区域时,此类数据访问可视为持久访问。另一方面,如果数据只被访问一次,则此类数据访问可视为流式访问。
cudaGetDeviceProperties(&prop,device_id);size_tsize=min(int(prop.l2CacheSize*0.75),prop.persistingL2CacheMaxSize);cudaDeviceSetLimit(cudaLimitPersistingL2CacheSize,size);/* set-aside 3/4 of L2 cache for persisting accesses or the max allowed*/
cudaStreamAttrValuestream_attribute;// Stream level attributes data structurestream_attribute.accessPolicyWindow.base_ptr=reinterpret_cast<void*>(ptr);// Global Memory data pointerstream_attribute.accessPolicyWindow.num_bytes=num_bytes;// Number of bytes for persistence access.// (Must be less than cudaDeviceProp::accessPolicyMaxWindowSize)stream_attribute.accessPolicyWindow.hitRatio=0.6;// Hint for cache hit ratiostream_attribute.accessPolicyWindow.hitProp=cudaAccessPropertyPersisting;// Type of access property on cache hitstream_attribute.accessPolicyWindow.missProp=cudaAccessPropertyStreaming;// Type of access property on cache miss.//Set the attributes to a CUDA stream of type cudaStream_tcudaStreamSetAttribute(stream,cudaStreamAttributeAccessPolicyWindow,&stream_attribute);
cudaKernelNodeAttrValuenode_attribute;// Kernel level attributes data structurenode_attribute.accessPolicyWindow.base_ptr=reinterpret_cast<void*>(ptr);// Global Memory data pointernode_attribute.accessPolicyWindow.num_bytes=num_bytes;// Number of bytes for persistence access.// (Must be less than cudaDeviceProp::accessPolicyMaxWindowSize)node_attribute.accessPolicyWindow.hitRatio=0.6;// Hint for cache hit rationode_attribute.accessPolicyWindow.hitProp=cudaAccessPropertyPersisting;// Type of access property on cache hitnode_attribute.accessPolicyWindow.missProp=cudaAccessPropertyStreaming;// Type of access property on cache miss.//Set the attributes to a CUDA Graph Kernel node of type cudaGraphNode_tcudaGraphKernelNodeSetAttribute(node,cudaKernelNodeAttributeAccessPolicyWindow,&node_attribute);
cudaAccessPropertyNormal:此访问属性会将先前应用的持久访问属性强制重置为普通状态。先前 CUDA 核函数中具有持久属性的内存访问,可能在其预期用途结束后很长时间内仍保留在 L2 缓存中。这种使用后仍持久保留的行为,会减少后续不使用持久属性的核函数可用的 L2 缓存量。使用cudaAccessPropertyNormal属性重置访问属性窗口,会移除先前访问的持久(优先保留)状态,就像先前的访问未带有访问属性一样。
4.14.4. L2 持久性示例
以下示例展示了如何为持久访问预留 L2 缓存,如何在 CUDA 核函数中通过 CUDA 流使用预留的 L2 缓存,以及如何随后重置 L2 缓存。
cudaStream_tstream;cudaStreamCreate(&stream);// Create CUDA streamcudaDevicePropprop;// CUDA device properties variablecudaGetDeviceProperties(&prop,device_id);// Query GPU propertiessize_tsize=min(int(prop.l2CacheSize*0.75),prop.persistingL2CacheMaxSize);cudaDeviceSetLimit(cudaLimitPersistingL2CacheSize,size);// set-aside 3/4 of L2 cache for persisting accesses or the max allowedsize_twindow_size=min(prop.accessPolicyMaxWindowSize,num_bytes);// Select minimum of user defined num_bytes and max window size.cudaStreamAttrValuestream_attribute;// Stream level attributes data structurestream_attribute.accessPolicyWindow.base_ptr=reinterpret_cast<void*>(data1);// Global Memory data pointerstream_attribute.accessPolicyWindow.num_bytes=window_size;// Number of bytes for persistence accessstream_attribute.accessPolicyWindow.hitRatio=0.6;// Hint for cache hit ratiostream_attribute.accessPolicyWindow.hitProp=cudaAccessPropertyPersisting;// Persistence Propertystream_attribute.accessPolicyWindow.missProp=cudaAccessPropertyStreaming;// Type of access property on cache misscudaStreamSetAttribute(stream,cudaStreamAttributeAccessPolicyWindow,&stream_attribute);// Set the attributes to a CUDA Streamfor(inti=0;i<10;i++){cuda_kernelA<<<grid_size,block_size,0,stream>>>(data1);// This data1 is used by a kernel multiple times}// [data1 + num_bytes) benefits from L2 persistencecuda_kernelB<<<grid_size,block_size,0,stream>>>(data1);// A different kernel in the same stream can also benefit// from the persistence of data1stream_attribute.accessPolicyWindow.num_bytes=0;// Setting the window size to 0 disable itcudaStreamSetAttribute(stream,cudaStreamAttributeAccessPolicyWindow,&stream_attribute);// Overwrite the access policy attribute to a CUDA StreamcudaCtxResetPersistingL2Cache();// Remove any persistent lines in L2cuda_kernelC<<<grid_size,block_size,0,stream>>>(data2);// data2 can now benefit from full L2 in normal mode
在不同 CUDA 流中并发执行的多个 CUDA 核函数,其所在的流可能各自分配了不同的访问策略窗口。但是,L2 预留缓存部分由所有这些并发 CUDA 核函数共享。因此,这部分预留缓存的净使用量是所有并发核函数各自使用量的总和。当持久访问的数据量超过 L2 预留缓存容量时,将内存访问指定为持久访问所带来的收益就会降低。
要管理 L2 缓存预留部分的利用情况,应用程序必须考虑以下因素:
L2 预留缓存的大小。
可能并发执行的 CUDA 核函数。
所有可能并发执行的 CUDA 核函数的访问策略窗口。
何时以及如何重置 L2,才能使普通访问或流式访问以相同的优先级使用先前预留的 L2 缓存。
4.14.7. 查询 L2 缓存属性
与 L2 缓存相关的属性是cudaDeviceProp结构体的一部分,可以使用 CUDA 运行时 APIcudaGetDeviceProperties进行查询
CUDA 设备属性包括:
l2CacheSize:GPU 上可用的 L2 缓存量。
persistingL2CacheMaxSize:可为持久内存访问预留的最大 L2 缓存量。
accessPolicyMaxWindowSize:访问策略窗口的最大大小。
4.14.8. 控制为持久内存访问预留的 L2 缓存大小
为持久内存访问预留的 L2 缓存大小可使用 CUDA 运行时 APIcudaDeviceGetLimit查询,并使用 CUDA 运行时 APIcudaDeviceSetLimit将其作为cudaLimit进行设置。设置此限制时的最大值为cudaDeviceProp::persistingL2CacheMaxSize。
enumcudaLimit{/* other fields not shown */cudaLimitPersistingL2CacheSize};
4.15. 内存同步域
4.15.1. 内存栅栏干扰
某些 CUDA 应用程序可能会出现性能下降,因为内存栅栏或刷新操作等待的事务多于 CUDA 内存一致性模型所要求的事务。
逻辑域的存在便于应用程序组合。在软件栈较低层级进行的单次核函数启动(例如来自 NCCL 的启动)可以选择一个具有语义意义的逻辑域,而无需关心周围的应用程序架构。较高层级可以使用映射来调控逻辑域。如果未设置逻辑域,其默认值为默认域;默认映射将默认域映射到 0,将远程域映射到 1(在具有多于 1 个域的 GPU 上)。在 CUDA 12.0 及更高版本中,某些特定库可能会将启动标记为远程域;例如,NCCL 2.16 会这样做。这些机制共同为常见应用程序提供了一种开箱即用的有益使用模式,无需更改其他组件、框架或应用程序层面的代码。另一种使用模式可能是对并行流进行划分,例如在使用 NVSHMEM 或核函数类型没有明确区分的应用程序中。流 A 可以将两个逻辑域都映射到物理域 0,流 B 则映射到 1,依此类推。
// Example of launching a kernel with the remote logical domaincudaLaunchAttributedomainAttr;domainAttr.id=cudaLaunchAttrMemSyncDomain;domainAttr.val=cudaLaunchMemSyncDomainRemote;cudaLaunchConfig_tconfig;// Fill out other config fieldsconfig.attrs=&domainAttr;config.numAttrs=1;cudaLaunchKernelEx(&config,myKernel,kernelArg1,kernelArg2...);
// Example of setting a mapping for a stream// (This mapping is the default for streams starting on compute capability 9.0 (Hopper) or later if not// explicitly set, and provided for illustration)cudaLaunchAttributeValuemapAttr;mapAttr.memSyncDomainMap.default_=0;mapAttr.memSyncDomainMap.remote=1;cudaStreamSetAttribute(stream,cudaLaunchAttributeMemSyncDomainMap,&mapAttr);
// Example of mapping different streams to different physical domains, ignoring// logical domain settingscudaLaunchAttributeValuemapAttr;mapAttr.memSyncDomainMap.default_=0;mapAttr.memSyncDomainMap.remote=0;cudaStreamSetAttribute(streamA,cudaLaunchAttributeMemSyncDomainMap,&mapAttr);mapAttr.memSyncDomainMap.default_=1;mapAttr.memSyncDomainMap.remote=1;cudaStreamSetAttribute(streamB,cudaLaunchAttributeMemSyncDomainMap,&mapAttr);
与其他启动属性一样,这些属性以统一的方式提供给 CUDA 流、使用cudaLaunchKernelEx的单次启动以及 CUDA 图中的核函数节点。典型用法是在流级别设置映射,并在启动级别设置逻辑域(或在流的一段使用区间前后设置),如上所述。
由主机线程创建的任何设备内存指针或事件句柄,都可以由同一进程中的任何其他线程直接引用。但是,设备指针或事件句柄在创建它们的进程之外无效,因此不能由属于不同进程的线程直接引用。要跨进程访问设备内存和 CUDA 事件,应用程序必须使用 CUDA 进程间通信(IPC)或虚拟内存管理 API,创建可跨进程使用的句柄,并通过标准主机操作系统 IPC 机制(例如进程间共享内存或文件)与其他进程共享这些句柄。在进程之间交换了可跨进程使用的句柄之后,必须使用 CUDA IPC 或 VMM API 从句柄获取进程局部的设备指针。随后,进程局部的设备指针就可以像在单个进程中一样使用。
CUDA 虚拟内存管理 API 允许创建可通过 IPC 共享的内存分配,并借助特定于操作系统的 IPC 句柄数据结构来支持多种操作系统。
4.17. 虚拟内存管理
在 CUDA 编程模型中,内存分配调用(例如cudaMalloc())返回 GPU 内存中的一个内存地址。该地址可用于任何 CUDA API,也可用于设备核函数内部。开发者可以使用cudaEnablePeerAccess启用对等设备对这些内存分配的访问。这样,不同设备上的核函数就可以访问相同的数据。但是,所有过去和未来的用户分配也都会映射到目标对等设备。这可能导致用户无意中承担将所有cudaMalloc分配的内存映射到对等设备的运行时开销。在大多数情况下,应用程序只需与另一台设备共享少量内存分配即可进行通信。通常没有必要将所有内存分配映射到所有设备。此外,将这种方法扩展到多节点环境本身就存在困难。
CUDA 的 VMM API 允许开发者显式保留虚拟地址范围,然后再将其映射到物理 GPU 内存,从而将类似的概念引入 GPU 内存管理。借助 VMM,应用程序可以明确选择允许其他设备访问的某些内存分配。
VMM API 使复杂应用程序能够更高效地管理多个 GPU(以及 CPU 核心)上的内存。通过支持对内存保留、映射和访问权限进行手动控制,VMM API 可以实现细粒度数据共享、零拷贝传输和自定义内存分配器等高级技术。CUDA VMM API 向用户提供了细粒度控制能力,用于管理应用程序中的 GPU 内存。
内存句柄:在 VMM 中,句柄是代表物理内存分配的不透明标识符。这些句柄是底层 CUDA VMM API 中内存管理的核心。它们支持对可映射到虚拟地址空间的物理内存对象进行灵活控制。一个句柄唯一标识一项物理内存分配。句柄充当对内存资源的抽象引用,而不暴露直接指针。句柄允许执行跨进程或设备导出和导入内存等操作,从而促进内存共享和虚拟化。
单播内存访问:在 VMM API 的上下文中,单播内存访问是指由特定设备或进程将物理内存受控地直接映射到唯一的虚拟地址范围并进行访问。单播内存访问并非将访问广播到多个设备,而是向某个特定 GPU 设备显式授予对某个保留虚拟地址范围的读写权限,该范围映射到一项物理内存分配。
多播内存访问:在 VMM API 的上下文中,多播内存访问是指使用多播机制,将单个物理内存分配或区域同时映射到多个设备的虚拟地址空间的能力。这使数据能够以一对多的方式在多个 GPU 之间高效共享,减少冗余数据传输并提高通信效率。NVIDIA 的 CUDA VMM API 支持创建多播对象,将来自多个设备的物理内存分配绑定在一起。
VMM API 的工作流程包含一系列内存管理步骤,重点是在不同设备或进程之间共享内存。首先,开发者必须在源设备上分配物理内存。为便于共享,VMM API 使用句柄向目标设备或进程传递必要的信息。用户必须导出一个用于共享的句柄,该句柄可以是特定于操作系统的句柄,也可以是特定于互连网络(fabric)的句柄。特定于操作系统的句柄仅限于单个节点上的进程间通信,而特定于互连网络(fabric)的句柄用途更加广泛,既可用于单节点环境,也可用于多节点环境。需要注意的是,使用特定于互连网络(fabric)的句柄需要启用 IMEX 通道。
句柄导出后,必须使用进程间通信协议将其共享给一个或多个接收进程,具体方法由开发者选择。然后,接收进程使用 VMM API 导入句柄。在句柄成功导出、共享和导入后,源进程和目标进程都必须预留虚拟地址空间,以便将所分配的物理内存映射到该空间。最后一步是为每个设备设置内存访问权限,确保建立适当的权限。附图进一步详细说明了整个过程,包括两种句柄方案。
分配物理内存使用虚拟内存管理 API 分配内存的第一步是创建一个物理内存块,为该分配提供后备存储。要分配物理内存,应用程序必须使用cuMemCreate API。此函数创建的分配没有任何设备或主机映射。函数参数CUmemGenericAllocationHandle描述了要分配的内存的属性,例如分配的位置、该分配是否将共享给另一个进程(或图形 API),或者要分配的内存的物理属性。用户必须确保请求的分配大小按适当的粒度对齐。可以使用cuMemGetAllocationGranularity查询有关分配粒度要求的信息。
CUmemGenericAllocationHandleallocatePhysicalMemory(intdevice,size_tsize){CUmemAllocationHandleTypehandleType=CU_MEM_HANDLE_TYPE_POSIX_FILE_DESCRIPTOR;CUmemAllocationPropprop={};prop.type=CU_MEM_ALLOCATION_TYPE_PINNED;prop.location.type=CU_MEM_LOCATION_TYPE_DEVICE;prop.location.id=device;prop.requestedHandleType=handleType;size_tgranularity=0;cuMemGetAllocationGranularity(&granularity,&prop,CU_MEM_ALLOC_GRANULARITY_MINIMUM);// Ensure size matches granularity requirements for the allocationsize_tpadded_size=ROUND_UP(size,granularity);// Allocate physical memoryCUmemGenericAllocationHandleallocHandle;cuMemCreate(&allocHandle,padded_size,&prop,0);returnallocHandle;}
CUmemGenericAllocationHandleallocatePhysicalMemory(intdevice,size_tsize){CUmemAllocationHandleTypehandleType=CU_MEM_HANDLE_TYPE_FABRIC;CUmemAllocationPropprop={};prop.type=CU_MEM_ALLOCATION_TYPE_PINNED;prop.location.type=CU_MEM_LOCATION_TYPE_DEVICE;prop.location.id=device;prop.requestedHandleType=handleType;size_tgranularity=0;cuMemGetAllocationGranularity(&granularity,&prop,CU_MEM_ALLOC_GRANULARITY_MINIMUM);// Ensure size matches granularity requirements for the allocationsize_tpadded_size=ROUND_UP(size,granularity);// Allocate physical memoryCUmemGenericAllocationHandleallocHandle;cuMemCreate(&allocHandle,padded_size,&prop,0);returnallocHandle;}
intipcSendShareableHandle(intsocket,intfd,pid_tprocess){structmsghdrmsg;structioveciov[1];union{structcmsghdrcm;char*control;}control_un;size_tsizeof_control=CMSG_SPACE(sizeof(int))*sizeof(char);control_un.control=(char*)malloc(sizeof_control);structcmsghdr*cmptr;ssize_treadResult;structsockaddr_uncliaddr;socklen_tlen=sizeof(cliaddr);// Construct client address to send this SHareable handle tomemset(&cliaddr,0,sizeof(cliaddr));cliaddr.sun_family=AF_UNIX;chartemp[20];sprintf(temp,"%s%u","/tmp/",process);strcpy(cliaddr.sun_path,temp);len=sizeof(cliaddr);// Send corresponding shareable handle to the clientintsendfd=fd;msg.msg_control=control_un.control;msg.msg_controllen=sizeof_control;cmptr=CMSG_FIRSTHDR(&msg);cmptr->cmsg_len=CMSG_LEN(sizeof(int));cmptr->cmsg_level=SOL_SOCKET;cmptr->cmsg_type=SCM_RIGHTS;memmove(CMSG_DATA(cmptr),&sendfd,sizeof(sendfd));msg.msg_name=(void*)&cliaddr;msg.msg_namelen=sizeof(structsockaddr_un);iov[0].iov_base=(void*)"";iov[0].iov_len=1;msg.msg_iov=iov;msg.msg_iovlen=1;ssize_tsendResult=sendmsg(socket,&msg,0);if(sendResult<=0){perror("IPC failure: Sending data over socket failed");free(control_un.control);return-1;}free(control_un.control);return0;}
intipcRecvShareableHandle(intsocket,int*fd){structmsghdrmsg={0};structioveciov[1];structcmsghdrcm;// Union to guarantee alignment requirements for control arrayunion{structcmsghdrcm;// This will not work on QNX as QNX CMSG_SPACE calls __cmsg_alignbytes// And __cmsg_alignbytes is a runtime function instead of compile-time macros// char control[CMSG_SPACE(sizeof(int))]char*control;}control_un;size_tsizeof_control=CMSG_SPACE(sizeof(int))*sizeof(char);control_un.control=(char*)malloc(sizeof_control);structcmsghdr*cmptr;ssize_tn;intreceivedfd;chardummy_buffer[1];ssize_tsendResult;msg.msg_control=control_un.control;msg.msg_controllen=sizeof_control;iov[0].iov_base=(void*)dummy_buffer;iov[0].iov_len=sizeof(dummy_buffer);msg.msg_iov=iov;msg.msg_iovlen=1;if((n=recvmsg(socket,&msg,0))<=0){perror("IPC failure: Receiving data over socket failed");free(control_un.control);return-1;}if(((cmptr=CMSG_FIRSTHDR(&msg))!=NULL)&&(cmptr->cmsg_len==CMSG_LEN(sizeof(int)))){if((cmptr->cmsg_level!=SOL_SOCKET)||(cmptr->cmsg_type!=SCM_RIGHTS)){free(control_un.control);return-1;}memmove(&receivedfd,CMSG_DATA(cmptr),sizeof(receivedfd));*fd=receivedfd;}else{free(control_un.control);return-1;}free(control_un.control);return0;}
应用程序可以通过向cuMemAddressReserve传递适当的参数来预留虚拟地址范围。获得的地址范围不会与任何设备或主机物理内存关联。预留的虚拟地址范围可以映射到属于系统中任何设备的内存块,从而为应用程序提供一个连续的 VA 范围,该范围由属于不同设备的内存提供后备存储并与其建立映射。应用程序应使用cuMemAddressFree将虚拟地址范围归还给 CUDA。用户必须确保在调用cuMemAddressFree之前已解除整个 VA 范围的映射。这些函数在概念上类似于 Linux 上的mmap和munmap,或 Windows 上的VirtualAlloc和VirtualFree。以下代码片段展示了该函数的用法:
CUdeviceptrptr;// `ptr` holds the returned start of virtual address range reserved.CUresultresult=cuMemAddressReserve(&ptr,size,0,0,0);// alignment = 0 for default alignment
映射内存
前两节中分配的物理内存和划出的虚拟地址空间体现了 VMM API 引入的内存与地址之间的区别。要使分配的内存可用,用户必须将内存映射到地址空间。必须使用cuMemMap将从cuMemAddressReserve获得的地址范围与从cuMemCreate或cuMemImportFromShareableHandle获得的物理分配相互关联。
只要划出了足够的地址空间,用户就可以将来自多个设备的分配关联到连续的虚拟地址范围中。要解除物理分配与地址范围之间的关联,用户必须使用cuMemUnmap解除该映射地址的映射。用户可以根据需要,将内存映射到同一个地址范围并解除映射任意多次,只要确保不尝试在已映射的预留 VA 范围上创建映射即可。以下代码片段展示了该函数的用法:
CUdeviceptrptr;// `ptr`: address in the address range previously reserved by cuMemAddressReserve.// `allocHandle`: CUmemGenericAllocationHandle obtained by a previous call to cuMemCreate.CUresultresult=cuMemMap(ptr,size,0,allocHandle,0);
4.17.3.4. 访问权限
CUDA 的虚拟内存管理 API 使应用程序能够通过访问控制机制显式保护其 VA 范围。使用cuMemMap将分配映射到地址范围中的某个区域并不会使该地址变得可访问,如果 CUDA 核函数访问该地址,则会导致程序崩溃。用户必须在源设备和执行访问的设备上使用cuMemSetAccess函数专门选择访问控制。这会允许或限制特定设备对已映射地址范围的访问。以下代码片段展示了该函数的用法:
voidsetAccessOnDevice(intdevice,CUdeviceptrptr,size_tsize){CUmemAccessDescaccessDesc={};accessDesc.location.type=CU_MEM_LOCATION_TYPE_DEVICE;accessDesc.location.id=device;accessDesc.flags=CU_MEM_ACCESS_FLAGS_PROT_READWRITE;// Make the address accessiblecuMemSetAccess(ptr,size,&accessDesc,1);}
CUmemGenericAllocationHandlecreateMCHandle(intnumDevices,size_tsize){CUmemAllocationPropmcProp={};mcProp.numDevices=numDevices;mcProp.handleTypes=CU_MEM_HANDLE_TYPE_FABRIC;// or on single node CU_MEM_HANDLE_TYPE_POSIX_FILE_DESCRIPTORsize_tgranularity=0;cuMulticastGetGranularity(&granularity,&mcProp,CU_MEM_ALLOC_GRANULARITY_MINIMUM);// Ensure size matches granularity requirements for the allocationsize_tpadded_size=ROUND_UP(size,granularity);mcProp.size=padded_size;// Create Multicast Object this has no devices and no physical memory associated yetCUmemGenericAllocationHandlemcHandle;cuMulticastCreate(&mcHandle,&mcProp);returnmcHandle;}
__global__voidall_reduce_norm_barrier_kernel(float*l2_norm,float*partial_l2_norm_mc,unsignedint*arrival_counter_uc,unsignedint*arrival_counter_mc,constunsignedintexpected_count){assert(1==blockDim.x*blockDim.y*blockDim.z*gridDim.x*gridDim.y*gridDim.z);floatl2_norm_sum=0.0;#if __CUDA_ARCH__ >= 900// atomic reduction to all replicas// this can be conceptually thought of as __threadfence_system(); atomicAdd_system(arrival_counter_mc, 1);cuda::ptx::multimem_red(cuda::ptx::release_t,cuda::ptx::scope_sys_t,cuda::ptx::op_add_t,arrival_counter_mc,n);// Need a fence between Multicast (mc) and Unicast (uc) access to the same memory `arrival_counter_uc` and `arrival_counter_mc`:// - fence.proxy instructions establish an ordering between memory accesses that may happen through different proxies// - Value .alias of the .proxykind qualifier refers to memory accesses performed using virtually aliased addresses to the same memory location.// from https://docs.nvidia.com/cuda/parallel-thread-execution/#parallel-synchronization-and-communication-instructions-membarcuda::ptx::fence_proxy_alias();// spin wait with acquire ordering on UC mapping till all peers have arrived in this iteration// Note: all ranks need to reach another barrier after this kernel, such that it is not possible for the barrier to be unblocked by an// arrival of a rank for the next iteration if some other rank is slow.cuda::atomic_ref<unsignedint,cuda::thread_scope_system>ac(arrival_counter_uc);while(expected_count>ac.load(cuda::memory_order_acquire));// Atomic load reduction from all replicas. It does not provide ordering so it can be relaxed.asmvolatile("multimem.ld_reduce.relaxed.sys.global.add.f32 %0, [%1];":"=f"(l2_norm_sum):"l"(partial_l2_norm_mc):"memory");#else#error "ERROR: multimem instructions require compute capability 9.0 or larger."#endif*l2_norm=std::sqrt(l2_norm_sum);}
虚拟内存管理 API 提供了一种方法,通过使用不同的虚拟地址多次调用cuMemMap,为同一内存分配创建多个虚拟内存映射或“代理”。这称为虚拟别名。除非 PTX ISA 中另有说明,否则在执行写入的设备操作(网格启动、memcpy、memset 等)完成之前,对该内存分配的一个代理的写入被视为与同一内存的任何其他代理不一致且不相干。对于在执行写入的设备操作之前已存在于 GPU 上、但在该写入设备操作完成后才进行读取的网格,其代理也被视为不一致且不相干。
例如,假设设备指针 A 和 B 是同一内存分配的虚拟别名,则以下代码片段被视为具有未定义行为:
__global__voidfoo(char*A,char*B){*A=0x1;printf("%d\n",*B);// Undefined behavior! *B can take on either// the previous value or some value in-between.}
假设这两个核函数(通过流或事件)按单调顺序执行,以下行为是已定义的。
__global__voidfoo1(char*A){*A=0x1;}__global__voidfoo2(char*B){printf("%d\n",*B);// *B == *A == 0x1 assuming foo2 waits for foo1// to complete before launching}cudaMemcpyAsync(B,input,size,stream1);// Aliases are allowed at// operation boundariesfoo1<<<1,1,0,stream1>>>(A);// allowing foo1 to access A.cudaEventRecord(event,stream1);cudaStreamWaitEvent(stream2,event);foo2<<<1,1,0,stream2>>>(B);cudaStreamWaitEvent(stream3,event);cudaMemcpyAsync(output,B,size,stream3);// Both launches of foo2 and// cudaMemcpy (which both// read) wait for foo1 (which writes)// to complete before proceeding
通过cuMemCreate,用户可以在分配时表明,已将某个特定的内存分配指定用于进程间通信或图形互操作。应用程序可以通过将CUmemAllocationProp::requestedHandleTypes设置为平台特定的字段来实现这一点。在 Windows 上,当CUmemAllocationProp::requestedHandleTypes设置为CU_MEM_HANDLE_TYPE_WIN32时,应用程序还必须在CUmemAllocationProp::win32HandleMetaData中指定一个 LPSECURITYATTRIBUTES 属性。此安全属性定义了哪些已导出的内存分配可以传递给其他进程。
#if defined(__linux__)prop.requestedHandleTypes=CU_MEM_HANDLE_TYPE_POSIX_FILE_DESCRIPTOR;#elseprop.requestedHandleTypes=CU_MEM_HANDLE_TYPE_WIN32;prop.win32HandleMetaData=// Windows specific LPSECURITYATTRIBUTES attribute.#endif
4.18. 计算互连传输
计算互连传输通过NCCL 设备 API和NVSHMEM,为 NCCL 和 NVSHMEM 等通信库提供经由 NVLink 互连网络(fabric)的大规模 GPU 间通信。当这些库与所需的通信模式相匹配时,大多数开发者应优先使用它们。计算互连传输主要面向编写此类通信库的开发者,或面向在这些库无法很好地涵盖其通信模式时需要精细控制的应用程序。自定义通信核函数的作者在需要比这些设备 API 单独提供的访问更加直接的访问时,也可以将互连网络(fabric)操作与 NCCL 和 NVSHMEM 设备 API 结合使用。
单播和多播内存共享 API 通过将远程物理内存映射到本地虚拟地址空间,使应用程序能够跨 NVLink 互连网络(fabric)访问 GPU 内存。一旦对等方的内存分配已映射并被授予访问权限,核函数就可以像访问本地内存一样,使用加载和存储来访问它(对于多播映射,还需使用multimem指令)。该模型既是以地址为中心的,也是以内存为中心的:共享的单位是虚拟地址到物理地址的映射,核函数在对等方上访问的每个字节,都必须能通过发起访问的进程已预留并映射的地址来访问。
计算互连传输为通过 NVLink 互连网络(fabric)连接的 GPU 提供了一种互补的、以资源为中心的模型。应用程序不再将对等方的内存导入本地地址空间,而是创建一个逻辑端点:一个具名的传输对象,表示可通过互连网络(fabric)访问的资源。逻辑端点由一个 32 位整数,即逻辑端点 ID标识;端点内的目标由该 ID 与一个 64 位偏移量共同标识,而不是由虚拟地址标识。由于该 ID 标识的是资源本身,因此该模型并不局限于内存,尽管内存目前是逻辑端点唯一暴露的资源类型。
当所有者更改端点的后备内存时,已导入的端点也仍然有效。对等方导入端点,将其与自己预留的某个端点 ID 关联,而不会导入所有者的内存分配。因此,所有者可以通过在本地重新绑定来扩大、缩小或替换端点背后的缓冲区,而对等方可以继续使用其本地端点 ID,无需重新导入端点。所有者及其对等方仍必须在重新绑定前后进行同步,以便在所有者将端点重新绑定到新内存期间,对等方不会访问该端点。此外,发出的操作若落在当前绑定的范围之外,则属于未定义行为。相比之下,VMM IPC 导入会映射一个特定的内存分配,因此在所有者一侧调整该内存分配的大小时,需要对等方导入并映射新的内存分配。
一旦端点已创建、已与需要它的对等方共享,并且已由资源提供后备支持,就可以针对对等方的逻辑端点 ID 和偏移量发出异步互连网络(fabric)操作,包括 put、get、原子操作和归约。与对已映射的对等方地址执行加载或存储不同,互连网络(fabric)操作会报告明确的完成状态,发起操作的代码可以检查该状态。发生故障时,应用程序可以重试、重新路由或采取其他恢复措施,而不是使进程发生故障。
端点可以与同一 NVLink 互连网络(fabric)内同一节点或不同节点上的进程共享。互连网络(fabric)IPC 句柄机制与 VMM API 使用的机制类似。有关互连网络(fabric)句柄和 IMEX 通道的详细信息,请参阅虚拟内存管理。
4.18.2. 预备知识
以下定义确立了本节后续内容中使用的关键对象和操作。
4.18.2.1. 定义
逻辑端点 ID:逻辑端点 ID(CUlogicalEndpointId)是一个 32 位值,用于标识进程内的逻辑端点。端点 ID 是进程局部的:每个进程使用cuLogicalEndpointIdReserve预留自己的范围,并选择将哪个预留 ID 与给定端点关联。互连网络(fabric)操作通过此 ID 和偏移量来寻址端点。单个端点 ID 标识一个端点,但多个 ID 可以标识同一端点。端点 ID 通过cuLogicalEndpointCreate或cuLogicalEndpointImport与端点关联。在使用cuLogicalEndpointIdRelease释放端点 ID 之前,必须使用cuLogicalEndpointDestroy移除此关联。在端点 ID 仍与端点关联时释放它属于未定义行为。后续预留可能会重用已释放的 ID。第 4.18.6 节介绍了逻辑端点 ID 的生命周期。
逻辑端点:逻辑端点是一个传输对象,表示可通过 NVLink 互连网络(fabric)访问的资源,并以有界偏移空间的形式暴露。创建端点会分配用于路由以该端点为目标的互连网络(fabric)操作的资源。随后,应用程序必须将目标资源显式绑定到端点偏移空间的一个或多个范围。互连网络(fabric)操作使用已关联的端点 ID 以及该空间内的偏移量来标识其目标。当进程使用cuLogicalEndpointCreate创建端点,或使用cuLogicalEndpointImport导入对等方端点时,端点会与预留的 ID 关联。在显式解除端点资源的绑定之前销毁端点关联,会解除这些资源的绑定,但不会销毁资源本身。在将资源与端点解除绑定之前销毁资源属于未定义行为。第 4.18.3 节概述了端点的生命周期。
单播逻辑端点:单播逻辑端点表示点对点传输目标。它具有一个在创建端点时指定的所有者设备,端点所绑定的内存位于该设备上。对等设备针对端点 ID 发出 put 或 get 操作,以将数据移入或移出所有者的已绑定内存。
计算互连传输句柄:计算互连传输句柄是传统指针的一种以资源为中心的替代方案。它由逻辑端点 ID 和偏移量组成一对:逻辑端点 ID 选择 NVLink 互连网络(fabric)上的目标位置,即单播端点的所有者设备或一个多播团队,而偏移量选择该目标位置的已绑定内存中的某个位置。互连网络(fabric)操作使用此句柄代替对等方虚拟地址。
put 和 get 操作:put 和 get 是计算互连传输提供的数据移动原语。put 操作将数据从发起操作的 GPU 移动到目标逻辑端点。其 multimem 变体cuda::ptx::fabric_try_put_multimem向多播逻辑端点执行广播,将源数据写入每个副本中相应的偏移位置。get 操作将数据从目标逻辑端点移动到发起操作的 GPU。在两个方向上,远端都通过逻辑端点 id 和偏移量来标识,而不是通过对等端虚拟地址来标识,并且远端分配的内存无需映射到发起操作的进程的虚拟地址空间中。
intcountedOpsSupported=0;cuDeviceGetAttribute(&countedOpsSupported,CU_DEVICE_ATTRIBUTE_LOGICAL_ENDPOINT_COUNTED_OPS_SUPPORTED,device);if(countedOpsSupported!=0){// `device` supports counted operations via logical endpoints}
来自所有者设备的单播访问
单播端点的所有者设备在传递给cuLogicalEndpointCreate的端点属性中指定。CU_DEVICE_ATTRIBUTE_LOGICAL_ENDPOINT_UNICAST_ACCESS_ON_OWNER_DEVICE_SUPPORTED设备属性指示该设备能否访问它所拥有的单播逻辑端点。如果不支持这种访问,设备可以通过指针访问所绑定的内存,这目前为所有者设备提供了最佳性能。所有者以外的设备可以通过与单播端点关联的逻辑端点 id 来访问该端点。
intownerAccessSupported=0;cuDeviceGetAttribute(&ownerAccessSupported,CU_DEVICE_ATTRIBUTE_LOGICAL_ENDPOINT_UNICAST_ACCESS_ON_OWNER_DEVICE_SUPPORTED,device);if(ownerAccessSupported!=0){// `device` supports unicast logical endpoint access on the owner device}
4.18.3. API 概述
逻辑端点 API 是底层CUDA Driver API的一部分,使用逻辑端点遵循明确定义的生命周期。下面的步骤概述了工作流程,后续各节将详细介绍每一步。这些步骤分为以下阶段:
std::vector<unsignedint>allCliqueIds(numRanks);MPI_Allgather(&localCliqueId,sizeof(unsignedint),MPI_BYTE,allCliqueIds.data(),sizeof(unsignedint),MPI_BYTE,MPI_COMM_WORLD);for(inti=0;i<numRanks;i++){if(allCliqueIds[i]!=localCliqueId){fprintf(stderr,"Rank %d: Clique id %u does not match expected %u\n",myRank,allCliqueIds[i],localCliqueId);returnEXIT_FAILURE;}}
4.18.5. 创建端点
创建和导入端点首先要确定进程需要多少个逻辑端点 id。然后使用cuLogicalEndpointIdReserve预留一个 id 范围,该函数返回该范围的基准 id。选择足够大的数量,以满足进程将创建或导入的每个端点的需要。与该范围关联的端点可以具有不同的属性。例如,应用程序可以为每个 GPU 预留一个 id,再为一个多播端点额外预留一个 id。此示例为每个秩预留一个 id:
逻辑端点 id 是进程局部的名称,其生命周期独立于它所标识的端点的生命周期。端点 id 始终处于以下状态之一:
未预留。该 id 不归该进程所有,不能与端点关联。cuLogicalEndpointIdReserve会将其预留。
已预留。该 id 归该进程所有,但尚未指代任何对象。使用已预留的 id 调用cuLogicalEndpointCreate或cuLogicalEndpointImport会将其与一个端点关联,并使其进入已关联状态。cuLogicalEndpointIdRelease会使其回到未预留状态。
已关联。该 id 指代一个端点,使用该 id 的互连网络操作以该端点为目标。cuLogicalEndpointDestroy会移除该关联,并使该 id 回到已预留状态。
cuLogicalEndpointIdReserve预留一个包含count个端点 id 的范围,并返回其基准baseLeId,因此预留的范围为[baseLeId,baseLeId+count)。基准是一个输出值:调用者不能选择获得哪些 id,并且如果没有包含count个 id 的可用范围,预留就会失败,例如,进程中的另一个库持有预留范围时就可能出现这种情况。
一个端点可以同时与多个 id 关联。例如,它可以通过cuLogicalEndpointCreate与所有者的 id 关联,并通过cuLogicalEndpointImport与其他 id 关联。这些 id 是同一端点的别名,针对其中任意一个 id 发起的操作都会到达同一目标。
cuLogicalEndpointDestroy移除一个 id 的关联。此后,通过后续的创建或导入操作,该 id 可以与另一个端点关联,无需再次预留。销毁操作还会解除该进程通过此 id 绑定的所有内存的绑定。只有在端点的最后一个别名被销毁时,端点本身才会被释放。
cuLogicalEndpointIdRelease(baseLeId,count)释放范围[baseLeId,baseLeId+count)中最多count个 id。该范围中的每个 id 都必须已经预留,并且与该范围中的 id 关联的每个端点都必须先被销毁。
由于预留以进程为单位,因此在每个导入进程中导入端点时,不必使用相同的 id。一种方便的约定是,每个进程预留一个大小相同的范围,为每个参与者预留一个 id,并在本地以baseLeId+peer来寻址给定对等端的端点。每个进程都有自己预留的baseLeId,它在各进程之间不必相同。如果在不同进程中使用不同 id 导入同一个对等端点,CUDA 不会检测或报告这种不匹配。应用程序有责任维护正确的本地对等端到端点 id 的映射。
与对等方共享端点遵循导出、传输、导入的交换过程:所有者将端点导出为互连网络(fabric)IPC 句柄,将该句柄传输给需要它的对等方,然后每个对等方导入端点,并将其与自身预留的某个尚未关联端点的逻辑端点 ID 关联。共享使用互连网络(fabric)IPC 句柄,因此端点必须绑定到可对外共享的内存,并且环境必须满足第 4.18.1 节中描述的互连网络(fabric)IPC 要求。
使用cuLogicalEndpointExport导出端点,请求与描述该端点时所用类型相同的 IPC 句柄类型(ipcHandleTypes)。这会生成一个CUlogicalEndpointFabricHandle,即代表该逻辑端点的互连网络(fabric)IPC 句柄。使用应用程序自行选择的进程间通信机制将其传输给对等方,然后让每个对等方使用cuLogicalEndpointImport导入它。导入 ID 在本地选择,使用cuLogicalEndpointImport导入它。导入方可以选择用于导入端点的逻辑端点 ID。此 ID 必须已成功预留,且不得与任何其他逻辑端点关联,但不必与所有者用于创建端点的 ID 相同。每个设备都可以在不同的 ID 处导入同一端点,甚至可以在多个不同的 ID 处导入它(即允许多次导入同一端点)。
下面的单播点对点示例在环上共享端点。每个秩导出自己的端点,并通过一次MPI_Sendrecv将句柄发送给接收邻居,同时收集发送邻居的句柄。它将该句柄导入为leId+sendRank,随后使用此 ID 针对所导入端点的绑定内存发出互连网络(fabric)操作:
// Export our own endpoint to a fabric IPC handle, hand it to the peers that// need it, and import each peer's handle to a locally reserved id.CUlogicalEndpointFabricHandlelocalHandle;CUlogicalEndpointFabricHandlesendRankHandle;cuLogicalEndpointExport(&localHandle,leId+myRank,CU_LOGICAL_ENDPOINT_IPC_HANDLE_TYPE_FABRIC);MPI_Sendrecv(&localHandle,sizeof(CUlogicalEndpointFabricHandle),MPI_BYTE,recvRank,0,&sendRankHandle,sizeof(CUlogicalEndpointFabricHandle),MPI_BYTE,sendRank,0,MPI_COMM_WORLD,MPI_STATUS_IGNORE);cuLogicalEndpointImport(leId+sendRank,&sendRankHandle,CU_LOGICAL_ENDPOINT_IPC_HANDLE_TYPE_FABRIC);
4.18.7.1. 确认就绪状态
cuLogicalEndpointCreate和cuLogicalEndpointImport在请求被接受后立即返回。在cuLogicalEndpointQuery报告就绪之前,将逻辑端点 ID 用于要求端点已完全构造的 API,会产生未定义行为。cuLogicalEndpointQuery本身是非阻塞的:如果所查询范围内的任何 ID 尚未就绪,它就返回 0;一旦给定范围内的所有 ID 都已就绪,它就返回非零值,因此通常会在轮询循环中调用它。
// Bind the whole backing allocation at endpoint offset 0, by allocation handle.cuLogicalEndpointBindMem(leId+myRank,cuDevice,0,exportHandle,0,exportSize,0);// No rank may issue an operation until every destination has been bound.MPI_CHECK(MPI_Barrier(MPI_COMM_WORLD));
由于对等方导入的是端点,而不是所有者的分配,因此所有者可以替换端点背后的内存,而无需任何对等方重新导入端点。使用cuLogicalEndpointUnbind解除当前范围的绑定,并通过同一个端点 ID 将新的分配绑定到端点偏移空间中的同一范围。所有者及其对等方必须在重新绑定前后进行同步,以确保在端点未绑定期间,没有对等方针对该端点发出操作。发出落在当前绑定范围之外的操作会产生未定义行为。
4.18.9. 互连网络(fabric)操作
线程通过执行接受计算互连传输句柄的互连网络(fabric)操作来访问端点资源,该句柄是一个逻辑端点 ID 与偏移量的组合。互连网络(fabric)操作是异步的,也就是说,程序必须显式等待它们完成,才能观察到它们的效果。互连网络(fabric)操作带有try_前缀,以指示它们可能失败。也就是说,在等待完成之后,线程必须检查该操作的完成机制(请参阅第 4.18.10 节),以确定操作是否成功。这使互连网络(fabric)操作有别于普通指针操作:基于指针的访问所发生的故障,是通过销毁上下文或整个应用程序来向应用程序报告的。想要处理这些错误的应用程序,例如要从指针故障中恢复的应用程序,只能在上下文或进程级别这样做。互连网络(fabric)操作允许应用程序在程序线程级别处理错误。
该示例发出互连网络(fabric)put 操作。put 从共享内存缓冲区读取数据,并将其写入目标句柄。多个线程将输入数据写入共享内存,然后使用__syncthreads与发出 put 的线程同步。put 通过异步代理读取共享内存,因此发出操作的线程调用cuda::ptx::fence_proxy_async(cuda::ptx::space_shared),以将通用代理的共享内存写入同步到异步代理。put 接受目标句柄、源缓冲区基址、字节数以及用于跟踪完成情况的mbarrier:
// Make the staged shared-memory source visible to the async proxy before the put reads it.cuda::ptx::fence_proxy_async(cuda::ptx::space_shared);cuda::ptx::fabric_try_put(cuda::ptx::space_shared,cuda::ptx::sem_relaxed,cuda::ptx::scope_sys,putLeId,offset,smemBuf,FABRIC_CHUNK_SIZE,&putBar);
该调用设置了若干指令限定符,其完整集合由 PTX ISA 规定,包括每条指令接受的访问大小、内存排序模式和作用域(请参阅互连网络(fabric)指令)。这里值得指出该操作的两个方面,因为它们将该操作与程序的其余部分联系起来:如何跟踪其完成情况,以及如何指定内存排序。
事务计数。使用mbarrier来指示完成的互连网络(fabric)操作遵循与使用 TMA 传输数据中描述的指针寻址cuda::ptx::cp_async_bulk复制相同的mbarrier事务记账模型。随着 put 完成,每交付 16 字节,它就将其mbarrier的事务计数减 1。在所有预期的到达都已发生且事务计数达到零后,屏障阶段完成。put 不会设置预期事务计数。在提交该操作之后发出的单独一个cuda::ptx::mbarrier_arrive_expect_tx会记录一次到达,并将事务计数增加字节数除以 16 的值,因为这就是 put 将减少的计数值。取回操作则使用基于字节的事务记账。cuda::ptx::fabric_try_get和cuda::ptx::fabric_try_pullred每交付一个字节就将事务计数减 1,因此cuda::ptx::mbarrier_arrive_expect_tx会加上完整的字节数。第 4.18.10 节介绍了 mbarrier 的布局要求,以及如何读回互连网络(fabric)状态。
带计数的 put 还会在其数据到达时递增目标端的字节计数器,因此接收方可以在访问本地数据之前轮询该计数器,而不必交换单独的完成消息。下面的代码使用cuda::ptx::fabric_try_put_counted(普通 put 的.counted::bytes变体)来实现这一点,并传入第二个目标偏移量,即计数器的端点偏移量:
// Make the staged shared-memory source visible to the async proxy before the put reads it.cuda::ptx::fence_proxy_async(cuda::ptx::space_shared);cuda::ptx::fabric_try_put_counted(cuda::ptx::space_shared,cuda::ptx::sem_relaxed,cuda::ptx::scope_sys,putLeId,offset,counterOffset,smemBuf,FABRIC_CHUNK_SIZE,&putBar);
仅有端点 ID 并不能提供对远程目标的指针访问。导入端点不会将其绑定的资源映射到导入方的虚拟地址空间。因此,下面的示例使用由发出操作的线程所在设备拥有的单播端点。leId是端点 ID,而绑定在dataOffset处的内存也映射到了该设备的虚拟地址空间中。dataPtr指向同一位置。
发出 put 后,线程等待其完成。在使用dataPtr通过通用代理读取目标之前,线程必须先使用cuda::ptx::sem_release发出cuda::ptx::fence_proxy_generic_fabric_alias,然后再使用cuda::ptx::sem_acquire发出。仅等待完成,并不能使互连网络(fabric)代理的写入排序在通用代理的指针加载之前。waitForSuccessfulCompletion代表第 4.18.10 节中描述的mbarrier等待和状态检查。目标的初始值为 0,smemSrcData是一个 16 字节的共享内存源,其第一个uint32_t元素保存着 42。
由同一线程(线程 0)发出并加载
namespaceptx=cuda::ptx;ptx::fabric_try_put(ptx::space_shared,ptx::sem_relaxed,ptx::scope_sys,leId,dataOffset,smemSrcData,16,&mBar);ptx::fabric_submit();ptx::mbarrier_arrive_expect_tx(ptx::sem_acquire,ptx::scope_cta,ptx::space_shared,&mBar,1);waitForSuccessfulCompletion(&mBar);// Order the subsequent generic-proxy load after the fabric put.ptx::fence_proxy_generic_fabric_alias(ptx::sem_release);ptx::fence_proxy_generic_fabric_alias(ptx::sem_acquire);assert(*dataPtr==42);
namespaceptx=cuda::ptx;cuda::atomic_ref<uint32_t,cuda::thread_scope_system>flag(*flagPtr);while(flag.load(cuda::memory_order_relaxed)!=1);// Order the data load after the observed flag update.ptx::fence_proxy_generic_fabric_alias(ptx::sem_acquire);assert(*dataPtr==42);
数据 put 完成后,发送方先发出cuda::ptx::fence_proxy_generic_fabric_alias(cuda::ptx::sem_release),然后再发出标志 put。当接收方的标志加载观察到该 put 写入的值 1 时,接收方就知道发送方已发布数据。在使用数据之前,接收方必须发出cuda::ptx::fence_proxy_generic_fabric_alias(cuda::ptx::sem_acquire)。此获取栅栏防止后续对数据的指针加载被排序在所观察到的标志更新之前。发送方的释放栅栏与接收方的获取栅栏共同使发送方的数据 put 排序在接收方的数据加载之前。因此,在没有任何其他数据写入的情况下,该加载会观察到值 42。
4.18.9.1. 逐线程操作与线程束集体操作
每条互连网络(fabric)指令都定义了自身的执行粒度。fabric.try_get、fabric.try_get.tensor、fabric.try_put、fabric.try_put.tensor和fabric.try_red是逐线程的:每次执行都会为发出指令的线程启动一个独立操作。fabric.try_pullred是线程束集体操作:一个线程束的全部 32 个通道都必须一起执行该指令。PTX ISA 规定了每条指令所要求的参与方式。
cuda::ptx::fabric_try_put接受跟踪该操作的 mbarrier。随着操作的数据送达,互连网络(fabric)引擎会在屏障上完成相应的事务,并在那里记录操作的状态。因此,传输已送达的信号来自 put 操作本身,而不是发出操作的线程。
put 操作会送达其字节,但不会告知屏障应预期多少字节。对于此处所示的逐线程 put 操作,发出操作的线程会在单独的步骤中提供该计数。它首先使用fabric_submit提交操作,以便互连网络(fabric)引擎最终开始处理该操作,然后调用cuda::ptx::mbarrier_arrive_expect_tx记录一次到达并增加预期事务计数,即该操作将送达的字节数,以 16 字节为单位计数。每个互连网络(fabric)操作都必须在跟踪其完成情况的屏障阶段推进之前提交。提交操作后,发出操作的线程要么执行屏障阶段推进所需的屏障操作(例如cuda::ptx::mbarrier_arrive_expect_tx或cuda::ptx::mbarrier_expect_tx),要么与执行该操作的另一个线程同步。发出操作的线程不必亲自在屏障上等待。另一个线程可以执行该等待。一旦所有预期的到达均已发生,且事务计数降为零,屏障阶段就会推进,等待随之返回。程序必须在网格退出之前等待每个互连网络(fabric)操作完成。网格退出时仍有操作未完成属于未定义行为。
以下序列提交该 put 操作并等待其完成:
cuda::ptx::fabric_submit();cuda::ptx::mbarrier_arrive_expect_tx(cuda::ptx::sem_relaxed,cuda::ptx::scope_cta,cuda::ptx::space_shared,&putBar,(FABRIC_CHUNK_SIZE/FABRIC_TX_GRANULARITY_BYTES));// Spin while the barrier's phase hasn't flipped yet. The report outputs are// only valid once the barrier completes, so inspect them after.boolisReportSeen=false;uint8_treportValue=0;boolcomplete=waitWithDebugTimeout([&](){return!cuda::ptx::mbarrier_try_wait_parity(cuda::ptx::mbarrier_phase_primary,cuda::ptx::sem_relaxed,cuda::ptx::scope_cta,isReportSeen,reportValue,&putBar,/*phaseParity=*/0);},"cftTryPutKernel: mbarrier try_wait parity");if(!complete){__trap();}if(isReportSeen){reportFabricError(&reportValue,offset);}
inline__device__voidreportFabricError(uint8_t*reportValue,uint64_toffset){constunsignedlonglongoff=offset;unsignedinterrCount=0;if(cudaFabricOpErrorStatusCount(reportValue,cudaFabricOpStatusSourceMbarrierV1,&errCount)!=cudaSuccess){printf("cudaFabricOpErrorStatusCount failed at offset %llu\n",off);return;}for(unsignedinti=0;i<errCount;++i){cudaFabricOpStatusInfoinfo=cudaFabricOpStatusInfoSuccess;if(cudaFabricOpErrorStatusGet(reportValue,cudaFabricOpStatusSourceMbarrierV1,i,&info)==cudaSuccess){printf("fabric put error[%u/%u] at offset %llu: status=%d\n",i,errCount,off,(int)info);}else{printf("cudaFabricOpErrorStatusGet failed for error[%u/%u] at offset %llu\n",i,errCount,off);}}}
上述完成序列记录了发出 put 操作的线程所贡献的到达计数和预期事务计数。哪个线程可以记录这些计数,取决于操作的执行粒度。对于逐线程操作,发出操作的线程必须为自己的操作记录这些计数。对于线程束集体执行的fabric.try_pullred,可以由参与线程束中的单个通道代表整个线程束记录这些计数,也可以由每个通道记录自己的到达。cuda::ptx::mbarrier_arrive_expect_tx是一个单独的融合操作:它在同一步骤中计入一次到达并增加预期事务计数,因此必须由一个线程执行这两项操作。它必须在使用fabric.submit提交操作之后、等待观察到完成之前运行。记录到达计数和预期事务计数的线程不必是在屏障上等待的线程。
// ---- Clean up endpoints and free the backing allocation. ----// Once every rank's stream has synchronized, all fabric puts// have completed and no rank will issue another operation. Making that global// with a barrier ensures no peer still targets an endpoint we clean up below.MPI_Barrier(MPI_COMM_WORLD);// Destroy the imported endpoint (the peer target our puts addressed). An import// is only a local reference to the peer's endpoint id and maps no peer memory,// so once our puts have drained this just drops that reference.cuLogicalEndpointDestroy(leId+sendRank);// Unbind and destroy our owned endpoint, then release the reserved id range.cuLogicalEndpointUnbind(leId+myRank,cuDevice,0,exportSize);cuLogicalEndpointDestroy(leId+myRank);cuLogicalEndpointIdRelease(leId,numRanks);// Free the backing allocation in VMM cleanup order: unmap the range, release// the physical handle, then free the reserved virtual address range.cuMemUnmap(exportPtr,exportSize);cuMemRelease(exportHandle);cuMemAddressFree(exportPtr,exportSize);
另一个进程发出的、以绑定到同一逻辑端点的资源为目标的互连网络(fabric)操作,可能仍在进行中。因此,在移除单播绑定之前,所有者必须等到每个导入方都已停止发出操作。在移除任何多播绑定之前,每个拥有已绑定副本的参与者都必须知道,所有进程均已停止发出操作。该示例在所有 rank 同步各自的 CUDA 流之后,使用一个屏障实现这一点。如果能够保持所要求的顺序,应用程序可以采用范围更小的同步方案。
EGM 使用操作系统分配的 NUMA 节点标识符。注意,此标识符不同于设备的序号,它与最近的主机节点相关联。除了现有方法外,用户还可以使用CU_DEVICE_ATTRIBUTE_HOST_NUMA_ID属性类型调用cuDeviceGetAttribute,获取主机节点的标识符(numaID),如下所示:
除内存分配之外,远程对等访问没有针对 EGM 的特定修改,并且遵循 CUDA 进程间(IPC)协议。有关 IPC 的更多详细信息,请参阅CUDA 编程指南。
用户应使用cuMemCreate分配内存,并且同样必须显式提供CU_MEM_LOCATION_TYPE_HOST_NUMA作为位置类型,提供numaID作为位置标识符。此外,应将CU_MEM_HANDLE_TYPE_FABRIC定义为所请求的句柄类型。以下代码片段展示了在节点 A 上分配物理内存的过程:
cuMemExportToShareableHandle(&fabricHandle,allocHandle,CU_MEM_HANDLE_TYPE_FABRIC,0);// At this point, fabricHandle should be sent to Node B via TCP/IP.
在节点 B 上,可以使用cuMemImportFromShareableHandle导入该句柄,并将其视为任何其他互连网络(fabric)句柄
// At this point, fabricHandle should be received from Node A via TCP/IP.CUmemGenericAllocationHandleallocHandle;cuMemImportFromShareableHandle(&allocHandle,&fabricHandle,CU_MEM_HANDLE_TYPE_FABRIC);
最后一步,用户应为节点 B 上的每个本地 GPU 授予适当的访问权限。以下代码片段示例为八个本地 GPU 授予读写访问权限:
// Give all 8 local GPUS access to exported EGM memory located on Node A. |CUmemAccessDescaccessDesc[8];for(inti=0;i<8;i++){accessDesc[i].location.type=CU_MEM_LOCATION_TYPE_DEVICE;accessDesc[i].location.id=i;accessDesc[i].flags=CU_MEM_ACCESS_FLAGS_PROT_READWRITE;}cuMemSetAccess(dptr,size,accessDesc,8);
CUDA 动态并行(通常缩写为 CDP)是 CUDA 编程模型的一项特性,它使 GPU 上运行的代码能够创建新的 GPU 工作。也就是说,已经在 GPU 上运行的设备代码可以通过额外的核函数启动向 GPU 添加新工作。该特性可以减少在主机和设备之间传递执行控制权和数据的需要,因为在设备上执行的线程可以在运行时做出启动配置决策。
核函数可以在运行时生成依赖于数据的并行工作。在 CUDA 中加入 CDP 之前,某些算法和编程模式需要进行修改,以消除递归、不规则循环结构或其他不适合扁平的单层并行的构造。使用 CUDA 动态并行可以更自然地表达这些程序结构。
注意
本节介绍 CUDA 动态并行的更新版本,有时称为 CDP2,它是 CUDA 12.0 及更高版本中的默认版本。CDP2 是计算能力(CC)9.0 及更高的设备上唯一可用的 CUDA 动态并行版本。对于 CC 低于 9.0 的设备,开发者仍可通过编译器参数-DCUDA_FORCE_CDP1_IF_SUPPORTED选择使用旧版 CUDA 动态并行 CDP1。CDP1 文档可在旧版 CUDA 编程指南中找到。计划在未来的 CUDA 版本中移除 CDP1。
4.20.2. 执行环境
CUDA 中的动态并行允许 GPU 线程配置、启动新网格,并对其进行隐式同步。网格是核函数启动的一个实例,其中包括线程块的具体形状以及由线程块组成的网格的具体形状。在以下各节中,需要注意核函数本身与该核函数的特定调用(即网格)之间的区别。
CUDA 动态并行依赖于CUDA 设备运行时,它支持调用一组有限的 API,这些 API 在语法上与 CUDA 运行时 API 类似,但可在设备代码中使用。设备运行时 API 的行为与其对应的主机端 API 类似,但存在一些差异。这些差异列于API 参考一节中的表格中。
在主机和设备上,CUDA 运行时都提供了用于启动核函数以及通过流和事件跟踪启动之间依赖关系的 API。在设备上,已启动的核函数和 CUDA 对象对发起调用的网格中的所有线程都可见。例如,这意味着一个流可以由一个线程创建,并由同一网格中的任何其他线程使用。但是,通过设备 API 调用创建的流和事件等 CUDA 对象,仅在创建它们的网格内有效。
4.20.2.3. 流和事件
CUDA 的流和事件允许控制核函数启动之间的依赖关系:启动到同一流中的核函数按顺序执行,而事件可用于在流之间创建依赖关系。在设备上创建的流和事件具有完全相同的用途。
#include<stdio.h>__global__voidchildKernel(){printf("Hello ");}__global__voidtailKernel(){printf("World!\n");}__global__voidparentKernel(){// launch childchildKernel<<<1,1>>>();if(cudaSuccess!=cudaGetLastError()){return;}// launch tail into cudaStreamTailLaunch stream// implicitly synchronizes: waits for child to completetailKernel<<<1,1,0,cudaStreamTailLaunch>>>();}intmain(intargc,char*argv[]){// launch parentparentKernel<<<1,1>>>();if(cudaSuccess!=cudaGetLastError()){return1;}// wait for parent to completeif(cudaSuccess!=cudaDeviceSynchronize()){return2;}return0;}
仅支持 CUDA 事件的流间同步功能。这意味着支持cudaStreamWaitEvent(),但不支持cudaEventSynchronize()、cudaEventElapsedTime()和cudaEventQuery()。由于不支持cudaEventElapsedTime(),必须通过cudaEventCreateWithFlags()创建 cudaEvents,并传入cudaEventDisableTiming标志。
如果调用线程打算与其他线程调用的子网格同步,则程序应自行执行充分的线程间同步,例如通过 CUDA 事件。
由于无法从父线程显式同步子工作,因此无法保证子网格中发生的更改对父网格内的线程可见。
4.20.4.2.4. 设备管理
核函数只能控制其正在运行的设备。这意味着设备运行时不支持cudaSetDevice()等设备 API。从 GPU 看到的活动设备(由cudaGetDevice()返回)的设备编号与从主机系统看到的相同。cudaDeviceGetAttribute()调用可以请求有关其他设备的信息,因为此 API 允许将设备 ID 指定为调用的参数。注意,设备运行时不提供可获取所有属性的cudaGetDeviceProperties()API,必须逐个查询属性。
// PTX-level Declaration of cudaLaunchDevice() when .address_size is 64.extern.func(.param.b32func_retval0)cudaLaunchDevice(.param.b64func,.param.b64parameterBuffer,.param.align4.b8gridDimension[12],.param.align4.b8blockDimension[12],.param.b32sharedMemSize,.param.b64stream);
下面的 CUDA 层面声明映射到前述 PTX 层面声明之一,可以在系统头文件cuda_device_runtime_api.h中找到它。该函数定义在cudadevrt系统库中,程序必须链接此库才能使用设备端核函数启动功能。
// CUDA-level declaration of cudaLaunchDevice()extern"C"__device__cudaError_tcudaLaunchDevice(void*func,void*parameterBuffer,dim3gridDimension,dim3blockDimension,unsignedintsharedMemSize,cudaStream_tstream);
// PTX-level Declaration of cudaGetParameterBuffer() when .address_size is 64.extern.func(.param.b64func_retval0)cudaGetParameterBuffer(.param.b64alignment,.param.b64size);
以下cudaGetParameterBuffer()的 CUDA 层面声明映射到前述 PTX 层面声明:
// CUDA-level Declaration of cudaGetParameterBuffer()extern"C"__device__void*cudaGetParameterBuffer(size_talignment,size_tsize);
在 CUDA 中直接访问来自 API 的 GPU 数据,可以使用 CUDA 核函数读写这些数据,从而在其他 API 中使用这些数据时提供 CUDA 功能。主要有两个概念:一种是直接方式,即与 OpenGL 和 Direct3D[9-11] 进行图形互操作,它能够将 OpenGL 和 Direct3D 的资源映射到 CUDA 地址空间;另一种是更灵活的外部资源互操作,它允许通过操作系统级句柄进行导入和导出,以访问内存和同步对象。以下 API 支持这种方式:Direct3D[11-12]、Vulkan 和 NVIDIA 软件通信接口互操作。
4.21.1. 图形互操作性
在使用 CUDA 访问 Direct3D 或 OpenGL 资源(例如 VBO,即顶点缓冲区对象)之前,必须先注册和映射该资源。使用相应的 CUDA 函数进行注册(参见下面的示例),会返回一个类型为structcudaGraphicsResource的 CUDA 图形资源,它持有 CUDA 设备指针或数组。要在核函数中访问设备数据,必须映射该资源。在资源处于已注册状态时,可以根据需要多次映射和取消映射它。核函数使用返回的设备内存地址来访问已映射的资源:对于缓冲区,该地址由cudaGraphicsResourceGetMappedPointer()返回;对于 CUDA 数组,则由cudaGraphicsSubResourceGetMappedArray()返回。一旦 CUDA 不再需要该资源,就可以注销它。
主要步骤如下:
向 CUDA 注册图形缓冲区
映射资源
访问已映射资源的设备指针或数组
在 CUDA 核函数中使用设备指针或数组
取消资源映射
注销资源
注意,注册资源的开销很大,因此理想情况下,每个资源只调用一次注册操作,但是,对于每个打算使用该资源的 CUDA 上下文,都必须单独注册该资源。可以调用cudaGraphicsResourceSetMapFlags()来指定使用提示(只写、只读),CUDA 驱动程序可以利用这些提示优化资源管理。还需注意,在资源处于已映射状态时,通过 OpenGL、Direct3D 或其他 CUDA 上下文访问该资源会产生未定义的结果。
4.21.1.1. OpenGL 互操作性
可以映射到 CUDA 地址空间的 OpenGL 资源包括 OpenGL 缓冲区、纹理和渲染缓冲区对象。缓冲区对象使用cudaGraphicsGLRegisterBuffer()注册,在 CUDA 中表现为普通的设备指针。纹理或渲染缓冲区对象使用cudaGraphicsGLRegisterImage()注册,在 CUDA 中表现为 CUDA 数组。
__global__voidsimple_vbo_kernel(float4*pos,unsignedintwidth,unsignedintheight,floattime){unsignedintx=blockIdx.x*blockDim.x+threadIdx.x;unsignedinty=blockIdx.y*blockDim.y+threadIdx.y;// calculate uv coordinatesfloatu=x/(float)width;floatv=y/(float)height;u=u*2.0f-1.0f;v=v*2.0f-1.0f;// calculate simple sine wave patternfloatfreq=4.0f;floatw=sinf(u*freq+time)*cosf(v*freq+time)*0.5f;// write output vertexpos[y*width+x]=make_float4(u,w,v,1.0f);}intmain(intargc,char**argv){char*ref_file=NULL;pArgc=&argc;pArgv=argv;#if defined(__linux__)setenv("DISPLAY",":0",0);#endifprintf("%s starting...\n",sSDKsample);if(argc>1){if(checkCmdLineFlag(argc,(constchar**)argv,"file")){// In this mode, we are running non-OpenGL and doing a compare of the VBO was generated correctlygetCmdLineArgumentString(argc,(constchar**)argv,"file",(char**)&ref_file);}}printf("\n");// First initialize OpenGL contextif(false==initGL(&argc,argv)){returnfalse;}// register callbacksglutDisplayFunc(display);glutKeyboardFunc(keyboard);glutMouseFunc(mouse);glutMotionFunc(motion);glutCloseFunc(cleanup);// Create an empty vertex buffer object (VBO)// 1. Register the VBO with CUDAcreateVBO(&vbo,&cuda_vbo_resource,cudaGraphicsMapFlagsWriteDiscard);// start rendering mainloop// 5. Render the results using OpenGLglutMainLoop();printf("%s completed, returned %s\n",sSDKsample,(g_TotalErrors==0)?"OK":"ERROR!");exit(g_TotalErrors==0?EXIT_SUCCESS:EXIT_FAILURE);}voidcreateVBO(GLuint*vbo,structcudaGraphicsResource**vbo_res,unsignedintvbo_res_flags){assert(vbo);// create buffer objectglGenBuffers(1,vbo);glBindBuffer(GL_ARRAY_BUFFER,*vbo);// initialize buffer objectunsignedintsize=mesh_width*mesh_height*4*sizeof(float);glBufferData(GL_ARRAY_BUFFER,size,0,GL_DYNAMIC_DRAW);glBindBuffer(GL_ARRAY_BUFFER,0);// register this buffer object with CUDAcheckCudaErrors(cudaGraphicsGLRegisterBuffer(vbo_res,*vbo,vbo_res_flags));SDK_CHECK_ERROR_GL();}voiddisplay(){float4*dptr;// 2. Map the VBO for writing from CUDAcheckCudaErrors(cudaGraphicsMapResources(1,&cuda_vbo_resource,0));size_tnum_bytes;checkCudaErrors(cudaGraphicsResourceGetMappedPointer((void**)&dptr,&num_bytes,cuda_vbo_resource));// 3. Run CUDA kernel to modify the vertex positions//call the CUDA kerneldim3block(8,8,1);dim3grid(mesh_width/block.x,mesh_height/block.y,1);simple_vbo_kernel<<<grid,block>>>(dptr,mesh_width,mesh_height,g_fAnim);// 4. Unmap the VBO checkCudaErrors(cudaGraphicsUnmapResources(1,&cuda_vbo_resource,0));glClear(GL_COLOR_BUFFER_BIT|GL_DEPTH_BUFFER_BIT);// set view matrixglMatrixMode(GL_MODELVIEW);glLoadIdentity();glTranslatef(0.0,0.0,translate_z);glRotatef(rotate_x,1.0,0.0,0.0);glRotatef(rotate_y,0.0,1.0,0.0);// 5. Render the updated using OpenGLglBindBuffer(GL_ARRAY_BUFFER,vbo);glVertexPointer(4,GL_FLOAT,0,0);glEnableClientState(GL_VERTEX_ARRAY);glColor3f(1.0,0.0,0.0);glDrawArrays(GL_POINTS,0,mesh_width*mesh_height);glDisableClientState(GL_VERTEX_ARRAY);glutSwapBuffers();g_fAnim+=0.01f;}voiddeleteVBO(GLuint*vbo,structcudaGraphicsResource*vbo_res){// 6. Unregister and delete VBOcheckCudaErrors(cudaGraphicsUnregisterResource(vbo_res));glBindBuffer(1,*vbo);glDeleteBuffers(1,vbo);*vbo=0;}voidcleanup(){if(vbo){deleteVBO(&vbo,cuda_vbo_resource);}}
限制与注意事项。
对于进行任何 OpenGL 互操作 API 调用的主机线程,其当前 OpenGL 上下文必须是资源正在被共享的那个上下文。
当 OpenGL 纹理变为无绑定纹理时(例如,使用glGetTextureHandle或glGetImageHandleAPI 请求图像或纹理句柄),便无法向 CUDA 注册该纹理。应用程序需要在请求图像或纹理句柄之前注册该纹理以用于互操作。
4.21.1.2. Direct3D 互操作性
Direct3D 互操作支持 Direct3D9、Direct3D10 和 Direct3D11,但不支持 Direct3D12。这里重点介绍 Direct3D11,有关 Direct3D9 和 Direct3D10,请参阅 CUDA 编程指南 12.9。可以映射到 CUDA 地址空间的 Direct3D 资源包括 Direct3D 缓冲区、纹理和表面。这些资源使用cudaGraphicsD3D11RegisterResource()注册。
CUDA 上下文只能与创建时将DriverType设置为D3D_DRIVER_TYPE_HARDWARE的 Direct3D11 设备互操作。
示例:二维纹理 Direct3D11 互操作
以下代码片段来自NVIDIA/cuda-samples中的 simpleD3D11Texture 示例。完整示例包含大量 DX11 样板代码,这里重点介绍 CUDA 端。
CUDA 核函数cuda_kernel_texture_2d在闪烁的蓝色背景上,以移动的红色/绿色阴影线图案绘制二维纹理,它依赖于先前的纹理值。底层数据是二维 CUDA 数组,其中行偏移量由行距定义。
/* * Paint a 2D texture with a moving red/green hatch pattern on a * strobing blue background. Note that this kernel reads to and * writes from the texture, hence why this texture was not mapped * as WriteDiscard. */__global__voidcuda_kernel_texture_2d(unsignedchar*surface,intwidth,intheight,size_tpitch,floatt){intx=blockIdx.x*blockDim.x+threadIdx.x;inty=blockIdx.y*blockDim.y+threadIdx.y;float*pixel;// in the case where, due to quantization into grids, we have// more threads than pixels, skip the threads which don't// correspond to valid pixelsif(x>=width||y>=height)return;// get a pointer to the pixel at (x,y)pixel=(float*)(surface+y*pitch)+4*x;// populate itfloatvalue_x=0.5f+0.5f*cos(t+10.0f*((2.0f*x)/width-1.0f));floatvalue_y=0.5f+0.5f*cos(t+10.0f*((2.0f*y)/height-1.0f));pixel[0]=0.5*pixel[0]+0.5*pow(value_x,3.0f);// redpixel[1]=0.5*pixel[1]+0.5*pow(value_y,3.0f);// greenpixel[2]=0.5f+0.5f*cos(t);// bluepixel[3]=1;// alpha}extern"C"voidcuda_texture_2d(void*surface,intwidth,intheight,size_tpitch,floatt){cudaError_terror=cudaSuccess;dim3Db=dim3(16,16);// block dimensions are fixed to be 256 threadsdim3Dg=dim3((width+Db.x-1)/Db.x,(height+Db.y-1)/Db.y);cuda_kernel_texture_2d<<<Dg,Db>>>((unsignedchar*)surface,width,height,pitch,t);error=cudaGetLastError();if(error!=cudaSuccess){printf("cuda_kernel_texture_2d() failed to launch error = %d\n",error);}}
为使指针与数据缓冲区保持对应,使用以下数据结构:
// Data structure for 2D texture shared between DX11 and CUDAstruct{ID3D11Texture2D*pTexture;ID3D11ShaderResourceView*pSRView;cudaGraphicsResource*cudaResource;void*cudaLinearMemory;size_tpitch;intwidth;intheight;intoffsetInShader;}g_texture_2d;
初始化 Direct3D 设备和纹理后,向 CUDA 注册这些资源一次。为匹配 Direct3D 像素格式,分配 CUDA 数组时采用相同的宽度和高度,以及与 Direct3D 纹理行距匹配的行距。
// register the Direct3D resources that are used in the CUDA kernel// we'll read to and write from g_texture_2d, so don't set any special map flags for itcudaGraphicsD3D11RegisterResource(&g_texture_2d.cudaResource,g_texture_2d.pTexture,cudaGraphicsRegisterFlagsNone);getLastCudaError("cudaGraphicsD3D11RegisterResource (g_texture_2d) failed");// CUDA cannot write into the texture directly : the texture is seen as a// cudaArray and can only be mapped as a texture// Create a buffer so that CUDA can write into it// the pixel fmt is DXGI_FORMAT_R32G32B32A32_FLOATcudaMallocPitch(&g_texture_2d.cudaLinearMemory,&g_texture_2d.pitch,g_texture_2d.width*sizeof(float)*4,g_texture_2d.height);getLastCudaError("cudaMallocPitch (g_texture_2d) failed");cudaMemset(g_texture_2d.cudaLinearMemory,1,g_texture_2d.pitch*g_texture_2d.height);
在渲染循环中,先映射资源,再启动 CUDA 核函数以更新纹理数据,然后取消资源映射。完成此步骤后,使用 Direct3D 设备在屏幕上绘制更新后的纹理。
cudaStream_tstream=0;constintnbResources=3;cudaGraphicsResource*ppResources[nbResources]={g_texture_2d.cudaResource,g_texture_3d.cudaResource,g_texture_cube.cudaResource,};cudaGraphicsMapResources(nbResources,ppResources,stream);getLastCudaError("cudaGraphicsMapResources(3) failed");// run kernels which will populate the contents of those texturesRunKernels();// unmap the resourcescudaGraphicsUnmapResources(nbResources,ppResources,stream);getLastCudaError("cudaGraphicsUnmapResources(3) failed");
最后,当 CUDA 不再需要这些资源时,将注销它们并释放设备数组。
// unregister the Cuda resourcescudaGraphicsUnregisterResource(g_texture_2d.cudaResource);getLastCudaError("cudaGraphicsUnregisterResource (g_texture_2d) failed");cudaFree(g_texture_2d.cudaLinearMemory);getLastCudaError("cudaFree (g_texture_2d) failed");
应用程序应创建多个 CUDA 上下文,为 SLI 配置中的每个 GPU 各创建一个。虽然这不是严格要求,但这样可以避免设备之间不必要的数据传输。应用程序可以使用用于 Direct3D 的cudaD3D[9|10|11]GetDevices()和用于 OpenGL 的cudaGLGetDevices()这两组调用,来确定在当前帧和下一帧中执行渲染的设备所对应的 CUDA 设备句柄。有了这些信息,应用程序通常会选择适当的设备,并将 Direct3D 或 OpenGL 资源映射到当deviceList参数设置为cudaD3D[9|10|11]DeviceListCurrentFrame或cudaGLDeviceListCurrentFrame时,由cudaD3D[9|10|11]GetDevices()或cudaGLGetDevices()返回的 CUDA 设备。
从cudaGraphicsD3D[9|10|11]RegisterResource和cudaGraphicsGLRegister[Buffer|Image]返回的资源只能在进行注册的设备上使用。因此,在 SLI 配置中,当不同帧的数据在不同的 CUDA 设备上计算时,必须为每个设备分别注册资源。
4.21.2. 外部资源互操作性
外部资源互操作性允许 CUDA 导入由 API 显式导出的某些资源。这些对象通常使用操作系统的原生句柄导出,例如 Linux 上的文件描述符或 Windows 上的 NT 句柄。这样可以在其他 API 与 CUDA 之间高效地共享资源,而无须在两者之间进行复制或创建副本。以下 API 支持此功能:Direct3D[11-12]、Vulkan 和 NVIDIA 软件通信接口互操作性。可以导入两种类型的资源:
内存对象
可以使用cudaImportExternalMemory()导入 CUDA。然后,可以在核函数内使用通过cudaExternalMemoryGetMappedBuffer()映射到该内存对象的设备指针,或通过cudaExternalMemoryGetMappedMipmappedArray()映射的 CUDA mipmap 数组来访问已导入的内存对象。根据内存对象的类型,可能可以在单个内存对象上建立多个映射。这些映射必须与导出方 API 建立的映射相匹配。任何不匹配的映射都会导致未定义行为。已导入的内存对象必须使用cudaDestroyExternalMemory()释放。释放内存对象不会释放到该对象的任何映射。因此,映射到该对象的任何设备指针都必须使用cudaFree()显式释放,映射到该对象的任何 CUDA mipmap 数组都必须使用cudaFreeMipmappedArray()显式释放。在对象被销毁后访问到该对象的映射是非法的。
为了导出内存对象,创建 Vulkan 实例时必须启用VK_KHR_external_memory_capabilities扩展,创建设备时必须启用VK_KHR_external_memory。此外,还必须启用平台特定的句柄类型,在 Windows 上为VK_KHR_external_memory_win32,在基于 UNIX 的系统上为VK_KHR_external_memory_fd。
类似地,为了导出同步对象,需要在设备级别启用VK_KHR_external_semaphore_capabilities,在实例级别启用VK_KHR_external_semaphore。还需要启用平台特定的句柄扩展,即 Windows 上的VK_KHR_external_semaphore_win32和基于 Unix 的系统上的VK_KHR_external_semaphore_fd。
导入由 Vulkan 导出的内存和同步对象时,必须在创建这些对象的同一设备上导入并映射它们。通过比较 CUDA 设备的 UUID 与 Vulkan 物理设备的 UUID,可以确定与创建这些对象的 Vulkan 物理设备相对应的 CUDA 设备,如以下来自 simpleVulkan 示例的代码片段所示。其中,vkDeviceUUID是 Vulkan API 结构体vkPhysicalDeviceIDProperties.deviceUUID的成员,定义了当前 Vulkan 实例的物理设备 ID。
// from the CUDA example `simpleVulkan`intSineWaveSimulation::initCuda(uint8_t*vkDeviceUUID,size_tUUID_SIZE){intcurrent_device=0;intdevice_count=0;intdevices_prohibited=0;cudaDevicePropdeviceProp;checkCudaErrors(cudaGetDeviceCount(&device_count));if(device_count==0){fprintf(stderr,"CUDA error: no devices supporting CUDA.\n");exit(EXIT_FAILURE);}// Find the GPU which is selected by Vulkanwhile(current_device<device_count){cudaGetDeviceProperties(&deviceProp,current_device);if((deviceProp.computeMode!=cudaComputeModeProhibited)){// Compare the cuda device UUID with vulkan UUIDintret=memcmp((void*)&deviceProp.uuid,vkDeviceUUID,UUID_SIZE);if(ret==0){checkCudaErrors(cudaSetDevice(current_device));checkCudaErrors(cudaGetDeviceProperties(&deviceProp,current_device));printf("GPU Device %d: \"%s\" with compute capability %d.%d\n\n",current_device,deviceProp.name,deviceProp.major,deviceProp.minor);returncurrent_device;}}else{devices_prohibited++;}current_device++;}if(devices_prohibited==device_count){fprintf(stderr,"CUDA error:"" No Vulkan-CUDA Interop capable GPU found.\n");exit(EXIT_FAILURE);}return-1;}
voidVulkanBaseApp::createExternalBuffer(VkDeviceSizesize,VkBufferUsageFlagsusage,VkMemoryPropertyFlagsproperties,VkExternalMemoryHandleTypeFlagsKHRextMemHandleType,VkBuffer&buffer,VkDeviceMemory&bufferMemory){VkBufferCreateInfobufferInfo={};bufferInfo.sType=VK_STRUCTURE_TYPE_BUFFER_CREATE_INFO;bufferInfo.size=size;bufferInfo.usage=usage;bufferInfo.sharingMode=VK_SHARING_MODE_EXCLUSIVE;VkExternalMemoryBufferCreateInfoexternalMemoryBufferInfo={};externalMemoryBufferInfo.sType=VK_STRUCTURE_TYPE_EXTERNAL_MEMORY_BUFFER_CREATE_INFO;externalMemoryBufferInfo.handleTypes=extMemHandleType;bufferInfo.pNext=&externalMemoryBufferInfo;if(vkCreateBuffer(m_device,&bufferInfo,nullptr,&buffer)!=VK_SUCCESS){throwstd::runtime_error("failed to create buffer!");}VkMemoryRequirementsmemRequirements;vkGetBufferMemoryRequirements(m_device,buffer,&memRequirements);#ifdef _WIN64WindowsSecurityAttributeswinSecurityAttributes;VkExportMemoryWin32HandleInfoKHRvulkanExportMemoryWin32HandleInfoKHR={};vulkanExportMemoryWin32HandleInfoKHR.sType=VK_STRUCTURE_TYPE_EXPORT_MEMORY_WIN32_HANDLE_INFO_KHR;vulkanExportMemoryWin32HandleInfoKHR.pNext=NULL;vulkanExportMemoryWin32HandleInfoKHR.pAttributes=&winSecurityAttributes;vulkanExportMemoryWin32HandleInfoKHR.dwAccess=DXGI_SHARED_RESOURCE_READ|DXGI_SHARED_RESOURCE_WRITE;vulkanExportMemoryWin32HandleInfoKHR.name=(LPCWSTR)NULL;#endif /* _WIN64 */VkExportMemoryAllocateInfoKHRvulkanExportMemoryAllocateInfoKHR={};vulkanExportMemoryAllocateInfoKHR.sType=VK_STRUCTURE_TYPE_EXPORT_MEMORY_ALLOCATE_INFO_KHR;#ifdef _WIN64vulkanExportMemoryAllocateInfoKHR.pNext=extMemHandleType&VK_EXTERNAL_MEMORY_HANDLE_TYPE_OPAQUE_WIN32_BIT_KHR?&vulkanExportMemoryWin32HandleInfoKHR:NULL;vulkanExportMemoryAllocateInfoKHR.handleTypes=extMemHandleType;#elsevulkanExportMemoryAllocateInfoKHR.pNext=NULL;vulkanExportMemoryAllocateInfoKHR.handleTypes=VK_EXTERNAL_MEMORY_HANDLE_TYPE_OPAQUE_FD_BIT;#endif /* _WIN64 */VkMemoryAllocateInfoallocInfo={};allocInfo.sType=VK_STRUCTURE_TYPE_MEMORY_ALLOCATE_INFO;allocInfo.pNext=&vulkanExportMemoryAllocateInfoKHR;allocInfo.allocationSize=memRequirements.size;allocInfo.memoryTypeIndex=findMemoryType(m_physicalDevice,memRequirements.memoryTypeBits,properties);if(vkAllocateMemory(m_device,&allocInfo,nullptr,&bufferMemory)!=VK_SUCCESS){throwstd::runtime_error("failed to allocate external buffer memory!");}vkBindBufferMemory(m_device,buffer,bufferMemory,0);}
4.21.2.1.4. 导出 Vulkan 同步对象
在 GPU 上执行的 Vulkan API 调用是异步的。为了定义执行顺序,Vulkan 提供了可与 CUDA 共享的信号量和栅栏。与内存对象类似,信号量可以由 Vulkan 导出,创建信号量时需要根据其类型指定导出标志。信号量分为二进制信号量和时间线信号量。二进制信号量只有一个 1 位计数器,表示已发出信号或未发出信号。时间线信号量有一个 64 位计数器,可以使用同一个信号量来定义执行顺序。simpleVulkan示例中包含时间线信号量和二进制信号量两者的代码路径。
voidVulkanBaseApp::createExternalSemaphore(VkSemaphore&semaphore,VkExternalSemaphoreHandleTypeFlagBitshandleType){VkSemaphoreCreateInfosemaphoreInfo={};semaphoreInfo.sType=VK_STRUCTURE_TYPE_SEMAPHORE_CREATE_INFO;VkExportSemaphoreCreateInfoKHRexportSemaphoreCreateInfo={};exportSemaphoreCreateInfo.sType=VK_STRUCTURE_TYPE_EXPORT_SEMAPHORE_CREATE_INFO_KHR;#ifdef _VK_TIMELINE_SEMAPHOREVkSemaphoreTypeCreateInfotimelineCreateInfo;timelineCreateInfo.sType=VK_STRUCTURE_TYPE_SEMAPHORE_TYPE_CREATE_INFO;timelineCreateInfo.pNext=NULL;timelineCreateInfo.semaphoreType=VK_SEMAPHORE_TYPE_TIMELINE;timelineCreateInfo.initialValue=0;exportSemaphoreCreateInfo.pNext=&timelineCreateInfo;#elseexportSemaphoreCreateInfo.pNext=NULL;#endif /* _VK_TIMELINE_SEMAPHORE */exportSemaphoreCreateInfo.handleTypes=handleType;semaphoreInfo.pNext=&exportSemaphoreCreateInfo;if(vkCreateSemaphore(m_device,&semaphoreInfo,nullptr,&semaphore)!=VK_SUCCESS){throwstd::runtime_error("failed to create synchronization objects for a CUDA-Vulkan!");}}
在 Windows 中,可以使用与对象关联的 NT 句柄,将使用VK_EXTERNAL_MEMORY_HANDLE_TYPE_OPAQUE_WIN32_BIT导出的 Vulkan 内存对象导入 CUDA,如下所示。注意,CUDA 不会接管 NT 句柄的所有权,应用程序有责任在不再需要该句柄时将其关闭。NT 句柄持有对该资源的引用,因此必须先显式释放该句柄,才能释放底层内存。
在 Linux 中,可以使用与对象关联的文件描述符,将使用VK_EXTERNAL_MEMORY_HANDLE_TYPE_OPAQUE_FD_BIT导出的 Vulkan 内存对象导入 CUDA,如下所示。注意,一旦导入,CUDA 就会接管该文件描述符的所有权。在成功导入后使用该文件描述符会导致未定义行为。
// from the CUDA example `simpleVulkan`voidimportCudaExternalMemory(void**cudaPtr,cudaExternalMemory_t&cudaMem,VkDeviceMemory&vkMem,VkDeviceSizesize,VkExternalMemoryHandleTypeFlagBitshandleType){cudaExternalMemoryHandleDescexternalMemoryHandleDesc={};if(handleType&VK_EXTERNAL_SEMAPHORE_HANDLE_TYPE_OPAQUE_WIN32_BIT){externalMemoryHandleDesc.type=cudaExternalMemoryHandleTypeOpaqueWin32;}elseif(handleType&VK_EXTERNAL_SEMAPHORE_HANDLE_TYPE_OPAQUE_WIN32_KMT_BIT){externalMemoryHandleDesc.type=cudaExternalMemoryHandleTypeOpaqueWin32Kmt;}elseif(handleType&VK_EXTERNAL_SEMAPHORE_HANDLE_TYPE_OPAQUE_FD_BIT){externalMemoryHandleDesc.type=cudaExternalMemoryHandleTypeOpaqueFd;}else{throwstd::runtime_error("Unknown handle type requested!");}externalMemoryHandleDesc.size=size;#ifdef _WIN64externalMemoryHandleDesc.handle.win32.handle=(HANDLE)getMemHandle(vkMem,handleType);#elseexternalMemoryHandleDesc.handle.fd=(int)(uintptr_t)getMemHandle(vkMem,handleType);#endifcheckCudaErrors(cudaImportExternalMemory(&cudaMem,&externalMemoryHandleDesc));
导入内存对象后,必须先对其进行映射才能使用。可以将设备指针映射到已导入的内存对象,如下所示。映射的偏移量和大小必须与使用相应 Vulkan API 创建映射时指定的值相匹配。所有已映射的设备指针都必须使用cudaFree()释放。
// from the CUDA example `simpleVulkan`, continuation of function `importCudaExternalMemory`cudaExternalMemoryBufferDescexternalMemBufferDesc={};externalMemBufferDesc.offset=0;externalMemBufferDesc.size=size;externalMemBufferDesc.flags=0;checkCudaErrors(cudaExternalMemoryGetMappedBuffer(cudaPtr,cudaMem,&externalMemBufferDesc));}
4.21.2.1.7. 将 mipmap 数组映射到已导入的内存对象
可以将 CUDA mipmap 数组映射到已导入的内存对象,如下所示。偏移量、各维尺寸、格式和 mip 级别数必须与使用相应 Vulkan API 创建映射时指定的值相匹配。此外,如果该 mipmap 数组在 Vulkan 中被绑定为颜色目标,则必须设置标志cudaArrayColorAttachment。所有已映射的 mipmap 数组都必须使用cudaFreeMipmappedArray()释放。以下独立代码片段展示了在将 mipmap 数组映射到已导入的内存对象时,如何将 Vulkan 参数转换为相应的 CUDA 参数。
cudaMipmappedArray_tmapMipmappedArrayOntoExternalMemory(cudaExternalMemory_textMem,unsignedlonglongoffset,cudaChannelFormatDesc*formatDesc,cudaExtent*extent,unsignedintflags,unsignedintnumLevels){cudaMipmappedArray_tmipmap=NULL;cudaExternalMemoryMipmappedArrayDescdesc={};memset(&desc,0,sizeof(desc));desc.offset=offset;desc.formatDesc=*formatDesc;desc.extent=*extent;desc.flags=flags;desc.numLevels=numLevels;// Note: 'mipmap' must eventually be freed using cudaFreeMipmappedArray()cudaExternalMemoryGetMappedMipmappedArray(&mipmap,extMem,&desc);returnmipmap;}//end mapMipmappedArrayOntoExternalMemory//begin getCudaChannelFormatDescForVulkanFormatcudaChannelFormatDescgetCudaChannelFormatDescForVulkanFormat(VkFormatformat){cudaChannelFormatDescd;memset(&d,0,sizeof(d));switch(format){caseVK_FORMAT_R8_UINT:d.x=8;d.y=0;d.z=0;d.w=0;d.f=cudaChannelFormatKindUnsigned;break;caseVK_FORMAT_R8_SINT:d.x=8;d.y=0;d.z=0;d.w=0;d.f=cudaChannelFormatKindSigned;break;caseVK_FORMAT_R8G8_UINT:d.x=8;d.y=8;d.z=0;d.w=0;d.f=cudaChannelFormatKindUnsigned;break;caseVK_FORMAT_R8G8_SINT:d.x=8;d.y=8;d.z=0;d.w=0;d.f=cudaChannelFormatKindSigned;break;caseVK_FORMAT_R8G8B8A8_UINT:d.x=8;d.y=8;d.z=8;d.w=8;d.f=cudaChannelFormatKindUnsigned;break;caseVK_FORMAT_R8G8B8A8_SINT:d.x=8;d.y=8;d.z=8;d.w=8;d.f=cudaChannelFormatKindSigned;break;caseVK_FORMAT_R16_UINT:d.x=16;d.y=0;d.z=0;d.w=0;d.f=cudaChannelFormatKindUnsigned;break;caseVK_FORMAT_R16_SINT:d.x=16;d.y=0;d.z=0;d.w=0;d.f=cudaChannelFormatKindSigned;break;caseVK_FORMAT_R16G16_UINT:d.x=16;d.y=16;d.z=0;d.w=0;d.f=cudaChannelFormatKindUnsigned;break;caseVK_FORMAT_R16G16_SINT:d.x=16;d.y=16;d.z=0;d.w=0;d.f=cudaChannelFormatKindSigned;break;caseVK_FORMAT_R16G16B16A16_UINT:d.x=16;d.y=16;d.z=16;d.w=16;d.f=cudaChannelFormatKindUnsigned;break;caseVK_FORMAT_R16G16B16A16_SINT:d.x=16;d.y=16;d.z=16;d.w=16;d.f=cudaChannelFormatKindSigned;break;caseVK_FORMAT_R32_UINT:d.x=32;d.y=0;d.z=0;d.w=0;d.f=cudaChannelFormatKindUnsigned;break;caseVK_FORMAT_R32_SINT:d.x=32;d.y=0;d.z=0;d.w=0;d.f=cudaChannelFormatKindSigned;break;caseVK_FORMAT_R32_SFLOAT:d.x=32;d.y=0;d.z=0;d.w=0;d.f=cudaChannelFormatKindFloat;break;caseVK_FORMAT_R32G32_UINT:d.x=32;d.y=32;d.z=0;d.w=0;d.f=cudaChannelFormatKindUnsigned;break;caseVK_FORMAT_R32G32_SINT:d.x=32;d.y=32;d.z=0;d.w=0;d.f=cudaChannelFormatKindSigned;break;caseVK_FORMAT_R32G32_SFLOAT:d.x=32;d.y=32;d.z=0;d.w=0;d.f=cudaChannelFormatKindFloat;break;caseVK_FORMAT_R32G32B32A32_UINT:d.x=32;d.y=32;d.z=32;d.w=32;d.f=cudaChannelFormatKindUnsigned;break;caseVK_FORMAT_R32G32B32A32_SINT:d.x=32;d.y=32;d.z=32;d.w=32;d.f=cudaChannelFormatKindSigned;break;caseVK_FORMAT_R32G32B32A32_SFLOAT:d.x=32;d.y=32;d.z=32;d.w=32;d.f=cudaChannelFormatKindFloat;break;default:assert(0);}returnd;}//end getCudaChannelFormatDescForVulkanFormat//begin getCudaExtentForVulkanExtentcudaExtentgetCudaExtentForVulkanExtent(VkExtent3DvkExt,uint32_tarrayLayers,VkImageViewTypevkImageViewType){cudaExtente={0,0,0};switch(vkImageViewType){caseVK_IMAGE_VIEW_TYPE_1D:e.width=vkExt.width;e.height=0;e.depth=0;break;caseVK_IMAGE_VIEW_TYPE_2D:e.width=vkExt.width;e.height=vkExt.height;e.depth=0;break;caseVK_IMAGE_VIEW_TYPE_3D:e.width=vkExt.width;e.height=vkExt.height;e.depth=vkExt.depth;break;caseVK_IMAGE_VIEW_TYPE_CUBE:e.width=vkExt.width;e.height=vkExt.height;e.depth=arrayLayers;break;caseVK_IMAGE_VIEW_TYPE_1D_ARRAY:e.width=vkExt.width;e.height=0;e.depth=arrayLayers;break;caseVK_IMAGE_VIEW_TYPE_2D_ARRAY:e.width=vkExt.width;e.height=vkExt.height;e.depth=arrayLayers;break;caseVK_IMAGE_VIEW_TYPE_CUBE_ARRAY:e.width=vkExt.width;e.height=vkExt.height;e.depth=arrayLayers;break;default:assert(0);}returne;}//end getCudaExtentForVulkanExtent//begin getCudaMipmappedArrayFlagsForVulkanImageunsignedintgetCudaMipmappedArrayFlagsForVulkanImage(VkImageViewTypevkImageViewType,VkImageUsageFlagsvkImageUsageFlags,boolallowSurfaceLoadStore){unsignedintflags=0;switch(vkImageViewType){caseVK_IMAGE_VIEW_TYPE_CUBE:flags|=cudaArrayCubemap;break;caseVK_IMAGE_VIEW_TYPE_CUBE_ARRAY:flags|=cudaArrayCubemap|cudaArrayLayered;break;caseVK_IMAGE_VIEW_TYPE_1D_ARRAY:flags|=cudaArrayLayered;break;caseVK_IMAGE_VIEW_TYPE_2D_ARRAY:flags|=cudaArrayLayered;break;default:break;}if(vkImageUsageFlags&VK_IMAGE_USAGE_COLOR_ATTACHMENT_BIT){flags|=cudaArrayColorAttachment;}if(allowSurfaceLoadStore){flags|=cudaArraySurfaceLoadStore;}returnflags;}
而对于使用VK_EXTERNAL_SEMAPHORE_HANDLE_TYPE_OPAQUE_WIN32_BIT导出的 Vulkan 信号量对象,可以使用与该对象关联的 NT 句柄将其导入 CUDA,如下所示。注意,CUDA 不会接管 NT 句柄的所有权,应用程序有责任在不再需要该句柄时将其关闭。NT 句柄持有对该资源的引用,因此必须先显式释放该句柄,才能释放底层信号量。
#ifdef _VK_TIMELINE_SEMAPHOREstaticuint64_twaitValue=1;staticuint64_tsignalValue=2;cudaExternalSemaphoreWaitParamswaitParams={};waitParams.flags=0;waitParams.params.fence.value=waitValue;cudaExternalSemaphoreSignalParamssignalParams={};signalParams.flags=0;signalParams.params.fence.value=signalValue;// Wait for vulkan to complete it's workcheckCudaErrors(cudaWaitExternalSemaphoresAsync(&m_cudaTimelineSemaphore,&waitParams,1,m_stream));// Now step the simulation, call CUDA kernelm_sim.stepSimulation(time,m_stream);// Signal vulkan to continue with the updated bufferscheckCudaErrors(cudaSignalExternalSemaphoresAsync(&m_cudaTimelineSemaphore,&signalParams,1,m_stream));waitValue+=2;signalValue+=2;#elsecudaExternalSemaphoreWaitParamswaitParams={};waitParams.flags=0;waitParams.params.fence.value=0;cudaExternalSemaphoreSignalParamssignalParams={};signalParams.flags=0;signalParams.params.fence.value=0;// Wait for vulkan to complete it's workcheckCudaErrors(cudaWaitExternalSemaphoresAsync(&m_cudaWaitSemaphore,&waitParams,1,m_stream));// Now step the simulation, call CUDA kernelm_sim.stepSimulation(time,m_stream);// Signal vulkan to continue with the updated bufferscheckCudaErrors(cudaSignalExternalSemaphoresAsync(&m_cudaSignalSemaphore,&signalParams,1,m_stream));#endif /* _VK_TIMELINE_SEMAPHORE */
从 NT 句柄导入内存对象有几种不同的方法。注意,当不再需要 NT 句柄时,应用程序有责任将其关闭。NT 句柄持有对资源的引用,因此必须显式释放该句柄,才能释放底层内存。导入 Direct3D 资源时,必须设置标志cudaExternalMemoryDedicated,如下面的代码片段所示。
在调用ID3D12Device::CreateHeap时通过设置标志D3D12_HEAP_FLAG_SHARED创建的可共享 Direct3D12 堆内存对象,可以使用与该对象关联的 NT 句柄导入 CUDA,如下所示。
cudaExternalMemory_timportD3D12HeapFromNTHandle(HANDLEhandle,unsignedlonglongsize){cudaExternalMemory_textMem=NULL;cudaExternalMemoryHandleDescdesc={};memset(&desc,0,sizeof(desc));desc.type=cudaExternalMemoryHandleTypeD3D12Heap;desc.handle.win32.handle=(void*)handle;desc.size=size;cudaImportExternalMemory(&extMem,&desc);// Input parameter 'handle' should be closed if it's not needed anymoreCloseHandle(handle);returnextMem;}
在调用D3D12Device::CreateCommittedResource时通过设置标志D3D12_HEAP_FLAG_SHARED创建的可共享 Direct3D12 已提交资源,可以使用与该对象关联的 NT 句柄导入 CUDA,如下所示。导入 Direct3D12 已提交资源时,必须设置标志cudaExternalMemoryDedicated。
cudaExternalMemory_timportD3D12CommittedResourceFromNTHandle(HANDLEhandle,unsignedlonglongsize){cudaExternalMemory_textMem=NULL;cudaExternalMemoryHandleDescdesc={};memset(&desc,0,sizeof(desc));desc.type=cudaExternalMemoryHandleTypeD3D12Resource;desc.handle.win32.handle=(void*)handle;desc.size=size;desc.flags|=cudaExternalMemoryDedicated;cudaImportExternalMemory(&extMem,&desc);// Input parameter 'handle' should be closed if it's not needed anymoreCloseHandle(handle);returnextMem;}
可以将设备指针映射到导入的内存对象,如下所示。映射的偏移量和大小必须与使用相应的 Direct3D12 API 创建映射时指定的值一致。所有映射的设备指针都必须使用cudaFree()释放。
void*mapBufferOntoExternalMemory(cudaExternalMemory_textMem,unsignedlonglongoffset,unsignedlonglongsize){void*ptr=NULL;cudaExternalMemoryBufferDescdesc={};memset(&desc,0,sizeof(desc));desc.offset=offset;desc.size=size;cudaExternalMemoryGetMappedBuffer(&ptr,extMem,&desc);// Note: 'ptr' must eventually be freed using cudaFree()returnptr;}
4.21.2.2.4. 将多级渐远纹理数组映射到导入的内存对象
可以将 CUDA 多级渐远纹理数组映射到导入的内存对象,如下所示。偏移量、维度、格式和 mip 级别数必须与使用相应的 Direct3D12 API 创建映射时指定的值一致。此外,如果该多级渐远纹理数组可以在 Direct3D12 中绑定为渲染目标,则必须设置标志cudaArrayColorAttachment。所有映射的多级渐远纹理数组都必须使用cudaFreeMipmappedArray()释放。以下代码示例展示了在将多级渐远纹理数组映射到导入的内存对象时,如何将参数转换为相应的 CUDA 参数。
cudaMipmappedArray_tmapMipmappedArrayOntoExternalMemory(cudaExternalMemory_textMem,unsignedlonglongoffset,cudaChannelFormatDesc*formatDesc,cudaExtent*extent,unsignedintflags,unsignedintnumLevels){cudaMipmappedArray_tmipmap=NULL;cudaExternalMemoryMipmappedArrayDescdesc={};memset(&desc,0,sizeof(desc));desc.offset=offset;desc.formatDesc=*formatDesc;desc.extent=*extent;desc.flags=flags;desc.numLevels=numLevels;// Note: 'mipmap' must eventually be freed using cudaFreeMipmappedArray()cudaExternalMemoryGetMappedMipmappedArray(&mipmap,extMem,&desc);returnmipmap;}cudaChannelFormatDescgetCudaChannelFormatDescForDxgiFormat(DXGI_FORMATdxgiFormat){cudaChannelFormatDescd;memset(&d,0,sizeof(d));switch(dxgiFormat){caseDXGI_FORMAT_R8_UINT:d.x=8;d.y=0;d.z=0;d.w=0;d.f=cudaChannelFormatKindUnsigned;break;caseDXGI_FORMAT_R8_SINT:d.x=8;d.y=0;d.z=0;d.w=0;d.f=cudaChannelFormatKindSigned;break;caseDXGI_FORMAT_R8G8_UINT:d.x=8;d.y=8;d.z=0;d.w=0;d.f=cudaChannelFormatKindUnsigned;break;caseDXGI_FORMAT_R8G8_SINT:d.x=8;d.y=8;d.z=0;d.w=0;d.f=cudaChannelFormatKindSigned;break;caseDXGI_FORMAT_R8G8B8A8_UINT:d.x=8;d.y=8;d.z=8;d.w=8;d.f=cudaChannelFormatKindUnsigned;break;caseDXGI_FORMAT_R8G8B8A8_SINT:d.x=8;d.y=8;d.z=8;d.w=8;d.f=cudaChannelFormatKindSigned;break;caseDXGI_FORMAT_R16_UINT:d.x=16;d.y=0;d.z=0;d.w=0;d.f=cudaChannelFormatKindUnsigned;break;caseDXGI_FORMAT_R16_SINT:d.x=16;d.y=0;d.z=0;d.w=0;d.f=cudaChannelFormatKindSigned;break;caseDXGI_FORMAT_R16G16_UINT:d.x=16;d.y=16;d.z=0;d.w=0;d.f=cudaChannelFormatKindUnsigned;break;caseDXGI_FORMAT_R16G16_SINT:d.x=16;d.y=16;d.z=0;d.w=0;d.f=cudaChannelFormatKindSigned;break;caseDXGI_FORMAT_R16G16B16A16_UINT:d.x=16;d.y=16;d.z=16;d.w=16;d.f=cudaChannelFormatKindUnsigned;break;caseDXGI_FORMAT_R16G16B16A16_SINT:d.x=16;d.y=16;d.z=16;d.w=16;d.f=cudaChannelFormatKindSigned;break;caseDXGI_FORMAT_R32_UINT:d.x=32;d.y=0;d.z=0;d.w=0;d.f=cudaChannelFormatKindUnsigned;break;caseDXGI_FORMAT_R32_SINT:d.x=32;d.y=0;d.z=0;d.w=0;d.f=cudaChannelFormatKindSigned;break;caseDXGI_FORMAT_R32_FLOAT:d.x=32;d.y=0;d.z=0;d.w=0;d.f=cudaChannelFormatKindFloat;break;caseDXGI_FORMAT_R32G32_UINT:d.x=32;d.y=32;d.z=0;d.w=0;d.f=cudaChannelFormatKindUnsigned;break;caseDXGI_FORMAT_R32G32_SINT:d.x=32;d.y=32;d.z=0;d.w=0;d.f=cudaChannelFormatKindSigned;break;caseDXGI_FORMAT_R32G32_FLOAT:d.x=32;d.y=32;d.z=0;d.w=0;d.f=cudaChannelFormatKindFloat;break;caseDXGI_FORMAT_R32G32B32A32_UINT:d.x=32;d.y=32;d.z=32;d.w=32;d.f=cudaChannelFormatKindUnsigned;break;caseDXGI_FORMAT_R32G32B32A32_SINT:d.x=32;d.y=32;d.z=32;d.w=32;d.f=cudaChannelFormatKindSigned;break;caseDXGI_FORMAT_R32G32B32A32_FLOAT:d.x=32;d.y=32;d.z=32;d.w=32;d.f=cudaChannelFormatKindFloat;break;default:assert(0);}returnd;}cudaExtentgetCudaExtentForD3D12Extent(UINT64width,UINTheight,UINT16depthOrArraySize,D3D12_SRV_DIMENSIONd3d12SRVDimension){cudaExtente={0,0,0};switch(d3d12SRVDimension){caseD3D12_SRV_DIMENSION_TEXTURE1D:e.width=width;e.height=0;e.depth=0;break;caseD3D12_SRV_DIMENSION_TEXTURE2D:e.width=width;e.height=height;e.depth=0;break;caseD3D12_SRV_DIMENSION_TEXTURE3D:e.width=width;e.height=height;e.depth=depthOrArraySize;break;caseD3D12_SRV_DIMENSION_TEXTURECUBE:e.width=width;e.height=height;e.depth=depthOrArraySize;break;caseD3D12_SRV_DIMENSION_TEXTURE1DARRAY:e.width=width;e.height=0;e.depth=depthOrArraySize;break;caseD3D12_SRV_DIMENSION_TEXTURE2DARRAY:e.width=width;e.height=height;e.depth=depthOrArraySize;break;caseD3D12_SRV_DIMENSION_TEXTURECUBEARRAY:e.width=width;e.height=height;e.depth=depthOrArraySize;break;default:assert(0);}returne;}unsignedintgetCudaMipmappedArrayFlagsForD3D12Resource(D3D12_SRV_DIMENSIONd3d12SRVDimension,D3D12_RESOURCE_FLAGSd3d12ResourceFlags,boolallowSurfaceLoadStore){unsignedintflags=0;switch(d3d12SRVDimension){caseD3D12_SRV_DIMENSION_TEXTURECUBE:flags|=cudaArrayCubemap;break;caseD3D12_SRV_DIMENSION_TEXTURECUBEARRAY:flags|=cudaArrayCubemap|cudaArrayLayered;break;caseD3D12_SRV_DIMENSION_TEXTURE1DARRAY:flags|=cudaArrayLayered;break;caseD3D12_SRV_DIMENSION_TEXTURE2DARRAY:flags|=cudaArrayLayered;break;default:break;}if(d3d12ResourceFlags&D3D12_RESOURCE_FLAG_ALLOW_RENDER_TARGET){flags|=cudaArrayColorAttachment;}if(allowSurfaceLoadStore){flags|=cudaArraySurfaceLoadStore;}returnflags;}
4.21.2.2.5. 导入同步对象
在调用ID3D12Device::CreateFence时通过设置标志D3D12_FENCE_FLAG_SHARED创建的可共享 Direct3D12 栅栏对象,可以使用与该对象关联的 NT 句柄导入 CUDA,如下所示。注意,当不再需要该句柄时,应用程序有责任将其关闭。NT 句柄持有对资源的引用,因此必须显式释放该句柄,才能释放底层信号量。
cudaExternalSemaphore_timportD3D12FenceFromNTHandle(HANDLEhandle){cudaExternalSemaphore_textSem=NULL;cudaExternalSemaphoreHandleDescdesc={};memset(&desc,0,sizeof(desc));desc.type=cudaExternalSemaphoreHandleTypeD3D12Fence;desc.handle.win32.handle=handle;cudaImportExternalSemaphore(&extSem,&desc);// Input parameter 'handle' should be closed if it's not needed anymoreCloseHandle(handle);returnextSem;}
NvSciBufObjcreateNvSciBufObject(){// Raw Buffer Attributes for CUDANvSciBufTypebufType=NvSciBufType_RawBuffer;uint64_trawsize=SIZE;uint64_talign=0;boolcpuaccess_flag=true;NvSciBufAttrValAccessPermperm=NvSciBufAccessPerm_ReadWrite;NvSciRmGpuIdgpuid[]={};CUuuiduuid;cuDeviceGetUuid(&uuid,dev);memcpy(&gpuid[0].bytes,&uuid.bytes,sizeof(uuid.bytes));// Disable cache on devNvSciBufAttrValGpuCachegpuCache[]={{gpuid[0],false}};NvSciBufAttrValGpuCompressiongpuCompression[]={{gpuid[0],NvSciBufCompressionType_GenericCompressible}};// Fill in valuesNvSciBufAttrKeyValuePairrawbuffattrs[]={{NvSciBufGeneralAttrKey_Types,&bufType,sizeof(bufType)},{NvSciBufRawBufferAttrKey_Size,&rawsize,sizeof(rawsize)},{NvSciBufRawBufferAttrKey_Align,&align,sizeof(align)},{NvSciBufGeneralAttrKey_NeedCpuAccess,&cpuaccess_flag,sizeof(cpuaccess_flag)},{NvSciBufGeneralAttrKey_RequiredPerm,&perm,sizeof(perm)},{NvSciBufGeneralAttrKey_GpuId,&gpuid,sizeof(gpuid)},{NvSciBufGeneralAttrKey_EnableGpuCache,&gpuCache,sizeof(gpuCache)},{NvSciBufGeneralAttrKey_EnableGpuCompression,&gpuCompression,sizeof(gpuCompression)}};// Create list by setting attributeserr=NvSciBufAttrListSetAttrs(attrListBuffer,rawbuffattrs,sizeof(rawbuffattrs)/sizeof(NvSciBufAttrKeyValuePair));NvSciBufAttrListCreate(NvSciBufModule,&attrListBuffer);// Reconcile And AllocateNvSciBufAttrListReconcile(&attrListBuffer,1,&attrListReconciledBuffer,&attrListConflictBuffer)NvSciBufObjAlloc(attrListReconciledBuffer,&bufferObjRaw);returnbufferObjRaw;}
NvSciBufObjbufferObjRo;// Readonly NvSciBuf memory obj// Create a duplicate handle to the same memory buffer with reduced permissionsNvSciBufObjDupWithReducePerm(bufferObjRaw,NvSciBufAccessPerm_Readonly,&bufferObjRo);returnbufferObjRo;
可以使用 NvSciBufObj 句柄将分配的 NvSciBuf 内存对象导入 CUDA,如下所示。应用程序应查询分配的 NvSciBufObj,以获取填写 CUDA 外部内存描述符所需的属性。注意,属性列表和 NvSciBuf 对象应由应用程序维护。如果导入 CUDA 的 NvSciBuf 对象也被其他驱动程序映射,那么应用程序必须根据NvSciBufGeneralAttrKey_GpuSwNeedCacheCoherency输出属性的值,使用 NvSciSync 对象(请参阅导入同步对象)作为适当的屏障,以维持 CUDA 与其他驱动程序之间的相干性。
cudaExternalMemory_timportNvSciBufObject(NvSciBufObjbufferObjRaw){/*************** Query NvSciBuf Object **************/NvSciBufAttrKeyValuePairbufattrs[]={{NvSciBufRawBufferAttrKey_Size,NULL,0},{NvSciBufGeneralAttrKey_GpuSwNeedCacheCoherency,NULL,0},{NvSciBufGeneralAttrKey_EnableGpuCompression,NULL,0}};NvSciBufAttrListGetAttrs(retList,bufattrs,sizeof(bufattrs)/sizeof(NvSciBufAttrKeyValuePair)));ret_size=*(static_cast<constuint64_t*>(bufattrs[0].value));// Note cache and compression are per GPU attributes, so read values for specific gpu by comparing UUID// Read cacheability granted by NvSciBufintnumGpus=bufattrs[1].len/sizeof(NvSciBufAttrValGpuCache);NvSciBufAttrValGpuCache[]cacheVal=(NvSciBufAttrValGpuCache*)bufattrs[1].value;boolret_cacheVal;for(inti=0;i<numGpus;i++){if(memcmp(gpuid[0].bytes,cacheVal[i].gpuId.bytes,sizeof(CUuuid))==0){ret_cacheVal=cacheVal[i].cacheability);}}// Read compression granted by NvSciBufnumGpus=bufattrs[2].len/sizeof(NvSciBufAttrValGpuCompression);NvSciBufAttrValGpuCompression[]compVal=(NvSciBufAttrValGpuCompression*)bufattrs[2].value;NvSciBufCompressionTyperet_compVal;for(inti=0;i<numGpus;i++){if(memcmp(gpuid[0].bytes,compVal[i].gpuId.bytes,sizeof(CUuuid))==0){ret_compVal=compVal[i].compressionType);}}/*************** NvSciBuf Registration With CUDA **************/// Fill up CUDA_EXTERNAL_MEMORY_HANDLE_DESCcudaExternalMemoryHandleDescmemHandleDesc;memset(&memHandleDesc,0,sizeof(memHandleDesc));memHandleDesc.type=cudaExternalMemoryHandleTypeNvSciBuf;memHandleDesc.handle.nvSciBufObject=bufferObjRaw;// Set the NvSciBuf object with required access permissions in this stepmemHandleDesc.handle.nvSciBufObject=bufferObjRo;memHandleDesc.size=ret_size;cudaImportExternalMemory(&extMemBuffer,&memHandleDesc);returnextMemBuffer;}
void*mapBufferOntoExternalMemory(cudaExternalMemory_textMem,unsignedlonglongoffset,unsignedlonglongsize){void*ptr=NULL;cudaExternalMemoryBufferDescdesc={};memset(&desc,0,sizeof(desc));desc.offset=offset;desc.size=size;cudaExternalMemoryGetMappedBuffer(&ptr,extMem,&desc);// Note: 'ptr' must eventually be freed using cudaFree()returnptr;}
4.21.2.3.3. 将多级渐远纹理数组映射到导入的内存对象
可以将 CUDA 多级渐远纹理数组映射到导入的内存对象,如下所示。可以根据分配的NvSciBufObj的属性填写偏移量、维度和格式。所有映射的多级渐远纹理数组都必须使用cudaFreeMipmappedArray()释放。以下代码示例展示了在将多级渐远纹理数组映射到导入的内存对象时,如何将 NvSciBuf 属性转换为相应的 CUDA 参数。
注意
mip 级别数必须为 1。
cudaMipmappedArray_tmapMipmappedArrayOntoExternalMemory(cudaExternalMemory_textMem,unsignedlonglongoffset,cudaChannelFormatDesc*formatDesc,cudaExtent*extent,unsignedintflags,unsignedintnumLevels){cudaMipmappedArray_tmipmap=NULL;cudaExternalMemoryMipmappedArrayDescdesc={};memset(&desc,0,sizeof(desc));desc.offset=offset;desc.formatDesc=*formatDesc;desc.extent=*extent;desc.flags=flags;desc.numLevels=numLevels;// Note: 'mipmap' must eventually be freed using cudaFreeMipmappedArray()cudaExternalMemoryGetMappedMipmappedArray(&mipmap,extMem,&desc);returnmipmap;}
4.21.2.3.4. 导入同步对象
可以使用cudaDeviceGetNvSciSyncAttributes()生成与给定 CUDA 设备兼容的 NvSciSync 属性。返回的属性列表可用于创建一个保证与给定 CUDA 设备兼容的NvSciSyncObj。
cudaExternalSemaphore_timportNvSciSyncObject(void*nvSciSyncObj){cudaExternalSemaphore_textSem=NULL;cudaExternalSemaphoreHandleDescdesc={};memset(&desc,0,sizeof(desc));desc.type=cudaExternalSemaphoreHandleTypeNvSciSync;desc.handle.nvSciSyncObj=nvSciSyncObj;cudaImportExternalSemaphore(&extSem,&desc);// Deleting/Freeing the nvSciSyncObj beyond this point will lead to undefined behavior in CUDAreturnextSem;}
为便于获取 CUDA 驱动程序 API 入口点,CUDA Toolkit 提供了对头文件的访问,这些头文件包含所有 CUDA 驱动程序 API 的函数指针定义。这些头文件随 CUDA Toolkit 一同安装,位于工具包的include/目录中。下表汇总了包含各个 CUDA API 头文件对应的typedefs的头文件。
CUDA 驱动程序符号采用基于版本的命名方案,除第一个版本外,其名称中都带有_v*扩展。当某个特定 CUDA 驱动程序 API 的签名或语义发生变化时,我们会递增相应驱动程序符号的版本号。以cuMemAlloc驱动程序 API 为例,第一个驱动程序符号名称为cuMemAlloc,下一个符号名称为cuMemAlloc_v2。在 CUDA 2.0(2000)中引入的第一个版本的类型定义是PFN_cuMemAlloc_v2000。在 CUDA 3.2(3020)中引入的下一个版本的类型定义是PFN_cuMemAlloc_v3020。
从上述代码片段中的typedefs可以看出,版本后缀_v10000和_v10010表明上述 API 分别是在 CUDA 10.0 和 CUDA 10.1 中引入的。
#include<cudaTypedefs.h>// Declare the entry points for cuStreamBeginCapturePFN_cuStreamBeginCapture_v10000pfn_cuStreamBeginCapture_v1;PFN_cuStreamBeginCapture_v10010pfn_cuStreamBeginCapture_v2;// Get the function pointer to the cuStreamBeginCapture driver symbolcuGetProcAddress("cuStreamBeginCapture",&pfn_cuStreamBeginCapture_v1,10000,CU_GET_PROC_ADDRESS_DEFAULT,&driverStatus);// Get the function pointer to the cuStreamBeginCapture_v2 driver symbolcuGetProcAddress("cuStreamBeginCapture",&pfn_cuStreamBeginCapture_v2,10010,CU_GET_PROC_ADDRESS_DEFAULT,&driverStatus);
参照上述代码片段,要获取驱动程序 APIcuStreamBeginCapture的_v1版本的地址,CUDA 版本参数应恰好为 10.0(10000)。同样,要获取该 API 的_v2版本的地址,CUDA 版本应为 10.1(10010)。指定较高的 CUDA 版本来获取驱动程序 API 的某个特定版本,可能并不总是具有可移植性。例如,在此处使用 11030 仍会返回_v2符号,但如果假设的_v3版本在 CUDA 11.3 中发布,那么当与 CUDA 11.3 驱动程序配合使用时,cuGetProcAddressAPI 就会开始转而返回较新的_v3符号。由于_v2和_v3符号的 ABI 和函数签名可能不同,使用为_v2符号设计的_v10010类型定义来调用_v3函数,会表现出未定义行为。
注意,使用无效的 CUDA 版本请求驱动程序 API 会返回错误CUDA_ERROR_NOT_FOUND。在上述代码示例中,传入小于 10000(CUDA 10.0)的版本将是无效的。
4.22.3.2. 使用运行时 API
运行时 APIcudaGetDriverEntryPointByVersion使用所提供的 CUDA 版本,以与cuGetProcAddress相同的方式获取所请求驱动程序符号的 ABI 兼容版本。在下面的代码片段中,所需的最低 CUDA 版本为 CUDA 11.2,因为cuMemAllocAsync是在该版本中引入的。
#include<cudaTypedefs.h>intcudaVersion;// Ensure a CUDA driver >= 11.2 is installed or we will get an error from cuGetProcAddressstatus=cuDriverGetVersion(&cudaVersion);if(cudaVersion>=11020){// Declare the entry pointPFN_cuMemAllocAsync_v11020pfn_cuMemAllocAsync;// Initialize the entry pointcudaGetDriverEntryPointByVersion("cuMemAllocAsync",&pfn_cuMemAllocAsync,11020,cudaEnableDefault,&driverStatus);// Call the entry pointif(driverStatus==cudaDriverEntryPointSuccess&&pfn_cuMemAllocAsync){pfn_cuMemAllocAsync(...);}}
4.22.3.3. 获取每线程默认流版本
某些 CUDA 驱动程序 API 可以配置为具有默认流或每线程默认流语义。具有每线程默认流语义的驱动程序 API,其名称以_ptsz或_ptds为后缀。例如,cuLaunchKernel有一个名为cuLaunchKernel_ptsz的每线程默认流变体。借助驱动程序入口点访问 API,用户可以请求驱动程序 APIcuLaunchKernel的每线程默认流版本,而不是默认流版本。将 CUDA 驱动程序 API 配置为具有默认流或每线程默认流语义会影响同步行为。有关更多详细信息,请参阅此处。
始终建议安装最新的 CUDA 工具包来访问新的 CUDA 驱动程序功能,但如果出于某种原因,用户不想更新或无法获取最新的工具包,则可以使用此 API,仅通过更新 CUDA 驱动程序来访问新的 CUDA 功能。为便于讨论,假设用户正在使用 CUDA 12.3,并且想使用 CUDA 12.5 驱动程序中提供的新驱动程序 APIcuFoo。下面的代码片段展示了这一用例:
intmain(){// Manually define the prototype as cudaTypedefs.h in CUDA 12.3 does not have the cuFoo typedeftypedefCUresult(CUDAAPI*PFN_cuFoo_v12050)(...);PFN_cuFoo_v12050pfn_cuFoo=NULL;CUdriverProcAddressQueryResultdriverStatus;intcudaVersion;// Ensure a CUDA driver >= 12.5 is installed or we will get an error from cuGetProcAddressCUresultstatus=cuDriverGetVersion(&cudaVersion);if(cudaVersion>=12050){// Get the address for cuFoo API using cuGetProcAddress. Specify CUDA version as// 12050 since cuFoo was introduced thenCUresultstatus=cuGetProcAddress("cuFoo",&pfn_cuFoo,12050,CU_GET_PROC_ADDRESS_DEFAULT,&driverStatus);if(status==CUDA_SUCCESS&&pfn_cuFoo){pfn_cuFoo(...);}else{printf("Cannot retrieve the address to cuFoo - driverStatus = %d\n",driverStatus);assert(0);}}// rest of code here}
在下一个示例中,我们将讨论如何获取在 CUDA Toolkit 的某个次版本中发布的 API 新版本。注意,在 cuda.h 头文件中,将cuDeviceGetUuid提升到 _v2 的版本宏,直到跨入新的主版本时才会更新。因此,以下示例展示了在 11.4 及后续版本期间如何获取 _v2 版本。
#include<cudaTypedefs.h>CUuuiduuid;CUdevicedev;CUresultstatus;intcudaVersion;CUdriverProcAddressQueryResultdriverStatus;status=cuDeviceGet(&dev,0);// Get device 0// handle status// Ensure a CUDA driver >= 11.4 is installed or we will get an error from cuGetProcAddressstatus=cuDriverGetVersion(&cudaVersion);if(cudaVersion>=11040){PFN_cuDeviceGetUuid_v11040pfn_cuDeviceGetUuid;status=cuGetProcAddress("cuDeviceGetUuid",&pfn_cuDeviceGetUuid,11040,CU_GET_PROC_ADDRESS_DEFAULT,&driverStatus);if(CUDA_SUCCESS==status&&pfn_cuDeviceGetUuid){pfn_cuDeviceGetUuid(&uuid,dev);}}
4.22.4. cuGetProcAddress 使用准则
以下是使用cuGetProcAddress时应牢记的准则。
将传递给cuGetProcAddress的 CUDA 版本编码为与类型定义版本一致的值(不要使用CUDA_VERSION之类的编译时常量,也不要使用cuDriverGetVersion返回的版本之类的动态版本)
// cuDeviceGetExecAffinitySupport was introduced in release CUDA 11.4#include<cuda.h>CUdriverProcAddressQueryResultdriverStatus;cudaVersion=...;status=cuGetProcAddress("cuDeviceGetExecAffinitySupport",&pfn,cudaVersion,0,&driverStatus);if(CUDA_SUCCESS==status){if(CU_GET_PROC_ADDRESS_VERSION_NOT_SUFFICIENT==driverStatus){printf("We can use the new feature when you upgrade cudaVersion to 11.4, but CUDA driver is good to go!\n");// Indicating cudaVersion was < 11.4 but run against a CUDA driver >= 11.4}elseif(CU_GET_PROC_ADDRESS_SYMBOL_NOT_FOUND==driverStatus){printf("Please update both CUDA driver and cudaVersion to at least 11.4 to use the new feature!\n");// Indicating driver is < 11.4 since string not found, doesn't matter what cudaVersion was}elseif(CU_GET_PROC_ADDRESS_SUCCESS==driverStatus&&pfn){printf("You're using cudaVersion and CUDA driver >= 11.4, using new feature!\n");pfn();}}
第一种情况的返回代码为CU_GET_PROC_ADDRESS_VERSION_NOT_SUFFICIENT,表示在 CUDA 驱动程序中搜索时找到了symbol,但它是在所提供的cudaVersion之后才添加的。在此示例中,将cudaVersion指定为 11030 或更小的任意值,并使用版本大于或等于 CUDA 11.4 的 CUDA 驱动程序运行时,就会得到CU_GET_PROC_ADDRESS_VERSION_NOT_SUFFICIENT这一结果。这是因为cuDeviceGetExecAffinitySupport是在 CUDA 11.4 (11040) 中添加的。
第二种情况的返回代码为CU_GET_PROC_ADDRESS_SYMBOL_NOT_FOUND,表示在 CUDA 驱动程序中搜索时未找到symbol。这可能有几种原因,例如,驱动程序较旧而不支持该 CUDA 函数,或者只是存在拼写错误。在后一种情况下,与上一个示例类似,如果用户将symbol设为 CUDeviceGetExecAffinitySupport,请注意字符串开头的大写 CU,那么cuGetProcAddress将无法找到该 API,因为字符串不匹配。前一种情况的一个例子可能是,用户针对支持新 API 的 CUDA 驱动程序开发应用程序,却将应用程序部署到较旧的 CUDA 驱动程序上。以上一个示例为例,如果开发者针对 CUDA 11.4 或更高版本进行开发,但部署时使用的是 CUDA 11.3 驱动程序,那么在开发过程中,cuGetProcAddress可能曾经成功,但在部署使用 CUDA 11.3 驱动程序运行的应用程序时,该调用将不再有效,并会在driverStatus中返回CU_GET_PROC_ADDRESS_SYMBOL_NOT_FOUND。
表 33展示了张量核心加速所支持的输入数据类型。在 CUDA 编译工具链中,可以通过内联 PTX 使用张量核心功能集。强烈建议应用程序通过 CUDA-X 库(例如 cuDNN、cuBLAS 和 cuFFT)或通过CUTLASS来使用此功能集,后者是一组 CUDA C++ 模板抽象和 Python 领域特定语言(DSL),旨在实现 CUDA 内各个层级的高性能矩阵-矩阵乘法(GEMM)及相关计算。
表 33 各计算能力的张量核心加速所支持的输入数据类型
计算能力
张量核心输入数据类型
FP64
TF32
BF16
FP16
FP8
FP6
FP4
INT8
INT4
7.5
是
是
是
8.0
是
是
是
是
是
是
8.6
是
是
是
是
是
8.7
是
是
是
是
是
8.9
是
是
是
是
是
是
9.0
是
是
是
是
是
是
10.0
是
是
是
是
是
是
是
是
10.3
是
是
是
是
是
是
是
10.7
是
是
是
是
是
是
是
11.0
是
是
是
是
是
是
是
12.x
是
是
是
是
是
是
是
5.2. CUDA 环境变量
以下一节列出了 CUDA 环境变量。与多进程服务(MPS)相关的环境变量记录在GPU 部署和管理指南中。
cudaGetDeviceCount()API 返回的设备数量仅包括可见设备,因此,使用整数设备标识符的 CUDA API 仅支持 [0, 可见设备数量 - 1] 范围内的序号。GPU 设备的枚举顺序决定了序号值。例如,在CUDA_VISIBLE_DEVICES=2,1的情况下,调用cudaSetDevice(0)会将设备 2 设置为当前设备,因为它最先被枚举到,并被分配了序号 0。此后调用cudaGetDevice(&device_ordinal)也会将device_ordinal设置为 0,对应于设备 2。
示例:
nvidia-smi-L# Get list of GPU UUIDsCUDA_VISIBLE_DEVICES=0,1
CUDA_VISIBLE_DEVICES=GPU-8932f937-d72c-4106-c12f-20bd9faed9f6
CUDA_VISIBLE_DEVICES=MIG-GPU-8932f937-d72c-4106-c12f-20bd9faed9f6/1/2
5.2.1.2. CUDA_DEVICE_ORDER
该环境变量控制 CUDA 枚举可用设备的顺序。
可选值:
FASTEST_FIRST:使用简单的启发式方法,按从最快到最慢的顺序枚举可用设备(默认)。
PCI_BUS_ID:按 PCI 总线 ID 的升序枚举可用设备。PCI 总线 ID 可通过nvidia-smi--query-gpu=name,pci.bus_id获取。
示例:
CUDA_DEVICE_ORDER=FASTEST_FIRST
CUDA_DEVICE_ORDER=PCI_BUS_ID
nvidia-smi--query-gpu=name,pci.bus_id# Get list of PCI bus IDs
1:这会强制驱动程序在初始化期间预加载NVVM和即时(JIT)编译所需的库。这会增加内存占用和 CUDA 驱动程序初始化所需的时间。要避免涉及多个线程的某些死锁情况,必须设置此环境变量。
0:默认行为。
示例:
CUDA_FORCE_PRELOAD_LIBRARIES=1
5.2.3. 执行
5.2.3.1. CUDA_LAUNCH_BLOCKING
该环境变量指定禁用还是启用异步核函数启动。
禁用异步执行会导致执行速度变慢,但有助于调试。它会强制 GPU 工作从 CPU 的角度来看同步运行。这样便可以在触发错误的具体 API 调用处观察到 CUDA API 错误,而不是在后续执行过程中才观察到。同步执行有助于调试。
可选值:
1:禁用异步执行。
0:异步执行(默认)。
示例:
CUDA_LAUNCH_BLOCKING=1
5.2.3.2. CUDA_DEVICE_MAX_CONNECTIONS
该环境变量控制并发计算引擎连接和复制引擎连接(工作队列)的数量,将两者均设置为指定值。如果独立的 GPU 任务,即从不同 CUDA 流中启动的核函数或复制操作,映射到同一个工作队列,就会产生虚假依赖关系,由于使用了相同的底层资源,这可能导致 GPU 工作串行化。为降低出现此类虚假依赖关系的概率,建议通过此环境变量控制的工作队列数量大于或等于每个上下文中的活动 CUDA 流数量。
在 Linux 主机上,将此环境变量设置为 1 会阻止提升设备性能状态,而是可以基于各种启发式方法隐式选择 pstate。此选项有可能用于降低功耗,但由于动态选择性能状态,在某些场景中可能会导致更高的延迟。
示例:
CUDA_DISABLE_PERF_BOOST=1# perf boost disabled, Linux only.CUDA_DISABLE_PERF_BOOST=0# default behavior
5.2.3.9. CUDA_PREFER_SPINLOCKS_ON_HOST
此环境变量向 CUDA 驱动程序和运行时提供提示,使其在某些内部主机端同步路径中优先采用基于自旋的加锁模式。在此模式下,内部锁可能会主动轮询以检查是否可用,而不是阻塞并让出 CPU。这可以通过避免内核态切换和唤醒开销,降低短时间持有的锁的同步延迟,从而改善低到中等争用情况下的快速路径性能(例如,多个主机线程争用同一个 CUDA 对象或执行上下文时)。基于自旋的加锁不提供调度器辅助的公平性或优先级继承。在主机线程被抢占、超额订阅或混合工作负载的情况下,启用基于自旋的加锁可能会增加优先级反转、饥饿或系统响应性下降的风险。
该环境变量指定一个位置,对于返回错误的受支持 CUDA API 调用,会在错误发生时将描述性错误日志消息打印到该位置。
例如,如果尝试使用无效的网格配置(如kernel<<<1,dim3(1,1,128)>>>(...))启动核函数,该核函数将无法启动,且cudaGetLastError()将返回通用的invalidconfigurationargument错误。 如果设置了CUDA_LOG_FILE环境变量,用户就可以在日志中看到以下描述性错误消息:[CUDA][E]BlockDimensions(1,1,128)includeoneormorevaluesthatexceedthedevicelimitof(1024,1024,64),并轻松确定所指定的线程块 z 维度无效。有关更多详细信息,请参阅错误日志管理。
给定 CUDA 线程通过malloc()、cuda::std::malloc()、cuda::std::calloc()、__nv_aligned_device_malloc()或cuda::std::aligned_alloc()分配的内存,在 CUDA 上下文的整个生存期内都会保持已分配状态,或者直到通过调用free()或cuda::std::free()显式释放为止。其他 CUDA 线程可以使用这些内存,包括后续核函数启动中的线程。任何 CUDA 线程都可以释放另一个线程分配的内存;但是,应注意确保同一个指针不会被释放多次。
堆的实际内存分配发生在模块加载到上下文中时,加载既可以通过 CUDA 驱动程序 API 显式进行(参见模块),也可以通过 CUDA 运行时 API 隐式进行。如果内存分配失败,模块加载会产生CUDA_ERROR_SHARED_OBJECT_INIT_FAILED错误。
模块加载后,堆大小便无法更改,而且它不会根据需要动态调整大小。
为设备堆保留的内存,是在通过cudaMalloc()等主机端 CUDA API 调用分配的内存之外额外保留的。
与主机内存 API 的互操作性
通过设备端函数malloc()、cuda::std::malloc()、cuda::std::calloc()、__nv_aligned_device_malloc()、cuda::std::aligned_alloc()或new关键字分配的内存,不能通过cudaMalloc、cudaMemcpy或cudaMemset等运行时或驱动程序 API 调用来使用或释放。同样,通过主机运行时 API 分配的内存,不能使用设备端函数free()、cuda::std::free()或delete关键字来释放。
按线程分配的示例:
#include<stdlib.h>#include<stdio.h>__global__voidsingle_thread_allocation_kernel(){size_tsize=123;char*ptr=(char*)malloc(size);memset(ptr,0,size);printf("Thread %d got pointer: %p\n",threadIdx.x,ptr);free(ptr);}intmain(){// Set a heap size of 128 megabytes.// Note that this must be done before any kernel is launched.cudaDeviceSetLimit(cudaLimitMallocHeapSize,128*1024*1024);single_thread_allocation_kernel<<<1,5>>>();cudaDeviceSynchronize();return0;}
#include<stdlib.h>__global__voidblock_level_allocation_kernel(){__shared__int*data;// The first thread in the block performs the allocation and shares the pointer// with all other threads through shared memory, so that access can be coalesced.if(threadIdx.x==0){size_tsize=blockDim.x*64;// 64 bytes per thread are allocated.data=(int*)malloc(size);}__syncthreads();// Check for failureif(data==nullptr)return;// Threads index into the memory, ensuring coalescencefor(inti=0;i<64;++i)data[i*blockDim.x+threadIdx.x]=threadIdx.x;// Ensure all threads complete before freeing__syncthreads();// Only one thread may free the memory!if(threadIdx.x==0)free(data);}intmain(){cudaDeviceSetLimit(cudaLimitMallocHeapSize,128*1024*1024);block_level_allocation_kernel<<<10,128>>>();cudaDeviceSynchronize();return0;}
#include<stdlib.h>#include<stdio.h>constintNUM_BLOCKS=20;__device__int*data_ptrs[NUM_BLOCKS];// Per-block pointer__global__voidallocate_memory_kernel(){// Only the first thread in the block performs the allocation// since we need only one allocation per block.if(threadIdx.x==0)data_ptrs[blockIdx.x]=(int*)malloc(blockDim.x*4);__syncthreads();// Check for failureif(data_ptrs[blockIdx.x]==nullptr)return;// Zero the data with all threads in paralleldata_ptrs[blockIdx.x][threadIdx.x]=0;}// Simple example: store the thread ID into each element__global__voiduse_memory_kernel(){int*ptr=data_ptrs[blockIdx.x];if(ptr!=nullptr)ptr[threadIdx.x]+=threadIdx.x;}// Print the content of the buffer before freeing it__global__voidfree_memory_kernel(){int*ptr=data_ptrs[blockIdx.x];if(ptr!=nullptr)printf("Block %d, Thread %d: final value = %d\n",blockIdx.x,threadIdx.x,ptr[threadIdx.x]);// Only free from one thread!if(threadIdx.x==0)free(ptr);}intmain(){cudaDeviceSetLimit(cudaLimitMallocHeapSize,128*1024*1024);// Allocate memoryallocate_memory_kernel<<<NUM_BLOCKS,10>>>();// Use memoryuse_memory_kernel<<<NUM_BLOCKS,10>>>();use_memory_kernel<<<NUM_BLOCKS,10>>>();use_memory_kernel<<<NUM_BLOCKS,10>>>();// Free memoryfree_memory_kernel<<<NUM_BLOCKS,10>>>();cudaDeviceSynchronize();return0;}
voidhost_function(){autolambda1=[]{};// NOT an extended lambda: no explicit execution space annotationsautolambda2=[]__device__{};// extended lambdaautolambda3=[]__host____device__{};// extended lambdaautolambda4=[]__host__{};// NOT an extended lambda}__host____device__voidhost_device_function(){autolambda1=[]{};// NOT an extended lambda: no explicit execution space annotationsautolambda2=[]__device__{};// extended lambdaautolambda3=[]__host____device__{};// extended lambdaautolambda4=[]__host__{};// NOT an extended lambda}__device__voiddevice_function(){// none of the lambdas within this function are extended lambdas,// because the enclosing function is not a __host__ or __host__ __device__ function.autolambda1=[]{};autolambda2=[]__device__{};autolambda3=[]__host____device__{};autolambda4=[]__host__{};}autoglobal_lambda=[]__host____device__{};// NOT an extended lambda because it is not defined// within a __host__ or __host__ __device__ function
autolambda0=[]__host____device__{};voidhost_function(){autolambda1=[]{};autolambda2=[]__device__{};autolambda3=[]__host____device__{};autolambda4=[]__device__()->double{return3.14;}autolambda5=[]__device__(intx)->decltype(&x){return0;}usinglambda0_t=decltype(lambda0);usinglambda1_t=decltype(lambda1);usinglambda2_t=decltype(lambda2);usinglambda3_t=decltype(lambda3);usinglambda4_t=decltype(lambda4);usinglambda5_t=decltype(lambda5);// 'lambda0' is not an extended lambda because it is defined outside function scopestatic_assert(!__nv_is_extended_device_lambda_closure_type(lambda0_t));static_assert(!__nv_is_extended_device_lambda_with_preserved_return_type(lambda0_t));static_assert(!__nv_is_extended_host_device_lambda_closure_type(lambda0_t));// 'lambda1' is not an extended lambda because it has no execution space annotationsstatic_assert(!__nv_is_extended_device_lambda_closure_type(lambda1_t));static_assert(!__nv_is_extended_device_lambda_with_preserved_return_type(lambda1_t));static_assert(!__nv_is_extended_host_device_lambda_closure_type(lambda1_t));// 'lambda2' is an extended device-only lambdastatic_assert(__nv_is_extended_device_lambda_closure_type(lambda2_t));static_assert(!__nv_is_extended_device_lambda_with_preserved_return_type(lambda2_t));static_assert(!__nv_is_extended_host_device_lambda_closure_type(lambda2_t));// 'lambda3' is an extended host-device lambdastatic_assert(!__nv_is_extended_device_lambda_closure_type(lambda3_t));static_assert(!__nv_is_extended_device_lambda_with_preserved_return_type(lambda3_t));static_assert(__nv_is_extended_host_device_lambda_closure_type(lambda3_t));// 'lambda4' is an extended device-only lambda with preserved return typestatic_assert(__nv_is_extended_device_lambda_closure_type(lambda4_t));static_assert(__nv_is_extended_device_lambda_with_preserved_return_type(lambda4_t));static_assert(!__nv_is_extended_host_device_lambda_closure_type(lambda4_t));// 'lambda5' is not an extended device-only lambda with preserved return type// because it references the operator()'s parameter types in the trailing return type.static_assert(__nv_is_extended_device_lambda_closure_type(lambda5_t));static_assert(!__nv_is_extended_device_lambda_with_preserved_return_type(lambda5_t));static_assert(!__nv_is_extended_host_device_lambda_closure_type(lambda5_t));}
voidhost_function(){autolambda1=[]__device__{};// enclosing function for lambda1 is "host_function()"autolambda2=[]{autolambda3=[]{autolambda4=[]__host____device__{};// enclosing function for lambda4 is "host_function"};};}autoglobal_lambda=[]{autolambda5=[]__host____device__{};// enclosing function for lambda5 does not exist};
扩展 lambda 的限制
扩展 lambda 不能定义在另一个扩展 lambda 表达式内部。示例:
voidhost_function(){autolambda1=[]__host____device__{// ERROR, extended lambda defined within another extended lambdaautolambda2=[]__host____device__{};};}
扩展 lambda 不能定义在泛型 lambda 表达式内部。示例:
voidhost_function(){autolambda1=[](auto){// ERROR, extended lambda defined within a generic lambdaautolambda2=[]__host____device__{};};}
voidhost_function(){autolambda1=[]__device__{return0;};// OK{autolambda2=[]__device__{return0;};// OKautolambda3=[]__device____host__{return0;};// OK}}structMyStruct1{MyStruct1(){autolambda4=[]__device__{return0;};// ERROR, address of the enclosing function is not accessible}};classMyStruct2{voidfoo(){autotemp1=[]__device__{return10;};// ERROR, enclosing function has private access in parent class}structMyStruct3{voidfoo(){autotemp1=[]__device__{return10;};// ERROR, enclosing class MyStruct3 has private access in its parent class}};};
template<typenameT>structA{usingBar=void;voidtest();};template<>structA<void>{};template<typenameBar>voidA<Bar>::test(){// In code sent to host compiler, nvcc will inject an address expression here, of the form:// (void (A< Bar> ::*)(void))(&A::test))// However, the class typedef 'Bar' (to void) shadows the template argument 'Bar',// causing the address expression in A<int>::test to actually refer to:// (void (A< void> ::*)(void))(&A::test))// which doesn't take the address of the enclosing routine 'A<int>::test' correctly.autolambda1=[]__host____device__{return4;};}intmain(){A<int>var;var.test();}
扩展 lambda 不能定义在函数的局部类中。示例:
voidhost_function(){structMyStruct{voidbar(){// ERROR, bar() is member of a class that is local to a functionautolambda2=[]__host____device__{return0;};}};}
扩展 lambda 的外围函数不能具有推导出的返回类型。示例:
autohost_function(){// ERROR, the return type of host_function() is deducedautolambda3=[]__host____device__{return0;};}
voidhost_function(){// ERROR, __host__ __device__ extended lambdas cannot be a generic lambdaautolambda1=[]__host____device__(autoi){returni;};// ERROR, a host-device extended lambda cannot be a generic lambdaautolambda2=[]__host____device__(auto...i){returnsizeof...(i);};}
template<template<typename...>classT,typename...P1,typename...P2>voidbar1(constT<P1...>,constT<P2...>){// ERROR, enclosing function has multiple parameter packsautolambda=[]__device__{return10;};}template<template<typename...>classT,typename...P1,typenameT2>voidbar2(constT<P1...>,T2){// ERROR, for enclosing function, the parameter pack is not last in the template parameter listautolambda=[]__device__{return10;};}template<typenameT,T>voidbar3(){// ERROR, for enclosing function, the second template parameter is not namedautolambda=[]__device__{return10;};}
示例 2:
template<typenameT>voidbar4(){autolambda1=[]__device__{return10;};}classMyStruct{structMyNestedStruct{};friendintmain();};intmain(){structMyLocalStruct{};// ERROR, enclosing function for device lambda in bar4() is instantiated with a type local to mainbar4<MyLocalStruct>();// ERROR, enclosing function for device lambda in bar4 is instantiated with a type// that is a private member of a classbar4<MyStruct::MyNestedStruct>();}
使用 Microsoft Visual Studio 主机编译器时,外围函数必须具有外部链接。存在此限制是因为主机编译器不支持将非外部链接函数的地址用作模板实参。CUDA 编译器的转换需要这些地址才能支持扩展 lambda。
使用 Microsoft Visual Studio 主机编译器时,不得在ifconstexpr块的主体内定义扩展 lambda。
voidhost_function(){// CORRECT, an init-capture is allowed for an extended device-only lambdaautolambda1=[x=1]__device__(){returnx;};// ERROR, an init-capture is not allowed for an extended host-device lambdaautolambda2=[x=1]__host____device__(){returnx;};inta=1;// ERROR, an extended __device__ lambda cannot capture variables by referenceautolambda3=[&a]__device__(){returna;};// ERROR, by-reference capture is not allowed for an extended device-only lambdaautolambda4=[&x=a]__device__(){returnx;};structMyStruct{};MyStructs1;// ERROR, a type local to a function cannot be used in the type of a captured variableautolambda6=[s1]__device__(){};// ERROR, an init-capture cannot be of type std::initializer_listautolambda7=[x={11}]__device__(){};std::initializer_list<int>b={11,22,33};// ERROR, an init-capture cannot be of type std::initializer_listautolambda8=[x=b]__device__(){};intvar=4;autolambda9=[=]__device__{intresult=0;ifconstexpr(false){//ERROR, An extended device-only lambda cannot first-capture 'var' in if-constexpr contextresult+=var;}returnresult;};autolambda10=[var]__device__{intresult=0;ifconstexpr(false){// CORRECT, 'var' already listed in explicit capture list for the extended lambdaresult+=var;}returnresult;};autolambda11=[=]__device__{intresult=var;ifconstexpr(false){// CORRECT, 'var' already implicit captured outside the 'if-constexpr' blockresult+=var;}returnresult;};}
template<typenameT>__global__voidkernel(Tin){in();}__host____device__voidhost_device_function(){// ERROR, the number and relative declaration order of// extended lambdas depend on __CUDA_ARCH__#if defined(__CUDA_ARCH__)autolambda1=[]__device__{return0;};autolambda2=[]__host____device__{return10;};#endifautolambda3=[]__device__{return4;};kernel<<<1,1>>>(lambda3);}
#include<cuda/std/type_traits>constchar&getRef(constchar*p){return*p;}voidfoo(){autolambda1=[]__device__{return"10";};// ERROR, attempt to extract the return type of a device lambda in host codecuda::std::result_of<decltype(lambda1)()>::typexx1="abc";autolambda2=[]__host____device__{return"10";};// CORRECT, lambda2 represents a host-device extended lambdacuda::std::result_of<decltype(lambda2)()>::typexx2="abc";autolambda3=[]__device__()->constchar*{return"10";};// CORRECT, lambda3 represents a device extended lambda with preserved return typecuda::std::result_of<decltype(lambda3)()>::typexx2="abc";static_assert(cuda::std::is_same_v<cuda::std::result_of<decltype(lambda3)()>::type,constchar*>);autolambda4=[]__device__(charx)->decltype(getRef(&x)){return0;};// lambda4's return type is not preserved because it references the operator()'s// parameter types in the trailing return type.static_assert(!__nv_is_extended_device_lambda_with_preserved_return_type(decltype(lambda4)));}
__device__intresult;template<typenameT>__global__voidkernel(Tin){result=in();}voidfoo(void){intx1=1;// ERROR, "x1" is only captured when __CUDA_ARCH__ is defined.autolambda1=[=]__host____device__{#ifdef __CUDA_ARCH__returnx1+1;#elsereturn10;#endif};kernel<<<1,1>>>(lambda1);}
template<typenameT>__global__voidkernel(Tin){int(*fp)(double)=in;fp(0);// CORRECT, conversion in device code is supportedautolambda1=[](double){return1;};}voidfoo(){autolambda_device=[]__device__(double){return1;};autolambda_host_device=[]__host____device__(double){return1;};kernel<<<1,1>>>(lambda_device);kernel<<<1,1>>>(lambda_host_device);// CORRECT, conversion for a __host__ __device__ lambda is supported in host codeint(*fp1)(double)=lambda_host_device;// ERROR, conversion for a device lambda is not supported in host codeint(*fp2)(double)=lambda_device;}
如前所述,在发送给主机编译器的代码中,CUDA 编译器会将仅设备扩展 lambda 表达式或主机-设备扩展 lambda 表达式替换为占位类型实例。此占位类型可能定义 C++ 特殊成员函数,例如构造函数和析构函数。因此,对于扩展 lambda 的闭包类型,某些标准 C++ 类型特征在 CUDA 前端编译器中可能产生与主机编译器中不同的结果。受影响的类型特征如下::std::is_trivially_copyable、std::is_trivially_constructible、std::is_trivially_copy_constructible、std::is_trivially_move_constructible、std::is_trivially_destructible。必须注意确保在实例化__global__、__device__、__constant__或__managed__函数模板或变量模板时不使用这些特征的结果。示例:
#include<cstdio>#include<type_traits>template<boolb>void__global__kernel(){printf("hi");}template<typenameT>voidkernel_launch(){// ERROR, this kernel launch may fail, because CUDA frontend compiler and host compiler// may disagree on the result of std::is_trivially_copyable_v trait on the// closure type of the extended lambdakernel<std::is_trivially_copyable_v<T>><<<1,1>>>();cudaDeviceSynchronize();}intmain(){intx=0;autolambda1=[=]__host____device__(){returnx;};kernel_launch<decltype(lambda1)>();}
CUDA 编译器会针对1-12中所述的部分情况生成编译器诊断信息;对于情况13-17,不会生成诊断信息,但主机编译器可能无法编译所生成的代码。
#include<cstdio>template<typenameT>__global__voidfoo(Tin){printf("value = %d\n",in());}structMyStruct{intvar;__host____device__MyStruct():var(10){};voidrun(){autolambda1=[=]__device__{// reference to "var" causes the 'this' pointer (MyStruct*) to be captured by valuereturnvar+1;};// Kernel launch fails at run time because 'this->var' is not accessible from the GPUfoo<<<1,1>>>(lambda1);cudaDeviceSynchronize();}};intmain(){MyStructs1;s1.run();}
#include<cstdio>template<typenameT>__global__voidfoo(Tin){printf("\n value = %d",in());}structMyStruct{intvar;__host____device__MyStruct():var(10){};voidrun(){// note the "*this" capture specificationautolambda1=[=,*this]__device__{// reference to "var" causes the object denoted by '*this' to be captured by// value, and the GPU code will access 'copy_of_star_this->var'returnvar+1;};// Kernel launch succeedsfoo<<<1,1>>>(lambda1);cudaDeviceSynchronize();}};intmain(){MyStructs1;s1.run();}
structMyStruct{intvar;__host____device__MyStruct():var(10){};voidhost_function(){// CORRECT, use in an extended device-only lambdaautolambda1=[=,*this]__device__{returnvar;};// Use in an extended host-device lambda// Error if *this capture not enabled by language dialectautolambda2=[=,*this]__host____device__{returnvar;};// Use in an non-annotated lambda in host function// Error if *this capture not enabled by language dialectautolambda3=[=,*this]{returnvar;};}__device__voiddevice_function(){// CORRECT, use in a lambda defined in a device-only functionautolambda1=[=,*this]__device__{returnvar;};// CORRECT, use in a lambda defined in a device-only functionautolambda2=[=,*this]__host____device__{returnvar;};// CORRECT, use in a lambda defined in a device-only functionautolambda3=[=,*this]{returnvar;};}__host____device__voidhost_device_function(){// CORRECT, use in an extended device-only lambdaautolambda1=[=,*this]__device__{returnvar;};// Use in an extended host-device lambda// Error if *this capture not enabled by language dialectautolambda2=[=,*this]__host____device__{returnvar;};// Use in an unannotated lambda in a host-device function// Error if *this capture not enabled by language dialectautolambda3=[=,*this]{returnvar;};}};
namespaceN1{structMyStruct{};template<typenameT>voidmy_function(T);};// namespace N1namespaceN2{template<typenameT>intmy_function(T);template<typenameT>voidrun(Tin){my_function(in);}}// namespace N2voidbar(N1::MyStructin){// For extended device-only lambda, the code sent to the host compiler is replaced with// the placeholder type instantiation expression// ' __nv_dl_wrapper_t< __nv_dl_tag<void (*)(N1::MyStruct in),(&bar),1> > { }'//// As a result, the namespace 'N1' participates in ADL lookup of the// call to "my_function()" in the body of N2::run, causing ambiguity.autolambda1=[=]__device__{};N2::run(lambda1);}
#include<nvfunctional>__device__intdevice_function(){return1;}__host__inthost_function(){return3;}autolambda_host=[]{return0;};__global__voidk(){nvstd::function<int()>fn1=host_function;// ERROR, initialized with address of __host__ functionnvstd::function<int()>fn2=lambda_host;// ERROR, initialized with address of functor with// __host__ operator() function}__global__voidkernel(nvstd::function<int()>f1){}voidfoo(void){autolambda_device=[=]__device__{return1;};nvstd::function<int()>fn1=device_function;// ERROR, initialized with address of __device__ functionnvstd::function<int()>fn2=lambda_device;// ERROR, initialized with address of functor with// __device__ operator() functionkernel<<<1,1>>>(fn2);// ERROR, passing nvstd::function from host to device}
nvstd::function在nvfunctional头文件中的定义如下:
namespacenvstd{template<typenameRetType,typename...ArgTypes>classfunction<RetType(ArgTypes...)>{public:// constructors__device____host__function()noexcept;__device____host__function(nullptr_t)noexcept;__device____host__function(constfunction&);__device____host__function(function&&);template<typenameF>__device____host__function(F);// destructor__device____host__~function();// assignment operators__device____host__function&operator=(constfunction&);__device____host__function&operator=(function&&);__device____host__function&operator=(nullptr_t);template<typenameF>__device____host__function&operator=(F&&);// swap__device____host__voidswap(function&)noexcept;// function capacity__device____host__explicitoperatorbool()constnoexcept;// function invocation__device__RetTypeoperator()(ArgTypes...)const;};// null pointer comparisonstemplate<typenameR,typename...ArgTypes>__device____host__booloperator==(constfunction<R(ArgTypes...)>&,nullptr_t)noexcept;template<typenameR,typename...ArgTypes>__device____host__booloperator==(nullptr_t,constfunction<R(ArgTypes...)>&)noexcept;template<typenameR,typename...ArgTypes>__device____host__booloperator!=(constfunction<R(ArgTypes...)>&,nullptr_t)noexcept;template<typenameR,typename...ArgTypes>__device____host__booloperator!=(nullptr_t,constfunction<R(ArgTypes...)>&)noexcept;// specialized algorithmstemplate<typenameR,typename...ArgTypes>__device____host__voidswap(function<R(ArgTypes...)>&,function<R(ArgTypes...)>&);}// namespace nvstd
namespacecuda{// same for "nv" and "cooperative_groups" namespacesstructfoo;// ERROR, class declaration in the "cuda" namespacevoidbar();// ERROR, function declaration in the "cuda" namespacenamespaceutils{}// ERROR, namespace declaration in the "cuda" namespace}// namespace cuda
namespaceutils{namespacecuda{// CORRECT, namespace "cuda" may be used nested within a non-reserved namespacevoidbar();}// namespace cuda}// namespace utils// ERROR, Equivalent to adding symbols to namespace "cuda" at global scopeusingnamespaceutils;
__host__voidhost_function(){intx;// CORRECT, __host__ variable__device__inty;// ERROR, __device__ variable declaration within a host function__tile__intz;// ERROR, __tile__ variable declaration within a host function__shared__intw;// ERROR, __shared__ variable declaration within a host function__managed__inth;// ERROR, __managed__ variable declaration within a host function__constant__inti;// ERROR, __constant__ variable declaration within a host functionextern__device__intj;// CORRECT, extern __device__ variable}
原子内存操作提供线程间同步保证,并且性能优于volatile操作。不过,CUDA C++ 的volatile操作不提供任何线程间同步保证,因此不适合此用途。以下示例展示了如何使用原子操作在两个线程之间传递消息。
#include<cuda/atomic>__global__voidkernel(int*flag,int*data){cuda::atomic_ref<int,cuda::thread_scope_device>atomic_ref{*flag};if(threadIdx.x==0){// Consumer: blocks until flag is set by producer, then reads datawhile(atomic_ref.load(cuda::memory_order_acquire)==0);if(*data!=42)__trap();// Errors if wrong data read}elseif(threadIdx.x==1){// Producer: writes data then sets flag*data=42;atomic_ref.store(1,cuda::memory_order_release);}}
#include<cuda/atomic>__global__voidkernel(cuda::atomic<int,cuda::thread_scope_device>*flag,int*data){if(threadIdx.x==0){// Consumer: blocks until flag is set by producer, then reads datawhile(flag->load(cuda::memory_order_acquire)==0);if(*data!=42)__trap();// Errors if wrong data read}elseif(threadIdx.x==1){// Producer: writes data then sets flag*data=42;flag->store(1,cuda::memory_order_release);}}
__global__voidkernel(int*flag,int*data){if(threadIdx.x==0){// Consumer: blocks until flag is set by producer, then reads datawhile(atomicAdd(flag,0)==0);// Load with Relaxed Read-Modify-Write__threadfence();// SequentiallyConsistent fenceif(*data!=42)__trap();// Errors if wrong data read}elseif(threadIdx.x==1){// Producer: writes data then sets flag*data=42;__threadfence();// SequentiallyConsistent fenceatomicExch(flag,1);// Store with Relaxed Read-Modify-Write}}
__host____device__voidhost_device_function(){staticintv1;// CORRECT, implicit __device__ memory space specifier// static __device__ int v2; // ERROR, __device__-only variable inside a host-device function#ifdef __CUDA_ARCH__static__device__intv3;// CORRECT, declaration is only visible during device compilation#elsestaticintv4;// CORRECT, declaration is only visible during host compilation#endif}
#include<cassert>__host____device__inthost_device_function(){staticintv=0;v++;returnv;}__global__voidkernel(){intret=host_device_function();// v = 1assert(ret==4);// FAIL}intmain(){host_device_function();// v = 1host_device_function();// v = 2intret=host_device_function();// v = 3assert(ret==3);// OKkernel<<<1,1>>>();cudaDeviceSynchronize();}
//first.cu:structS;// forward declaration__device__voidfoo(S);// ERROR, type 'S' is an incomplete type__device__auto*ptr=foo;// ODR-use, address takenintmain(){}
//second.cu:structS{};// struct definition__device__voidfoo(S){}// function definition
# compilerinvocation
$ nvcc-std=c++14-rdc=truefirst.cusecond.cu-oprog
nvlink error : Prototype doesn't match for '_Z3foo1S' in '/tmp/tmpxft_00005c8c_00000000-18_second.o', first defined in '/tmp/tmpxft_00005c8c_00000000-18_second.o'nvlink fatal : merge_elf failed
从主机代码启动__global__函数时,各实参类型可以是非平凡可复制的,也可以是非平凡可析构的。不过,这些类型的处理并不遵循标准 C++ 模型,如下所述。用户代码必须确保此工作流程不会影响程序的正确性。此工作流程在两个方面偏离了标准 C++:
使用原始内存复制,而非调用复制构造函数
CUDA Runtime 通过复制原始内存内容将核函数实参传递给__global__函数,最终使用memcpy完成复制。如果某个实参是非平凡可复制的,并提供了用户定义的复制构造函数,则在从主机到设备的复制过程中,会跳过该构造函数调用的操作和副作用。
示例:
#include<cassert>structMyStruct{intvalue=1;int*ptr;MyStruct()=default;__host____device__MyStruct(constMyStruct&){ptr=&value;}};__global__voiddevice_function(MyStructmy_struct){// this assert fails because "my_struct" is obtained by copying// the raw memory content and the copy constructor is skipped.assert(my_struct.ptr==&my_struct.value);// FAIL}voidhost_function(MyStructmy_struct){assert(my_struct.ptr==&my_struct.value);// CORRECT}intmain(){MyStructmy_struct;host_function(my_struct);device_function<<<1,1>>>(my_struct);// copy constructor invoked in the host-side onlycudaDeviceSynchronize();}
#include<cassert>__managed__intvar=0;structMyStruct{__host____device__~MyStruct(){var=3;}};__global__voiddevice_function(MyStructmy_struct){assert(var==0);// FAIL, MyStruct::~MyStruct() sets the value to 3}intmain(){MyStructmy_struct;// GPU kernel execution is asynchronous with host execution.// As a result, MyStruct::~MyStruct() could be executed before// the kernel finishes executing.device_function<<<1,1>>>(my_struct);cudaDeviceSynchronize();}
structBase1{virtual__host____device__~Base1(){}};structDerived1:Base1{};// implicitly-declared virtual destructor// ~Derived1() has __host__ __device__ execution space specifiersstructBase2{virtual__device__~Base2()=default;};structDerived2:Base2{};// implicitly-declared virtual destructor// ~Derived2() has __device__ execution space specifiers
constexpr__device__intdevice_func(){return0;}constexpr__tile__inttile_func(){return0;}constexpr__device____host___inthost_device_func(){return0;}intmain(){constexprintx1=device_func();// UB: calling a __device__-only constexpr function from host codeconstexprintx2=tile_func();// UB: calling a __tile__-only constexpr function from host codeconstexprintx3=host_device_func();// OK}
constexpr__host__inthost_func(intx){returnx+1;};__global__voiddoit(){constexprintval=host_func(1);// OK: call is in a context that// requires constant evaluation.}__tile_global__voidtile_doit(){constexprintval=host_func(1);// OK: call is in a context that// requires constant evaluation.}constexpr__device__intdevice_func(intx){returnx+1;}constexpr__tile__inttile_func(intx){returnx+2;}intmain(){constexprintval=device_func(1)+tile_func(1);// OK: call is in a context that// requires constant evaluation.}
constexpr__host__inthost_func(intx){returnx+1;}__tile__intdoit(intin){in=host_func(in);// UB: call occurs outside of a context that requires// constant evaluation.constexprintother=host_func(10);// OK with -expt-relaxed-constexpr:// call is required to be evaluated at compile time}
// NOTE: "host_func" is emitted in generated device code because it is// called from device code in a non-constexpr contextconstexpr__host__inthost_func(intx){returnx+1;}__device__intdoit(intin){in=host_func(in);// OK, even though argument is not a constant expressionreturnin;}
inthost_var1,host_var2;constexpr__host__int*host_func(boolb){returnb?&host_var1:&host_var2;};__device__intdoit(boolflag){int*ptr;ptr=host_func(flag);// UB: host_func() attempts to refer to host variables 'host_var1' and 'host_var2'.// code will compile, but will NOT execute correctly.return*ptr;}
使用异常(throw/catch)和 RTTI(typeid,dynamic_cast)。示例:
structBase{};structDerived:publicBase{};// NOTE: "host_func" is emitted in generated device codeconstexprinthost_func(boolb,Base*ptr){if(b){return1;}elseif(typeid(ptr)==typeid(Derived)){// UB: use of typeid in code executing on the GPUreturn2;}else{throwint{4};// UB: use of throw in code executing on the GPU}}__device__voiddoit(boolflag){intval;Derivedd;val=host_func(flag,&d);//UB: host_func() attempts use typeid and throw(), which are not allowed in code that executes on the GPU}
__device__intdevice_var1,device_var2;constexpr__device__int*device_func(boolb){returnb?&device_var1:&device_var2;};__tile__inttile_var1,tile_var2;constexpr__tile__int*tile_func(boolb){returnb?&tile_var1:&tile_var2;};intdoit1(boolflag){int*ptr;ptr=device_func(flag);// UB: device_func() attempts to refer to device variables 'device_var1' and 'device_var2'// code will compile, but will NOT execute correctly.return*ptr;}intdoit2(boolflag){int*ptr;ptr=tile_func(flag);// UB: tile_func() attempts to refer to __tile__ variables 'tile_var1' and 'tile_var2'// code will compile, but will NOT execute correctly.return*ptr;}
警告
由于存在上述限制,且编译器不会对不正确的用法给出诊断信息,因此建议避免从设备代码调用标准 C++ 头文件std::中的函数。这类函数的实现因主机平台而异。相反,强烈建议调用 CUDA C++ 标准库libcu++中cuda::std::命名空间内的等效功能。
constexprintConstexprVar=4;// scalar typestructMyStruct{staticconstexprintConstexprVar=100;};constexprMyStructmy_struct=MyStruct{};// class typeconstexprintarray[]={1,2,3};__device__constexprintget_value(intidx){returnarray[idx];// CORRECT}__device__voidfoo(intidx){intv1=ConstexprVar;// CORRECTintv2=MyStruct::ConstexprVar;// CORRECT// const int &v3 = ConstexprVar1; // ERROR, reference to host constexpr variable// const int *v4 = &ConstexprVar1; // ERROR, address of host constexpr variableintv5=get_value(2);// CORRECT, 'get_value(2)' is a constant expression.// int v6 = get_value(idx); // ERROR, 'get_value(idx)' is not a constant expression// int v7 = array[2]; // ERROR, 'array' is not scalar type.MyStructv8=my_struct;// CORRECT}
template<typename...Pack>__global__voidkernel1();// CORRECT// template <typename... Pack, template T>// __global__ void kernel2(); // ERROR, parameter pack is not the last parametertemplate<typename...TArgs>structMyStruct{};// template <typename... Pack1, typename... Pack2>// __global__ void kernel3(MyStruct<Pack1...>, MyStruct<Pack2...>); // ERROR, more than one parameter pack
structMyStruct1{MyStruct1()=default;};voidhost_function(){MyStruct1my_struct;// __host__ __device__ constructor}__device__voiddevice_function(){MyStruct1my_struct;// __host__ __device__ constructor}structMyStruct2{__device__MyStruct2()=default;// WARNING: __device__ annotation is ignored};structMyStruct3{__host__MyStruct3();};MyStruct3::MyStruct3()=default;// out-of-line definition, not ignored__device__voiddevice_function2(){// MyStruct3 my_struct; // ERROR, __host__ constructor}structMyStruct4{// MyStruct4::~MyStruct4 has host execution space, not ignored because virtualvirtual__host__~MyStruct4()=default;};__device__voiddevice_function3(){MyStruct4my_struct4;// implicit destructor call for 'my_struct4':// ERROR: call from a __device__ function 'device_function3' to a// __host__ function 'MyStruct4::~MyStruct4'}
#include<initializer_list>__device__voidfoo(std::initializer_list<int>in){}__device__voidbar(){foo({4,5,6});// (a) initializer list containing only constant expressions.inti=4;foo({i,5,6});// (b) initializer list with at least one non-constant element.// This form may have better performance than (a).}
CUDA 前端编译器在调用主机编译器之前,会将函数声明更改为具有void返回类型。这可能会破坏主机代码中对__device__函数的推导返回类型的内省。因此,对于在设备函数体之外引用此类推导返回类型的情况,CUDA 编译器将发出编译时错误。
示例:
__device__autodevice_function(intx){// deduced return typereturnx;// decltype(auto) has the same behavior}__global__voidkernel(){intx=sizeof(device_function(2));// CORRECT, device code scope}// const int size = sizeof(device_function(2)); // ERROR, return type deduction on hostvoidhost_function(){// using T = decltype(device_function(2)); // ERROR, return type deduction on host}voidhost_fn1(){// ERROR, referenced outside device function bodiesint(*p1)(int)=fn1;structS_local_t{// ERROR, referenced outside device function bodiesdecltype(fn2(10))m1;S_local_t():m1(10){}};}// ERROR, referenced outside device function bodiestemplate<typenameT=decltype(fn2)>voidhost_fn2(){}template<typenameT>structMyStruct{};// ERROR, referenced outside device function bodiesstructS1_derived_t:MyStruct<decltype(fn1)>{};
5.3.12.2. 变量模板
使用 Microsoft 编译器时,__device__、__tile__或__constant__变量模板不能用const限定。
示例:
// ERROR on Windows (non-portable), const-qualifiedtemplate<typenameT>__device__constTvar=0;// CORRECT, ptr1 is not const-qualifiedtemplate<typenameT>__device__constT*ptr1=nullptr;// ERROR on Windows (non-portable), ptr2 is const-qualifiedtemplate<typenameT>__device__constT*constptr2=nullptr;
inline__device__intdevice_var1;// CORRECT, when compiled in Separate Compilation mode (-rdc=true or -dc)// ERROR, when compiled in Whole Program Compilation modestaticinline__device__intdevice_var2;// CORRECT, internal linkagenamespace{inline__device__intdevice_var3;// CORRECT, internal linkageinline__shared__intshared_var;// CORRECT, internal linkagestaticinline__device__intdevice_var4;// CORRECT, internal linkageinline__device__intdevice_var5;// CORRECT, internal linkage}// namespace
structS{intx,y;};// __device__ auto [a, b] = S{4, 5}; // ERROR
5.3.14. C++20 限制
5.3.14.1. 三路比较运算符
__device__和__global__函数支持三路比较运算符(<=>),但某些用法隐式依赖于由主机实现提供的 C++ 标准库功能。使用这些运算符可能需要指定标志--expt-relaxed-constexpr以消除警告,并且该功能要求主机实现满足设备代码的要求。
示例:
#include<compare> // std::strong_ordering implementationstructS{intx,y;autooperator<=>(constS&)const=default;// (a)__host____device__booloperator<=>(intrhs)const{returnfalse;}// (b)};__host____device__boolhost_device_function(Sa,Sb){if(a<=>1)// CORRECT, calls a user-defined host-device overload (b)returntrue;returna<b;// CORRECT, call to an implicitly-declared function (a)// Note: it requires a device-compatible std::strong_ordering// implementation provided in the header <compare>// and the flag --expt-relaxed-constexpr}
constevalinthost_consteval(){return10;}__device__constevalintdevice_consteval(){return10;}__device__intdevice_function(){returnhost_consteval();// CORRECT, even if called from device code}__host____device__inthost_device_function(){returndevice_function();// CORRECT, even if called from host-device code}
__device__floatdevice_var=4.0f;// Variable in device memory__constant__floatconstant_mem_var=4.0f;// Variable in constant memory// For readability, the following example focuses on a device variable.intmain(){float*device_ptr;cudaGetSymbolAddress((void**)&device_ptr,device_var);// Gets address of device_varsize_tsymbol_size;cudaGetSymbolSize(&symbol_size,device_var);// Retrieves the size of the symbol (4 bytes).floathost_var;cudaMemcpyFromSymbol(&host_var,device_var,sizeof(host_var));// Copies from device to host.host_var=3.0f;cudaMemcpyToSymbol(device_var,&host_var,sizeof(host_var));// Copies from host to device.}
extern__shared__chardynamic_smem_pointer[];// extern __shared__ char* dynamic_smem_pointer; alternative syntax__global__voidkernel(){// or a __device__ function__shared__intsmem_var1[4];// static sizeautosmem_var2=(int*)dynamic_smem_pointer;// dynamic size}intmain(){size_tshared_memory_size=16;kernel<<<1,1,shared_memory_size>>>();cudaDeviceSynchronize();}
#include<cassert>__device____managed__intglobal_var=10;// OKint*ptr=&global_var;// ERROR: use of a managed variable in static initializationstructMyStruct1{intfield;MyStruct1():field(global_var){};};structMyStruct2{~MyStruct2(){global_var=10;}};MyStruct1temp1;// ERROR: use of managed variable in dynamic initializationMyStruct2temp2;// ERROR: use of managed variable in the destructor of// object with static storage duration__device____managed__constintconst_var=10;// ERROR: const-qualified type__device____managed__int&reference=global_var;// ERROR: reference typetemplate<int*Addr>structMyStruct3{};MyStruct3<&global_var>temp;// ERROR: address of managed variable is not a constant expression__global__voidkernel(int*ptr){assert(ptr==&global_var);// OKglobal_var=20;// OK}intmain(){int*ptr=&global_var;// OKkernel<<<1,1>>>(ptr);cudaDeviceSynchronize();global_var++;// OKdecltype(global_var)var1;// ERROR: managed variable used as unparenthesized argument to decltypedecltype((global_var))var2;// OK}
5.4.1.2.3. __tile__变量
__tile__内存空间说明符类似于__device__。带有__tile__标记的变量分配在设备全局内存中,并可由 CUDA Runtime API 函数访问。与__device__变量不同,__tile__变量可以从分块代码中直接访问。
__device__intx_device=0;__tile__intx_tile=0;// ERROR: Variable cannot be both device and tile__device____tile__intx_device_tile=0;__global__voidsimt_function(int*in){x_device=1;// OK: __device__ variable accessed from SIMT codex_tile=1;// ERROR: __tile__ variable accessed from SIMT code*in=1;// OK: May point to any device global memory, including x_tile.}__tile_global__voidtile_function(int*in){x_device=1;// ERROR: __device__ variable accessed from tile codex_tile=1;// OK: __tile__ variable accessed from tile code*in=1;// OK: May point to any device global memory, including x_device.}intmain(){int*x_device_ptr;cudaGetSymbolAddress((void**)&x_device_ptr,x_device);// Gets address of x_deviceint*x_tile_ptr;cudaGetSymbolAddress((void**)&x_tile_ptr,x_tile);// Gets address of x_tile// OK: Passing pointer to tile variable into SIMT kernelsimt_function<<<1,1>>>(x_tile_ptr);cudaDeviceSynchronize();// OK: Passing pointer to device variable into tile kerneltile_function<<<1,1>>>(x_device_ptr);cudaDeviceSynchronize();}
structMyStruct{intx;mutableinty;};__device__voidexternal_function(constMyStruct&);__global__voidkernel(const__grid_constant__MyStructs){// s.x++; // Compile error: tried to modify read-only memory// s.y++; // Undefined Behavior: tried to modify read-only memory// Compiler will NOT create a per-thread local copy of "s":external_function(s);}
计算能力 9.0 及更高版本允许用户指定编译时线程块簇维度,以便核函数能够使用 CUDA 中的簇层次结构。编译时簇维度可以使用__cluster_dims__属性按以下语法指定:__cluster_dims__([x,[y,[z]]])。下面的示例展示了编译时簇大小,其中 X 维度为 2,Y 和 Z 维度为 1。
线程块簇的维度也可以在运行时指定,并且可以使用cudaLaunchKernelEx API 启动带有簇的核函数。此 API 接受一个类型为cudaLaunchConfig_t的配置参数、一个核函数指针和核函数参数。下面的示例展示了运行时核函数配置。
__global__voidkernel(floatparameter1,intparameter2){}intmain(){cudaLaunchConfig_tconfig={0};// The grid dimension is not affected by cluster launch, and is still enumerated// using the number of blocks.// The grid dimension should be a multiple of cluster size.config.gridDim=dim3{4};// 4 blocksconfig.blockDim=dim3{32};// 32 threads per blockconfig.dynamicSmemBytes=1024;// 1 KBcudaLaunchAttributeattribute[1];attribute[0].id=cudaLaunchAttributeClusterDimension;attribute[0].val.clusterDim.x=2;// Cluster size in X-dimensionattribute[0].val.clusterDim.y=1;attribute[0].val.clusterDim.z=1;config.attrs=attribute;config.numAttrs=1;floatparameter1=3.0f;intparameter2=4;cudaLaunchKernelEx(&config,kernel,parameter1,parameter2);}
CUDA 核函数每个线程所需的资源可能会以不期望的方式限制最大线程块大小。为保持与未来硬件和工具包的前向兼容性,并确保至少有一个线程块能够在一个流式多处理器(SM)上运行,开发者应包含单参数形式的__launch_bounds__(maxThreadsPerBlock),它指定核函数启动时将使用的最大线程块大小。未这样做可能导致“启动请求的资源过多”错误。在某些情况下,提供双参数版本的__launch_bounds__(maxThreadsPerBlock,minBlocksPerMultiprocessor)可以提高性能。minBlocksPerMultiprocessor的最佳值应通过对每个核函数进行详细分析来确定。
#include<cuda_runtime_api.h>#include<memory.h>#include<cstdlib>#include<ctime>#include<stdio.h>// assuming blockDim.x is 128__global__voidexample_syncthreads(int*input_data,int*output_data){__shared__intshared_data[128];shared_data[threadIdx.x]=input_data[blockDim.x*blockIdx.x+threadIdx.x];// All threads synchronize, guaranteeing all writes to 'shared_data' are ordered // before any thread is unblocked from '__syncthreads()':__syncthreads();// A single thread safely reads 'shared_data':if(threadIdx.x==0){floatsum=0;for(inti=0;i<blockDim.x;++i){sum+=shared_data[i];}output_data[blockIdx.x]=sum;}}voidinitArray(int*A,intlength){std::srand(std::time({}));for(inti=0;i<length;i++){A[i]=int(10.f*(rand()/(float)RAND_MAX));}}intmain(intargc,char**arg){constexprintblock_size=128;constexprintinput_length=1024;constexprintoutput_length=input_length/block_size;// Pointers to memory vectorsint*input=nullptr;int*output=nullptr;int*comparisonResult=(int*)malloc(output_length*sizeof(int));// Use unified memory to allocate bufferscudaMallocManaged(&input,input_length*sizeof(int));cudaMallocManaged(&output,output_length*sizeof(int));initArray(input,input_length);intgrid_size=input_length/block_size;example_syncthreads<<<grid_size,block_size>>>(input,output);cudaDeviceSynchronize();for(inti=0;i<output_length;i++){comparisonResult[i]=0;for(intj=0;j<block_size;j++){comparisonResult[i]+=input[i*block_size+j];}}for(inti=0;i<output_length;i++){if(output[i]!=comparisonResult[i]){printf("Results do not match at index %d: %d != %d\n",i,output[i],comparisonResult[i]);exit(-1);}}printf("Test passed\n");return0;}
// assuming blockDim.x is 128__global__voidsyncthreads_valid_behavior(int*input_data,int*output_data){__shared__intshared_data[128];shared_data[threadIdx.x]=input_data[threadIdx.x];if(blockIdx.x>0){// CORRECT, uniform condition across all block threads__syncthreads();output_data[threadIdx.x]=shared_data[128-threadIdx.x];}}
而以下示例则表现出无效行为,例如核函数挂起,或未定义行为:
// assuming blockDim.x is 128__global__voidsyncthreads_invalid_behavior1(int*input_data,int*output_data){__shared__intshared_data[256];shared_data[threadIdx.x]=input_data[threadIdx.x];if(threadIdx.x>0){// WRONG, non-uniform condition__syncthreads();// Undefined Behavioroutput_data[threadIdx.x]=shared_data[128-threadIdx.x];}}
// assuming blockDim.x is 128__global__voidsyncthreads_invalid_behavior2(int*input_data,int*output_data){__shared__intshared_data[256];shared_data[threadIdx.x]=input_data[threadIdx.x];for(inti=0;i<blockDim.x;++i){if(i==threadIdx.x){// WRONG, non-uniform condition__syncthreads();// Undefined Behavior}}output_data[threadIdx.x]=shared_data[128-threadIdx.x];}
__global__voidexample_syncwarp(int*input_data,int*output_data){if(threadIdx.x<warpSize){__shared__intshared_data[warpSize];shared_data[threadIdx.x]=input_data[threadIdx.x];__syncwarp();// equivalent to __syncwarp(0xFFFFFFFF)if(threadIdx.x==0)output_data[0]=shared_data[1];}}
5.4.4.3. 内存栅栏函数
CUDA 编程模型假定采用弱序内存模型。换言之,CUDA 线程向共享内存、全局内存、页锁定主机内存或对等设备内存写入数据的顺序,不一定与另一个 CUDA 线程或主机线程观察到数据写入的顺序一致。在没有内存栅栏或同步的情况下读取或写入同一内存位置,会导致未定义行为。
#include<cuda/atomic>__device__intcount=0;__global__voidsum(constfloat*array,intN,volatilefloat*result){__shared__boolisLastBlockDone;// Each block sums a subset of the input array.floatpartialSum=calculatePartialSum(array,N);if(threadIdx.x==0){// Thread 0 of each block stores the partial sum to global memory.// The compiler will use a store operation that bypasses the L1 cache// since the "result" variable is declared as volatile.// This ensures that the threads of the last block will read the correct// partial sums computed by all other blocks.result[blockIdx.x]=partialSum;// Thread 0 makes sure that the increment of the "count" variable is// only performed after the partial sum has been written to global memory.cuda::atomic_thread_fence(cuda::memory_order_seq_cst,cuda::thread_scope_device);// Thread 0 signals that it is done.intcount_old=atomicInc(&count,gridDim.x);// Thread 0 determines if its block is the last block to be done.isLastBlockDone=(count_old==(gridDim.x-1));}// Synchronize to make sure that each thread reads the correct value of// isLastBlockDone.__syncthreads();if(isLastBlockDone){// The last block sums the partial sums stored in result[0 .. gridDim.x-1]floattotalSum=calculateTotalSum(result);if(threadIdx.x==0){// Thread 0 of last block stores the total sum to global memory and// resets the count variable, so that the next kernel call works// properly.result[0]=totalSum;count=0;}}}
#include<cuda_runtime.h>__global__voidatomicAdd_kernel(int*addr){atomicAdd_system(addr,10);}voidtest_atomicAdd(intdevice_id){int*addr;cudaMallocManaged(&addr,4);*addr=0;cudaDevicePropdeviceProp;cudaGetDeviceProperties(&deviceProp,device_id);if(deviceProp.concurrentManagedAccess!=1){return;// the device does not coherently access managed memory concurrently with the CPU}atomicAdd_kernel<<<...>>>(addr);__sync_fetch_and_add(addr,10);// CPU atomic operation}
#include<cuda/memory>#include<cuda/std/bit>__device__floatcustomAtomicAdd(float*d_ptr,floatvalue){volatileunsigned*d_ptr_unsigned=reinterpret_cast<unsigned*>(d_ptr);unsignedold_value=*d_ptr_unsigned;unsignedassumed;do{assumed=old_value;floatassumed_float=cuda::std::bit_cast<float>(assumed);floatexpected_value=assumed_float+value;unsignedexpected_value_unsigned=cuda::std::bit_cast<unsigned>(expected_value);old_value=atomicCAS(d_ptr_unsigned,assumed,expected_value_unsigned);// Note: uses integer comparison to avoid hang in case of NaN (since NaN != NaN)}while(assumed!=old_value);returncuda::std::bit_cast<float>(old_value);}
// Not permitted in a host function__host__voidbar(){unsignedu1=1,u2=2;__nv_atomic_load(&u1,&u2,__NV_ATOMIC_RELAXED,__NV_THREAD_SCOPE_SYSTEM);}// Not permitted to be applied to local memory__device__voidfoo(){unsigneda=1,b;__nv_atomic_load(&a,&b,__NV_ATOMIC_RELAXED,__NV_THREAD_SCOPE_SYSTEM);}// Not permitted as a template default argument.// The function address cannot be taken.template<void*F=__nv_atomic_load_n>classX{void*f=F;// The function address cannot be taken.};// Not permitted to be called in a constructor initialization list.classY{inta;public:__device__Y(int*b):a(__nv_atomic_load_n(b,__NV_ATOMIC_RELAXED)){}};
// Check whether at least one thread's predicate evaluates to trueif(pred){// Invalid: the value of 'at_least_one' is non-deterministic// and could vary between executions.at_least_one=__activemask()>0;}
unsignedmask=__activemask();// Assume mask == 0xFFFFFFFF (all bits set, all threads active)intpredicate=threadIdx.x%2==0;// 1 for even threads, 0 for odd threadsintresult=__any_sync(mask,predicate);// Active threads might not be preserved
intlaneId=threadIdx.x%warpSize;intdata=...// all warp threads get 'data' from lane 0intresult1=__shfl_sync(0xFFFFFFFF,data,0);if(laneId<4){// lanes 0, 1, 2, 3 get 'data' from lane 1intresult2=__shfl_sync(0xb1111,data,1);}// lanes [0 - 15] get 'data' from lane 0// lanes [16 - 31] get 'data' from lane 16intresult3=__shfl_sync(0xFFFFFFFF,value,warpSize/2);// each lane gets 'data' from the lane two positions above// lanes 30, 31 get their original valueintresult4=__shfl_down_sync(0xFFFFFFFF,data,2);
无效的线程束洗牌用法示例:
intlaneId=threadIdx.x%warpSize;intvalue=...// undefined behavior: lane 0 does not participate in the callintresult=(laneId>0)?__shfl_sync(0xFFFFFFFF,value,0):0;if(laneId<=4){// undefined behavior: destination lanes 5, 6 are not active for lanes 3, 4result=__shfl_down_sync(0b11111,value,2);}// undefined behavior: width is not a power of 2__shfl_sync(0xFFFFFFFF,value,0,/*width=*/31);
警告
这些内建函数并不隐含内存屏障。它们不保证任何内存顺序。
示例 1:在线程束内广播单个值
#include<cassert>#include<cuda/warp>__global__voidwarp_broadcast_kernel(intinput){intlaneId=threadIdx.x%32;intvalue;if(laneId==0){// unused variable for all threads except lane 0value=input;}value=cuda::device::warp_shuffle_idx(value,0);// Synchronize all threads in warp, and get "value" from lane 0assert(value==input);}intmain(){warp_broadcast_kernel<<<1,32>>>(1234);cudaDeviceSynchronize();return0;}
#include<assert.h>__global__voidwarp_broadcast_kernel(intinput){intlaneId=threadIdx.x%32;intvalue;if(laneId==0){// unused variable for all threads except lane 0value=input;}value=__shfl_sync(0xFFFFFFFF,value,0);// Synchronize all threads in warp, and get "value" from lane 0assert(value==input);}intmain(){warp_broadcast_kernel<<<1,32>>>(1234);cudaDeviceSynchronize();return0;}
#include<cstdio>#include<cub/cub.cuh>__global__voidscan_sub_partition_with_8_threads_kernel(){usingWarpScan=cub::WarpScan<int,8>;usingTempStorage=typenameWarpScan::TempStorage;__shared__TempStoragetemp_storage;intlaneId=threadIdx.x%32;intvalue=31-laneId;// starting value to accumulateintpartial_sum;WarpScan(temp_storage).InclusiveSum(value,partial_sum);printf("Thread %d final value = %d\n",threadIdx.x,partial_sum);}intmain(){scan_sub_partition_with_8_threads_kernel<<<1,32>>>();cudaDeviceSynchronize();return0;}
#include<stdio.h>__global__voidscan_sub_partition_with_8_threads_kernel(){intlaneId=threadIdx.x%32;intvalue=31-laneId;// starting value to accumulate// Loop to accumulate scan within my partition.// Scan requires log2(8) == 3 steps for 8 threadsfor(intdelta=1;delta<=4;delta*=2){inttmp=__shfl_up_sync(0xFFFFFFFF,value,delta,/*width=*/8);// read from laneId - deltaintsource_lane=laneId%8-delta;if(source_lane>=0)// lanes with 'source_lane < 0' have their value unchangedvalue+=tmp;}printf("Thread %d final value = %d\n",threadIdx.x,value);}intmain(){scan_sub_partition_with_8_threads_kernel<<<1,32>>>();cudaDeviceSynchronize();return0;}
#include<cstdio>#include<cub/cub.cuh>#include<cuda/warp>__global__voidwarp_reduce_kernel(){usingWarpReduce=cub::WarpReduce<int>;usingTempStorage=typenameWarpReduce::TempStorage;__shared__TempStoragetemp_storage;intlaneId=threadIdx.x%32;intvalue=31-laneId;// starting value to accumulateautoaggregate=WarpReduce(temp_storage).Sum(value);aggregate=cuda::device::warp_shuffle_idx(aggregate,0);printf("Thread %d final value = %d\n",threadIdx.x,aggregate);}intmain(){warp_reduce_kernel<<<1,32>>>();cudaDeviceSynchronize();return0;}
#include<stdio.h>__global__voidwarp_reduce_kernel(){intlaneId=threadIdx.x%32;intvalue=31-laneId;// starting value to accumulate// Use XOR mode to perform butterfly reduction// A full-warp reduction requires log2(32) == 5 stepsfor(inti=1;i<=16;i*=2)value+=__shfl_xor_sync(0xFFFFFFFF,value,i);// "value" now contains the sum across all threadsprintf("Thread %d final value = %d\n",threadIdx.x,value);}intmain(){warp_reduce_kernel<<<1,32>>>();cudaDeviceSynchronize();return0;}
__global__voidvalid_examples(){if(threadIdx.x<4){// threads 0, 1, 2, 3 are active__all_sync(0b1111,pred);// CORRECT, threads 0, 1, 2, 3 participate in the call}if(threadIdx.x==0)return;// exit// CORRECT, all non-exited threads participate in the call__all_sync(0xFFFFFFFF,pred);}
if(threadIdx.x<4){// threads 0, 1, 2, 3 are active__all_sync(0b0000011,pred);// WRONG, threads 2, 3 are active but not set in mask__all_sync(0b1111111,pred);// WRONG, threads 4, 5, 6 are not active but set in mask}// WRONG, participating threads have a different and overlapping mask__all_sync(threadIdx.x==0?1:0xFFFFFFFF,pred);
#if !defined(__CUDA_ARCH__)typedefintmy_type;#elsetypedefdoublemy_type;#endif__device__my_typemy_var;// ERROR: my_var's type depends on __CUDA_ARCH____global__voidkernel(my_typein){// ERROR: kernel's type depends on __CUDA_ARCH__...}
__device__intresult;template<typenameT>__global__voidkernel(Tin){result=in;}__host____device__voidhost_device_function(void){#if !defined(__CUDA_ARCH__)kernel<<<1,1>>>(1);// ERROR: "kernel<int>" instantiation only// when __CUDA_ARCH__ is undefined!#endif}intmain(void){host_device_function();cudaDeviceSynchronize();return0;}
#if !defined(__CUDA_ARCH__)voidhost_function(void){}// ERROR: The definition of host_function()// is only present when __CUDA_ARCH__// is undefined#endif
nvcc -arch=compute_70 -dc a.cu
nvcc -arch=compute_80 -dc b.cu
nvcc -arch=sm_80 a.o b.o
Only one version of the ``get_ptr()`` function is used at link time, so the behavior depends on which version is chosen. To avoid this issue, either ``a.cu`` and ``b.cu`` must be compiled for the same compute architecture, or ``__CUDA_ARCH__`` should not be used in the shared header function.
size_tsmem_ptr_64bit=static_cast<size_t>(smem_ptr_32bit);// zero-extend to 64 bitsvoid*generic_ptr=__cvta_shared_to_generic(smem_ptr_64bit);assert(generic_ptr==&smem_var);
5.4.8.3. 低级加载和存储函数
T__ldg(constT*address);
函数__ldg()执行只读 L1/Tex 缓存加载。它支持所有 C++ 基本类型、CUDA 向量类型(三分量类型除外)以及扩展浮点类型,例如__half、__half2、__nv_bfloat16和__nv_bfloat162。
unsigneda=9;unsignedb=6;boolsmaller_value;unsignedmin_value=__vibmin_u32(a,b,&smaller_value);// min_value is 6, smaller_value is true
三对无符号 16 位整数的最大值:
unsigneda=0x00050002;unsignedb=0x00070004;unsignedc=0x00020006;unsignedmax_value=__vimax3_u16x2(a,b,c);// max(5, 7, 2) and max(2, 4, 6), so max_value is 0x00070006
void*res1=__builtin_assume_aligned(ptr,32);// compiler can assume 'res1' is at least 32-byte alignedvoid*res2=__builtin_assume_aligned(ptr,32,8);// compiler can assume 'res2 = (char*) ptr - 8' is at least 32-byte aligned
5.4.9.3. __builtin_assume()和__assume()
void__builtin_assume(boolpredicate)void__assume(boolpredicate)// only with Microsoft Compiler
__device__boolis_greater_than_zero(intvalue){returnvalue>0;}__device__boolf(intvalue){__builtin_assume(value>0);returnis_greater_than_zero(value);// returns true, without evaluating the condition}
或者,也可以将它直接放在设备函数内部 C++ 表达式语句中的间接函数调用之前。请注意,虽然支持对自由函数的间接函数调用,但不支持对函数引用或类成员函数的间接调用。
__device__intdev_func1();structMyStruct{__device__intmember_func2();};__device__voidtest(){auto*dev_func_ptr=&dev_func1;// type: int (*)(void)#pragma nv_abi preserve_n_control(8)intv1=dev_func_ptr();// CORRECT, indirect call#pragma nv_abi preserve_n_control(8)intv2=dev_func1();// WRONG, direct call; the pragma has no effect// dev_func1 has type: int(void)auto&dev_func_ref=&dev_func1;// type: int (&)(void)#pragma nv_abi preserve_n_control(8)intv3=dev_func_ref();// WRONG, call to a reference// the pragma has no effectautomember_function_ptr=&MyStruct::member_func2;// type: int (MyStruct::*)(void)#pragma nv_abi preserve_n_control(8)intv4=member_function_ptr();// WRONG, indirect call to member function// the pragma has no effect}
当此 pragma 指令应用于设备函数的声明或定义时,它会修改对该函数的任何调用的自定义 ABI 属性。当它放置在间接函数调用位置时,仅影响该特定调用的 ABI 属性。请注意,放置在调用位置时,此 pragma 指令仅影响间接函数调用;它对直接函数调用没有影响。
#pragma nv_abi preserve_n_control(8)__device__intdev_func3();__device__intdev_func4();__device__voidtest(){intv1=dev_func3();// CORRECT, the pragma affects the direct callauto*dev_func_ptr=&dev_func4;// type: int (*)(void)#pragma nv_abi preserve_n_control(8)intv2=dev_func_ptr();// CORRECT, the pragma affects the indirect callintv3=dev_func_ptr();// WRONG, the pragma has no effect}
核函数的执行会中止,并在主机程序中引发中断。assert()宏会导致 CUDA 上下文损坏,使任何后续的 CUDA 调用或核函数调用均以cudaErrorAssert失败。
如果expression不等于零,则核函数执行不受影响。
例如,源文件test.cu中的以下程序
#include<assert.h>__global__voidtestAssert(void){intis_one=1;intshould_be_one=0;// This will have no effectassert(is_one);// This will halt kernel executionassert(should_be_one);}intmain(void){testAssert<<<1,1>>>();cudaDeviceSynchronize();return0;}
#pragma nv_diag_suppress 177 // "declared but never referenced"voidfoo(){inti=0;}#pragma nv_diag_default 177voidbar(){inti=0;}
以下 pragma 指令可用于保存和恢复当前的诊断 pragma 指令状态:
#pragma nv_diagnostic push#pragma nv_diagnostic pop
示例:
#pragma nv_diagnostic push#pragma nv_diag_suppress 177 // "declared but never referenced"voidfoo(){inti=0;}#pragma nv_diagnostic popvoidbar(){inti=0;// raise a warning}
wmma::fragment<wmma::accumulator,16,16,16,float>frag;floatalpha=0.5f;// Same value for all threads in warp/*...*/for(intt=0;t<frag.num_elements;t++)frag.x[t]*=alpha;
对于 4 位精度,可用的 API 保持不变,但必须将experimental::precision::u4或experimental::precision::s4指定为片段的数据类型。由于片段的元素被打包在一起,因此该片段的num_storage_elements将小于num_elements。因此,子字节片段的num_elements变量返回子字节类型element_type<T>的元素数量。这也适用于单比特精度,在这种情况下,从element_type<T>到storage_element_type<T>的映射如下:
experimental::precision::u4->unsigned(8elementsin1storageelement)experimental::precision::s4->int(8elementsin1storageelement)experimental::precision::b1->unsigned(32elementsin1storageelement)T->T//all other types
张量核心所需的特殊格式可能因设备架构的每个主版本和次版本而异。线程仅持有整个矩阵的一个片段(一种不透明的、特定于架构的 ABI 数据结构),这使情况更加复杂;开发者不得对各个参数如何映射到参与矩阵乘加运算的寄存器作出假设。
由于片段是特定于架构的,如果函数 A 和函数 B 是针对不同但链接兼容的架构编译的,并被链接到同一个设备可执行文件中,则将片段从函数 A 传递到函数 B 是不安全的。在这种情况下,片段的大小和布局将特定于一种架构,在另一种架构中使用 WMMA API 将导致不正确的结果,或者可能导致数据损坏。
sm_70 和 sm_75 就是两个链接兼容但片段布局不同的架构示例。
fragA.cu:voidfoo(){wmma::fragment<...>mat_a;bar(&mat_a);}fragB.cu:voidbar(wmma::fragment<...>*mat_a){// operate on mat_a }
// sm_70 fragment layout$>nvcc-dc-arch=compute_70-code=sm_70fragA.cu-ofragA.o// sm_75 fragment layout$>nvcc-dc-arch=compute_75-code=sm_75fragB.cu-ofragB.o// Linking the two together$>nvcc-dlink-arch=sm_75fragA.ofragB.o-ofrag.o
#include<mma.h>usingnamespacenvcuda;__global__voidwmma_ker(half*a,half*b,float*c){// Declare the fragmentswmma::fragment<wmma::matrix_a,16,16,16,half,wmma::col_major>a_frag;wmma::fragment<wmma::matrix_b,16,16,16,half,wmma::row_major>b_frag;wmma::fragment<wmma::accumulator,16,16,16,float>c_frag;// Initialize the output to zerowmma::fill_fragment(c_frag,0.0f);// Load the inputswmma::load_matrix_sync(a_frag,a,16);wmma::load_matrix_sync(b_frag,b,16);// Perform the matrix multiplicationwmma::mma_sync(c_frag,a_frag,b_frag,c_frag);// Store the outputwmma::store_matrix_sync(c,c_frag,16,wmma::mem_row_major);}
5.5. 浮点计算
5.5.1. 浮点数简介
自 1985 年二进制浮点算术IEEE-754 标准获采纳以来,几乎所有主流计算系统,包括 NVIDIA 的 CUDA 架构,都已实现该标准。IEEE-754 标准规定了应如何对浮点算术的结果进行近似。
融合乘加运算对 NaN 传播的影响可能与两个独立运算不同。但是,FMA 对 NaN 的处理并非在所有目标平台上都完全相同。当存在多个 NaN 操作数时,不同的实现可能优先选择静默 NaN,也可能传播某个操作数的载荷。此外,当存在多个 NaN 操作数时,IEEE-754 并未严格要求确定性的载荷选择顺序。NaN 也可能出现在中间计算中,例如或,从而产生由实现定义的 NaN 载荷。
另请参阅nvcc用户手册,了解专门影响 CUDA 设备代码中浮点行为的编译器标志的详细说明:-ftz、-prec-div、-prec-sqrt、-fmad、--use_fast_math。除了这些浮点选项之外,在用户程序的具体情境中验证其他编译器优化的影响也很重要。建议用户通过广泛的测试来验证结果的正确性,并比较启用优化时获得的结果与禁用所有设备代码优化时获得的结果;另请参阅-G编译器标志。
当舍入为整数后的值超出目标整数格式的范围时,IEEE-754 和 C/C++ 语言标准都没有明确规定浮点值到整数值的转换。GPU 设备将值钳位到范围内的行为在PTX ISA 转换指令一节中进行了说明。不过,如果超出范围的转换不是直接通过 PTX 指令调用的,编译器优化可能会利用未指定行为条款,从而导致未定义行为,并使 CUDA 程序无效。CUDA Math 文档针对各个函数/内建函数向用户发出警告。例如,请考虑__double2int_rz()指令。这可能与主机编译器和库实现的行为不同。
floatf1=0.5f;// 0.5, '0.5f' is a decimal floating-point literalfloatf2=0x1p-1f;// 0.5, '0x1p-1f' is a hexadecimal floating-point literalfloatf3=0.1f;// f1, f2 are represented as 0 01111110 00000000000000000000000// f3 is represented as 0 01111011 10011001100110011001101
/// Loading an integer from global into shared memory__global__voidkernel(int*globalInput){__shared__intx;thread_blockg=this_thread_block();// Choose a leader in the thread blockif(g.thread_rank()==0){// load from global into shared for all threads to work withx=(*globalInput);}// After loading data into shared memory, you want to synchronize// if all threads in your thread block need to see itg.sync();// equivalent to __syncthreads();}
/// The following code will create two sets of tiled groups, of size 32 and 4 respectively:/// The latter has the provenance encoded in the type, while the first stores it in the handlethread_blockblock=this_thread_block();thread_block_tile<32>tile32=tiled_partition<32>(block);thread_block_tile<4,thread_block>tile4=tiled_partition<4>(block);
/// The following code will create tiles of size 128 on all Compute Capabilities./// block_tile_memory can be omitted on Compute Capability 8.0 or higher.__global__voidkernel(...){// reserve shared memory for thread_block_tile usage,// specify that block size will be at most 256 threads.__shared__block_tile_memory<256>shared;thread_blockthb=this_thread_block(shared);// Create tiles with 128 threads.autotile=tiled_partition<128>(thb);// ...}
5.6.3.1.5. coalesced_group 类
在 CUDA 的 SIMT 架构中,多处理器在硬件层面上以每组 32 个线程的方式执行线程,这些组称为线程束。如果应用程序代码中存在依赖数据的条件分支,导致线程束内的线程发生分歧,则线程束会串行执行每个分支,并禁用不在该路径上的线程。在路径上保持活跃的线程称为合并线程。协作组提供了发现并创建包含所有合并线程的组的功能。
/// Consider a situation whereby there is a branch in the/// code in which only the 2nd, 4th and 8th threads in each warp are/// active. The coalesced_threads() call, placed in that branch, will create (for each/// warp) a group, active, that has three threads (with/// ranks 0-2 inclusive).__global__voidkernel(int*globalInput){// Lets say globalInput says that threads 2, 4, 8 should handle the dataif(threadIdx.x==*globalInput){coalesced_groupactive=coalesced_threads();// active contains 0-2 inclusiveactive.sync();}}
勘误在 CUDA 11.1 中引入的、同时接受 src 和 dst 输入布局的memcpy_asyncAPI 要求以元素而非字节为单位提供布局。元素类型从TyElem推断得出,其大小为sizeof(TyElem)。如果使用cuda::aligned_size_t<N>类型作为布局,则指定的元素数乘以sizeof(TyElem)必须是 N 的倍数,并且建议使用std::byte或char作为元素类型。
如果指定的复制形状或布局的类型为cuda::aligned_size_t<N>,则将保证对齐值至少为min(16,N)。在这种情况下,dst和src指针都需要按 N 字节对齐,并且复制的字节数需要是 N 的倍数。
代码生成要求:计算能力最低为 5.0,异步性要求计算能力为 8.0,C++11
需要包含cooperative_groups/memcpy_async.h头文件。
示例:
/// This example streams elementsPerThreadBlock worth of data from global memory/// into a limited sized shared memory (elementsInShared) block to operate on.#include<cooperative_groups.h>#include<cooperative_groups/memcpy_async.h>namespacecg=cooperative_groups;__global__voidkernel(int*global_data){cg::thread_blocktb=cg::this_thread_block();constsize_telementsPerThreadBlock=16*1024;constsize_telementsInShared=128;__shared__intlocal_smem[elementsInShared];size_tcopy_count;size_tindex=0;while(index<elementsPerThreadBlock){cg::memcpy_async(tb,local_smem,elementsInShared,global_data+index,elementsPerThreadBlock-index);copy_count=min(elementsInShared,elementsPerThreadBlock-index);cg::wait(tb);// Work with local_smemindex+=copy_count;}}
/// This example streams elementsPerThreadBlock worth of data from global memory/// into a limited sized shared memory (elementsInShared) block to operate on in/// multiple (two) stages. As stage N is kicked off, we can wait on and operate on stage N-1.#include<cooperative_groups.h>#include<cooperative_groups/memcpy_async.h>namespacecg=cooperative_groups;__global__voidkernel(int*global_data){cg::thread_blocktb=cg::this_thread_block();constsize_telementsPerThreadBlock=16*1024+64;constsize_telementsInShared=128;__align__(16)__shared__intlocal_smem[2][elementsInShared];intstage=0;// First kick off an extra requestsize_tcopy_count=elementsInShared;size_tindex=copy_count;cg::memcpy_async(tb,local_smem[stage],elementsInShared,global_data,elementsPerThreadBlock-index);while(index<elementsPerThreadBlock){// Now we kick off the next request...cg::memcpy_async(tb,local_smem[stage^1],elementsInShared,global_data+index,elementsPerThreadBlock-index);// ... but we wait on the one before itcg::wait_prior<1>(tb);// Its now available and we can work with local_smem[stage] here// (...)//// Calculate the amount of data that was actually copied, for the next iteration.copy_count=min(elementsInShared,elementsPerThreadBlock-index);index+=copy_count;// A cg::sync(tb) might be needed here depending on whether// the work done with local_smem[stage] can release threads to race ahead or not// Wrap to the next stagestage^=1;}cg::wait(tb);// The last local_smem[stage] can be handled here}
/// This example divides a 32-sized tile into a group with odd/// numbers and a group with even numbers_global__voidoddEven(int*inputArr){autoblock=cg::this_thread_block();autotile32=cg::tiled_partition<32>(block);// inputArr contains random integersintelem=inputArr[block.thread_rank()];// after this, tile32 is split into 2 groups,// a subtile where elem&1 is true and one where its falseautosubtile=cg::binary_partition(tile32,(elem&1));}
{// cg::plus<int> is specialized within cg::reduce and calls __reduce_add_sync(...) on CC 8.0+cg::reduce(tile,(int)val,cg::plus<int>());// cg::plus<float> fails to match with an accelerator and instead performs a standard shuffle based reductioncg::reduce(tile,(float)val,cg::plus<float>());// While individual components of a vector are supported, reduce will not use hardware intrinsics for the following// It will also be necessary to define a corresponding operator for vector and any custom types that may be usedint4vec={...};cg::reduce(tile,vec,cg::plus<int4>())// Finally lambdas and other function objects cannot be inspected for dispatch// and will instead perform shuffle based reductions using the provided function object.cg::reduce(tile,(int)val,[](intl,intr)->int{returnl+r;});}
API 的*_async变体异步计算结果,由其中一个参与线程将结果存储到指定目标或用于更新指定目标,而不是由每个线程返回结果。要观察这些异步调用的效果,调用这些操作的线程组或包含这些线程的更大的组需要进行同步。
对于原子存储或更新变体,atomic参数可以是CUDA C++ Standard Library中提供的cuda::atomic或cuda::atomic_ref。此 API 变体仅可在 CUDA C++ Standard Library 支持这些类型的平台和设备上使用。归约结果用于根据指定的op以原子方式更新原子对象,例如,对于cg::plus(),结果会以原子方式加到原子对象上。atomic所持有的类型必须与TyArg的类型匹配。原子对象的作用域必须包含组中的所有线程,如果多个组并发使用同一个原子对象,则作用域必须包含使用该原子对象的所有组中的所有线程。原子更新以宽松内存顺序执行。
*_scan_update集体操作接受一个额外的参数atomic,该参数可以是CUDA C++ Standard Library中提供的cuda::atomic或cuda::atomic_ref。这些 API 变体仅可在 CUDA C++ Standard Library 支持这些类型的平台和设备上使用。这些变体将根据op,使用组中所有线程的输入值之和对atomic执行更新。每个线程都会将atomic的先前值与扫描结果组合并返回。atomic所持有的类型必须与TyVal的类型匹配。原子对象的作用域必须包含组中的所有线程,如果多个组并发使用同一个原子对象,则作用域必须包含使用该原子对象的所有组中的所有线程。原子更新以宽松内存顺序执行。
以下伪代码说明了扫描的更新变体如何工作:
/* inclusive_scan_update behaves as the following block, except both reduce and inclusive_scan is calculated simultaneously.auto total = reduce(group, val, op);TyVal old;if (group.thread_rank() == selected_thread) { atomically { old = atomic.load(); atomic.store(op(old, total)); }}old = group.shfl(old, selected_thread);return op(inclusive_scan(group, val, op), old);*/
需要包含cooperative_groups/scan.h头文件。
使用 exclusive_scan 进行流压缩的示例:
#include<cooperative_groups.h>#include<cooperative_groups/scan.h>namespacecg=cooperative_groups;// put data from input into output only if it passes test_fn predicatetemplate<typenameGroup,typenameData,typenameTyFn>__device__intstream_compaction(Group&g,Data*input,intcount,TyFn&&test_fn,Data*output){intper_thread=count/g.num_threads();intthread_start=min(g.thread_rank()*per_thread,count);intmy_count=min(per_thread,count-thread_start);// get all passing items from my part of the input// into a contagious part of the array and count them.inti=thread_start;while(i<my_count+thread_start){if(test_fn(input[i])){i++;}else{my_count--;input[i]=input[my_count+thread_start];}}// scan over counts from each thread to calculate my starting// index in the outputintmy_idx=cg::exclusive_scan(g,my_count);for(i=0;i<my_count;++i){output[my_idx+i]=input[thread_start+i];}// return the total number of items in the outputreturng.shfl(my_idx+my_count,g.num_threads()-1);}
使用 exclusive_scan_update 进行动态缓冲区空间分配的示例:
#include<cooperative_groups.h>#include<cooperative_groups/scan.h>namespacecg=cooperative_groups;// Buffer partitioning is static to make the example easier to follow,// but any arbitrary dynamic allocation scheme can be implemented by replacing this function.__device__intcalculate_buffer_space_needed(cg::thread_block_tile<32>&tile){returntile.thread_rank()%2+1;}__device__intmy_thread_data(inti){returni;}__global__voidkernel(){__shared__externintbuffer[];__shared__cuda::atomic<int,cuda::thread_scope_block>buffer_used;autoblock=cg::this_thread_block();autotile=cg::tiled_partition<32>(block);buffer_used=0;block.sync();// each thread calculates buffer size it needsintbuf_needed=calculate_buffer_space_needed(tile);// scan over the needs of each thread, result for each thread is an offset// of that thread’s part of the buffer. buffer_used is atomically updated with// the sum of all thread's inputs, to correctly offset other tile’s allocationsintbuf_offset=cg::exclusive_scan_update(tile,buffer_used,buf_needed);// each thread fills its own part of the buffer with thread specific datafor(inti=0;i<buf_needed;++i){buffer[buf_offset+i]=my_thread_data(i);}block.sync();// buffer_used now holds total amount of memory allocated// buffer is {0, 0, 1, 0, 0, 1 ...};}
#include<cooperative_groups.h>usingnamespacecooperative_groups;void__device__init_shared_data(constthread_block&block,int*data);void__device__local_processing(constthread_block&block);void__device__process_shared_data(constthread_block&block,int*data);__global__voidcluster_kernel(){extern__shared__intarray[];autocluster=this_cluster();autoblock=this_thread_block();// Use this thread block to initialize some shared stateinit_shared_data(block,&array[0]);autotoken=cluster.barrier_arrive();// Let other blocks know this block is running and data was initialized// Do some local processing to hide the synchronization latencylocal_processing(block);// Map data in shared memory from the next block in the clusterint*dsmem=cluster.map_shared_rank(&array[0],(cluster.block_rank()+1)%cluster.num_blocks());// Make sure all other blocks in the cluster are running and initialized shared data before accessing dsmemcluster.barrier_wait(std::move(token));// Consume data in distributed shared memoryprocess_shared_data(block,dsmem);cluster.sync();}
例如,在某些用例中,应用程序具有大量小型核函数,每个核函数代表处理流水线中的一个阶段。当前 CUDA 编程模型要求存在这些核函数,以确保在下一流水线阶段工作的线程块准备好使用数据之前,当前流水线阶段的线程块已经生成数据。在这种情况下,提供全局线程块间同步的能力将允许重构应用程序,使其具有持久线程块,这些线程块能够在给定阶段完成时在设备上进行同步。
要在核函数内部对整个网格进行同步,只需使用grid.sync()函数:
grid_groupgrid=this_grid();grid.sync();
而在启动核函数时,必须使用cudaLaunchCooperativeKernelCUDA 运行时启动 API 或CUDAdriverequivalent,而不是<<<...>>>执行配置语法。
示例:
为了保证线程块同时驻留在 GPU 上,需要仔细考虑启动的线程块数量。例如,可以按如下方式启动与 SM 数量相同的线程块:
intdev=0;cudaDevicePropdeviceProp;cudaGetDeviceProperties(&deviceProp,dev);// initialize, then launchcudaLaunchCooperativeKernel((void*)my_kernel,deviceProp.multiProcessorCount,numThreads,args);
或者,可以按如下方式使用占用率计算器,计算每个 SM 可以同时容纳多少个线程块,从而最大限度地提高可用并行度:
/// This will launch a grid that can maximally fill the GPU, on the default stream with kernel argumentsintnumBlocksPerSm=0;// Number of threads my_kernel will be launched withintnumThreads=128;cudaDevicePropdeviceProp;cudaGetDeviceProperties(&deviceProp,dev);cudaOccupancyMaxActiveBlocksPerMultiprocessor(&numBlocksPerSm,my_kernel,numThreads,0);// launchvoid*kernelArgs[]={/* add kernel args */};dim3dimBlock(numThreads,1,1);dim3dimGrid(deviceProp.multiProcessorCount*numBlocksPerSm,1,1);cudaLaunchCooperativeKernel((void*)my_kernel,dimGrid,dimBlock,kernelArgs);
在 CUDA C++ 中,共享内存既可以声明为大小静态确定的文件作用域变量或函数作用域变量,也可以声明为extern变量,其大小由核函数的调用方在运行时通过启动配置参数确定。这两种声明类型在设备运行时中均有效。
__global__voidpermute(intn,int*data){extern__shared__intsmem[];if(n<=1)return;smem[threadIdx.x]=data[threadIdx.x];__syncthreads();permute_data(smem,n);__syncthreads();// Write back to GMEM since we can't pass SMEM to children.data[threadIdx.x]=smem[threadIdx.x];__syncthreads();if(threadIdx.x==0){permute<<<1,256,n/2*sizeof(int)>>>(n/2,data);permute<<<1,256,n/2*sizeof(int)>>>(n/2,data+n/2);}}voidhost_launch(int*data){permute<<<1,256,256*sizeof(int)>>>(256,data);}
由于可以直接引用设备端符号,那些引用符号的 CUDA 运行时 API(例如cudaMemcpyToSymbol()或cudaGetSymbolAddress())便没有必要,设备运行时也不支持它们。这意味着,无法在正在运行的核函数内更改常量数据,即使是在子核函数启动之前也不行,因为对__constant__空间的引用是只读的。
5.6.4.3. SM ID 和线程束 ID
请注意,在 PTX 中,%smid和%warpid被定义为易变值。设备运行时可能会将线程块重新调度到不同的 SM 上,以便更高效地管理资源。因此,依赖%smid或%warpid在线程或线程块的整个生命周期内保持不变是不安全的。
5.6.4.4. 启动设置 API
设备端核函数启动介绍了从设备代码启动核函数的语法,该语法使用与主机 CUDA 运行时 API 相同的三重尖括号启动表示法。
核函数启动是一种通过设备运行时库公开的系统级机制。也可以通过cudaGetParameterBuffer()和cudaLaunchDevice() API 直接从 PTX 使用该机制。CUDA 应用程序可以自行调用这些 API,其要求与 PTX 相同。在这两种情况下,用户均需负责按照规范,以正确的格式正确填充所有必要的数据结构。这些数据结构保证向后兼容。
CUDA 设备运行时公开了一些特殊的命名流,它们为从设备启动的核函数和图提供特定行为。与设备图启动相关的命名流在设备启动中有介绍。另外两个可在 CUDA 设备运行时中用于核函数和 memcpy 操作的命名流是cudaStreamTailLaunch和cudaStreamTailLaunch。本节介绍这些命名流的具体行为。
// In this example, C2's launch will not wait for C1's completion__global__voidP(...){C1<<<...,cudaStreamFireAndForget>>>(...);C2<<<...,cudaStreamFireAndForget>>>(...);}
// In this example, C2 will only launch after C1 completes.__global__voidP(...){C1<<<...,cudaStreamTailLaunch>>>(...);C2<<<...,cudaStreamTailLaunch>>>(...);}
// In this example, C will only launch after all X, F and P complete.__global__voidP(...){C<<<...,cudaStreamTailLaunch>>>(...);X<<<...,cudaStreamPerThread>>>(...);F<<<...,cudaStreamFireAndForget>>>(...)}
// In this example, P2 will only launch after C completes.__global__voidP1(...){C<<<...,cudaStreamTailLaunch>>>(...);}__global__voidP2(...){}intmain(...){...P1<<<...>>>(...);P2<<<...>>>(...);...}
每个网格只有一个尾部启动流。要通过尾部启动来启动并发网格,可以采用以下示例所示的方式。
// In this example, C1 and C2 will launch concurrently after P's completion__global__voidT(...){C1<<<...,cudaStreamFireAndForget>>>(...);C2<<<...,cudaStreamFireAndForget>>>(...);}__global__voidP(...){...T<<<...,cudaStreamTailLaunch>>>(...);}
如果存在均作用于某个原子对象 M 的原子操作 X 和 Y,使得 A 按顺序先于 X,X 修改 M,Y 按顺序先于 B,并且 Y 读取 X 写入的值,或者读取假设 X 是释放操作时以其为首的假想释放序列中任何副作用写入的值,且每个操作(A、B、X 和 Y)指定的作用域都包含执行其他各操作的线程,则释放栅栏 A 与获取栅栏 B 同步。
如果存在原子操作 X,使得 A 按顺序先于 X,X 修改 M,并且 B 读取 X 写入的值,或者读取假设 X 是释放操作时以其为首的假想释放序列中任何副作用写入的值,且每个操作(A、B 和 X)指定的作用域都包含执行其他各操作的线程,则释放栅栏 A 与在原子对象 M 上执行获取操作的原子操作 B 同步。
如果存在某个作用于 M 的原子操作 X,使得 X 按顺序先于 B,并且读取 A 写入的值,或者读取以 A 为首的释放序列中任何副作用写入的值,且每个操作(A、B 和 X)指定的作用域都包含执行其他各操作的线程,则在原子对象 M 上执行释放操作的原子操作 A 与获取栅栏 B 同步。
[注意:设备线程相对于主机线程的某些当前限制是我们已知的实现缺陷,我们可能会随着时间的推移修复这些缺陷。例如,设备线程最终仅对具有自动存储期的对象执行 volatile 操作或原子操作时会产生未定义行为。然而,设备线程相对于主机线程的其他限制是有意作出的选择。这些选择使某些性能优化成为可能,而如果设备线程严格遵循 C++ 标准,这些优化就无法实现。例如,为最终仅执行原子写入或栅栏的程序提供前向进展,会降低整体性能,却几乎没有实际益处。注意结束。]
1// Example: Execution.Model.Device.02// Outcome: grid eventually terminates per device.threads.4 because the atomic object does not have automatic storage duration.3__global__voidex0(cuda::atomic_ref<int,cuda::thread_scope_device>atom){4if(threadIdx.x==0){5while(atom.load(cuda::memory_order_relaxed)==0);6}elseif(threadIdx.x==1){7atom.store(1,cuda::memory_order_relaxed);8}9}
1// Example: Execution.Model.Device.12// Allowed outcome: No thread makes progress because device threads don't support host.threads.2.3__global__voidex1(){4while(true)cuda::std::this_thread::yield();5}
1// Example: Execution.Model.Device.22// Allowed outcome: No thread makes progress because device threads don't support host.threads.43// for objects with automatic storage duration (see exception in device.threads.3).4__global__voidex2(){5volatileboolTrue=true;6while(True);7}
1// Example: Execution.Model.Device.32// Allowed outcome: No thread makes progress because device threads don't support host.threads.53// for objects with automatic storage duration (see exception in device.threads.4).4__global__voidex3(){5cuda::atomic<bool,cuda::thread_scope_thread>True=true;6while(True.load());7}
1// Example: Execution.Model.Device.42// Allowed outcome: No thread makes progress because device threads don't support host.thread.6.3__globalvoidex4(){4while(true){/* empty */}5}
[注意:该设备线程不必与 API 调用“相关”,例如,对一个流或进程执行操作的 API 可以确保另一个流或进程上的设备线程取得进展。注意结束。]
[注意:测试程序是否符合 CUDA API 前向进展要求的一种简单但不充分的方法是,在设置以下环境变量后运行程序:CUDA_DEVICE_MAX_CONNECTIONS=1CUDA_LAUNCH_BLOCKING=1,然后检查程序是否仍会终止。如果不会,则程序存在错误。此方法并不充分,因为它无法发现所有前向进展错误,但确实可以发现许多此类错误。注意结束。]
CUDA API 前向进展保证的示例。
1// Example: Execution.Model.API.1 2// Outcome: if no other device threads (e.g., from other processes) are making progress, 3// this program terminates and returns cudaSuccess. 4// Rationale: CUDA guarantees that if the device is empty: 5// - `cudaDeviceSynchronize` eventually ensures that at least one device-thread makes progress, which implies that eventually `hello_world` grid and one of its device-threads start. 6// - All thread-block threads eventually start (due to "if a device thread makes progress, all other threads in its thread-block cluster eventually make progress"). 7// - Once all threads in thread-block arrive at `__syncthreads` barrier, all waiting threads are unblocked. 8// - Therefore all device threads eventually exit the `hello_world`` grid. 9// - And `cudaDeviceSynchronize`` eventually unblocks.10__global__voidhello_world(){__syncthreads();}11intmain(){12hello_world<<<1,2>>>();13return(int)cudaDeviceSynchronize();14}
1// Example: Execution.Model.API.2 2// Allowed outcome: eventually, no thread makes progress. 3// Rationale: the `cudaDeviceSynchronize` API below is only called if a device thread eventually makes progress and sets the flag. 4// However, CUDA only guarantees that `producer` device thread eventually starts if the synchronization API is called. 5// Therefore, the host thread may never be unblocked from the flag spin-loop. 6cuda::atomic<int,cuda::thread_scope_system>flag=0; 7__global__voidproducer(){flag.store(1);} 8intmain(){ 9cudaHostRegister(&flag,sizeof(flag));10producer<<<1,1>>>();11while(flag.load()==0);12returncudaDeviceSynchronize();13}
1// Example: Execution.Model.API.3 2// Allowed outcome: eventually, no thread makes progress. 3// Rationale: same as Example.Model.API.2, with the addition that a single CUDA query API call does not guarantee 4// the device thread eventually starts, only repeated CUDA query API calls do (see Execution.Model.API.4). 5cuda::atomic<int,cuda::thread_scope_system>flag=0; 6__global__voidproducer(){flag.store(1);} 7intmain(){ 8cudaHostRegister(&flag,sizeof(flag)); 9producer<<<1,1>>>();10(void)cudaStreamQuery(0);11while(flag.load()==0);12returncudaDeviceSynchronize();13}
1// Example: Execution.Model.API.4 2// Outcome: terminates. 3// Rationale: same as Execution.Model.API.3, but this example repeatedly calls 4// a CUDA query API in within the flag spin-loop, which guarantees that the device thread 5// eventually makes progress. 6cuda::atomic<int,cuda::thread_scope_system>flag=0; 7__global__voidproducer(){flag.store(1);} 8intmain(){ 9cudaHostRegister(&flag,sizeof(flag));10producer<<<1,1>>>();11while(flag.load()==0){12(void)cudaStreamQuery(0);13}14returncudaDeviceSynchronize();15}
1// Example: Execution.Model.Stream.0 2// Allowed outcome: eventually, no thread makes progress. 3// Rationale: while CUDA guarantees that one device thread makes progress, since there 4// is no dependency between `first` and `second`, it does not guarantee which thread, 5// and therefore it could always pick the device thread from `second`, which then never 6// unblocks from the spin-loop. 7// That is, `second` may starve `first`. 8cuda::atomic<int,cuda::thread_scope_system>flag=0; 9__global__voidfirst(){flag.store(1,cuda::memory_order_relaxed);}10__global__voidsecond(){while(flag.load(cuda::memory_order_relaxed)==0){}}11intmain(){12cudaHostRegister(&flag,sizeof(flag));13cudaStream_ts0,s1;14cudaStreamCreate(&s0);15cudaStreamCreate(&s1);16first<<<1,1,0,s0>>>();17second<<<1,1,0,s1>>>();18returncudaDeviceSynchronize();19}
1// Example: Execution.Model.Stream.1 2// Outcome: terminates. 3// Rationale: same as Execution.Model.Stream.0, but this example has a stream dependency 4// between first and second, which requires CUDA to run the grids in order. 5cuda::atomic<int,cuda::thread_scope_system>flag=0; 6__global__voidfirst(){flag.store(1,cuda::memory_order_relaxed);} 7__global__voidsecond(){while(flag.load(cuda::memory_order_relaxed)==0){}} 8intmain(){ 9cudaHostRegister(&flag,sizeof(flag));10cudaStream_ts0;11cudaStreamCreate(&s0);12first<<<1,1,0,s0>>>();13second<<<1,1,0,s0>>>();14returncudaDeviceSynchronize();15}